In order to meet all demands of all customers, our company has employed a lot of excellent experts and professors in the field to design and compile the Databricks-Certified-Professional-Data-Engineer test dump with a high quality. It has been a generally accepted fact that the Databricks-Certified-Professional-Data-Engineer exam reference guide from our company are more useful and helpful for all people who want to pass exam and gain the related exam. We believe this resulted from our constant practice, hard work and our strong team spirit. With the high class operation system, the Databricks-Certified-Professional-Data-Engineer study question from our company has won the common recognition from a lot of international customers for us. If you decide to buy our Databricks-Certified-Professional-Data-Engineer test dump, we can assure you that you will pass exam in the near future.
| Section | Weight | Objectives |
|---|---|---|
| Delta Lake | 20-25% | - Delta Lake fundamentals
|
| Data Ingestion | 15-20% | - Batch ingestion methods
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
>> Databricks-Certified-Professional-Data-Engineer Sample Questions Pdf <<
ActualTestsIT is growing faster and many people find that obtaining a certificate has outstanding advantage over other peer, especially for promotion or applying for a large company. ActualTestsIT helps fresh people enter into this area and help experienced workers have good opportunities for further development. Thus our passing rate of best Databricks-Certified-Professional-Data-Engineer Study Guide materials is nearly highest in this area. That's why we grows rapidly recent years and soon become the pioneer in Databricks-Certified-Professional-Data-Engineer qualification certificate learning guide providers. Our Databricks-Certified-Professional-Data-Engineer study guide will be your best choice to help you clear exam certainly.
NEW QUESTION # 34
In order to facilitate near real-time workloads, a data engineer is creating a helper function to leverage the schema detection and evolution functionality of Databricks Auto Loader. The desired function will automatically detect the schema of the source directly, incrementally process JSON files as they arrive in a source directory, and automatically evolve the schema of the table when new fields are detected.
The function is displayed below with a blank: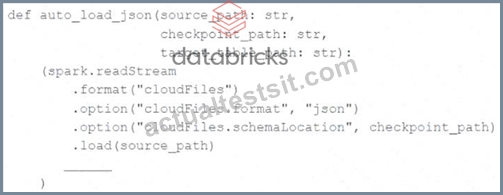
Which response correctly fills in the blank to meet the specified requirements?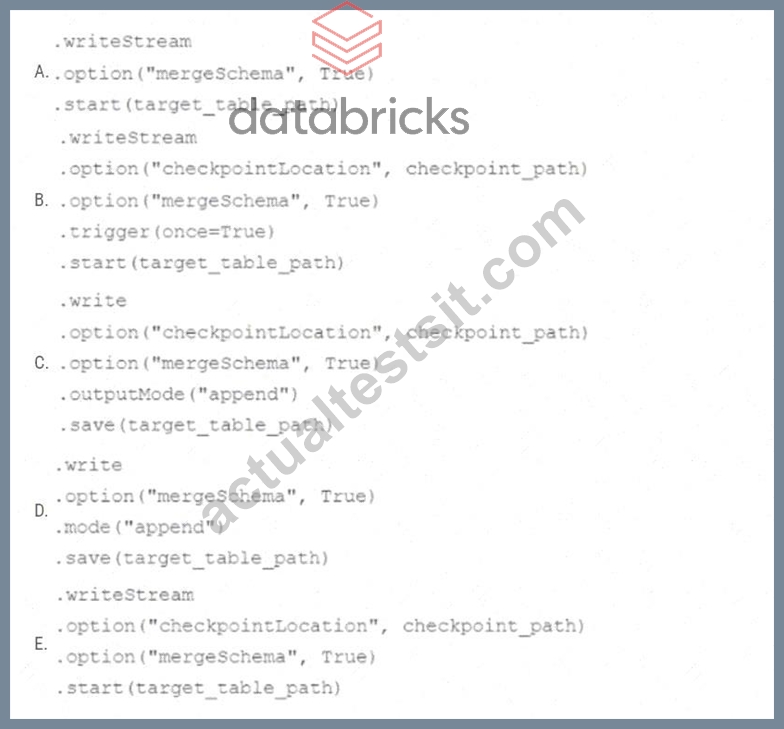
Answer: C
Explanation:
Option B correctly fills in the blank to meet the specified requirements. Option B uses the "cloudFiles.
schemaLocation" option, which is required for the schema detection and evolution functionality of Databricks Auto Loader. Additionally, option B uses the "mergeSchema" option, which is required for the schema evolution functionality of Databricks Auto Loader. Finally, option B uses the "writeStream" method, which is required for the incremental processing of JSON files as they arrive in a source directory. The other options are incorrect because they either omit the required options, use the wrong method, or use the wrong format. References:
* Configure schema inference and evolution in Auto Loader: https://docs.databricks.com/en/ingestion
/auto-loader/schema.html
* Write streaming data: https://docs.databricks.com/spark/latest/structured-streaming/writing-streaming- data.html
NEW QUESTION # 35
Assuming that the Databricks CLI has been installed and configured correctly, which Databricks CLI command can be used to upload a custom Python Wheel to object storage mounted with the DBFS for use with a production job?
Answer: C
Explanation:
Explanation
The libraries command group allows you to install, uninstall, and list libraries on Databricks clusters. You can use the libraries install command to install a custom Python Wheel on a cluster by specifying the --whl option and the path to the wheel file. For example, you can use the following command to install a custom Python Wheel named mylib-0.1-py3-none-any.whl on a cluster with the id 1234-567890-abcde123:
databricks libraries install --cluster-id 1234-567890-abcde123 --whl
dbfs:/mnt/mylib/mylib-0.1-py3-none-any.whl
This will upload the custom Python Wheel to the cluster and make it available for use with a production job.
You can also use the libraries uninstall command to uninstall a library from a cluster, and the libraries list command to list the libraries installed on a cluster.
References:
Libraries CLI (legacy): https://docs.databricks.com/en/archive/dev-tools/cli/libraries-cli.html Library operations: https://docs.databricks.com/en/dev-tools/cli/commands.html#library-operations Install or update the Databricks CLI: https://docs.databricks.com/en/dev-tools/cli/install.html
NEW QUESTION # 36
A data engineer is configuring a Databricks Asset Bundle to deploy a job with granular permissions. The requirements are:
* Grant the data-engineers group CAN_MANAGE access to the job.
* Ensure the auditors' group can view the job but not modify/run it.
* Avoid granting unintended permissions to other users/groups.
How should the data engineer deploy the job while meeting the requirements?
Answer: B
Explanation:
Comprehensive and Detailed Explanation from Databricks Documentation:
Databricks Asset Bundles (DABs) allow jobs, clusters, and permissions to be defined as code in YAML configuration files. According to the Databricks documentation on job permissions and bundle deployment, when defining permissions within a job resource, they must be scoped directly under that specific job's definition. This ensures that permissions are applied only to the intended job resource and not inadvertently propagated to other jobs or resources.
In this scenario, the data engineer must grant the data-engineers group CAN_MANAGE access, allowing them to configure, edit, and manage the job, while the auditors group should only have CAN_VIEW, giving them read-only access to see configurations and results without the ability to modify or execute. Importantly, no additional groups should be granted permissions, in order to follow the principle of least privilege.
Options A and B introduce unnecessary or unintended groups (like admin-team in A) or define permissions outside of the job scope (as in B). Option C improperly separates the permissions block outside the job resource, which is not aligned with Databricks bundle best practices.
Option D is the correct approach because it defines the job resource my-job with its name, tasks, clusters, and the exact intended permissions (CAN_MANAGE for data-engineers and CAN_VIEW for auditors). This aligns with Databricks' principle of least privilege and ensures compliance with governance standards in Unity Catalog-enabled workspaces.
NEW QUESTION # 37
A data engineer is optimizing a managed Delta table that suffers from data skew and frequently changing query filter columns . The engineer wants to avoid costly data rewrites when query patterns evolve. The table size is under 1 TB.
How should the data engineer meet this requirement?
Answer: D
Explanation:
The Databricks documentation describes Liquid Clustering as the recommended data layout optimization for evolving workloads. Unlike traditional partitioning or Z-ordering, Liquid Clustering dynamically maintains data organization without rewriting existing files when clustering keys change. It handles data skew automatically and supports flexible re-clustering based on query patterns. Partitioning and Z-ordering require full data rewrites whenever key structures change, making them expensive for tables with frequently evolving access patterns. For tables under a few terabytes, Liquid Clustering offers the best balance between scalability, adaptability, and maintenance efficiency. Thus, option C aligns with Databricks' best practice for modern adaptive layout optimization.
NEW QUESTION # 38
The data architect has mandated that all tables in the Lakehouse should be configured as external Delta Lake tables.
Which approach will ensure that this requirement is met?
Answer: A
Explanation:
Explanation
This is the correct answer because it ensures that this requirement is met. The requirement is that all tables in the Lakehouse should be configured as external Delta Lake tables. An external table is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created by using the location keyword to specify the path to an existing directory in a cloud storage system, such as DBFS or S3. By creating external tables, the data engineering team can avoid losing data if they drop or overwrite the table, as well as leverage existing data without moving or copying it.
Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Create an external table" section.
NEW QUESTION # 39
......
Are you still worried about low wages? Are you still anxious to get a good job? Are you still anxious about how to get a Databricks-Certified-Professional-Data-Engineer certificate? If yes, our Databricks-Certified-Professional-Data-Engineer study materials will be the good choice for you. If you have our Databricks-Certified-Professional-Data-Engineer study materials, I believe you difficulties will be solved, and you will have a better life. And Databricks-Certified-Professional-Data-Engineer real test has a high quality as well as a high pass rate of 99% to 100%. What is more, Databricks-Certified-Professional-Data-Engineer test prep provides free trial downloading before your purchasing.
Databricks-Certified-Professional-Data-Engineer Exam Certification Cost: https://www.actualtestsit.com/Databricks/Databricks-Certified-Professional-Data-Engineer-exam-prep-dumps.html