DOWNLOAD the newest Pass4suresVCE Databricks-Certified-Data-Analyst-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1aFlwjM_rwAi4phCefjSv3DvxGCooMrhR
Different from traditional learning methods, our Databricks-Certified-Data-Analyst-Associate exam products adopt the latest technology to improve your learning experience. We hope that all candidates can try our free demo before deciding to buy our Databricks-Certified-Data-Analyst-Associate study guide. The Q&A contained in the free demo are also compiled by our vetaren professionals who keep close on the changes of the Databricks-Certified-Data-Analyst-Associate learning dumps according to the real exam. Come and have a try, you will get satisfied with our Databricks-Certified-Data-Analyst-Associate training engine!
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Data Analyst Associate Exam |
| Exam Number: | Databricks-Certified-Data-Analyst-Associate |
| Real Exam Qty: | 45 |
| Exam Format: | Multiple-choice, Scenario-based questions |
| Available Languages: | English |
| Exam Price: | $200 USD |
| Certificate Validity Period: | 2 years |
| Exam Duration: | 90 minutes |
| Passing Score: | Approximately 70% (not officially disclosed) |
| Recommended Training: | Databricks Academy - Data Analyst Associate Learning Path |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Certified-Data-Analyst-Associate Sample Questions |
| Exam Way: | Online proctored or authorized test center |
| Pre Condition: | No mandatory prerequisites; recommended 6+ months hands-on experience in data analysis and SQL usage with Databricks |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-analyst-associate |
>> Instant Databricks-Certified-Data-Analyst-Associate Download <<
In this version, you don't need an active internet connection to use the Databricks-Certified-Data-Analyst-Associate practice test software. This software mimics the style of real test so that users find out pattern of the real test and kill the exam anxiety. Pass4suresVCE offline practice exam is customizable and users can change questions and duration of Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) mock tests.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 40
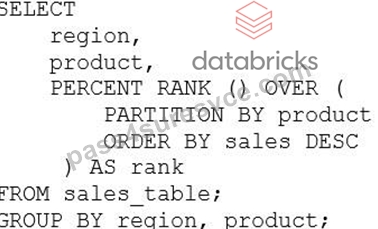
A data analyst has been asked to use the below table sales_table to get the percentage rank of products within region by the sales: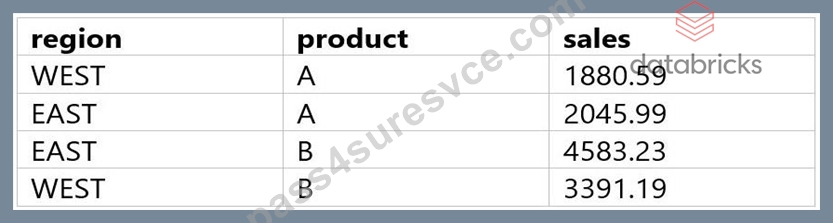
The result of the query should look like this: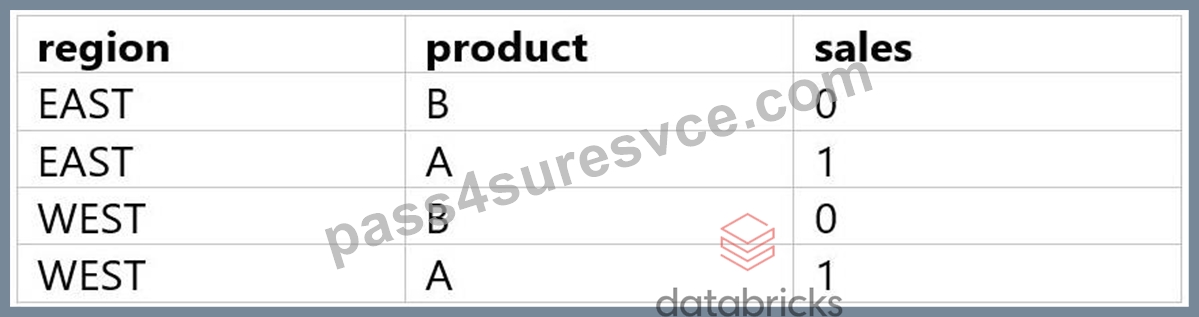
Which of the following queries will accomplish this task?
A)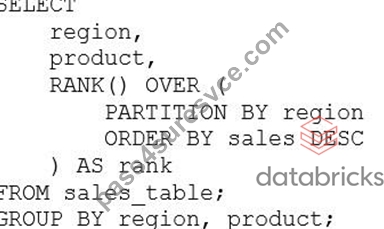
B)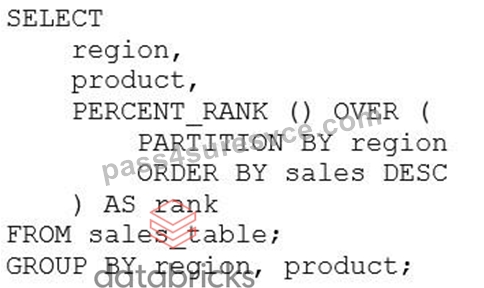
C)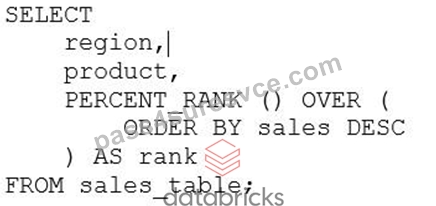
Answer: A
Explanation:
The correct query to get the percentage rank of products within region by the sales is option B. This query uses the PERCENT_RANK() window function to calculate the relative rank of each product within each region based on the sales amount. The window function is partitioned by region and ordered by sales in descending order. The result is aliased as rank and displayed along with the region and product columns. The other options are incorrect because:
A) Option A uses the RANK() window function instead of the PERCENT_RANK() function. The RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
C) Option C uses the DENSE_RANK() window function instead of the PERCENT_RANK() function. The DENSE_RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
D) Option D uses the ROW_NUMBER() window function instead of the PERCENT_RANK() function. The ROW_NUMBER() function returns the sequential number of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM(). Reference:
1: PERCENT_RANK (Transact-SQL)
2: Window functions in Databricks SQL
3: Databricks Certified Data Analyst Associate Exam Guide
NEW QUESTION # 41
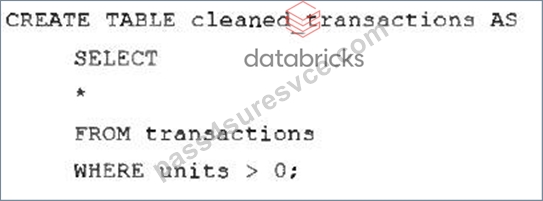
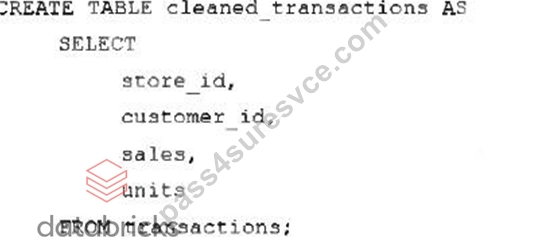
A data analyst is working in an organization that utilizes a multi-hop, medallion architecture. They have been tasked with creating a new Gold table from an existing Silver table.
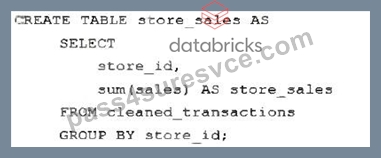
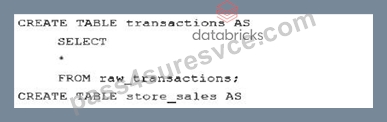
Which query is performing a hop from a Silver table to a Gold table?
Answer: A
Explanation:
Option C is the correct answer because it creates a new aggregated table, store_sales, from the existing cleaned
/refined table cleaned_transactions. In a medallion architecture, a table such as cleaned_transactions represents a Silver-layer table because it contains cleaned or validated transaction-level data. The query then creates store_sales by grouping by store_id and calculating SUM(sales), which is an aggregation suitable for analytics and reporting. That is exactly the Silver-to-Gold hop.
Option A creates cleaned_transactions from transactions, so it is moving toward a cleaned Silver table, not creating a Gold table. Option B creates transactions from raw_transactions, which is closer to a raw-to-Bronze or Bronze preparation step. Option D filters rows from transactions into cleaned_transactions, which is also a cleaning/validation step associated with Silver, not Gold.
Exact extract from official Databricks documentation: Databricks describes medallion architecture as improving data through "Bronze # Silver # Gold layer tables." The same official page identifies Silver as
"Data cleaning and validation" and Gold as "Dimensional modeling and aggregation." Databricks also states that the Gold layer "consists of aggregated data tailored for analytics and reporting."
NEW QUESTION # 42
Delta Lake stores table data as a series of data files, but it also stores a lot of other information.
Which of the following is stored alongside data files when using Delta Lake?
Answer: D
Explanation:
Delta Lake stores table data as a series of data files in a specified location, but it also stores table metadata in a transaction log. The table metadata includes the schema, partitioning information, table properties, and other configuration details. The table metadata is stored alongside the data files and is updated atomically with every write operation. The table metadata can be accessed using the DESCRIBE DETAIL command or the DeltaTable class in Scala, Python, or Java. The table metadata can also be enriched with custom tags or user-defined commit messages using the TBLPROPERTIES or userMetadata options. Reference:
Enrich Delta Lake tables with custom metadata
Delta Lake Table metadata - Stack Overflow
Metadata - The Internals of Delta Lake
NEW QUESTION # 43
A data analyst has a managed table table_name in database database_name. They would now like to remove the table from the database and all of the data files associated with the table. The rest of the tables in the database must continue to exist.
Which of the following commands can the analyst use to complete the task without producing an error?
Answer: D
Explanation:
The DROP TABLE command removes a table from the metastore and deletes the associated data files. The syntax for this command is DROP TABLE [IF EXISTS] [database_name.] table_name;. The optional IF EXISTS clause prevents an error if the table does not exist. The optional database_name. prefix specifies the database where the table resides. If not specified, the current database is used. Therefore, the correct command to remove the table table_name from the database database_name and all of the data files associated with it is DROP TABLE database_name.table_name;. The other commands are either invalid syntax or would produce undesired results. References: Databricks - DROP TABLE
NEW QUESTION # 44
A data analyst has been asked to use the below table sales_table to get the percentage rank of products within region by the sales: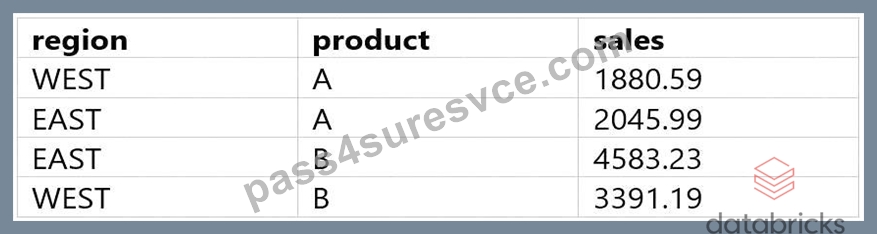
The result of the query should look like this: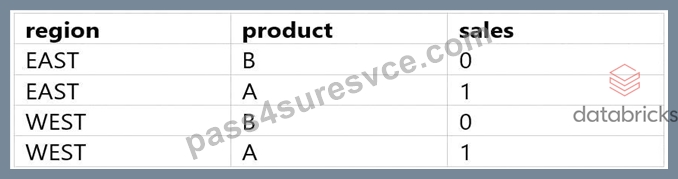
Which of the following queries will accomplish this task?
A)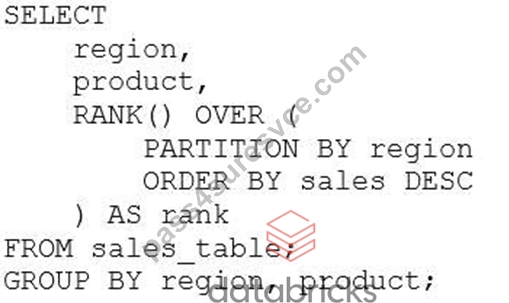
B)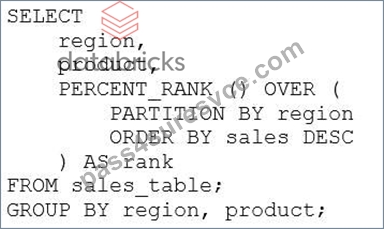
C)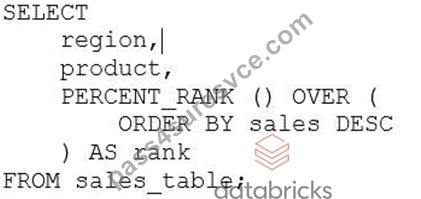
D)
Answer: A
Explanation:
The correct query to get the percentage rank of products within region by the sales is option B. This query uses the PERCENT_RANK() window function to calculate the relative rank of each product within each region based on the sales amount. The window function is partitioned by region and ordered by sales in descending order. The result is aliased as rank and displayed along with the region and product columns. The other options are incorrect because:
* A. Option A uses the RANK() window function instead of the PERCENT_RANK() function. The RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
* C. Option C uses the DENSE_RANK() window function instead of the PERCENT_RANK() function.
The DENSE_RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
* D. Option D uses the ROW_NUMBER() window function instead of the PERCENT_RANK() function.
The ROW_NUMBER() function returns the sequential number of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM(). References:
* 1: PERCENT_RANK (Transact-SQL)
* 2: Window functions in Databricks SQL
* 3: Databricks Certified Data Analyst Associate Exam Guide
NEW QUESTION # 45
......
Official Databricks-Certified-Data-Analyst-Associate Study Guide: https://www.pass4suresvce.com/Databricks-Certified-Data-Analyst-Associate-pass4sure-vce-dumps.html
P.S. Free 2026 Databricks Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by Pass4suresVCE: https://drive.google.com/open?id=1aFlwjM_rwAi4phCefjSv3DvxGCooMrhR