P.S. Free 2026 Microsoft AI-103 dumps are available on Google Drive shared by PassExamDumps: https://drive.google.com/open?id=1encKaGlcgaPfX8JgV25ReyaJllabbMRm
Our company pays high attentions to the innovation of our AI-103 study dump. We constantly increase the investment on the innovation and build an incentive system for the members of the research expert team. Our experts group specializes in the research and innovation of our AI-103 exam practice guide and supplements the latest innovation and research results into the AI-103 Quiz prep timely. Our experts group collects the latest academic and scientific research results and traces the newest industry progress in the update of the AI-103 study materials.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement agentic solutions | 20-25% | - Manage agent operations
|
| Topic 2: Plan and manage Azure AI solutions | 25-30% | - Manage AI solution lifecycle
|
| Topic 3: Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
| Topic 4: Implement computer vision solutions | 10-15% | - Analyze visual content
|
| Topic 5: Implement generative AI solutions | 25-30% | - Develop generative AI applications
|
>> Latest AI-103 Exam Question <<
Many clients worry that after they bought our AI-103 exam simulation they might find the exam questions are outdated and waste their time, money and energy. There are no needs to worry about that situation because our AI-103 study materials boost high-quality and it is proved by the high passing rate and hit rate. And we keep updating our AI-103 learing quiz all the time. We provide the best AI-103 practice guide and hope our sincere service will satisfy all the clients.
NEW QUESTION # 22
You have a chat app in a Microsoft Foundry project and an Azure AI Search vectorized index.
You need to connect to the index to meet the following requirements:
- Complex questions must retrieve information from multiple chunks.
- Multi-turn conversations must influence retrieval planning.
- Retrievals must run in parallel to reduce latency.
Which retrieval approach should you use?
Answer: D
Explanation:
An agentic Retrieval-Augmented Generation (RAG) architecture is the best fit for your requirements. Traditional, linear RAG pipelines struggle with complex, multi-turn dependencies, whereas an agentic approach natively solves them through iterative reasoning and tool orchestration.
Here is how an agentic RAG pattern specifically satisfies each the three technical requirements:
1. Complex Questions & Multi-Chunk Retrieval
The Challenge: Complex questions often require aggregating distinct pieces of information scattered across different documents or sections.
The Agentic Solution: An agent uses a Reasoning and Acting (ReAct) loop. It evaluates the user's query, breaks it down into sub-questions, and executes multiple distinct search queries. It then synthesizes the information from these diverse chunks before generating a final response.
2. Multi-Turn Conversations & Retrieval Planning
The Challenge: Standard RAG often just passes the latest user message or a simple chat history summary to the search index, which can lose context or misinterpret the user's true intent in long conversations.
The Agentic Solution: The agent acts as a query planner. It maintains the state of the conversation and dynamically decides if a retrieval is needed, what specific keywords or vectors to target based on past turns, and how to reformulate the query to bridge context gaps.
3. Parallel Retrievals for Low Latency
The Challenge: Sequential lookups drastically increase time-to-first-token (TTFT), harming the chat user experience.
The Agentic Solution: Modern AI agent frameworks allow the LLM to emit multiple tool calls simultaneously. The application layer can intercept these calls and execute parallel asynchronous queries against your Azure AI Search vectorized index, drastically minimizing latency.
Reference:
https://arxiv.org/html/2501.09136v1
NEW QUESTION # 23
Hotspot Question
You have an Azure subscription.
You need to create a new resource that will generate fictional stores in response to user prompts.
The solution must ensure that the resource uses a customer-managed key to protect data.
How should you complete the script? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.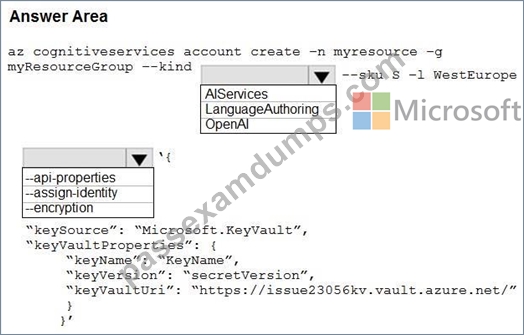
Answer:
Explanation: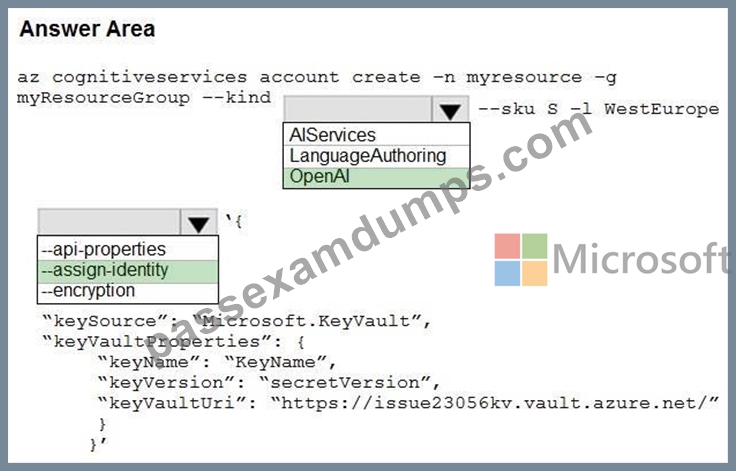
Explanation:
Box 1: OpenAI
To generate fictional stores in response to user prompts, you need a generative AI model (such as GPT-3.5 or GPT-4). The Azure OpenAI service natively supports this generative capability and allows you to secure your deployed models and data using customer-managed keys (CMK).
Box 2: --assign-identity
When defining the Azure Key Vault resource script to enable customer-managed keys (CMK), you must use --assign-identity (or assign-identity).
Reference:
https://learn.microsoft.com/en-us/azure/search/search-how-to-managed-identities
NEW QUESTION # 24
You have an invoice-processing application named App1 that uses Azure Content Understanding in Foundry Tools. You are building a new Content Understanding pipeline named Pipeline1 that must meet the following requirements:
* Compare an invoice to its related purchase order.
* Validate the invoice against static vendor contract documents.
* Return a single structured output that includes discrepancy findings.
You need to configure Pipeline1 and expose the pipeline as a single analyzer endpoint. What should you configure?
Answer: A
Explanation:
Configure a multi-file task in pro mode . At analysis time, provide the invoice and its related purchase order as the input documents. During analyzer creation, add the static vendor contracts as reference data . Pro mode can reason across multiple input documents and use reference documents as contextual knowledge for validation, enrichment, and discrepancy detection. Microsoft specifically documents the scenario of supplying an invoice and purchase order as inputs while using contract files as reference data to identify inconsistencies.
Define a field schema containing the required invoice information and generated discrepancy findings.
Building the task creates an analyzer ID that applications invoke through one analyzer API endpoint, producing a unified structured result governed by that schema.
Standard mode is optimized for straightforward processing of individual files. It does not support cross-file analysis, reference-dataset integration, or the multi-step reasoning required to compare invoices, purchase orders, and contractual conditions. A "multi-file task in standard mode" is therefore not a supported configuration. Confidence scores do not address document comparison and, notably, are not available in pro mode.
Study Guide alignment: configure Content Understanding analyzers, design structured schemas, process multiple documents, integrate reference data, and implement document validation workflows .
NEW QUESTION # 25
You have a Semantic Kernel agent that provides answers to product questions.
You plan to extend the capabilities of the agent to answer questions about the status of orders.
You need to ensure that the agent answers order status questions as quickly as possible. The solution must minimize development effort.
What should you include in the solution?
Answer: A
Explanation:
To enable the agent to answer questions about order status, you need a plugin.
In Semantic Kernel, a plugin acts as a container for the specific capabilities (functions) that allow an agent to interact with external data or systems, such as an order database or API.
To help me give you a more specific example or guide, could you tell me:
The data source where order info is kept (e.g., a SQL database, a REST API, or Shopify) The programming language you're using for the Kernel (C# or Python) Reference:
https://learn.microsoft.com/en-us/semantic-kernel/frameworks/agent/agent-functions
NEW QUESTION # 26
You need to recommend a plan to create a customer support agent by using the Microsoft Foundry Agent Service. The agent must meet the following requirements:
* Retain user preferences across multiple conversations.
* Enable users to provide contextual grounding by directly uploading documents during a chat.
Which Foundry capability should you recommend for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.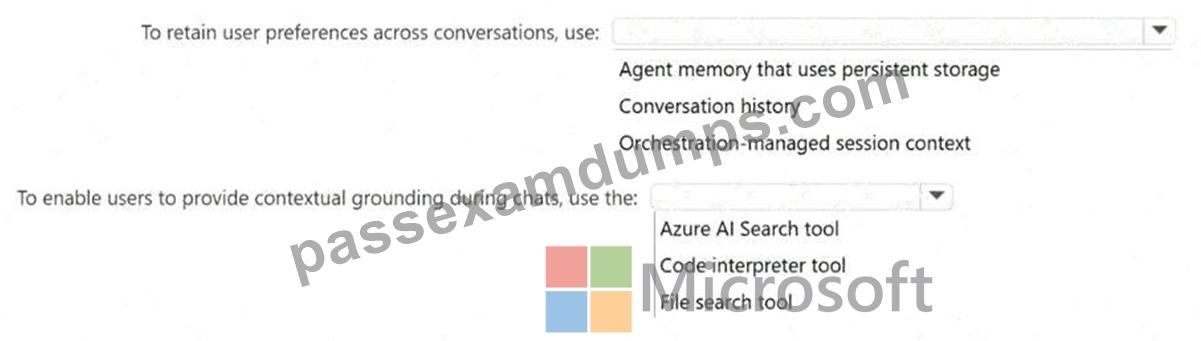
Answer:
Explanation: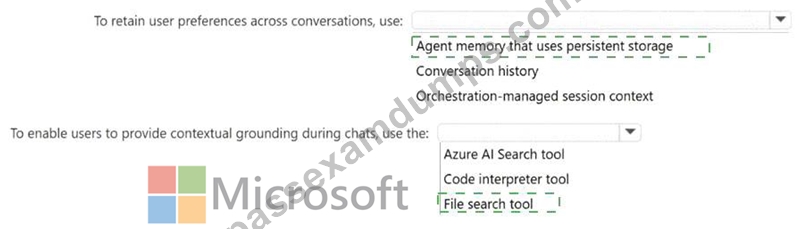
Explanation:
To retain user preferences across conversations, use: Agent memory that uses persistent storage To enable users to provide contextual grounding during chats, use the: file search tool The correct capability for retaining user preferences is agent memory that uses persistent storage .
Microsoft Foundry Agent Service memory is a managed long-term memory capability that enables continuity across sessions, devices, and workflows. It is specifically intended to let agents retain user preferences, maintain relevant historical context, and personalize responses across separate conversations. Memory stores provide the persistent storage layer, and scope can be used to segment memories for secure user-specific experiences.
The correct capability for contextual grounding from user-uploaded documents is the file search tool .
Microsoft describes file search as the tool that enables Foundry agents to search through documents and retrieve relevant information from outside the base model, including proprietary product information and user- provided documents. The file search workflow supports uploading files, creating a vector store, enabling the tool on the agent, and querying those documents through the agent.
Conversation history alone supports continuity within a conversation, but it is not durable preference memory across multiple conversations. An Azure AI Search tool is better for preconfigured enterprise indexes, while file search is the direct document-upload grounding capability. Reference topics: Foundry Agent Service memory, memory stores, File Search tool, vector stores, and grounded agent responses.
NEW QUESTION # 27
......
Our online test engine and the windows software of the AI-103 guide materials can evaluate your exercises of the virtual exam and practice exam intelligently. Our calculation system of the AI-103 study engine is designed subtly. Our evaluation process is absolutely correct. We are strictly in accordance with the detailed grading rules of the real exam. And our pass rate of the AI-103 Exam Questions are high as 98% to 100%, it is unique in the market.
AI-103 Valid Mock Exam: https://www.passexamdumps.com/AI-103-valid-exam-dumps.html
BTW, DOWNLOAD part of PassExamDumps AI-103 dumps from Cloud Storage: https://drive.google.com/open?id=1encKaGlcgaPfX8JgV25ReyaJllabbMRm