Databricks-Machine-Learning-Professional높은통과율덤프공부문제, Databricks-Machine-Learning-Professional최고품질덤프문제

Pass4Test Databricks-Machine-Learning-Professional 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=19_sRrBESVKTA4TmYnxJT0VUK_cuFi4by
Pass4Test에서는 가장 최신이자 최고인Databricks인증 Databricks-Machine-Learning-Professional시험덤프를 제공해드려 여러분이 IT업계에서 더 순조롭게 나아가도록 최선을 다해드립니다. Databricks인증 Databricks-Machine-Learning-Professional덤프는 최근 실제시험문제를 연구하여 제작한 제일 철저한 시험전 공부자료입니다. Databricks인증 Databricks-Machine-Learning-Professional시험준비자료는 Pass4Test에서 마련하시면 기적같은 효과를 안겨드립니다.
Databricks Databricks-Machine-Learning-Professional Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Machine Learning Professional |
|---|
| Exam Number: | Databricks-Machine-Learning-Professional |
|---|
| Exam Format: | Multiple choice |
|---|
| Real Exam Qty: | 60 |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Exam Price: | USD 200 |
|---|
| Passing Score: | 70% |
|---|
| Available Languages: | English |
|---|
| Related Certifications: | Databricks Certified Machine Learning Associate |
|---|
| Exam Duration: | 120 minutes |
|---|
| Sample Questions: | Databricks Databricks-Machine-Learning-Professional Sample Questions |
|---|
| Exam Way: | Online (proctored) or Test Center |
|---|
| Pre Condition: | No formal prerequisites, but 1+ years of hands-on experience performing the machine learning tasks outlined in the exam guide is highly recommended. Recommended courses: Machine Learning at Scale and Advanced Machine Learning Operations (instructor-led or self-paced via Databricks Academy). |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification/machine-learning-professional |
|---|
>> Databricks-Machine-Learning-Professional높은 통과율 덤프공부문제 <<
Databricks-Machine-Learning-Professional최고품질 덤프문제 - Databricks-Machine-Learning-Professional시험패스 가능한 인증덤프
IT업계에 종사하고 계시나요? 최근 유행하는Databricks인증 Databricks-Machine-Learning-Professional IT인증시험에 도전해볼 생각은 없으신지요? IT 인증자격증 취득 의향이 있으시면 저희. Pass4Test의 Databricks인증 Databricks-Machine-Learning-Professional덤프로 시험을 준비하시면 100%시험통과 가능합니다. Pass4Test의 Databricks인증 Databricks-Machine-Learning-Professional덤프는 착한 가격에 고품질을 지닌 최고,최신의 버전입니다. Pass4Test덤프로 가볼가요?
Databricks Databricks-Machine-Learning-Professional 시험요강:
| 주제 | 소개 |
|---|
| 주제 1 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| 주제 2 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| 주제 3 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| 주제 4 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| 주제 5 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| 주제 6 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| 주제 7 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
최신 ML Data Scientist Databricks-Machine-Learning-Professional 무료샘플문제 (Q190-Q195):
질문 # 190
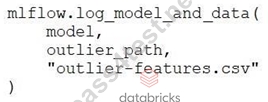
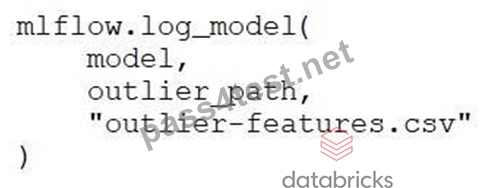
A data scientist wants to log outlier feature data from a CSV file at path outlier_path with an MLflow run for model model. Which code block will accomplish this task inside of an existing MLflow run block?
- A.
- B. mlflow.log_data(outlier_path, "outlier-features.csv")
- C. mlflow.log_artifact(outlier_path, "outlier-features.csv")
- D.
정답:C
설명:
To log external files, such as a CSV containing outlier feature data, MLflow provides the mlflow.log_artifact() function. This function uploads the specified file or directory (outlier_path) as an artifact under the provided artifact path ("outlier-features.csv"). It is the correct way to associate data files with an MLflow run, whereas mlflow.log_model() is reserved for logging model objects, not arbitrary data.
질문 # 191
A Machine Learning Engineer is using Lakehouse Monitoring to track the performance of ML models deployed in their environment. They want to monitor significant distributional drift in categorical features with a metric bounded on [0,1] for easy interpretation. Which statistical method should they use?
- A. Wasserstein Distance
- B. Jensen-Shannon Distance
- C. Kullback-Leibler Distance
- D. Kolmogorov-Smirnov Test
정답:B
설명:
Jensen-Shannon Distance is well suited for measuring distributional drift in categorical features. It is symmetric, numerically stable, and bounded between 0 and 1, which makes it easy to interpret and ideal for monitoring categorical feature drift in Lakehouse Monitoring.
질문 # 192
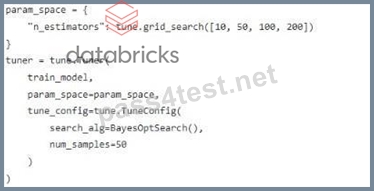
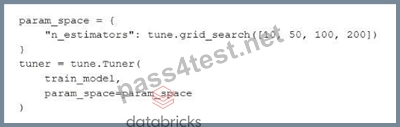
A Data Scientist has been performing hyperparameter tuning using Ray Tune with grid search.
After team discussions, they decide to switch to Bayesian optimization to more efficiently explore the parameter space.
Their current code is:
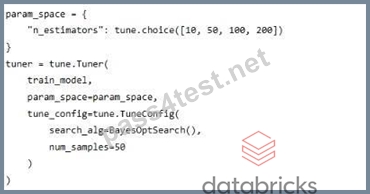
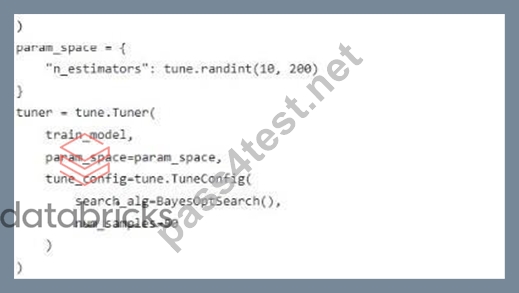
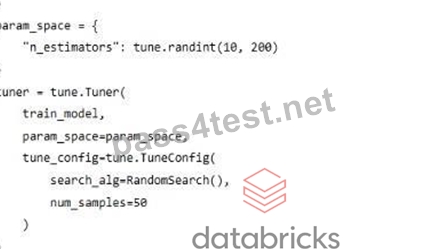
How can they implement this change?
정답:C
설명:
Bayesian optimization in Ray Tune requires defining a continuous or discrete search space (such as tune.randint) and explicitly configuring a Bayesian search algorithm. Using tune.randint defines a probabilistic parameter domain, and setting search_alg to BayesOptSearch enables Bayesian optimization to efficiently explore the space based on past trial results, rather than exhaustively enumerating all values as in grid search.
질문 # 193
A machine learning engineer is in the process of implementing a feature drift monitoring solution.
They are planning to use the following steps:
1. Measure the distributions of each feature variable in the training
set
2. Deploy a model to production
3. Measure the distributions of each feature variable in inference
4. _______
Which action should be completed as Step #4?
- A. Obtain the observed values (actual) feature values and compare to the predicted values
- B. Measure the latency of the model's prediction time
- C. Run a statistical test to determine if there are changes in the feature variable distribution over time
- D. Retrain the model based on any new feature variables that have been added to the feature set
정답:C
설명:
The final step in a feature drift monitoring solution is to run a statistical test (e.g., Kolmogorov- Smirnov test) to determine whether the feature distributions in production have significantly diverged from those in the training set. This helps detect drift and maintain model reliability.
질문 # 194
A Data Scientist is preparing a Spark ML pipeline on a customer dataset with numeric features age, annual_income, and transaction_count, each varying widely. Because the chosen algorithm requires inputs normalized to the [0,1] range, they need to apply the appropriate Spark ML transformer to these features. Which Spark ML transformer should the Data Scientist use to scale all features to the [0,1] range?
- A. MinMaxScaler
- B. MaxAbsScaler
- C. RobustScaler
- D. StandardScaler
정답:A
설명:
MinMaxScaler rescales each numeric feature to a fixed range, typically [0, 1], by subtracting the minimum value and dividing by the feature's range. This makes it the appropriate Spark ML transformer when an algorithm explicitly requires inputs normalized to the [0,1] interval.
질문 # 195
......
Databricks-Machine-Learning-Professional최고품질 덤프문제: https://www.pass4test.net/Databricks-Machine-Learning-Professional.html
- Databricks-Machine-Learning-Professional최신버전 덤프공부자료 😟 Databricks-Machine-Learning-Professional완벽한 시험공부자료 🌞 Databricks-Machine-Learning-Professional질문과 답 🌕 ▛ kr.fast2test.com ▟을(를) 열고➡ Databricks-Machine-Learning-Professional ️⬅️를 입력하고 무료 다운로드를 받으십시오Databricks-Machine-Learning-Professional완벽한 시험공부자료
- Databricks-Machine-Learning-Professional높은 통과율 덤프공부문제 시험대비 덤프공부 🎩 ➽ www.itdumpskr.com 🢪의 무료 다운로드✔ Databricks-Machine-Learning-Professional ️✔️페이지가 지금 열립니다Databricks-Machine-Learning-Professional최신버전 덤프공부자료
- Databricks-Machine-Learning-Professional시험대비 덤프데모문제 다운 🗜 Databricks-Machine-Learning-Professional시험대비 최신버전 덤프 🍾 Databricks-Machine-Learning-Professional시험패스 가능한 인증공부 ⛰ 무료로 쉽게 다운로드하려면《 kr.fast2test.com 》에서「 Databricks-Machine-Learning-Professional 」를 검색하세요Databricks-Machine-Learning-Professional최신버전 덤프공부자료
- Databricks-Machine-Learning-Professional높은 통과율 덤프공부문제 시험대비 덤프공부 🔏 【 www.itdumpskr.com 】을(를) 열고[ Databricks-Machine-Learning-Professional ]를 입력하고 무료 다운로드를 받으십시오Databricks-Machine-Learning-Professional완벽한 시험공부자료
- Databricks-Machine-Learning-Professional질문과 답 👑 Databricks-Machine-Learning-Professional시험덤프공부 🐯 Databricks-Machine-Learning-Professional인기자격증 인증시험덤프 🕒 ⏩ www.passtip.net ⏪에서➤ Databricks-Machine-Learning-Professional ⮘를 검색하고 무료로 다운로드하세요Databricks-Machine-Learning-Professional 100%시험패스 자료
- 100% 합격보장 가능한 Databricks-Machine-Learning-Professional높은 통과율 덤프공부문제 덤프공부 😆 「 www.itdumpskr.com 」을(를) 열고⇛ Databricks-Machine-Learning-Professional ⇚를 검색하여 시험 자료를 무료로 다운로드하십시오Databricks-Machine-Learning-Professional퍼펙트 최신버전 덤프자료
- 100% 합격보장 가능한 Databricks-Machine-Learning-Professional높은 통과율 덤프공부문제 시험덤프 ➡️ ✔ www.itdumpskr.com ️✔️을 통해 쉽게➤ Databricks-Machine-Learning-Professional ⮘무료 다운로드 받기Databricks-Machine-Learning-Professional시험대비 공부
- 최신버전 Databricks-Machine-Learning-Professional높은 통과율 덤프공부문제 완벽한 시험대비 덤프공부 🐵 ▷ www.itdumpskr.com ◁에서➥ Databricks-Machine-Learning-Professional 🡄를 검색하고 무료로 다운로드하세요Databricks-Machine-Learning-Professional인기자격증 인증시험덤프
- Databricks-Machine-Learning-Professional시험패스 가능한 인증공부 🧂 Databricks-Machine-Learning-Professional시험대비 📖 Databricks-Machine-Learning-Professional 100%시험패스 자료 🍬 무료 다운로드를 위해 지금➥ www.pass4test.net 🡄에서▶ Databricks-Machine-Learning-Professional ◀검색Databricks-Machine-Learning-Professional퍼펙트 최신버전 덤프자료
- 퍼펙트한 Databricks-Machine-Learning-Professional높은 통과율 덤프공부문제 덤프공부문제 📯 지금⏩ www.itdumpskr.com ⏪에서⇛ Databricks-Machine-Learning-Professional ⇚를 검색하고 무료로 다운로드하세요Databricks-Machine-Learning-Professional퍼펙트 최신버전 덤프자료
- 시험대비 Databricks-Machine-Learning-Professional높은 통과율 덤프공부문제 뎜프데모 😀 지금➡ kr.fast2test.com ️⬅️에서《 Databricks-Machine-Learning-Professional 》를 검색하고 무료로 다운로드하세요Databricks-Machine-Learning-Professional최신 덤프데모 다운로드
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, me.muz.li, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! Pass4Test Databricks-Machine-Learning-Professional 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=19_sRrBESVKTA4TmYnxJT0VUK_cuFi4by