Valid Databricks Databricks-Certified-Professional-Data-Engineer Test Syllabus - Reliable Databricks-Certified-Professional-Data-Engineer Exam Registration
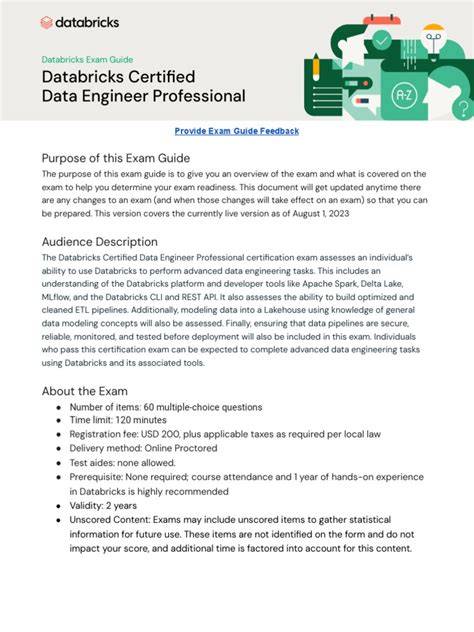
A whole new scope opens up to you and you are immediately hired by reputed firms. Even though the Databricks Databricks-Certified-Professional-Data-Engineer certification boosts your career options, you have to pass the Databricks-Certified-Professional-Data-Engineer Exam. This Databricks Databricks-Certified-Professional-Data-Engineer exam serves to filter out the capable from incapable candidates.
Databricks Certified Professional Data Engineer exam is a rigorous test that measures a candidate's knowledge and skills in various areas of Databricks, including data engineering, data modeling, data integration, data processing, and data storage. Databricks-Certified-Professional-Data-Engineer exam consists of multiple-choice questions and performance-based tasks that require candidates to demonstrate their ability to solve real-world problems using Databricks. Databricks-Certified-Professional-Data-Engineer Exam is designed to assess the candidate's ability to design and implement scalable, reliable, and efficient data solutions that meet business requirements.
>> Valid Databricks Databricks-Certified-Professional-Data-Engineer Test Syllabus <<
Reliable Databricks Databricks-Certified-Professional-Data-Engineer Exam Registration & Databricks-Certified-Professional-Data-Engineer Learning Mode
Our company is a professional certificate exam materials provider. We offer candidates high quality questions and answers for the Databricks-Certified-Professional-Data-Engineer exam bootcamp, and they can pass the exam through learning and practicing the materials. You can get the Databricks-Certified-Professional-Data-Engineer Exam Bootcamp about ten minutes after your payment, and if you have any questions about the Databricks-Certified-Professional-Data-Engineer exam dumps, you can notify us by email or you can chat with our online chat service.
Databricks, a unified analytics platform provider that helps organizations process and analyze large data sets, offers a certification exam for data engineers called the Databricks Certified Professional Data Engineer. Databricks-Certified-Professional-Data-Engineer exam is designed to test the skills and knowledge of data engineers in building and managing data pipelines, ETL processes, and data architectures within the Databricks platform. Databricks Certified Professional Data Engineer Exam certification is intended to validate the expertise of data engineers in implementing and managing data projects, and to demonstrate their competency in using the Databricks platform.
Databricks Certified Professional Data Engineer exam is a certification program that validates the skills and knowledge of professionals working with big data technologies, particularly on the Databricks platform. Databricks-Certified-Professional-Data-Engineer Exam is designed to test the candidate's ability to design, build, and maintain data pipelines, implement machine learning workflows, and optimize performance on the Databricks platform. Databricks Certified Professional Data Engineer Exam certification is ideal for data engineers, data architects, and big data professionals who want to demonstrate their expertise in the field.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q93-Q98):
NEW QUESTION # 93
A table named user_ltv is being used to create a view that will be used by data analysis on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:

An analyze who is not a member of the auditing group executing the following query:

Which result will be returned by this query?
- A. All columns will be displayed normally for those records that have an age greater than 17; records not meeting this condition will be omitted.
- B. All age values less than 18 will be returned as null values all other columns will be returned with the values in user_ltv.
- C. All columns will be displayed normally for those records that have an age greater than 18; records not meeting this condition will be omitted.
- D. All records from all columns will be displayed with the values in user_ltv.
Answer: C
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 94
A query is taking too long to run. After investigating the Spark UI, the data engineer discovered a significant amount of disk spill. The compute instance being used has a core-to-memory ratio of 1:2.
What are the two steps the data engineer should take to minimize spillage? (Choose 2 answers)
- A. Reduce spark.sql.files.maxPartitionBytes.
- B. Choose a compute instance with more network bandwidth.
- C. Increase spark.sql.files.maxPartitionBytes.
- D. Choose a compute instance with more disk space.
- E. Choose a compute instance with a higher core-to-memory ratio.
Answer: A,E
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks recommends addressing disk spilling-which occurs when Spark tasks run out of memory-by increasing memory per core and controlling partition size. Selecting an instance type with a higher memory-to-core ratio (A) provides each task with more available RAM, directly reducing the chance of spilling to disk. Additionally, reducing spark.sql.files.maxPartitionBytes (D) creates smaller partitions, preventing any single task from holding too much data in memory. Increasing partition size (C) or disk capacity (B) does not solve memory bottlenecks, and bandwidth (E) affects network I/O, not spill behavior. Therefore, the correct actions are A and D.
NEW QUESTION # 95
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).

Which statement describes what will happen when the above code is executed?
- A. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
- B. The connection to the external table will fail; the string "redacted" will be printed.
- C. The connection to the external table will succeed; the string value of password will be printed in plain text.
- D. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
- E. The connection to the external table will succeed; the string "redacted" will be printed.
Answer: E
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks. Verified References: [Databricks Certified Data Engineer Professional], under "Security & Governance" section; Databricks Documentation, under
"Secrets" section.
NEW QUESTION # 96
A junior data engineer has manually configured a series of jobs using the Databricks Jobs UI. Upon reviewing their work, the engineer realizes that they are listed as the "Owner" for each job. They attempt to transfer "Owner" privileges to the "DevOps" group, but cannot successfully accomplish this task.
Which statement explains what is preventing this privilege transfer?
- A. Databricks jobs must have exactly one owner; "Owner" privileges cannot be assigned to a group.
- B. Other than the default "admins" group, only individual users can be granted privileges on jobs.
- C. A user can only transfer job ownership to a group if they are also a member of that group.
- D. The creator of a Databricks job will always have "Owner" privileges; this configuration cannot be changed.
- E. Only workspace administrators can grant "Owner" privileges to a group.
Answer: A
Explanation:
The reason why the junior data engineer cannot transfer "Owner" privileges to the "DevOps" group is that Databricks jobs must have exactly one owner, and the owner must be an individual user, not a group. A job cannot have more than one owner, and a job cannot have a group as an owner. The owner of a job is the user who created the job, or the user who was assigned the ownership by another user. The owner of a job has the highest level of permission on the job, and can grant or revoke permissions to other users or groups. However, the owner cannot transfer the ownership to a group, only to another user. Therefore, the junior data engineer's attempt to transfer "Owner" privileges to the "DevOps" group is not possible. Reference:
Jobs access control: https://docs.databricks.com/security/access-control/table-acls/index.html Job permissions: https://docs.databricks.com/security/access-control/table-acls/privileges.html#job-permissions
NEW QUESTION # 97
The data engineering team noticed that one of the job normally finishes in 15 mins but gets stuck randomly when reading remote databases due to a network packet drop, which of the following steps can be used to improve the stability of the job?
- A. Use Databrick REST API to monitor long running jobs and issue a kill command
- B. Use Cluster timeout setting in the Job cluster UI
- C. Modify the task, to include a timeout to kill the job if it runs more than 15 mins.
- D. Use Jobs runs, active runs UI section to monitor and kill long running job
- E. Use Spark job time out setting in the Spark UI
Answer: C
Explanation:
Explanation
The answer is, Modify the task, to include time out to kill the job if it runs more than 15 mins.
https://docs.microsoft.com/en-us/azure/databricks/data-engineering/jobs/jobs#timeout
NEW QUESTION # 98
......
Reliable Databricks-Certified-Professional-Data-Engineer Exam Registration: https://www.itexamsimulator.com/Databricks-Certified-Professional-Data-Engineer-brain-dumps.html
- Free PDF Quiz Databricks Databricks-Certified-Professional-Data-Engineer Databricks Certified Professional Data Engineer Exam First-grade Valid Test Syllabus 📏 Download ➽ Databricks-Certified-Professional-Data-Engineer 🢪 for free by simply searching on { www.practicevce.com } 🚊New Databricks-Certified-Professional-Data-Engineer Exam Questions
- Real Databricks-Certified-Professional-Data-Engineer Exam Dumps 🧈 Databricks-Certified-Professional-Data-Engineer Valid Vce Dumps 🥞 Exam Databricks-Certified-Professional-Data-Engineer Review 🚰 Immediately open 「 www.pdfvce.com 」 and search for 《 Databricks-Certified-Professional-Data-Engineer 》 to obtain a free download 🕢Databricks-Certified-Professional-Data-Engineer Valid Test Pass4sure
- Free PDF Quiz Databricks Databricks-Certified-Professional-Data-Engineer Databricks Certified Professional Data Engineer Exam First-grade Valid Test Syllabus 🕋 Download ➤ Databricks-Certified-Professional-Data-Engineer ⮘ for free by simply entering ⮆ www.prepawaypdf.com ⮄ website 🧦Exam Databricks-Certified-Professional-Data-Engineer Sample
- Databricks-Certified-Professional-Data-Engineer Latest Exam Online 🏊 Latest Databricks-Certified-Professional-Data-Engineer Exam Forum 🔢 Reliable Databricks-Certified-Professional-Data-Engineer Test Dumps 🥦 Download ▛ Databricks-Certified-Professional-Data-Engineer ▟ for free by simply entering ➥ www.pdfvce.com 🡄 website 🐻Databricks-Certified-Professional-Data-Engineer Valid Vce Dumps
- Best Databricks-Certified-Professional-Data-Engineer : Databricks Certified Professional Data Engineer Exam Exam Torrent Provide Three Versions for choosing 🐂 Open 「 www.examcollectionpass.com 」 and search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to download exam materials for free 🍰Actual Databricks-Certified-Professional-Data-Engineer Tests
- Precise Valid Databricks-Certified-Professional-Data-Engineer Test Syllabus | Perfect Reliable Databricks-Certified-Professional-Data-Engineer Exam Registration and Complete Databricks Certified Professional Data Engineer Exam Learning Mode 💠 Copy URL ▶ www.pdfvce.com ◀ open and search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ to download for free 📉Databricks-Certified-Professional-Data-Engineer Braindumps Pdf
- Databricks-Certified-Professional-Data-Engineer Complete Exam Dumps 🪐 Exam Databricks-Certified-Professional-Data-Engineer Review ⛺ Databricks-Certified-Professional-Data-Engineer Latest Test Fee 🤳 Download ➽ Databricks-Certified-Professional-Data-Engineer 🢪 for free by simply entering ☀ www.testkingpass.com ️☀️ website 🌕Official Databricks-Certified-Professional-Data-Engineer Practice Test
- Databricks - High Hit-Rate Databricks-Certified-Professional-Data-Engineer - Valid Databricks Certified Professional Data Engineer Exam Test Syllabus 🦞 Search for 【 Databricks-Certified-Professional-Data-Engineer 】 and download exam materials for free through ➽ www.pdfvce.com 🢪 📏Actual Databricks-Certified-Professional-Data-Engineer Tests
- Databricks-Certified-Professional-Data-Engineer Latest Exam Online 🟨 Actual Databricks-Certified-Professional-Data-Engineer Tests 🍢 Official Databricks-Certified-Professional-Data-Engineer Practice Test 🚁 Download ➠ Databricks-Certified-Professional-Data-Engineer 🠰 for free by simply entering ▷ www.examcollectionpass.com ◁ website 🚏Databricks-Certified-Professional-Data-Engineer Braindumps Pdf
- Databricks - High Hit-Rate Databricks-Certified-Professional-Data-Engineer - Valid Databricks Certified Professional Data Engineer Exam Test Syllabus 📸 Search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ and download exam materials for free through ➤ www.pdfvce.com ⮘ 🔉Reliable Databricks-Certified-Professional-Data-Engineer Test Dumps
- www.easy4engine.com Databricks-Certified-Professional-Data-Engineer Exam Dumps Offers Exam Passing Money Back Guarantee 🦰 The page for free download of 「 Databricks-Certified-Professional-Data-Engineer 」 on ( www.easy4engine.com ) will open immediately 🥠Actual Databricks-Certified-Professional-Data-Engineer Tests
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.intensedebate.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes