Passing the Designing and Implementing Multi-Agent AI Solutions (AI-500) exam requires the ability to manage time effectively. In addition to the Microsoft AI-500 exam study materials, practice is essential to prepare for and pass the Microsoft AI-500 Exam on the first try. It is critical to do self-assessment and learn time management skills.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 2: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Evaluate solution quality
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security
|
| Topic 4: Develop multi-agent solutions in Azure | 30-35% | - Design and implement advanced prompt engineering strategies
|
>> AI-500 Latest Exam Discount <<
There are only key points in our AI-500 Training Materials. From the experience of our former customers, you can finish practicing all the contents in our training materials within 20 to 30 hours, which is enough for you to pass the AI-500 exam as well as get the related certification. That is to say, you can pass the Designing and Implementing Multi-Agent AI Solutions exam as well as getting the related certification only with the minimum of time and efforts under the guidance of our training materials. So what you are waiting for? Just come and buy them!
NEW QUESTION # 26
You have a Microsoft Foundry multi-agent solution that uses Microsoft Agent Framework and LangGraph.
Telemetry from the workload is sent to Application Insights.
You need to implement observability components to meet the following requirements:
* Support the investigation of user interactions across agents, models, tools, functions, and API boundaries without relying on verbose production logs.
* Produce recurring and comparable measurements of deployed response quality and safety over time.
What should you use? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Runtime instrumentation: OpenTelemetry distributed tracing with correlation IDs; Post-deployment assessment: A scheduled evaluation that uses test datasets.
Distributed tracing is the correct runtime mechanism because the objective is to reconstruct a user interaction across agents, models, tools, functions, and API boundaries without relying on verbose log text. Microsoft Foundry uses OpenTelemetry-compatible traces and Application Insights so related spans can be correlated into one execution path. Correlation identifiers allow operators to isolate one conversation and inspect where latency, failures, or unexpected behavior originated. The second requirement is different: it asks for recurring, comparable measurements of deployed response quality and safety. Scheduled evaluations against stable test datasets provide that longitudinal benchmark and are more appropriate than ad hoc tracing or infrastructure- only dashboards. Together, OpenTelemetry answers "what happened in this run?" while scheduled evaluation answers "is behavior getting better or worse over time?" The selected pair therefore covers both operational diagnosis and quality regression monitoring. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry observability concepts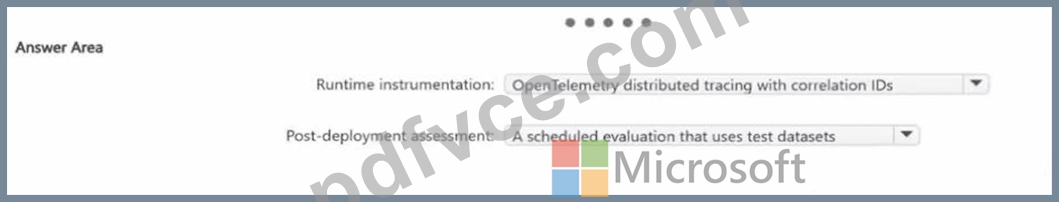
NEW QUESTION # 27
You have a Microsoft Foundry agent that handles customer support chats. The agent has two tools named get_contract_terms and calculate_refund.
On turns where refunds must be calculated, the agent inconsistently calls the tools.
You need to reliably force refund-estimate turns to call calculate_refund.
Which request configuration should you use?
Answer: A
Explanation:
The requirement is to force one specific tool, `calculate_refund`, whenever the application determines that a refund estimate is required. A named function in `tool_choice` removes ambiguity by directing the model to invoke that exact function. `tool_choice: " auto " ` allows the model to decide whether to call a tool and which tool to use. `tool_choice: " required " ` forces some tool call but does not guarantee that `calculate_refund` is selected when multiple tools are available. A natural-language instruction remains probabilistic and is not equivalent to an API-level enforcement setting. Microsoft ' s function-calling API documents named tool choice as the deterministic way to force a specific function. Therefore A is correct. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure OpenAI - Function calling and tool choice
NEW QUESTION # 28
You are designing a multitenant software as a service (SaaS) platform that uses multiple agents. Users will send latency-sensitive inference requests to the platform by using a shared API.
Initially, there will be 20 tenants, and the platform will expand to 200 tenants.
You need to identify the compute component for a production agent runtime. The solution must meet the following requirements:
Isolate workloads for each tenant by using containerization.
Dynamically scale based on demand.
Minimize administrative effort.
What should you use?
Answer: A
NEW QUESTION # 29
You have a Microsoft Agent Framework solution for customer support that includes the following agents:
* A triage agent
* A refund specialist agent that runs in the same process as the triage agent
* A compliance review agent that is exposed by a partner team as a remote service You need to identify which integration components the triage agent will use to coordinate interactions with the other agents.
What should you identify for each agent? To answer, drag the appropriate components to the correct agents Each component may be used once, more than once, or not at all You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.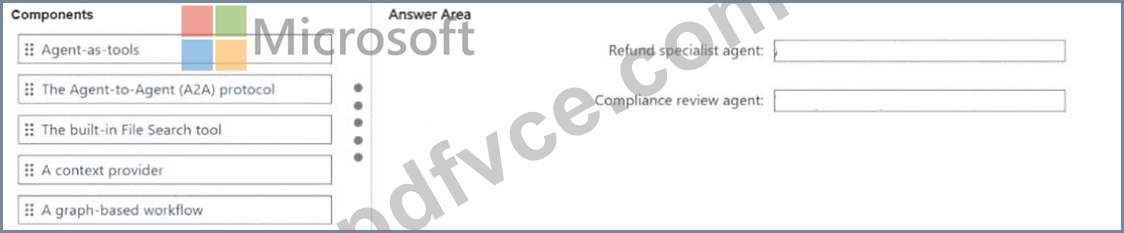
Answer:
Explanation:
Explanation:
Refund specialist agent: Agent-as-tools; Compliance review agent: Agent-to-Agent (A2A) protocol.
The refund specialist runs in the same process as the triage agent, so exposing it as an agent-as-tool is the lightweight composition pattern. The outer triage agent can decide when to invoke the specialist while retaining overall task ownership. The compliance reviewer is different: it is a remote service owned by a partner team. Agent-to-Agent (A2A) is the interoperable protocol intended for independently hosted agents that may use a different runtime or framework. It supports capability discovery and remote task interaction without coupling the caller to the partner ' s implementation. Using A2A for the in-process specialist would add unnecessary network/protocol complexity, while treating the partner agent as an in-process tool would not match the deployment boundary. The two selections therefore reflect Microsoft ' s distinction between local agent composition and remote agent interoperability. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Agent Framework - agents as tools and A2A
NEW QUESTION # 30
You have a Microsoft Foundry multi-agent solution. The solution includes an orchestrator that uses Azure Al Search as a semantic cache to shortlist agents and invokes the top match.
You have a version-controlled repository that contains a curated dataset, expected routing, and expected responses. A pull request adds an agent named Agent 1, new sample utterances, and a changed selector prompt.
You need to configure an automated prerelease evaluation gate for the pull request. The solution must meet the following requirements:
* Validate the integrated system response after the new agent is available to orchestration.
* Validate the semantic cache retrieval quality against the expected results.
* Keep regression tests aligned with the pull request changes.
How should you configure the evaluation gate? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: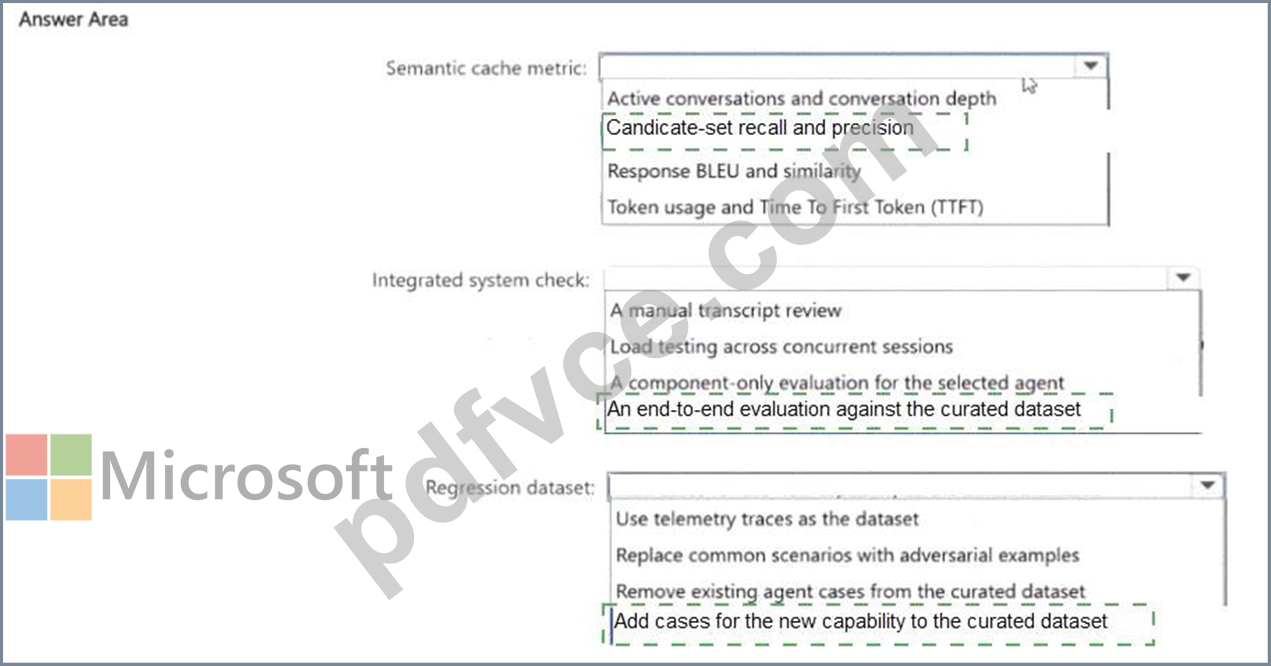
Explanation:
Semantic cache metric: Candidate-set recall and precision; Integrated system check: An end-to-end evaluation against the curated dataset; Regression dataset: Add cases for the new capability to the curated dataset.
The semantic cache is acting as a retrieval/shortlisting component, so recall and precision are the appropriate measures of whether expected agent candidates are surfaced and whether irrelevant candidates are avoided.
The pull request also changes the selector prompt and adds an agent, so component-only tests are insufficient; an end-to-end evaluation must exercise retrieval, routing, the new agent, and final response generation together. Finally, the version-controlled regression dataset should evolve with the capability. Adding representative cases for the new agent keeps expected routing and responses aligned with the code and prompt changes in the pull request. Microsoft Foundry evaluation guidance treats curated datasets as reusable regression assets for CI/CD quality gates. Together, these three selections test retrieval quality, integrated behavior, and regression coverage at the correct layers. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - evaluation datasets and CI/CD evaluation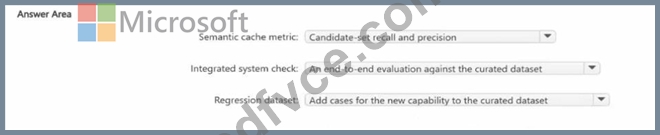
NEW QUESTION # 31
......
Luckily, we are going to tell you a good new that the demo of the AI-500 study materials are easily available in our company. If you buy the study materials from our company, we are glad to offer you with the best demo of our study materials. You will have a deep understanding of the AI-500 Study Materials from our company, and then you will find that the study materials from our company will very useful and suitable for you to prepare for you AI-500 exam.
Minimum AI-500 Pass Score: https://www.pdfvce.com/Microsoft/AI-500-exam-pdf-dumps.html