Updated DEA-C02–100% Free Exam Objectives Pdf | Valid DEA-C02 Exam Experience

P.S. Free & New DEA-C02 dumps are available on Google Drive shared by SurePassExams: https://drive.google.com/open?id=1s5pm7lLOaYEUWeosBPvXd2be7mNsgG9A
Most people now like to practice DEA-C02 study braindumps on computer or phone, but I believe there are nostalgic people like me who love paper books. The PDF version of our DEA-C02 actual exam supports printing. This PDF version also supports mobile phone scanning, so that you can make full use of fragmented time whenever and wherever possible. And the PDF version of our DEA-C02 learning guide can let you free from the constraints of the network, so that you can do exercises whenever you want.
| Section | Weight | Objectives |
|---|
| Data Architecture and Processing | 20% | - Data Storage Architecture
- 1. Micro-partitioning and clustering
- 2. Hybrid Tables concepts
- 3. Table types (Permanent, Transient, Temporary)
- Data Pipeline Design
- 1. Pipeline monitoring and error handling
- 2. Stream and task patterns
- 3. Data scheduling and orchestration
- Data Modeling for Performance
- 1. Slowly changing dimensions (SCD)
- 2. Star and snowflake schemas
- 3. Dimension handling
|
| Performance Optimization | 15% | - Query Optimization
- 1. Query profiling and analysis
- 2. Query result caching
- 3. Indexing strategies with clustering
- 4. Avoiding common performance pitfalls
- Data Optimization
- 1. Materialized views
- 2. Data cache management
- 3. Search optimization service
- Warehouse Performance
- 1. Multi-cluster warehouses
- 2. Warehouse scaling policies
- 3. Warehouse sizing and selection
- 4. Resource monitors
|
| Data Transformation with Snowflake | 30% | - Snowflake Scripting
- 1. Procedures and control flow
- 2. Dynamic SQL
- 3. Error handling
- Data Processing Patterns
- 1. MERGE, UPDATE, DELETE operations
- 2. Time travel and change data capture
- 3. Zero-copy cloning for ETL
- SQL Transformations
- 1. Window functions advanced usage
- 2. Working with semi-structured data (VARIANT)
- 3. Data type conversions and handling
- 4. Complex JOINs and set operations
|
| Data Ingestion and Consumption | 20% | - Data Unloading
- 1. Partitioning unloading data
- 2. Data export best practices
- 3. Unloading to internal and external stages
- Bulk Loading and Unloading
- 1. Data loading performance optimization
- 2. Handling staged files
- 3. COPY INTO command options and best practices
- 4. File format options (CSV, JSON, Parquet, AVRO)
- Continuous Data Loading
- 1. Snowpipe configuration and usage
- 2. Automating data loading with tasks
- 3. Real-time data ingestion patterns
|
| Security and Governance | 15% | - Governance and Compliance
- 1. Access history and auditing
- 2. Data retention policies
- 3. Object tagging
- 4. Row access policies
- Data Security
- 1. External tokenization
- 2. Column-level security
- 3. Data masking and tokenization
- 4. Row-level security policies
- Access Control
- 1. Role-based access control (RBAC)
- 2. Role hierarchy and ownership
- 3. GRANT and REVOKE operations
|
>> DEA-C02 Exam Objectives Pdf <<
Valid DEA-C02 Exam Experience | Reliable DEA-C02 Test Sample
SurePassExams is a website specifically provide the certification exam information sources for Snowflake professionals. Through many reflects from people who have purchase SurePassExams's products, SurePassExams is proved to be the best website to provide the source of information about DEA-C02 Certification Exam. The product of DEA-C02 is a very reliable training tool for you. The answers of the exam exercises provided by SurePassExams is very accurate. Our SurePassExams's senior experts are continuing to enhance the quality of our training materials.
Snowflake SnowPro Advanced: Data Engineer (DEA-C02) Sample Questions (Q285-Q290):
NEW QUESTION # 285
A data engineering team uses Snowflake to analyze website clickstream data stored in AWS S3. The data is partitioned by year and month in the S3 bucket. They need to query the data frequently for reporting purposes but don't want to ingest the entire dataset into Snowflake due to storage costs and infrequent full dataset analysis. Which approach is the MOST efficient and cost-effective way to enable querying of this data in Snowflake?
- A. Create a Snowpipe pointing to the S3 bucket and ingest the data continuously into a Snowflake table.
- B. Use Snowflake's COPY INTO command to ingest data directly from S3 into a Snowflake table on a scheduled basis.
- C. Create a Snowflake internal stage, copy the necessary files into the stage, and then load the data into a Snowflake table.
- D. Load all the data into a Snowflake table and create a materialized view on top of the table to pre-aggregate the data for reporting.
- E. Create a Snowflake external stage pointing to the S3 bucket, define an external table on the stage, and use partitioning metadata to optimize queries.
Answer: E
Explanation:
Using an external table pointing to the S3 bucket is the most efficient and cost-effective approach. It allows you to query the data directly in S3 without ingesting it into Snowflake, saving on storage costs. Partitioning metadata further optimizes query performance by allowing Snowflake to only scan relevant partitions based on the query criteria.
NEW QUESTION # 286
You are managing a Snowflake environment where data retention is set to the default 1 day for all databases and tables. You need to clone a production table, 'CUSTOMER DATA, to a development environment to test some complex transformations. However, after cloning, you realize that the original 'CUSTOMER DATA' table in production was accidentally dropped 2 days ago. Which of the following statements accurately describe the situation and what can be done, if anything?
- A. While the source 'CUSTOMER DATA' is dropped and outside the retention period, the clone created will remain available and fully functional for querying. It is an independent copy. The clone is usable indefinitely, within the limits of your Snowflake account storage.
- B. The cloned 'CUSTOMER DATA' table will only remain accessible if the source database was also cloned at the same time. If only the table was cloned, the cloned table is unusable after 1 day.
- C. The cloned 'CUSTOMER DATA' table in the development environment will no longer be accessible because the source table has been dropped and the data retention period has expired. The clone is effectively useless.
- D. The cloned 'CUSTOMER DATA' table in the development environment will inherit the data retention period from the original 'CUSTOMER DATA' table, so it will also be inaccessible after 1 day if dropped in development.
- E. The cloned 'CUSTOMER DATA' table in the development environment will remain accessible because the clone operation created a point-in-time snapshot.
Answer: A
Explanation:
Cloning creates a separate, independent copy of the table's metadata and data at the time of the clone operation. Even if the original table is dropped and the data retention period has passed for the original table, the cloned table remains accessible and fully functional, as it has its own independent copy of the data. Option B is incorrect as future changes to DEV will be recoverable based on DEV retention settings which can be independent from PROD.
NEW QUESTION # 287
A data engineer is tasked with implementing a data governance strategy in Snowflake. They need to automatically apply a tag 'PII CLASSIFICATION' to all columns containing Personally Identifiable Information (PII). Given the following requirements: 1. The tag must be applied as close to data ingestion as possible. 2. The tagging process should be automated and scalable. 3. The tag value should be dynamically set based on a regular expression match against column names and data types. Which of the following approaches would be MOST effective and efficient in achieving these goals?
- A. Create a Snowflake Task that runs daily, querying the INFORMATION SCHEMCOLUMNS view, identifying potential PII columns based on regular expressions, and then executing ALTER TABLE ... ALTER COLUMN ... SET TAG commands.
- B. Manually tag each column containing PII using the Snowflake web UI or the 'ALTER TABLE ... ALTER COLUMN ... SET TAG' command. Train data stewards to identify and tag new columns.
- C. Implement a custom application using the Snowflake JDBC driver to periodically scan table schemas, detect PII columns, and apply tags using dynamic SQL.
- D. Use Snowflake's Event Tables in conjunction with a stream and task. Configure the stream to capture DDL changes, and the task to evaluate new columns and apply the tag based on the column metadata using regular expressions.
- E. Implement a stored procedure that leverages external functions to call a Python script hosted on AWS Lambda, which uses a machine learning model to identify PII and apply Snowflake tags.
Answer: D
Explanation:
Option C is the most effective because it leverages Snowflake's native event capture mechanisms (Event Tables, Streams and Tasks) to react to DDL changes in near real-time. This approach is automated, scalable, and avoids the overhead of periodic polling. Options A and B involve periodic scanning which is less efficient. Option D is manual and doesn't scale. Option E introduces unnecessary complexity with external functions and ML models for a relatively simple task, increasing operational overhead.
NEW QUESTION # 288
You are tasked with ingesting data from an external stage into Snowflake. The data is in JSON format and compressed using GZIP. The JSON files contain nested arrays. You need to create a file format object that Snowflake can use to properly parse the dat a. Which of the following options represents the MOST efficient and correct file format definition to achieve this? Assume the stage is already created and accessible.
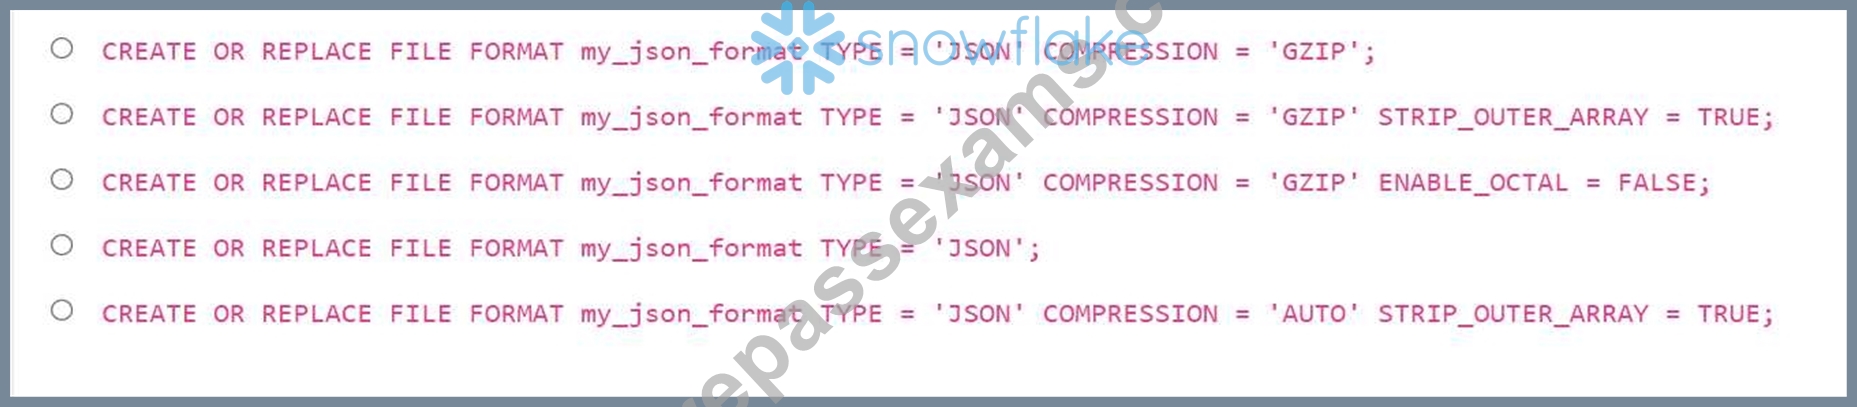
- A. Option D
- B. Option B
- C. Option C
- D. Option E
- E. Option A
Answer: B
Explanation:
Option B is the most efficient and correct. The COMPRESSION = 'GZIP' parameter is necessary to handle the GZIP compression. 'STRIP OUTER ARRAY = TRUE is crucial when dealing with JSON files containing nested arrays or a single outer array, which is a common scenario for data coming from external sources. It allows Snowflake to correctly parse each element of the array as a separate row. Option A is incorrect because it doesn't address the potential outer array structure. Option C is incorrect because 'ENABLE OCTAL' is not relevant to the array structure issue. Option D is incorrect as it lacks the compression parameter. Option E is also suitable , but gzip is better performance than AUTO.
NEW QUESTION # 289
A financial services company is using Snowflake Streams on a table 'TRANSACTIONS' to capture changes for auditing purposes. The 'TRANSACTIONS' table contains sensitive data, and the auditing team requires the stream to only capture changes to specific columns: 'ACCOUNT ID', 'TRANSACTION DATE', and 'TRANSACTION AMOUNT'. Which of the following approaches is the MOST efficient and secure way to achieve this requirement, ensuring minimal performance impact and data exposure?
- A. Create a View that selects only the 'ACCOUNT ID, 'TRANSACTION DATE, and 'TRANSACTION AMOUNT columns and create a Stream on the View.
- B. Create a Stream on the 'TRANSACTIONS' table and use a masking policy on the stream's output to redact the unnecessary columns.
- C. Create a standard Stream on the 'TRANSACTIONS table and then filter the results in downstream processing to only include the required columns.
- D. Create a Stream on the 'TRANSACTIONS' table. Periodically truncate stream and reload all data from TRANSACTION table by applying filter while loading.
- E. Create a task that clones the TRANSACTIONS table and a stream on that cloned table, limiting what changes are captured using a WHERE clause on the cloning command.
Answer: A
Explanation:
Creating a View that selects only the required columns and then creating a Stream on the View is the most efficient and secure approach. It limits the data exposed to the Stream from the outset, minimizing performance impact and ensuring that sensitive data is not unnecessarily captured in the Stream. Option A exposes all columns initially, which violates security. Option C masks data after it's been captured, still exposing it to the stream. Option D would lose change tracking and reloads all data instead of only changes and E can lead to data duplication.
NEW QUESTION # 290
......
Of course, when we review a qualifying exam, we can't be closed-door. We should pay attention to the new policies and information related to the test DEA-C02 certification. For the convenience of the users, the DEA-C02 test materials will be updated on the homepage and timely update the information related to the qualification examination. Annual qualification examination, although content broadly may be the same, but as the policy of each year, the corresponding examination pattern grading standards and hot spots will be changed, the DEA-C02 Test Prep can help users to spend the least time to pass the exam.
Valid DEA-C02 Exam Experience: https://www.surepassexams.com/DEA-C02-exam-bootcamp.html
- DEA-C02 Valid Exam Pattern 🌘 DEA-C02 Practice Test Online 🪕 Reliable DEA-C02 Exam Voucher 🍨 ▛ www.examcollectionpass.com ▟ is best website to obtain ▛ DEA-C02 ▟ for free download 🔋DEA-C02 Pass Guide
- Snowflake DEA-C02 PDF Dumps - Effective Preparation Material [2026] 🎵 Search for ➥ DEA-C02 🡄 and obtain a free download on 《 www.pdfvce.com 》 🐟Test DEA-C02 Cram Review
- Pass Guaranteed Quiz DEA-C02 - SnowPro Advanced: Data Engineer (DEA-C02) Perfect Exam Objectives Pdf 📋 Download ⏩ DEA-C02 ⏪ for free by simply searching on ▷ www.easy4engine.com ◁ 🎷Reliable DEA-C02 Test Prep
- Quiz Realistic DEA-C02 Exam Objectives Pdf - Valid SnowPro Advanced: Data Engineer (DEA-C02) Exam Experience 😯 Open ➽ www.pdfvce.com 🢪 enter { DEA-C02 } and obtain a free download 📽New DEA-C02 Dumps Files
- 2026 Pass-Sure DEA-C02: SnowPro Advanced: Data Engineer (DEA-C02) Exam Objectives Pdf 🌌 Enter ▛ www.examdiscuss.com ▟ and search for ➡ DEA-C02 ️⬅️ to download for free 🦯DEA-C02 Valid Exam Pattern
- Updated DEA-C02 Exam Objectives Pdf - Guaranteed Snowflake DEA-C02 Exam Success with Well-Prepared Valid DEA-C02 Exam Experience 🛐 ☀ www.pdfvce.com ️☀️ is best website to obtain ▶ DEA-C02 ◀ for free download 🏺DEA-C02 Practice Test Online
- DEA-C02 Exam Objectives Pdf - Quiz 2026 DEA-C02: SnowPro Advanced: Data Engineer (DEA-C02) – First-grade Valid Exam Experience 💉 Go to website [ www.examcollectionpass.com ] open and search for 【 DEA-C02 】 to download for free 🥒Test DEA-C02 Questions Vce
- Snowflake DEA-C02 PDF Dumps - Effective Preparation Material [2026] 🦖 Search on ⮆ www.pdfvce.com ⮄ for ⮆ DEA-C02 ⮄ to obtain exam materials for free download 🩱Latest DEA-C02 Test Simulator
- Free PDF 2026 DEA-C02: Trustable SnowPro Advanced: Data Engineer (DEA-C02) Exam Objectives Pdf 🎊 Immediately open ⮆ www.practicevce.com ⮄ and search for ⏩ DEA-C02 ⏪ to obtain a free download 🔮DEA-C02 Pass Guide
- DEA-C02 Practice Test Online 🎠 DEA-C02 Valid Exam Pattern 📽 Latest DEA-C02 Test Online ✋ Search on ➽ www.pdfvce.com 🢪 for ☀ DEA-C02 ️☀️ to obtain exam materials for free download 🖖Test DEA-C02 Questions Vce
- DEA-C02 Valid Braindumps Pdf 🍇 DEA-C02 Pass Guide ❤ Latest DEA-C02 Test Online 🦠 Search for ▶ DEA-C02 ◀ and download it for free on [ www.troytecdumps.com ] website ↪Reliable DEA-C02 Exam Voucher
- learn.csisafety.com.au, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, fakescam.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, pixabay.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
2026 Latest SurePassExams DEA-C02 PDF Dumps and DEA-C02 Exam Engine Free Share: https://drive.google.com/open?id=1s5pm7lLOaYEUWeosBPvXd2be7mNsgG9A