Free PDF Databricks - Latest Certified-Data-Engineer-Professional - New Databricks Certified Data Engineer Professional Test Registration

Based on high-quality products, our Certified-Data-Engineer-Professional guide torrent has high quality to guarantee your test pass rate, which can achieve 98% to 100%. Certified-Data-Engineer-Professional study tool is updated online by our experienced experts, and then sent to the user. So you don’t need to pay extra attention on the updating of study materials. The data of our Certified-Data-Engineer-Professional exam torrent is forward-looking and can grasp hot topics to help users master the latest knowledge. If you fail the exam with Certified-Data-Engineer-Professional Guide Torrent, we promise to give you a full refund in the shortest possible time. Of course, if you are not reconciled and want to re-challenge yourself again, we will give you certain discount.
| Section | Objectives |
|---|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create pipeline components using control flow operators such as if/else and foreach
- 2. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 3. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 4. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 5. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 6. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 2. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
|
| Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
>> New Certified-Data-Engineer-Professional Test Registration <<
Certified-Data-Engineer-Professional valid Pass4sures torrent & Certified-Data-Engineer-Professional useful study vce
With the development of society and the perfection of relative laws and regulations, the Certified-Data-Engineer-Professional certificate in our career field becomes a necessity for our country. Passing the Certified-Data-Engineer-Professional and obtaining the certificate may be the fastest and most direct way to change your position and achieve your goal. And we are just right here to give you help to pass the Certified-Data-Engineer-Professional Exam. Being considered the most authentic brand in this career, our professional experts are making unremitting efforts to provide our customers the latest and valid Certified-Data-Engineer-Professional exam simulation.
Databricks Certified Data Engineer Professional Sample Questions (Q249-Q254):
NEW QUESTION # 249
The data engineering team maintains the following code:
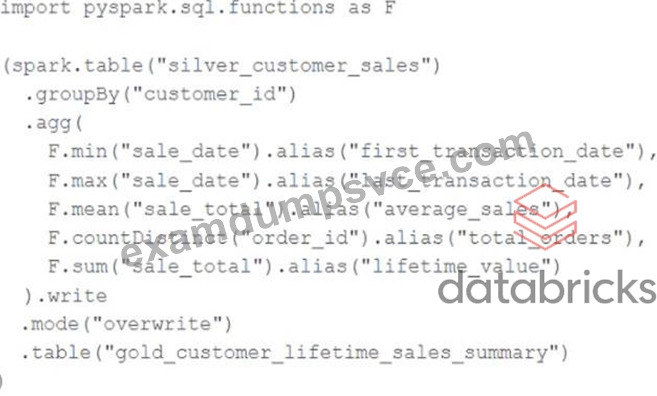
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job.
- B. A batch job will update the gold_customer_lifetime_sales_summary table, replacing only those rows that have different values than the current version of the table, using customer_id as the primary key.
- C. An incremental job will leverage running information in the state store to update aggregate values in the gold_customer_lifetime_sales_summary table.
- D. An incremental job will detect if new rows have been written to the silver_customer_sales table; if new rows are detected, all aggregates will be recalculated and used to overwrite the gold_customer_lifetime_sales_summary table.
- E. The silver_customer_sales table will be overwritten by aggregated values calculated from all records in the gold_customer_lifetime_sales_summary table as a batch job.
Answer: A
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids. The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed.
NEW QUESTION # 250
The data engineer team has been tasked with configured connections to an external database that does not have a supported native connector with Databricks. The external database already has data security configured by group membership. These groups map directly to user group already created in Databricks that represent various teams within the company. A new login credential has been created for each group in the external database. The Databricks Utilities Secrets module will be used to make these credentials available to Databricks users. Assuming that all the credentials are configured correctly on the external database and group membership is properly configured on Databricks, which statement describes how teams can be granted the minimum necessary access to using these credentials?
- A. "Read'' permissions should be set on a secret key mapped to those credentials that will be used by a given team.
- B. No additional configuration is necessary as long as all users are configured as administrators in the workspace where secrets have been added.
- C. "Manage" permission should be set on a secret scope containing only those credentials that will be used by a given team.
- D. "Read" permissions should be set on a secret scope containing only those credentials that will be used by a given team.
Answer: D
Explanation:
In Databricks, using the Secrets module allows for secure management of sensitive information such as database credentials. Granting 'Read' permissions on a secret key that maps to database credentials for a specific team ensures that only members of that team can access these credentials. This approach aligns with the principle of least privilege, granting users the minimum level of access required to perform their jobs, thus enhancing security.
NEW QUESTION # 251
A data engineering team is collaborating on a Databricks project where each team member needs to develop and test code independently before merging changes into the main branch.
They want to avoid accidental overwrites or branch switching issues while ensuring that all work is version- controlled and can be integrated into their CI/CD pipeline.
How should the data engineer achieve collaboration?
- A. Team members use the Databricks CLI to clone the Git repository and perform Git operations from a cluster's web terminal.
- B. Team members edit notebooks directly in the workspace's shared folder and periodically copy changes into a Git folder for version control.
- C. Each team member creates their own Databricks Git folder, mapped to the same remote Git repository, and works in their own development branch within their personal folder.
- D. All team members work in the same Databricks Git folder and perform Git operations (pull, push, commit, branch switching) directly in that shared folder.
Answer: C
Explanation:
Using separate Databricks Git folders per user mapped to the same remote repository allows each team member to work independently on their own branch without interfering with others.
This prevents accidental overwrites or branch conflicts while ensuring all changes are version- controlled and easily integrated into CI/CD workflows.
NEW QUESTION # 252
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.
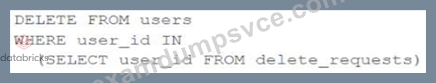
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
- A. Yes; Delta Lake ACID guarantees provide assurance that the delete command succeeded fully and permanently purged these records.
- B. No; files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files.
- C. No; the Delta Lake delete command only provides ACID guarantees when combined with the merge into command.
- D. Yes; the Delta cache immediately updates to reflect the latest data files recorded to disk.
- E. No; the Delta cache may return records from previous versions of the table until the cluster is restarted.
Answer: B
Explanation:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage.
NEW QUESTION # 253
A data engineer is using the AUTO CDC API in Lakeflow Spark Declarative Pipeline to propagate deletions from a source table (orders_source) to a target table (orders_target). The source has Change Data Feed (CDF) enabled, but some delete events arrive out of order due to upstream delays. How does the AUTO CDC API internally ensure deletions are applied correctly despite out-of-order events?
- A. It ignores deletions if they arrive after updates for the same key.
- B. It uses sequence_by to order events and retains tombstones for deleted rows until older sequences are processed.
- C. It runs VACUUM on the target table to purge conflicting records.
- D. It manually sorts incoming events by timestamp before applying changes.
Answer: B
Explanation:
AUTO CDC uses the sequence_by column to deterministically order change events for each key.
Delete operations create tombstones that are retained until all earlier sequence values have been processed, ensuring that out-of-order delete events are still applied correctly and consistently in the target table.
NEW QUESTION # 254
......
Remember that this is a crucial part of your career, and you must keep pace with the changing time to achieve something substantial in terms of a certification or a degree. So do avail yourself of this chance to get help from our exceptional Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) dumps to grab the most competitive Databricks Certified-Data-Engineer-Professional certificate. ExamDumpsVCE has formulated the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) product in three versions. You will find their specifications below to understand them better.
Training Certified-Data-Engineer-Professional Tools: https://www.examdumpsvce.com/Certified-Data-Engineer-Professional-valid-exam-dumps.html
- Certified-Data-Engineer-Professional test valid questions - Certified-Data-Engineer-Professional exam latest torrent - Certified-Data-Engineer-Professional test review dumps 🚊 Download [ Certified-Data-Engineer-Professional ] for free by simply entering [ www.testkingpass.com ] website 💭Vce Certified-Data-Engineer-Professional Download
- Certified-Data-Engineer-Professional new questions - Certified-Data-Engineer-Professional dumps VCE - Certified-Data-Engineer-Professional dump collection 🌽 Search on 《 www.pdfvce.com 》 for ➥ Certified-Data-Engineer-Professional 🡄 to obtain exam materials for free download 🤠Latest Test Certified-Data-Engineer-Professional Experience
- Certified-Data-Engineer-Professional new questions - Certified-Data-Engineer-Professional dumps VCE - Certified-Data-Engineer-Professional dump collection ↘ The page for free download of ▛ Certified-Data-Engineer-Professional ▟ on ⇛ www.exam4labs.com ⇚ will open immediately 💑Certified-Data-Engineer-Professional Valid Test Pattern
- Certified-Data-Engineer-Professional Real Questions 🧡 Certified-Data-Engineer-Professional Test Simulator Fee 🤱 Certified-Data-Engineer-Professional Sample Questions Answers 🦮 Search for ⇛ Certified-Data-Engineer-Professional ⇚ and obtain a free download on { www.pdfvce.com } 🏂Dumps Certified-Data-Engineer-Professional Download
- Certified-Data-Engineer-Professional Valid Test Pattern 💄 Certified-Data-Engineer-Professional Valid Test Pattern 🛅 Certified-Data-Engineer-Professional Test Simulator Fee 🧎 Open ☀ www.examcollectionpass.com ️☀️ and search for ( Certified-Data-Engineer-Professional ) to download exam materials for free 🧀Cost Effective Certified-Data-Engineer-Professional Dumps
- Free PDF 2026 Professional Databricks Certified-Data-Engineer-Professional: New Databricks Certified Data Engineer Professional Test Registration 🦙 “ www.pdfvce.com ” is best website to obtain ➥ Certified-Data-Engineer-Professional 🡄 for free download 💦Latest Certified-Data-Engineer-Professional Test Blueprint
- Latest Test Certified-Data-Engineer-Professional Experience 🔽 Vce Certified-Data-Engineer-Professional Download 🧒 Reliable Certified-Data-Engineer-Professional Exam Cram 🗼 Download ➡ Certified-Data-Engineer-Professional ️⬅️ for free by simply searching on “ www.troytecdumps.com ” 🦄Examcollection Certified-Data-Engineer-Professional Vce
- Top Certified-Data-Engineer-Professional Questions 🏊 Certified-Data-Engineer-Professional Certification Test Answers 🚈 Certified-Data-Engineer-Professional Sample Questions Answers 🚡 The page for free download of ▶ Certified-Data-Engineer-Professional ◀ on { www.pdfvce.com } will open immediately 💭Certified-Data-Engineer-Professional Valid Test Pattern
- Valid New Certified-Data-Engineer-Professional Test Registration - Pass Guaranteed Training Certified-Data-Engineer-Professional Tools: Databricks Certified Data Engineer Professional 😘 Search for ➥ Certified-Data-Engineer-Professional 🡄 on ✔ www.practicevce.com ️✔️ immediately to obtain a free download 😊Certified-Data-Engineer-Professional Certification Test Answers
- Certified-Data-Engineer-Professional Books PDF 🏘 Reliable Certified-Data-Engineer-Professional Exam Cram 🧭 Certified-Data-Engineer-Professional Useful Dumps 😦 Simply search for ➠ Certified-Data-Engineer-Professional 🠰 for free download on ▶ www.pdfvce.com ◀ 👲Cost Effective Certified-Data-Engineer-Professional Dumps
- Pass Guaranteed Quiz Databricks - Unparalleled Certified-Data-Engineer-Professional - New Databricks Certified Data Engineer Professional Test Registration 🤮 Easily obtain 《 Certified-Data-Engineer-Professional 》 for free download through 【 www.prepawayete.com 】 🔥Certified-Data-Engineer-Professional Sample Questions Answers
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes