Although at this moment, the pass rate of our Nutanix NCM-MCI-6.10 exam braindumps can be said to be the best compared with that of other exam tests, our experts all are never satisfied with the current results because they know the truth that only through steady progress can our Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI) NCM-MCI-6.10 Preparation materials win a place in the field of exam question making forever.
| Section | Objectives |
|---|---|
| Topic 1: Manage and Configure Nutanix Virtual Infrastructure | - Resource scheduling and optimization - VM management and operations - AHV cluster configuration |
| Topic 2: Deploy and Upgrade Nutanix Environments | - Foundation processes - Cluster installation and configuration - Software and firmware upgrades |
| Topic 3: Analyze and Remediate Performance Issues | - Troubleshooting network performance - Troubleshooting storage performance - Performance monitoring and metrics |
| Topic 4: Troubleshoot and Resolve Complex Issues | - Cluster health management - Failure recovery procedures - Log analysis and diagnostics |
| Topic 5: Configure and Manage Nutanix Networking | - Network segmentation and microsegmentation - Advanced networking scenarios - AHV networking configuration |
| Topic 6: Manage and Optimize Nutanix Storage | - Storage optimization and efficiency - Storage container and VDisk management - Data protection and disaster recovery |
| Topic 7: Implement and Manage Security and Compliance | - Security hardening - Compliance frameworks - Access control and authentication |
>> NCM-MCI-6.10 Latest Test Dumps <<
Only high-quality and high-precision NCM-MCI-6.10 qualification question can enable learners to be confident to take the qualification examination, and our NCM-MCI-6.10 learning materials are such high-quality learning materials, it can meet the user to learn the most popular test site knowledge. Because our experts have extracted the frequent annual test centers are summarized to provide users. Only excellent learning materials such as our NCM-MCI-6.10 Study Tool can meet the needs of the majority of candidates, and now you should make the most decision is to choose our NCM-MCI-6.10 exam questions.
NEW QUESTION # 12
Task 5
An administrator has noticed that after a host failure, the SQL03 VM was not powered back on from another host within the cluster. The Other SQL VMs (SQL01, SQL02) have recovered properly in the past.
Resolve the issue and configure the environment to ensure any single host failure affects a minimal number os SQL VMs.
Note: Do not power on any VMs
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
One possible reason why the SQL03 VM was not powered back on after a host failure is that the cluster was configured with the default (best effort) VM high availability mode, which does not guarantee the availability of VMs in case of insufficient resources on the remaining hosts. To resolve this issue, I suggest changing the VM high availability mode to guarantee (reserved segments), which reserves some memory on each host for failover of VMs from a failed host. This way, the SQL03 VM will have a higher chance of being restarted on another host in case of a host failure.
To change the VM high availability mode to guarantee (reserved segments), you can follow these steps:
Log in to Prism Central and select the cluster where the SQL VMs are running.
Click on the gear icon on the top right corner and select Cluster Settings.
Under Cluster Services, click on Virtual Machine High Availability.
Select Guarantee (Reserved Segments) from the drop-down menu and click Save.
To configure the environment to ensure any single host failure affects a minimal number of SQL VMs, I suggest using anti-affinity rules, which prevent VMs that belong to the same group from running on the same host. This way, if one host fails, only one SQL VM will be affected and the other SQL VMs will continue running on different hosts.
To create an anti-affinity rule for the SQL VMs, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Group.
Enter a name for the group, such as SQL Group, and click Next.
Select the SQL VMs (SQL01, SQL02, SQL03) from the list and click Next.
Select Anti-Affinity from the drop-down menu and click Next.
Review the group details and click Finish.
I hope this helps. How else can I help?
https://portal.nutanix.com/page/documents/details?targetId=AHV-Admin-Guide-v6_5:ahv-affinity-policies-c.html
A screenshot of a computer Description automatically generated with medium confidence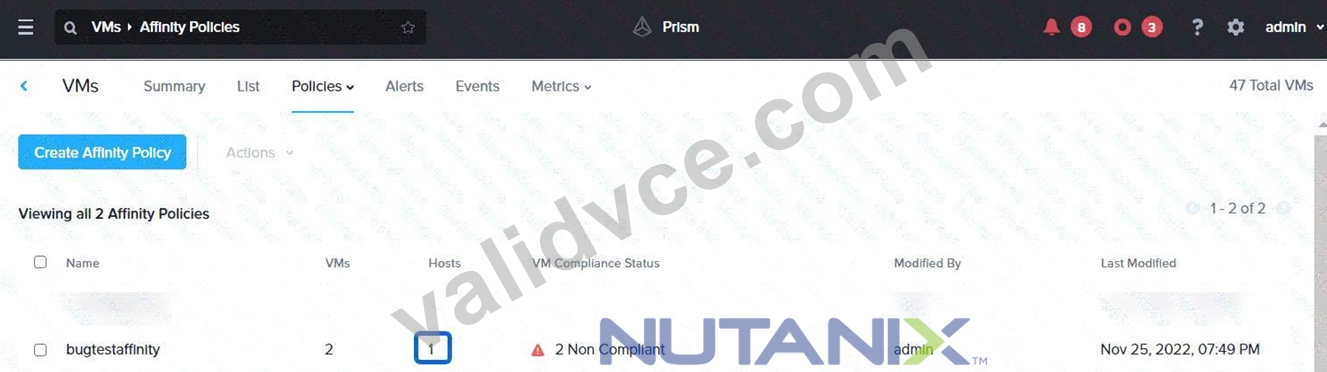
NEW QUESTION # 13
Task 3
An administrator needs to create a report named VMs_Power_State that lists the VMs in the cluster and their basic details including the power state for the last month.
No other entities should be included in the report.
The report should run monthly and should send an email to admin@syberdyne.net when it runs.
Generate an instance of the report named VMs_Power_State as a CSV and save the zip file as Desktop\Files\VMs_Power_state.zip Note: Make sure the report and zip file are named correctly. The SMTP server will not be configured.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To create a report named VMs_Power_State that lists the VMs in the cluster and their basic details including the power state for the last month, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Report.
Enter VMs_Power_State as the report name and a description if required. Click Next.
Under the Custom Views section, select Data Table. Click Next.
Under the Entity Type option, select VM. Click Next.
Under the Custom Columns option, add the following variables: Name, Cluster Name, vCPUs, Memory, Power State. Click Next.
Under the Time Period option, select Last Month. Click Next.
Under the Report Settings option, select Monthly from the Schedule drop-down menu. Enter admin@syberdyne.net as the Email Recipient. Select CSV as the Report Output Format. Click Next.
Review the report details and click Finish.
To generate an instance of the report named VMs_Power_State as a CSV and save the zip file as Desktop\Files\VMs_Power_state.zip, you can follow these steps:
Log in to Prism Central and click on Operations on the left menu.
Select Reports from the drop-down menu and find the VMs_Power_State report from the list. Click on Run Now.
Wait for the report to be generated and click on Download Report. Save the file as Desktop\Files\VMs_Power_state.zip.
1.Open the Report section on Prism Central (Operations > Reports)
2.Click on the New Report button to start the creation of your custom report
3.Under the Custom Views section, select Data Table
4.Provide a title to your custom report, as well as a description if required.
5.Under the Entity Type option, select VM
6.This report can include all as well as a selection of the VMs
7.Click on the Custom Columns option and add the below variables:
a.Name - Name of the listed Virtual Machine
b.vCPUs - A combination of the vCores and vCPU's assigned to the Virtual Machine c.Memory - Amount of memory assigned to the Virtual Machine d.Disk Capacity - The total amount of assigned virtual disk capacity e.Disk Usage - The total used virtual disk capacity f.Snapshot Usage - The total amount of capacity used by snapshots (Excluding Protection Domain snapshots)
8.Under the Aggregation option for Memory and Disk Usage accept the default Average option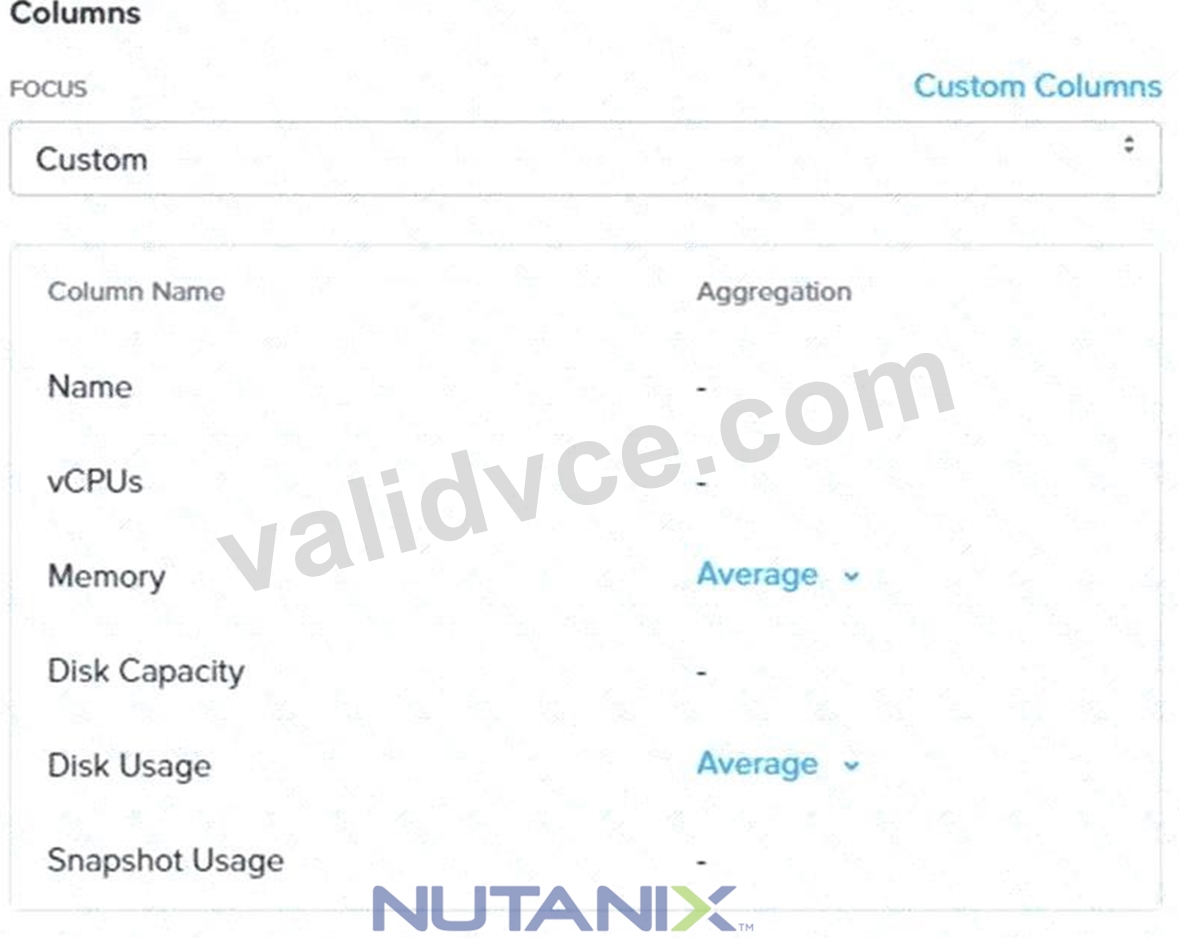
9.Click on the Add button to add this custom selection to your report
10.Next click on the Save and Run Now button on the bottom right of the screen
11.Provide the relevant details on this screen for your custom report:
12.You can leave the Time Period For Report variable at the default of Last 24 Hours
13.Specify a report output of preference (PDF or CSV) and if required Additional Recipients for this report to be mailed to. The report can also simply be downloaded after this creation and initial run if required
14.Below is an example of this report in a CSV format:
NEW QUESTION # 14
An administrator regularly sees a WARN for backup_schedule_check and also receives alerts for Pulse not being enabled on Cluster 1.
Detailed information for backup_schedule_check:
Node xx.xx.xx.xx:
WARN: Backup schedule(s) exist for protection domain NoVMs; however, there are no entities in the protection domain.
Refer
to KB 1910 (http://portal.nutanix.com/kb/1910) for details on backup_schedule_check or Recheck with: ncc health_checks data_protection_checks protection_domain_checks backup_schedule_check.
This shows up in NCC, however, it is something set up by the company and they do not want the NCC check to be run.
Configure Cluster 1 to no longer have messages in NCC about the backup_schedule_check.
Turn off the alert for Pulse not being enabled, and resolve the alert. They would like messages about Pulse to be recorded, but do not want an alert.
Note: You may need to run the "Pulse is not enabled" check in order to have one to resolve.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure Cluster 1 from its Prism Element interface.
1. Disable the backup_schedule_check NCC Check
This will prevent the WARN message for the NoVMs protection domain.
* Log in to the Cluster 1 Prism Element (PE) interface.
* Navigate to the Health dashboard (click the "heart" icon in the top-left).
* In the left-hand menu, select NCC.
* In the search bar for the checks, type backup_schedule_check to find the specific check.
* Select the checkbox next to the backup_schedule_check in the list.
* Click the Disable button that appears above the table. This will stop this check from running during NCC health reports.
2. Configure and Resolve Pulse Alerts
This process involves two parts: disabling the alerting policy, and then enabling Pulse itself to resolve the underlying condition.
A. Disable the Alert Policy
This stops the system from generating a new alert if Pulse is ever disabled, satisfying the "do not want an alert" requirement.
* Click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Alert Policies.
* In the search bar, type Pulse to find the policy.
* Select the checkbox for the alert policy named Pulse is not enabled (or pulse_disabled_alert).
* Click the Update button.
* Uncheck the Enable box for the policy.
* Click Save.
B. Enable Pulse (to Resolve the Condition)
This enables the Pulse service to record messages (as requested) and fixes the root cause of the alert, allowing it to be resolved.
* Click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Pulse.
* Click the Enable Pulse button (or "Update" if it's already partially configured).
* Check the box for Enable Pulse.
* (Note: Any "Enable alerts for Pulse" boxes would remain unchecked or be ignored, as the main Alert Policy itself is now disabled.)
* Click Save.
C. Resolve the Active Alert
* Navigate to the Alerts dashboard (click the "bell" icon in the top-left).
* Find the active alert: Pulse is not enabled.
* (Note: If the alert is not present, you would first go to the Health dashboard, run the check_pulse NCC check to generate it, and then return to the Alerts dashboard.)
* Select the checkbox next to the "Pulse is not enabled" alert.
* Click the Resolve button that appears at the top of the list. Since the underlying condition (Pulse being disabled) is now fixed, the alert will be successfully resolved.
NEW QUESTION # 15
An administrator needs to perform AOS and AHV upgrades on a Nutanix cluster and wants to ensure that VM data is replicated as quickly as possible when hosts and CVMs are rebooted.
Configure Cluster 1 so that after planned host and CVM reboots, the rebuild scan starts immediately.
Note:
You will need to use SSH for this task. Ignore the fact that this is a 1-node cluster.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure the immediate rebuild scan on Cluster 1.
This task must be performed from an SSH session connected to a CVM (Controller VM) on Cluster 1.
1. Access the Cluster 1 CVM
* From the Prism Central dashboard, navigate to Hardware > Clusters and click on Cluster 1 to open its Prism Element (PE) interface.
* In the Cluster 1 PE, navigate to Hardware > CVMs to find the IP address of any CVM in the cluster.
* Use an SSH client (like PuTTY) to connect to the CVM's IP address.
* Log in with the admin user and password.
2. Modify the Rebuild Delay Setting
By default, the cluster waits 15 minutes (900 seconds) before starting a rebuild scan after a CVM reboot. You will change this setting to 0.
* Once logged into the CVM, run the following command to set the delay to 0 seconds:
gflag --set --gflags=stargate_delayed_rebuild_scan_secs=0
* (Optional but recommended) You can verify the change took effect by running the "get" command:
gflag --get --gflags=stargate_delayed_rebuild_scan_secs
The output should now show stargate_delayed_rebuild_scan_secs=0.
NEW QUESTION # 16
An administrator wants to increase the performance of their Database virtual machine.
Database_VM has a database that is spread across three vDisks in the volume group Database_VM. The volume group is directly attached to the virtual machine. Previous performance analysis has indicated all storage requests are going to the same node. While this test environment has 1 node, the production environment has 3 nodes.
Configure the Volume Group Database_VM so that it's optimized for the user's VM and the production environment. The virtual machine has been powered off and moved to this test cluster for the maintenance work.
Note: Do not power on the VM.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure the Volume Group for optimized performance in the production environment.
This task is performed in Prism Central.
* From the main dashboard, navigate to Compute & Storage > Volume Groups.
* Find the Volume Group named Database_VM in the list.
* Select the checkbox next to Database_VM.
* Click the Actions dropdown menu and select Update.
* In the "Update Volume Group" dialog, scroll to the bottom of the "Basic Configuration" section.
* Find the checkbox labeled Enable Client Side Load Balancing and check it.
Note: This setting allows the iSCSI initiator within the guest VM to connect to all CVMs in the cluster, distributing the storage load from the three vDisks across all three nodes in the production environment instead of focusing all I/O on just one.
Click Save.
NEW QUESTION # 17
......
We are leading company and innovator in this NCM-MCI-6.10 exam area. We are grimly determined and confident in helping you pass the NCM-MCI-6.10 exam. With professional experts and brilliant teamwork, our NCM-MCI-6.10 exam dumps have helped exam candidates succeed since the beginning. To make our NCM-MCI-6.10 Practice Engine more precise, we do not mind splurge heavy money and effort to invite the most professional teams into our group. They are the core value and truly helpful with the greatest skills.
NCM-MCI-6.10 Pdf Exam Dump: https://www.validvce.com/NCM-MCI-6.10-exam-collection.html