DOWNLOAD the newest Prep4pass DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1BsyaGb3t93V-aq2HOhYpFRzv9vhePpGx
Now you do not need to worry about the relevancy and top standard of Prep4pass Implementing Data Engineering Solutions Using Azure Databricks in DP-750 exam questions. These Microsoft DP-750 dumps are designed and verified by qualified DP-750 exam trainers. Now you can trust Prep4pass DP-750 Practice Questions and start preparation without wasting further time. With the Prep4pass DP-750 exam questions, you will get everything that you need to learn, prepare and pass the challenging DP-750 exam with good scores.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 2: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 3: Prepare and process data | 30-35% | - Data quality and validation
|
| Topic 4: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
>> DP-750 Test Simulator Fee <<
With the development of society and the perfection of relative laws and regulations, the DP-750 certificate in our career field becomes a necessity for our countryPassing the DP-750 and obtaining the certificate may be the fastest and most direct way to change your position and achieve your goal. And we are just right here to give you help. Being considered the most authentic brand in this career, our professional experts are making unremitting efforts to provide our customers the latest and valid DP-750 Exam simulation.
NEW QUESTION # 42
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.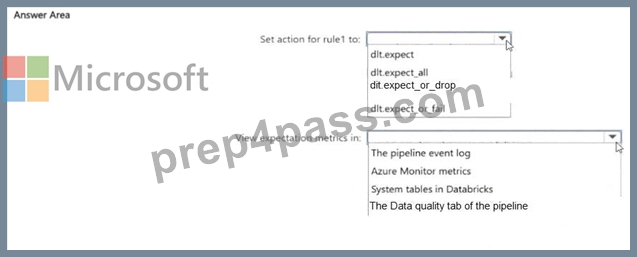
Answer:
Explanation: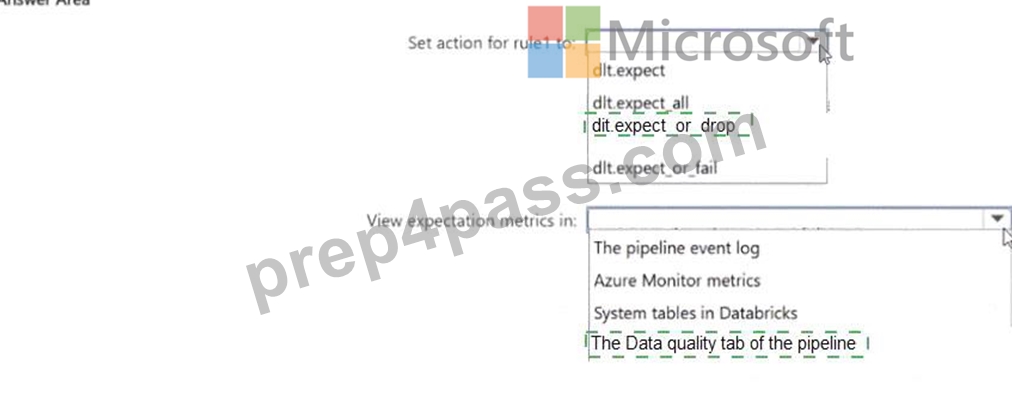
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 43
You have an Azure Databricks workspace that contains a Delta table named Table 1. Table 1 has accumulated obsolete files.
You need to reduce storage costs. The solution must preserve 30 days of time travel history. Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
The correct answers are B and E.
The goal is to reduce storage costs while preserving 30 days of time travel. Two actions are needed:
Set delta.deletedFileRetentionDuration to a value aligned with the 30-day requirement (Option B). Note: the answer option states '10 days' which would be insufficient for 30-day time travel - in practice this property should be set to at least 30 days. This property defines the retention floor: VACUUM will not delete any file newer than this threshold.
Run VACUUM on Table1 (Option E). VACUUM physically removes unreferenced data files older than the retention duration from storage. Without running VACUUM, obsolete files accumulate indefinitely regardless of the retention property setting - the property tells VACUUM what to keep; VACUUM is what does the actual cleanup.
Option C (OPTIMIZE) compacts small files for better query performance but never deletes anything. Option D (logRetentionDuration) keeps the transaction log for time travel but doesn't free up the data file storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-vacuum
NEW QUESTION # 44
You have an Azure Databricks workspace and a remote Git repository named Repo1. Repo1 contains two branches named main and Branch1.
You are on a development team that works in Repo1.
You commit changes to Branch1 and must merge the changes into main.
Before completing the merge, you need to meet the following requirements:
* Ensure that Branch1 includes the changes committed to main since Branch1 was created.
* Ensure that merge conflicts are detected and resolved.
What should you do first?
Answer: B
Explanation:
The latest remote changes from main must first be retrieved so that the development environment has the current main-branch state. After pulling those updates, main can be merged into Branch1, and any conflicts can be detected and resolved before Branch1 is proposed for integration into main. Immediately merging a stale local copy of main into Branch1 could omit commits added remotely after Branch1 was created. Pulling Branch1 only synchronizes the feature branch and does not retrieve the required main-branch changes.
Creating a pull request before updating and testing Branch1 would defer conflict discovery until later in the integration process. Pulling the latest main changes is therefore the correct first operation in the sequence.
Microsoft Learn
NEW QUESTION # 45
Hotspot Question
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2.
You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running.
How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.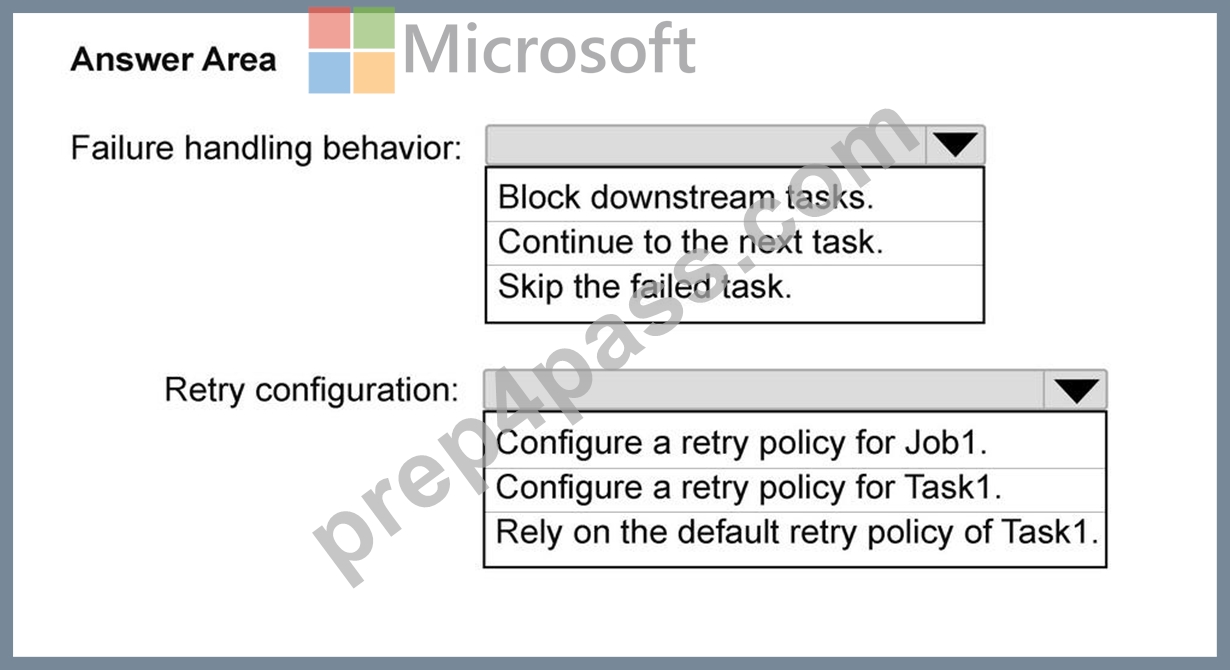
Answer:
Explanation: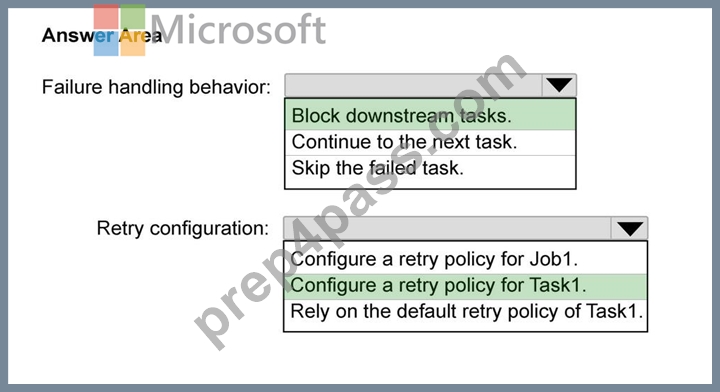
NEW QUESTION # 46
Drag and Drop Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
- asset_id
- asset_type
- asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.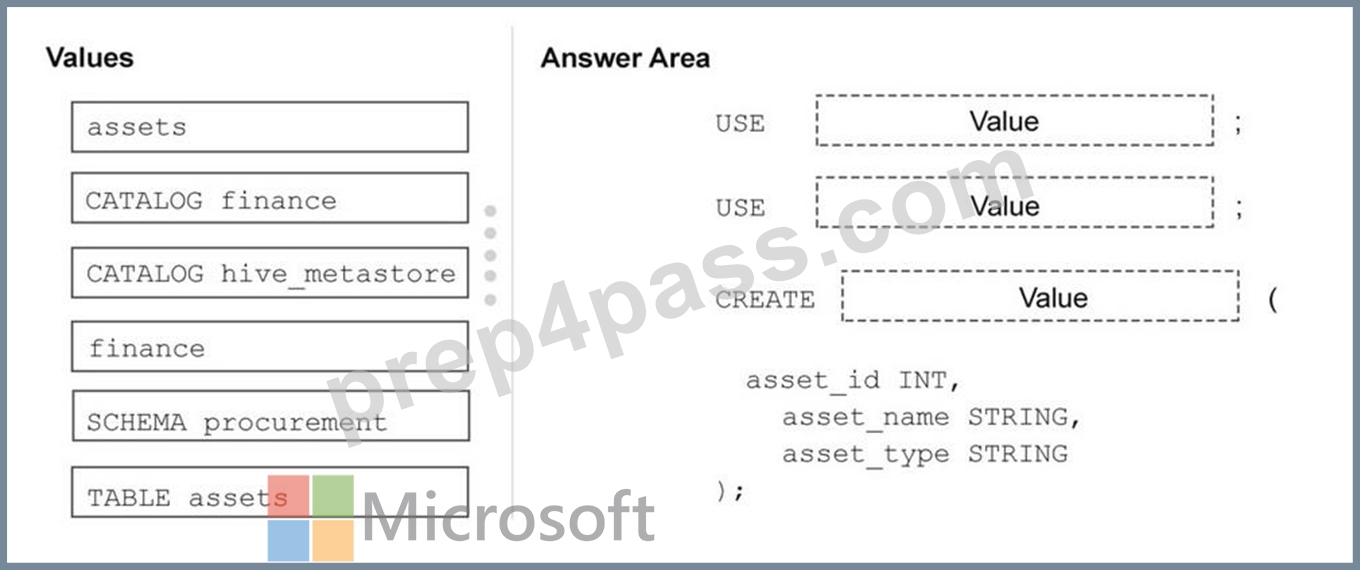
Answer:
Explanation: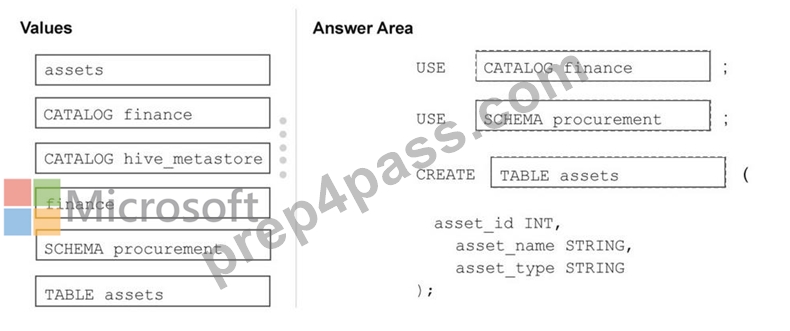
NEW QUESTION # 47
......
Our company, with a history of ten years, has been committed to making efforts on developing DP-750 exam guides in this field. Since the establishment, we have won wonderful feedback from customers and ceaseless business and continuously worked on developing our DP-750 exam prepare to make it more received by the public. Moreover, our understanding of the importance of information technology has reached a new level. Efforts have been made in our experts to help our candidates successfully Pass DP-750 Exam. Seldom dose the e-market have an authorized study materials for reference.
DP-750 Certification: https://www.prep4pass.com/DP-750_exam-braindumps.html
P.S. Free & New DP-750 dumps are available on Google Drive shared by Prep4pass: https://drive.google.com/open?id=1BsyaGb3t93V-aq2HOhYpFRzv9vhePpGx