BTW, DOWNLOAD part of Exam4Free DP-800 dumps from Cloud Storage: https://drive.google.com/open?id=12dtd8isejkjbhrUh3l3VQPngaNoGJXnR
In order to facilitate the user's offline reading, the DP-800 study braindumps can better use the time of debris to learn. Our DP-800 study braindumps can be very good to meet user demand in this respect, allow the user to read and write in a good environment continuously consolidate what they learned. Our DP-800 prep guide has high quality. So there is all effective and central practice for you to prepare for your test. With our professional ability, we can accord to the necessary testing points to edit DP-800 Exam Questions. It points to the exam heart to solve your difficulty. So high quality materials can help you to pass your exam effectively, make you feel easy, to achieve your goal.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> DP-800 Training For Exam <<
For one thing, the most advanced operation system in our company which can assure you the fastest delivery speed on our DP-800 exam questions. For another thing, with the online app version of our DP-800 actual exam, you can just feel free to practice the questions in our DP-800 Training Materials on all kinds of electronic devices. In addition, under the help of our DP-800 exam questions, the pass rate among our customers has reached as high as 98% to 100%. We are look forward to become your learning partner in the near future.
NEW QUESTION # 59
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders.
dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.Orders.
Solution: Identify the partition number for the oldest month, and then run the following Transact- SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
Does this meet the goal?
Answer: A
Explanation:
Correct:
* Identify the partition number for the oldest month, and then run the following Transact-SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
The best Transact-SQL statement to remove all rows for the oldest month while minimizing the impact on other queries is TRUNCATE TABLE with a WITH (PARTITIONS (...)) clause.
Why TRUNCATE TABLE ... WITH (PARTITIONS (...)) is Best
Efficiency: TRUNCATE TABLE is a Data Definition Language (DDL) operation that removes data by deallocating the data pages, which is a metadata operation and is very fast, regardless of the amount of data in the partition.
Minimal Logging: It uses less transaction log space compared to a DELETE statement, which logs each row deletion individually.
Low Impact on Concurrency: It performs a quick, partition-specific operation. A row-by-row DELETE would be a long-running transaction and could cause locking and blocking issues for other queries accessing the table.
Data Integrity: Because the table has a clustered index and is partitioned by the same column (aligned indexes), the TRUNCATE PARTITION operation is a fast, partition-level maintenance operation that targets only that specific data subset.
Incorrect:
* : Identify the partition scheme for the oldest month, and then run the following Transact-SQL statement.
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME (partition_scheme_name);
The DROP PARTITION SCHEME statement removes the partition scheme object from the database but does not remove the data itself or free up the space, and it requires all tables to be moved off the scheme first, which is a complex operation. This does not meet the goal of removing the data efficiently.
* Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
A standard DELETE statement, even with a WHERE clause that uses the partition column, can be a time-consuming, logged operation that causes locking and blocking on the main table, negatively impacting performance.
Reference:
https://stackoverflow.com/questions/63632963/truncate-partition-vs-drop-partition-performace- wise-which-one-is-efficient-an
NEW QUESTION # 60
You have an Azure SQL database named SalesDB that contains tables named Sales.Orders and Sales.
OrderLines. Both tables contain sales data
You have a Retrieval Augmented Generation (RAG) service that queries SalesDB to retrieve order details and passes the results to a large language model (ILM) as JSON text. The following is a sample of the JSON.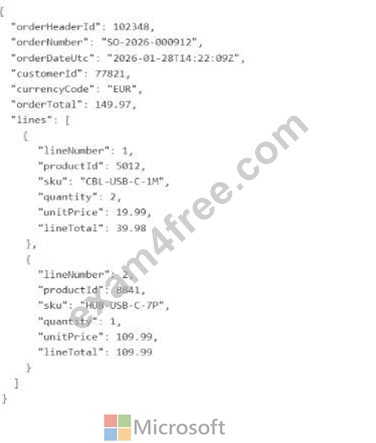
You need to return one 1SON document per order that includes the order header fields and an array of related order lines. The LIM must receive a single JSON array of orders, where each order contains a lines property that is a JSON array of line Items.
Which transact-SQL commands should you use to produce the required JSON shape from the relational tables? To answer, drag the appropriate commands to the correct operations. Each command may be used once, more than once, or not at all. Vou may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.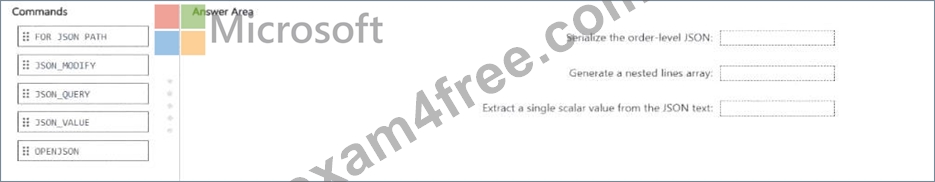
Answer:
Explanation: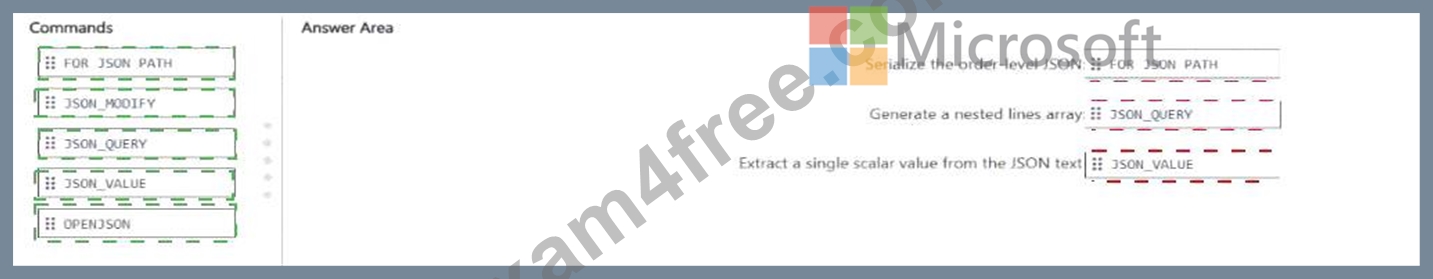
Explanation:
* Serialize the order-level JSON : FOR JSON PATH
* Generate a nested lines array : JSON_QUERY
* Extract a single scalar value from the JSON text : JSON_VALUE
The correct mapping is based on how SQL Server and Azure SQL JSON functions are designed to shape relational data into JSON for AI and RAG scenarios.
To serialize the order-level JSON , use FOR JSON PATH . Microsoft documents that FOR JSON PATH gives you full control over the JSON output shape and formats the result as an array of JSON objects . It is the standard way to turn relational query results into the JSON structure needed by downstream consumers such as APIs and LLM-based RAG services. It also supports nested output through subqueries and aliases.
To generate a nested lines array , use JSON_QUERY . Microsoft explains that JSON_QUERY returns a JSON object or array from JSON text, and it is used when you want to preserve a JSON fragment instead of treating it as plain text. In this scenario, the nested lines property must be emitted as a proper JSON array inside each order document, so JSON_QUERY is the correct command to embed that array in the final JSON shape.
To extract a single scalar value from the JSON text , use JSON_VALUE . Microsoft explicitly states that JSON_VALUE extracts a scalar value from a JSON string, while JSON_QUERY is for objects or arrays. So whenever the requirement is to pull out one property such as an order number, currency code, or customer ID from JSON text, JSON_VALUE is the correct function.
The unused commands are not the best fit here:
* OPENJSON is primarily for parsing JSON into rows and columns, not for shaping relational tables into nested output.
* JSON_MODIFY is for updating JSON text, not generating the required output structure.
So the drag-and-drop answers are:
* Serialize the order-level JSON # FOR JSON PATH
* Generate a nested lines array # JSON_QUERY
* Extract a single scalar value from the JSON text # JSON_VALUE
NEW QUESTION # 61
You have a database that contains production data. The schema is stored in a Git repository as an SDK-style SQL database project and contains the following reference data.
Name
Data type
RefID
int, identity
Code
nvarchar(10)
CreatedDate
datetime2
Description
nvarchar(255)
A deployment pipeline can be rerun automatically when a transient failure occurs.
You need to deploy the reference data as part of the same CI/CD process. Rerunning the pipeline must produce the same outcome and must NOT create duplicate rows.
What should you do?
Answer: B
NEW QUESTION # 62
You have an Azure SQL table that contains the following data.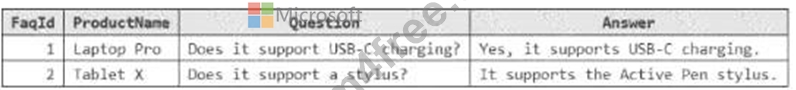
You need to retrieve data to be used as context for a large language model (LLM). The solution must minimize token usage.
Which formal should you use to send the data to the LLM?
Answer: B
Explanation:
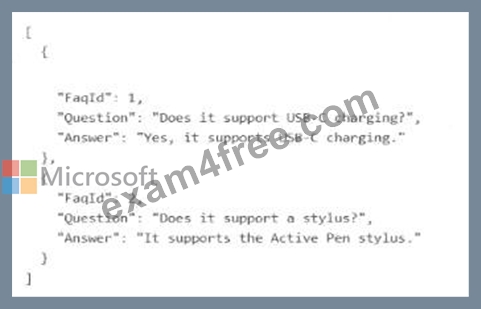
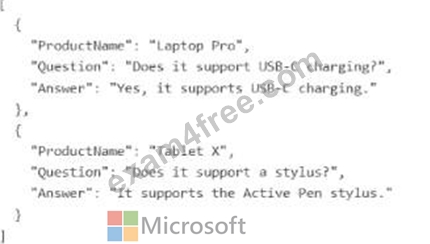
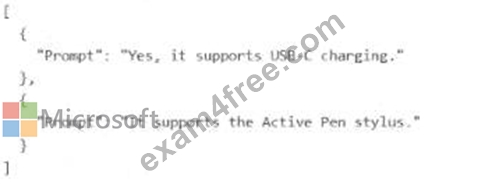
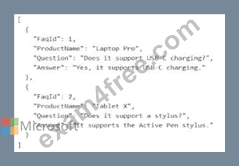
The correct choice is Option A because it provides the relevant semantic context the LLM needs while avoiding an unnecessary field that would add tokens without improving answer quality.
For LLM grounding and RAG-style context, Microsoft guidance emphasizes mapping and sending the fields that contain text pertinent to the use case . In this FAQ scenario, the useful context is the ProductName , the Question , and the Answer . Those three fields help the model understand both the subject domain and the actual Q & A pair. By contrast, FaqId is just a technical identifier and generally adds no semantic value for response generation, so including it wastes tokens.
That is why Option A is better than the others:
* Option A keeps the meaningful text fields and removes the low-value identifier.
* Option B is too minimal because it includes only the answer text as Prompt, which strips away the product and question context the LLM may need for accurate grounding.
* Option C keeps FaqId but omits ProductName, which can be important disambiguating context.
* Option D includes everything, but that does not minimize token usage because it keeps the unnecessary FaqId.
NEW QUESTION # 63
You have a Microsoft SQL Server 2025 database that contains a table named products. products contains two columns named description and embedding. embedding is generated from description.
You have an application named App1. App1 has a feature that uses the following query.
VECTOR_DISTANCE('cosine', @query_vector, embedding)
Users report that the feature is slow during peak usage times.
You discover that during peak usage times, the semantic search latency increases and CPU utilization spikes.
You need to reduce latency and CPU utilization related to the App1 feature.
What should you do?
Answer: A
Explanation:
To optimize your Microsoft SQL Server 2025 environment, you should transition from a brute- force distance calculation to an Approximate Nearest Neighbor (ANN) search using a DiskANN- based vector index.
The Solution: Vector Indexing
The VECTOR_DISTANCE function performs a full table scan, calculating the distance for every single row. During peak times, this consumes massive CPU cycles. A vector index allows SQL Server to navigate a pre-built graph to find matches, reducing complexity from O(n) to O(log n).
Implementation Steps
1. Create the Vector Index
You must specify the distance metric during index creation. For cosine similarity, use COSINE.
CREATE VECTOR INDEX idx_product_embedding
ON products (embedding)
WITH (METRIC = 'COSINE');
2. Update the Search Query
Replace the WHERE or ORDER BY clause that uses VECTOR_DISTANCE with the VECTOR_SEARCH function.
SELECT TOP (10) description, embedding
FROM products
WHERE VECTOR_SEARCH(
embedding,
@query_vector,
'COSINE',
10 -- Number of neighbors to return
);
Why This Solves Your Problem
CPU Relief: Avoids calculating distances for millions of rows.
Lower Latency: DiskANN is designed for sub-second retrieval even on large datasets.
Peak Performance: By offloading the math to a specialized index structure, the engine remains responsive for other transactional queries.
Reference:
https://learn.microsoft.com/en-us/azure/postgresql/extensions/how-to-use-pgdiskann
NEW QUESTION # 64
......
Many students often start to study as the exam is approaching. Time is very valuable to these students, and for them, one extra hour of study may mean 3 points more on the test score. If you are one of these students, then DP-800 exam tests are your best choice. Because students often purchase materials from the Internet, there is a problem that they need transport time, especially for those students who live in remote areas. When the materials arrive, they may just have a little time to read them before the exam. However, with DP-800 Exam Questions, you will never encounter such problems, because our materials are distributed to customers through emails. After you have successfully paid, you can immediately receive DP-800 test guide from our customer service staff, and then you can start learning immediately.
Reliable DP-800 Exam Online: https://www.exam4free.com/DP-800-valid-dumps.html
P.S. Free & New DP-800 dumps are available on Google Drive shared by Exam4Free: https://drive.google.com/open?id=12dtd8isejkjbhrUh3l3VQPngaNoGJXnR