Valid Certified-Data-Engineer-Professional Dumps Demo | Reliable Certified-Data-Engineer-Professional Test Book

The Prep4away is committed to ace your Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam preparation and ensure your success on the first attempt. To achieve this objective the Prep4away is offering top-rated, real, and updated Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions in three different formats. The names of these formats are Certified-Data-Engineer-Professional PDF dumps file, desktop practice test software, and web-based practice test software.
| Section | Weight | Objectives |
|---|
| Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines
- Apply AUTO CDC APIs and exactly-once semantics
|
| CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API
- Implement testing and deployment pipelines
|
| Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data
- Apply advanced Spark transformations
|
| Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures
- Use Spark UI, Query Profiler, and system tables
|
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering
- Apply dimensional modeling techniques
|
| Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures
- Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
- Manage dependencies, libraries, and UDFs
|
| Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage
- Leverage system tables and observability tools
|
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs
- Implement row-level security, column masking, and compliance
|
>> Valid Certified-Data-Engineer-Professional Dumps Demo <<
Certified-Data-Engineer-Professional Exam Braindumps: Databricks Certified Data Engineer Professional & Certified-Data-Engineer-Professional Certification Training
You can learn Certified-Data-Engineer-Professional quiz torrent skills and theory at your own pace, and you are not necessary to waste your time on some useless books or materials and you will save more time and energy that you can complete other thing. We also provide every candidate who wants to get certification with free Demo to check our materials. It is time for you to realize the importance of our Certified-Data-Engineer-Professional Test Prep, which can help you solve these annoyance and obtain a Certified-Data-Engineer-Professional certificate in a more efficient and productive way.
Databricks Certified Data Engineer Professional Sample Questions (Q195-Q200):
NEW QUESTION # 195
The data governance team has instituted a requirement that the "user" table containing Personal Identifiable Information (PII) must have the appropriate masking on the SSN column. This means that anyone outside of the HRAdminGroup should see masked social security numbers as ***-**-
****.
The team created a masking function:

What does the data governance team need to do next to achieve this goal?
- A. CREATE TABLE users
(name STRING, ssn STRING);
ALTER TABLE users ALTER COLUMN ssn SET MASK ssn_mask; - B. CREATE TABLE users
(name STRING);
ALTER TABLE users CREATE COLUMN ssn CREATE MASK ssn_mask; - C. CREATE TABLE users
(name STRING, ssn INT MASKED ssn_mask); - D. CREATE TABLE users
(name STRING, int STRING);
ALTER TABLE users ALTER COLUMN ssn CREATE MASK if is_member('HRAdminGroup');
Answer: A
Explanation:
In Databricks, after creating a masking function, you apply it to a column using ALTER TABLE
<table> ALTER COLUMN <column> SET MASK <mask_function>. The table must already include the column (here, ssn as STRING). This ensures that only users in the HRAdminGroup see the unmasked SSN, while all others see the masked value.
NEW QUESTION # 196
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x- scala2.12' runtime. Which command should the data engineer use?
- A. databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name Data Engineer_cluster
- B. databricks compute add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- C. databricks clusters add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- D. databricks clusters create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name DataEngineer_cluster
Answer: D
Explanation:
The correct Databricks CLI command to create a new cluster is databricks clusters create. You specify the runtime with --spark-version (here '14.3.x-scala2.12'), the number of workers with -- num-workers, the node type with --node-type-id, and the cluster name with --cluster-name. This command properly initializes the cluster with the desired configuration.
NEW QUESTION # 197
Which distribution does Databricks support for installing custom Python code packages?
- A. Wheels
- B. jars
- C. nom
- D. CRAM
- E. sbt
- F. CRAN
Answer: C
Explanation:
https://learn.microsoft.com/en-us/azure/databricks/workflows/jobs/how-to/use-python-wheels-in-workflows
NEW QUESTION # 198
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
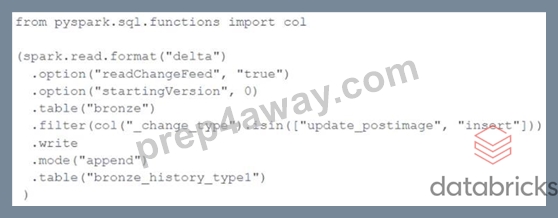
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
- B. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
- C. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- D. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- E. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
Answer: A
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 199
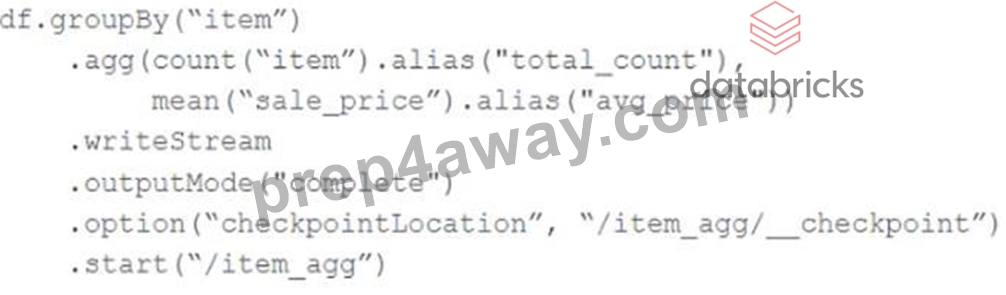
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query:
Proposed query:
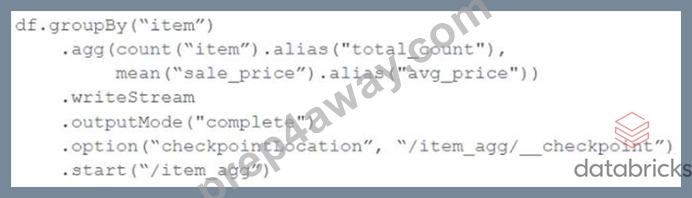
Which step must also be completed to put the proposed query into production?
- A. Run REFRESH TABLE delta, /item_agg'
- B. Register the data in the "/item_agg" directory to the Hive metastore
- C. Increase the shuffle partitions to account for additional aggregates
- D. Specify a new checkpointlocation
- E. Remove .option (mergeSchema', true') from the streaming write
Answer: D
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
NEW QUESTION # 200
......
Prep4away has come up with real Databricks Certified-Data-Engineer-Professional Dumps for students so they can pass Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam in a single try and get to their destination. Prep4away has made this study material after consulting with the professionals and getting their positive feedback. A lot of students have used our product and prepared successfully for the test.
Reliable Certified-Data-Engineer-Professional Test Book: https://www.prep4away.com/Databricks-certification/braindumps.Certified-Data-Engineer-Professional.ete.file.html
- 100% Pass Quiz 2026 High Pass-Rate Certified-Data-Engineer-Professional: Valid Databricks Certified Data Engineer Professional Dumps Demo 👵 Search for ➠ Certified-Data-Engineer-Professional 🠰 and easily obtain a free download on ▛ www.dumpsquestion.com ▟ 🔘New Certified-Data-Engineer-Professional Test Objectives
- Reliable Certified-Data-Engineer-Professional Dumps Ppt 🟠 Certified-Data-Engineer-Professional Latest Test Format 💓 Best Certified-Data-Engineer-Professional Practice 💠 Enter ⏩ www.pdfvce.com ⏪ and search for ▛ Certified-Data-Engineer-Professional ▟ to download for free 😩Certified-Data-Engineer-Professional Test Pass4sure
- Why Practicing With www.dumpsmaterials.com Certified-Data-Engineer-Professional Dumps is Necessary? 🏡 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and download it for free immediately on 「 www.dumpsmaterials.com 」 🙈Certified-Data-Engineer-Professional Latest Study Questions
- Experience 24/7 Support And Real Databricks Certified-Data-Engineer-Professional Exam Questions With Pdfvce 🔎 Copy URL ( www.pdfvce.com ) open and search for ➤ Certified-Data-Engineer-Professional ⮘ to download for free 🤓Valid Certified-Data-Engineer-Professional Test Pattern
- Useful Certified-Data-Engineer-Professional – 100% Free Valid Dumps Demo | Reliable Certified-Data-Engineer-Professional Test Book 🚊 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and obtain a free download on ➤ www.prep4away.com ⮘ 🥙New Certified-Data-Engineer-Professional Test Objectives
- Certified-Data-Engineer-Professional Test Sample Online 🥾 Exam Certified-Data-Engineer-Professional Actual Tests 🔸 Exam Certified-Data-Engineer-Professional Actual Tests 😱 ▛ www.pdfvce.com ▟ is best website to obtain ⏩ Certified-Data-Engineer-Professional ⏪ for free download 💚Certified-Data-Engineer-Professional Valid Dumps Demo
- Reliable Certified-Data-Engineer-Professional Dumps Ppt 🆗 Certified-Data-Engineer-Professional Test Sample Online 🏢 New Certified-Data-Engineer-Professional Test Objectives 👋 Download ➥ Certified-Data-Engineer-Professional 🡄 for free by simply searching on ➡ www.prep4away.com ️⬅️ 📔Certified-Data-Engineer-Professional Reliable Exam Papers
- Certified-Data-Engineer-Professional Cram File - Certified-Data-Engineer-Professional Exam Cram - Certified-Data-Engineer-Professional Latest Dumps 🌇 Search for ➠ Certified-Data-Engineer-Professional 🠰 and download exam materials for free through ➥ www.pdfvce.com 🡄 🐝Certified-Data-Engineer-Professional Test Pass4sure
- Useful Certified-Data-Engineer-Professional – 100% Free Valid Dumps Demo | Reliable Certified-Data-Engineer-Professional Test Book ⏩ The page for free download of ☀ Certified-Data-Engineer-Professional ️☀️ on ⏩ www.troytecdumps.com ⏪ will open immediately 🖋Certified-Data-Engineer-Professional Reliable Exam Papers
- New Certified-Data-Engineer-Professional Test Objectives 🍤 Certified-Data-Engineer-Professional New Dumps Sheet 📅 Practice Certified-Data-Engineer-Professional Questions 🧆 The page for free download of ⏩ Certified-Data-Engineer-Professional ⏪ on ⇛ www.pdfvce.com ⇚ will open immediately 🏊Certified-Data-Engineer-Professional Valid Dumps Demo
- 100% Pass Quiz 2026 High Pass-Rate Certified-Data-Engineer-Professional: Valid Databricks Certified Data Engineer Professional Dumps Demo 🏗 Easily obtain free download of 「 Certified-Data-Engineer-Professional 」 by searching on ➥ www.testkingpass.com 🡄 🌃Reliable Certified-Data-Engineer-Professional Dumps Ppt
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes