Databricks Databricks-Certified-Professional-Data-Engineerテストトレーニング、Databricks-Certified-Professional-Data-Engineer日本語版対応参考書

さらに、Jpshiken Databricks-Certified-Professional-Data-Engineerダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1d1w_O_3XI-dStzbbQXBjhDdlVK8vR_Or
JpshikenのDatabricks-Certified-Professional-Data-Engineer参考書は間違いなくあなたが一番信頼できるDatabricks-Certified-Professional-Data-Engineer試験に関連する資料です。まだそれを信じていないなら、すぐに自分で体験してください。そうすると、きっと私の言葉を信じるようになります。Jpshikenのサイトをクリックして問題集のデモをダウンロードすることができますから、ご利用ください。PDF版でもソフト版でも提供されていますから、先ず体験して下さい。問題集の品質を自分自身で確かめましょう。
Databricks Databricks-Certified-Professional-Data-Engineer Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Data Ingestion | 15-20% | - Batch ingestion methods
- 1. DBR autoloader
- 2. Spark APIs for ingestion
- 3. Integration with external systems
- Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Data governance fundamentals
- 2. Differences between data lake, data warehouse, and lakehouse
- 3. Bronze, silver, gold data layers
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Task dependencies and orchestration
- 2. Jobs and job scheduling
- 3. Monitoring and alerting
|
| Data Processing with Spark | 25-30% | - Python and SQL for data engineering
- 1. Performance optimization techniques
- 2. Spark APIs in Python
- 3. Built-in and user-defined functions
- Spark DataFrames and Spark SQL
- 1. Spark SQL queries and functions
- 2. Window functions
- 3. DataFrame operations and transformations
|
| Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. Time travel and data versioning
- 2. Optimize and Z-order
- 3. ACID transactions
- Delta Lake operations
- 1. Schema evolution and enforcement
- 2. Merge, update, delete operations
- 3. Delta Live Tables
|
>> Databricks Databricks-Certified-Professional-Data-Engineerテストトレーニング <<
Databricks-Certified-Professional-Data-Engineer日本語版対応参考書 & Databricks-Certified-Professional-Data-Engineer技術内容
Databricks-Certified-Professional-Data-Engineerテスト教材は、主に3つの学習モード(Pdf、オンライン、ソフトウェア)をそれぞれ使用します。その中でも、ソフトウェアモデルはコンピューターユーザー向けに設計されており、ユーザーがWindowsインターフェイスを使用して学習のDatabricks-Certified-Professional-Data-Engineerテスト準備を開くことができます。ユーザーが読むのに便利です。 Databricks-Certified-Professional-Data-Engineerテスト教材には、オンライン学習プラットフォームとは異なる最大の利点があります。Databricks-Certified-Professional-Data-Engineerクイズトレントは、クライアントにログインして同時に詳細を学習することができ、人々はDatabricks-Certified-Professional-Data-Engineerあらゆる種類の電子機器のテスト準備。
Databricks Certified Professional Data Engineer Exam 認定 Databricks-Certified-Professional-Data-Engineer 試験問題 (Q89-Q94):
質問 # 89
Which of the following SQL commands are used to append rows to an existing delta table?
- A. INSERT INTO table_name
- B. UPDATE table_name
- C. APPEND INTO DELTA table_name
- D. APPEND INTO table_name
- E. COPY DELTA INTO table_name
正解:A
解説:
Explanation
The answer is INSERT INTO table_name
Insert adds rows to an existing table, this is very similar to add rows a traditional Database or Da-tawarehouse.
質問 # 90
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
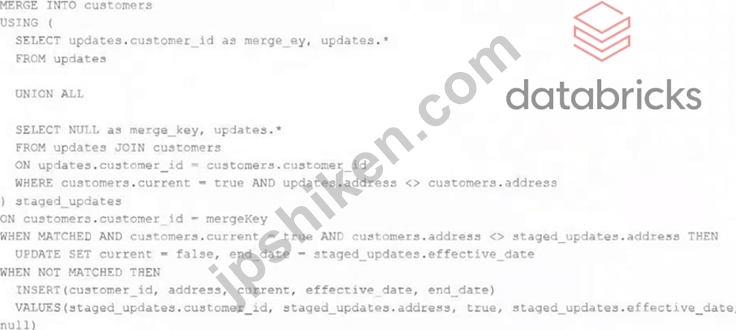
Which statement describes this implementation?
- A. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
- B. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
- C. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- D. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
- E. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
正解:A
解説:
The logic uses the MERGE INTO command to merge new records from the view updates into the table customers. The MERGE INTO command takes two arguments: a target table and a source table or view. The command also specifies a condition to match records between the target and the source, and a set of actions to perform when there is a match or not. In this case, the condition is to match records by customer_id, which is the primary key of the customers table. The actions are to update the existing record in the target with the new values from the source, and set the current_flag to false to indicate that the record is no longer current; and to insert a new record in the target with the new values from the source, and set the current_flag to true to indicate that the record is current. This means that old values are maintained but marked as no longer current and new values are inserted, which is the definition of a Type 2 table. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Merge Into (Delta Lake on Databricks)" section.
質問 # 91
Data science team has requested they are missing a column in the table called average price, this can be calculated using units sold and sales amt, which of the following SQL statements allow you to reload the data with additional column
- A. OVERWRITE sales AS SELECT *, salesAmt/unitsSold as avgPrice FROM sales
- B. 1.INSERT OVERWRITE sales
2.SELECT *, salesAmt/unitsSold as avgPrice FROM sales - C. MERGE INTO sales USING (SELECT *, salesAmt/unitsSold as avgPrice FROM sales)
- D. COPY INTO SALES AS SELECT *, salesAmt/unitsSold as avgPrice FROM sales
- E. 1.CREATE OR REPLACE TABLE sales
2.AS SELECT *, salesAmt/unitsSold as avgPrice FROM sales
正解:E
解説:
Explanation
1.CREATE OR REPLACE TABLE sales
2.AS SELECT *, salesAmt/unitsSold as avgPrice FROM sales
The main difference between INSERT OVERWRITE and CREATE OR REPLACE TABLE(CRAS) is that CRAS can modify the schema of the table, i.e it can add new columns or change data types of existing columns. By default INSERT OVERWRITE only overwrites the data.
INSERT OVERWRITE can also be used to overwrite schema, only when
spark.databricks.delta.schema.autoMerge.enabled is set true if this option is not enabled and if there is a schema mismatch command will fail.
質問 # 92
Which of the following is the correct statement for a session scoped temporary view?
- A. Temporary views can be still accessed even if the notebook is detached and attached
- B. Temporary views can be still accessed even if cluster is restarted
- C. Temporary views stored in memory
- D. Temporary views are created in local_temp database
- E. Temporary views are lost once the notebook is detached and re-attached
正解:E
解説:
Explanation
The answer is Temporary views are lost once the notebook is detached and attached There are two types of temporary views that can be created, Session scoped and Global
*A local/session scoped temporary view is only available with a spark session, so another notebook in the same cluster can not access it. if a notebook is detached and reattached local temporary view is lost.
*A global temporary view is available to all the notebooks in the cluster, if a cluster restarts global temporary view is lost.
質問 # 93
A data engineer is designing a Lakeflow Spark Declarative Pipeline to process streaming order data. The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id is not null and amount is greater than zero. Invalid records should be dropped. Which Lakeflow Spark Declarative Pipelines configuration implements this requirement using Python?
- A. @dlt.table
@dlt.expect_or_drop( " valid_customer " , " customer_id IS NOT NULL " )
@dlt.expect_or_drop( " valid_amount " , " amount > 0 " )
def silver_orders():
return dlt.read_stream( " bronze_orders " ) - B. @dlt.table
def silver_orders():
return dlt.read_stream( " bronze_orders " ) \
.expect( " valid_customer " , " customer_id IS NOT NULL " ) \
.expect( " valid_amount " , " amount > 0 " ) - C. @dlt.table
def silver_orders():
return dlt.read_stream( " bronze_orders " ) \
.expect_or_drop( " valid_customer " , " customer_id IS NOT NULL " ) \
.expect_or_drop( " valid_amount " , " amount > 0 " ) - D. @dlt.table
@dlt.expect( " valid_customer " , " customer_id IS NOT NULL " )
@dlt.expect( " valid_amount " , " amount > 0 " )
def silver_orders():
return dlt.read_stream( " bronze_orders " )
正解:A
解説:
Databricks documents that expectation decorators are applied to datasets using decorators such as @dp.expect
, @dp.expect_or_drop , and related variants. The expect_or_drop behavior drops records that violate the constraint before they are written to the target dataset. That matches the requirement exactly. ( Databricks Documentation ) Option D is the only answer that uses the documented decorator pattern correctly and applies drop semantics for both constraints. Options B and C use expect , which records the violation but does not drop invalid records. Option A is not the documented API pattern for Lakeflow expectations, because expectations are declared as decorators on the table or view definition rather than chained as DataFrame methods. ( Databricks Documentation )
======
質問 # 94
......
JpshikenクライアントがDatabricks-Certified-Professional-Data-Engineerクイズ準備を購入する前後に、思いやりのあるオンラインカスタマーサービスを提供します。クライアントは、購入前にDatabricks-Certified-Professional-Data-Engineer試験実践ガイドの価格、バージョン、内容を尋ねることができます。ソフトウェアの使用方法、Databricks-Certified-Professional-Data-Engineerクイズ準備の機能、Databricks-Certified-Professional-Data-Engineer学習資料の使用中に発生する問題、および払い戻しの問題について相談できます。オンラインカスタマーサービスの担当者がDatabricks-Certified-Professional-Data-Engineer試験実践ガイドに関する質問に回答し、辛抱強く情熱的に問題を解決します。
Databricks-Certified-Professional-Data-Engineer日本語版対応参考書: https://www.jpshiken.com/Databricks-Certified-Professional-Data-Engineer_shiken.html
- Databricks-Certified-Professional-Data-Engineer独学書籍 🏌 Databricks-Certified-Professional-Data-Engineer試験内容 🥮 Databricks-Certified-Professional-Data-Engineerトレーニング費用 🍤 今すぐ【 www.goshiken.com 】を開き、⮆ Databricks-Certified-Professional-Data-Engineer ⮄を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語
- Databricks-Certified-Professional-Data-Engineerテストソフトウェア、Databricks-Certified-Professional-Data-Engineer最新トレーニング資料、Databricks-Certified-Professional-Data-Engineer練習資料 🥍 今すぐ⇛ www.goshiken.com ⇚で▶ Databricks-Certified-Professional-Data-Engineer ◀を検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語版トレーリング
- Databricks-Certified-Professional-Data-Engineer実際試験 🔔 Databricks-Certified-Professional-Data-Engineer基礎問題集 🕟 Databricks-Certified-Professional-Data-Engineerキャリアパス 🌈 ウェブサイト( www.japancert.com )から➥ Databricks-Certified-Professional-Data-Engineer 🡄を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer模擬トレーリング
- Databricks-Certified-Professional-Data-Engineer試験問題集、Databricks Databricks-Certified-Professional-Data-Engineer資料は大好評を博します 😪 ⇛ www.goshiken.com ⇚から➽ Databricks-Certified-Professional-Data-Engineer 🢪を検索して、試験資料を無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer問題例
- Databricks Databricks-Certified-Professional-Data-Engineer 一発合格問題 🏵 ⮆ Databricks-Certified-Professional-Data-Engineer ⮄を無料でダウンロード⮆ www.mogiexam.com ⮄ウェブサイトを入力するだけDatabricks-Certified-Professional-Data-Engineer基礎問題集
- Databricks-Certified-Professional-Data-Engineer実際試験 🎯 Databricks-Certified-Professional-Data-Engineer認定資格 🌙 Databricks-Certified-Professional-Data-Engineer入門知識 🙁 ▛ www.goshiken.com ▟で➥ Databricks-Certified-Professional-Data-Engineer 🡄を検索して、無料で簡単にダウンロードできますDatabricks-Certified-Professional-Data-Engineerトレーニング費用
- Databricks-Certified-Professional-Data-Engineer独学書籍 🌟 Databricks-Certified-Professional-Data-Engineer問題例 🐑 Databricks-Certified-Professional-Data-Engineer認定資格 🤷 ウェブサイト▛ www.xhs1991.com ▟から( Databricks-Certified-Professional-Data-Engineer )を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer入門知識
- Databricks-Certified-Professional-Data-Engineer試験問題集、Databricks Databricks-Certified-Professional-Data-Engineer資料は大好評を博します 📻 ▷ www.goshiken.com ◁を開き、⇛ Databricks-Certified-Professional-Data-Engineer ⇚を入力して、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語
- Databricks-Certified-Professional-Data-Engineerテストソフトウェア、Databricks-Certified-Professional-Data-Engineer最新トレーニング資料、Databricks-Certified-Professional-Data-Engineer練習資料 🩺 【 www.jpexam.com 】から簡単に➥ Databricks-Certified-Professional-Data-Engineer 🡄を無料でダウンロードできますDatabricks-Certified-Professional-Data-Engineer独学書籍
- Databricks-Certified-Professional-Data-Engineerトレーニング費用 🚼 Databricks-Certified-Professional-Data-Engineer復習範囲 ↘ Databricks-Certified-Professional-Data-Engineer入門知識 📧 ▶ www.goshiken.com ◀にて限定無料の➡ Databricks-Certified-Professional-Data-Engineer ️⬅️問題集をダウンロードせよDatabricks-Certified-Professional-Data-Engineer受験対策
- Databricks-Certified-Professional-Data-Engineer試験の準備方法|最高のDatabricks-Certified-Professional-Data-Engineerテストトレーニング試験|素晴らしいDatabricks Certified Professional Data Engineer Exam日本語版対応参考書 📆 URL ➤ www.passtest.jp ⮘をコピーして開き、【 Databricks-Certified-Professional-Data-Engineer 】を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineerトレーニング費用
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
無料でクラウドストレージから最新のJpshiken Databricks-Certified-Professional-Data-Engineer PDFダンプをダウンロードする:https://drive.google.com/open?id=1d1w_O_3XI-dStzbbQXBjhDdlVK8vR_Or