You can use this Databricks-Certified-Professional-Data-Engineer simulation software without an internet connection after installation. Tracking and reporting features of our Databricks Databricks-Certified-Professional-Data-Engineer practice exam software makes it easier for you to identify and overcome mistakes. Customization feature of this format allows you to change time limits and questions numbers of mock exams.
| Section | Objectives |
|---|---|
| Data Ingestion and Transformation | - Ingest data using Apache Spark and Databricks - Handle batch and streaming data pipelines - Transform and clean datasets using Spark SQL and DataFrame APIs |
| Production Pipelines and Orchestration | - Automate ETL pipelines and scheduling - Pipeline reliability and fault tolerance - Build and manage workflows using Databricks Jobs |
| Data Modeling and Storage | - Schema evolution and data partitioning strategies - Delta Lake table design and optimization - Design scalable data lakehouse architectures |
| Security, Governance, Monitoring, and Optimization | - Implement Unity Catalog governance and access control - Monitor and optimize Spark workloads - Cost optimization and performance tuning |
>> Databricks-Certified-Professional-Data-Engineer Latest Exam Cram <<
Our company is a professional certificate exam materials provider, and we have occupied in this field for years. Databricks-Certified-Professional-Data-Engineer exam dumps are high-quality, and we have received many good feedbacks from our customers. In addition, we offer you free demo for you to have a try before buying Databricks-Certified-Professional-Data-Engineer Exam Braindumps, and you will have a better understanding of what you are going to buy. We have online and offline chat service stuffs, who are quite familiar with the Databricks-Certified-Professional-Data-Engineer exam dumps, if you have any questions, just contact us.
NEW QUESTION # 245
A platform engineer is creating catalogs and schemas for the development team to use.
The engineer has created an initial catalog, catalog_A, and initial schema, schema_A. The engineer has also granted USE CATALOG, USE SCHEMA, and CREATE TABLE to the development team so that the engineer can begin populating the schema with new tables.
Despite being owner of the catalog and schema, the engineer noticed that they do not have access to the underlying tables in Schema_A.
What explains the engineer's lack of access to the underlying tables?
Answer: B
Explanation:
In Databricks, catalogs, schemas (or databases), and tables are managed through the Unity Catalog or Hive Metastore, depending on the environment. Permissions and ownership within these structures are governed by access control lists (ACLs).
Catalog and Schema Ownership: When a platform engineer creates a catalog (such as catalog_A) and schema (such as schema_A), they automatically become the owner of those entities. This ownership gives them control over granting permissions for those entities (i.e., granting the USE CATALOG and USE SCHEMA privileges to others). However, ownership of the catalog or schema does not automatically extend to ownership or permission of individual tables within that schema.
Table Permissions: For tables within a schema, the permission model is more granular. The table creator (i.e., whoever creates the table) is automatically assigned as the owner of that table. In this case, the platform engineer owns the schema but does not automatically inherit permissions to any table created within the schema unless explicitly granted by the table's owner or unless they grant permissions to themselves.
Why the Engineer Lacks Access: The platform engineer notices that they do not have access to the underlying tables in schema_A despite being the owner of the schema. This occurs because the schema's ownership does not cascade to the tables. The engineer must either:
Grant permissions to themselves for the tables in schema_A, or
Be granted permissions by whoever created the tables within the schema.
Resolution: As the owner of the schema, the platform engineer can easily grant themselves the required permissions (such as SELECT, INSERT, etc.) for the tables in the schema. This explains why the owner of a schema may not automatically have access to the tables and must take explicit steps to acquire those permissions.
Reference
Databricks Unity Catalog Documentation: Manage Permissions
[Databricks Permissions and Ownership](https://docs.databricks.com/security/access-control/workspace-acl.html#permissions
NEW QUESTION # 246
A data engineer is investigating a query in Databricks SQL that runs significantly slower than expected. Upon opening the Query Profile, the engineer notices that the node consuming the most elapsed time is a HashAggregate operator, yet the overall query still takes far longer than a similar query on a comparable dataset. The engineer suspects the HashAggregate node is the primary bottleneck and plans to focus all tuning efforts there.
Which approach should the data engineer use to identify the true performance bottleneck in the Query Profile?
Answer: C
Explanation:
Databricks Query Profile provides operator-level execution statistics, including rows processed, execution duration, memory consumption, and spilling behavior.
A HashAggregate operator with high elapsed time is not necessarily the original source of poor performance. Upstream joins can generate unexpectedly large intermediate datasets, forcing downstream aggregation operators to process substantially more records.
Cartesian products and inefficient nested-loop joins are particularly important to investigate because they can multiply row counts dramatically.
Option C correctly recommends examining the complete operator tree, comparing rows produced by successive operators, and identifying excessive data expansion or spilling.
Option A focuses exclusively on the visible symptom. Option B considers memory consumption but overlooks upstream causes. Option D assumes Photon compatibility is responsible without sufficient evidence.
Examining operator relationships provides a more accurate performance diagnosis.
Databricks on Google Cloud
NEW QUESTION # 247
Which of the following techniques structured streaming uses to ensure recovery of failures during stream processing?
Answer: E
Explanation:
Explanation
The answer is Checkpointing and write-ahead logging.
Structured Streaming uses checkpointing and write-ahead logs to record the offset range of data being processed during each trigger interval.
NEW QUESTION # 248
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver). The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 249
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.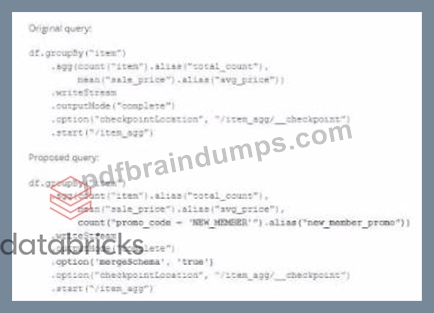
Which step must also be completed to put the proposed query into production?
Answer: B
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
Reference:
Databricks documentation on Structured Streaming: https://docs.databricks.com/spark/latest/structured-streaming/index.html Databricks documentation on streaming checkpoints: https://docs.databricks.com/spark/latest/structured-streaming/production.html#checkpointing
NEW QUESTION # 250
......
In modern society, innovation is of great significance to the survival of a company. The new technology of the Databricks-Certified-Professional-Data-Engineer study materials is developing so fast. So the competitiveness among companies about the study materials is fierce. Luckily, our company masters the core technology of developing the Databricks-Certified-Professional-Data-Engineer study materials. No company in the field can surpass us. So we still hold the strong strength in the market. At present, our Databricks-Certified-Professional-Data-Engineer study materials have applied for many patents. We attach great importance on the protection of our intellectual property. What is more, our research center has formed a group of professional experts responsible for researching new technology of the Databricks-Certified-Professional-Data-Engineer Study Materials. The technology of the Databricks-Certified-Professional-Data-Engineer study materials will be innovated every once in a while. As you can see, we never stop innovating new version of the Databricks-Certified-Professional-Data-Engineer study materials. We really need your strong support.
Databricks-Certified-Professional-Data-Engineer Latest Dumps Sheet: https://www.pdfbraindumps.com/Databricks-Certified-Professional-Data-Engineer_valid-braindumps.html