Vce DEA-C02 File & Exam DEA-C02 Outline

DOWNLOAD the newest DumpStillValid DEA-C02 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1ZXGnO0NycyJAZBLFAz4HWN0OJFZfuxLS
As far as we know, in the advanced development of electronic technology, lifelong learning has become more accessible, which means everyone has opportunities to achieve their own value and life dream though some ways such as the DEA-C02 certification. With over a decade’s endeavor, our DEA-C02 practice materials successfully become the most reliable products in the industry. There is a great deal of advantages of our DEA-C02 exam questions you can spare some time to get to know.
| Section | Weight | Objectives |
|---|
| Data Ingestion and Consumption | 20% | - Data Unloading
- 1. Data export best practices
- 2. Unloading to internal and external stages
- 3. Partitioning unloading data
- Bulk Loading and Unloading
- 1. COPY INTO command options and best practices
- 2. Handling staged files
- 3. File format options (CSV, JSON, Parquet, AVRO)
- 4. Data loading performance optimization
- Continuous Data Loading
- 1. Snowpipe configuration and usage
- 2. Real-time data ingestion patterns
- 3. Automating data loading with tasks
|
| Data Transformation with Snowflake | 30% | - Data Processing Patterns
- 1. Time travel and change data capture
- 2. Zero-copy cloning for ETL
- 3. MERGE, UPDATE, DELETE operations
- SQL Transformations
- 1. Complex JOINs and set operations
- 2. Window functions advanced usage
- 3. Data type conversions and handling
- 4. Working with semi-structured data (VARIANT)
- Snowflake Scripting
- 1. Procedures and control flow
- 2. Dynamic SQL
- 3. Error handling
|
| Performance Optimization | 15% | - Data Optimization
- 1. Materialized views
- 2. Search optimization service
- 3. Data cache management
- Query Optimization
- 1. Avoiding common performance pitfalls
- 2. Query profiling and analysis
- 3. Indexing strategies with clustering
- 4. Query result caching
- Warehouse Performance
- 1. Warehouse sizing and selection
- 2. Multi-cluster warehouses
- 3. Warehouse scaling policies
- 4. Resource monitors
|
| Data Architecture and Processing | 20% | - Data Pipeline Design
- 1. Pipeline monitoring and error handling
- 2. Data scheduling and orchestration
- 3. Stream and task patterns
- Data Storage Architecture
- 1. Hybrid Tables concepts
- 2. Table types (Permanent, Transient, Temporary)
- 3. Micro-partitioning and clustering
- Data Modeling for Performance
- 1. Star and snowflake schemas
- 2. Dimension handling
- 3. Slowly changing dimensions (SCD)
|
| Security and Governance | 15% | - Governance and Compliance
- 1. Row access policies
- 2. Object tagging
- 3. Access history and auditing
- 4. Data retention policies
- Access Control
- 1. Role-based access control (RBAC)
- 2. Role hierarchy and ownership
- 3. GRANT and REVOKE operations
- Data Security
- 1. Column-level security
- 2. External tokenization
- 3. Row-level security policies
- 4. Data masking and tokenization
|
>> Vce DEA-C02 File <<
Exam DEA-C02 Outline - Reliable DEA-C02 Dumps Questions
Your success is guaranteed if you choose our DEA-C02 training guide to prapare for you coming exam! The questions and answers format of our DEA-C02 exam braindumps is rich with the most accurate information and knowledage which are collected by our professional experts who have been in this career for over ten years. what is more, our DEA-C02 Study Guide also provides you the latest simulating exam to enhance your exam skills. So with our DEA-C02 learning questions, your success is guaranteed!
Snowflake SnowPro Advanced: Data Engineer (DEA-C02) Sample Questions (Q129-Q134):
NEW QUESTION # 129
You need to unload data from a Snowflake table named 'CUSTOMER DATA to an AWS S3 bucket The data should be unloaded in Parquet format, partitioned by the 'CUSTOMER REGION' column, and automatically compressed with GZIP. Furthermore, you only want to unload customers whose 'REGISTRATION DATE is after '2023-01-01'. Which of the following 'COPY INTO' statement correctly achieves this?
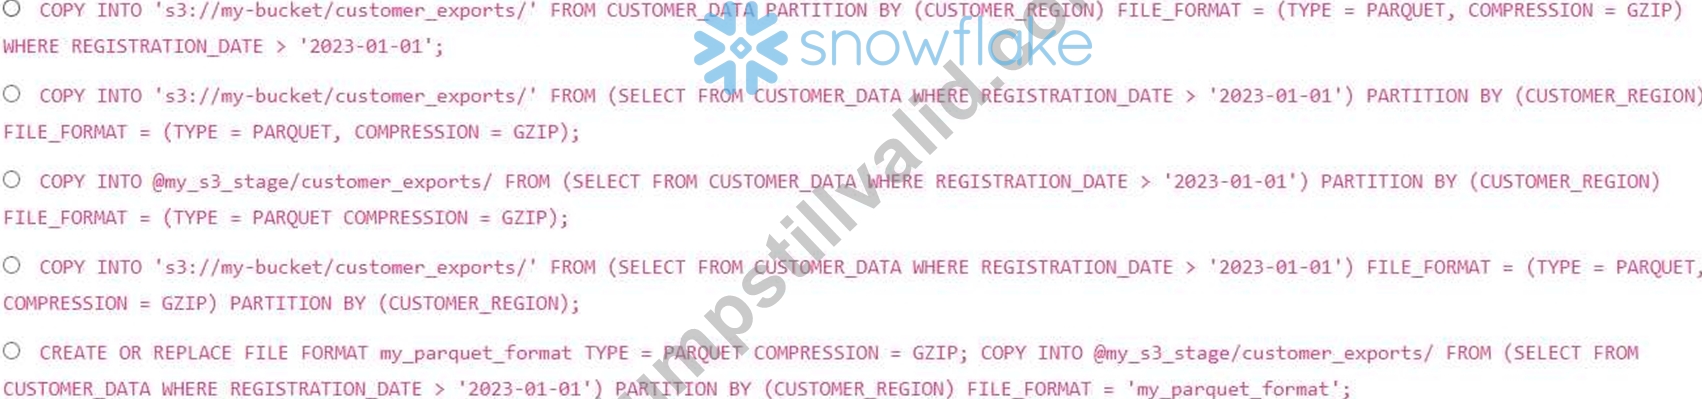
- A. Option A
- B. Option D
- C. Option C
- D. Option B
- E. Option E
Answer: E
Explanation:
The correct 'COPY INTO' statement requires using a named stage and a named file format. A subquery is used to filter the data based on the 'REGISTRATION_DATE. The 'PARTITION BY clause is used to partition the data by 'CUSTOMER REGION'. You must create a FILE FORMAT seperately and refer to it later. Other solutions have syntax errors, incorrect stage references, or incorrect ordering of clauses. Option 'A' doesn't use a stage nor it allows for a where condition. Option 'B' doesn't work since 'TYPE' and 'COMPRESSIONS are properties of a file format, not direct arguments to FILE_FORMAT. 'C' includes the 'TYPE and 'COMPRESSION' inline when this is not allowed. 'D' contains the same error with FILE FORMAT as 'C' and 'B' and does not use a stage.
NEW QUESTION # 130
You are designing a data pipeline using Snowpipe to ingest data from multiple S3 buckets into a single Snowflake table. Each S3 bucket represents a different data source and contains files in JSON format. You want to use Snowpipe's auto-ingest feature and a single Snowpipe object for all buckets to simplify management and reduce overhead. However, each data source has a different JSON schem a. How can you best achieve this goal while ensuring data is loaded correctly and efficiently into the target table?
- A. Create a separate Snowpipe for each S3 bucket. Although this creates more Snowpipe objects, it allows you to specify a different FILE FORMAT and transformation logic for each data source.
- B. Since Snowpipe cannot handle multiple schemas with a single pipe, pre-process the data in S3 using an AWS Lambda function to transform all files into a common schema before they are ingested by the Snowpipe.
- C. Use a single Snowpipe with a generic FILE FORMAT that can handle all possible JSON schemas. Implement a VIEW on top of the target table to transform and restructure the data based on the source bucket.
- D. Use a single Snowpipe and leverage Snowflake's ability to call a user-defined function (UDF) within the 'COPY INTO' statement to transform the data based on the S3 bucket path. The UDF can parse the bucket path and apply the appropriate JSON schema transformation.
- E. Use a single Snowpipe and leverage Snowflake's VARIANT data type to store the raw JSON data. Create separate external tables, each pointing to a specific S3 bucket, and use SQL queries to transform and load the data into the target table.
Answer: D
Explanation:
The most efficient and manageable approach is to use a single Snowpipe with a UDF to handle schema variations. The UDF can inspect the S3 bucket path (available as metadata within the 'COPY INTO' statement) and apply the correct transformation logic for each data source. Creating separate Snowpipes (A) adds unnecessary overhead. Using a generic 'FILE FORMAT and a VIEW (B) might work for simple transformations, but it becomes complex with significant schema differences. Using VARIANT and external tables (C) defeats the purpose of Snowpipe. Pre-processing in S3 (E) adds complexity outside of Snowflake. UDF provides schema flexibility during ingest and leverages Snowpipe's capabilities directly.
NEW QUESTION # 131
You are tasked with optimizing a continuous data pipeline that loads data from an external stage into a Snowflake table using streams.
The pipeline is experiencing significant latency during peak hours. The stream is defined on a very large table with frequent updates and deletes. Which of the following strategies would be MOST effective in reducing the latency of the data pipeline, considering stream performance and cost implications?
- A. Implement a materialized view on top of the stream to pre-aggregate the data.
- B. Create multiple streams on the same base table, each filtering for specific types of changes (e.g., INSERT, UPDATE, DELETE).
- C. Increase the size of the virtual warehouse used for loading data. This will provide more compute resources for processing the stream.
- D. Implement a more aggressive pruning strategy on the base table to reduce the amount of data that the stream needs to track.
- E. Reduce the RETENTION TIME of the stream. This will limit the amount of historical data tracked and improve performance.
Answer: D
Explanation:
Pruning on the base table directly reduces the amount of data the stream has to track, therefore improving performance. Increasing warehouse size (A) might help but is not directly related to the stream's efficiency. Creating multiple streams (C) will likely increase the overhead. Reducing RETENTION _ TIME (D) might lead to data loss if changes are not consumed promptly. A materialized view (E) consumes credits and does not directly affect stream performance. The correct answer focuses on minimizing the workload for the stream itself.
NEW QUESTION # 132
A data engineer is tasked with migrating data from a large on-premise Hadoop cluster to Snowflake using Spark. The Hadoop cluster contains nested JSON dat a. To optimize performance and minimize data transformation in Spark, what is the most efficient approach to read the JSON data into a Spark DataFrame and write it directly to a Snowflake table?
- A. Use the Snowflake Spark connector with the 'inferSchema' option set to 'true' when reading the JSON data. This allows Spark to automatically infer the schema and write directly to Snowflake.
- B. Use the 'STORAGE_INTEGRATION' feature in Snowflake to directly access the JSON files in Hadoop (via an external stage) and load the data without using Spark at all.
- C. Read the JSON data as text files, then use Spark to parse and flatten the JSON structure before writing to Snowflake using the Snowflake JDBC connector.
- D. Define a schema manually in Spark, then read the JSON data into a Spark DataFrame. Use the Snowflake Spark connector to write the data to Snowflake, specifying the schema explicitly.
- E. Read the JSON data as strings and utilize Snowflake's 'PARSE JSON' function within a Spark SQL query to transform and load the data into a variant column in Snowflake.
Answer: D
Explanation:
Defining a schema manually in Spark provides the most control over the data types and avoids potential schema inference issues. While Snowflake can parse JSON directly (option E and D), using Spark allows for potential transformations and data cleaning before loading. Option B's 'inferSchema' can be slow and may not accurately represent complex nested structures. Option A forces unnecessary string parsing in Spark, and direct access via STORAGE INTEGRATION bypasses the request to use spark connectors.
NEW QUESTION # 133
You accidentally truncated a large table named 'SALES DATA' in your 'REPORTING DB" database. You realize this happened 2 days ago, and your account has the default Time Travel retention of 1 day. You need to recover this table with minimal downtime. Analyze the situation and determine the best course of action, considering cost and recovery time.
- A. Immediately contact Snowflake Support to initiate a restore from Fail-safe, understanding that this process may take several hours or even days.
- B. Create a clone of the table using the 'AT clause and a timestamp from 1 day ago. This would prevent any additional cost.
- C. Increase the account-level to 2 days and then use the UNDROP TABLE SALES_DATA' command.
- D. Because the data retention period has expired, the table is unrecoverable using Snowflake's built-in features; you must restore from an external backup solution if available.
- E. Raise a support ticket requesting data recovery from failsafe. Since data retention period has expired.
Answer: A
Explanation:
Since the Time Travel window (1 day) has passed, the 'UNDROP' command and cloning using or 'BEFORE clauses will not work (eliminating options B and D). While option C might be true if no external backups exist, the most appropriate first step is to contact Snowflake support (option A). This is because, even though Time Travel has expired, Fail-safe might still contain the data, offering a potential recovery path, although it is a longer process and not guaranteed. Option E is also a valid answer.
NEW QUESTION # 134
......
Snowflake DEA-C02 is a certification exam to test IT expertise and skills. If you find a job in the IT industry, many human resource managers in the interview will reference what Snowflake related certification you have. If you have Snowflake DEA-C02 Certification, apparently, it can improve your competitiveness.
Exam DEA-C02 Outline: https://www.dumpstillvalid.com/DEA-C02-prep4sure-review.html
- Newest Vce DEA-C02 File - Pass DEA-C02 Exam 🍸 Enter ➽ www.pass4test.com 🢪 and search for ⇛ DEA-C02 ⇚ to download for free ♿Upgrade DEA-C02 Dumps
- DEA-C02 Reliable Practice Materials 💍 DEA-C02 Exam Training 🦗 DEA-C02 Valid Test Preparation 🎉 Simply search for ( DEA-C02 ) for free download on ( www.pdfvce.com ) 👲DEA-C02 Valid Test Dumps
- Free DEA-C02 Brain Dumps 📤 Test DEA-C02 Dumps Demo 🥂 DEA-C02 Exam Training 💯 Copy URL ➤ www.testkingpass.com ⮘ open and search for ( DEA-C02 ) to download for free ⌛DEA-C02 Examcollection Questions Answers
- Three Snowflake DEA-C02 Exam Questions Formats - Make Your Exam Preparation Easy 🍱 Open website ▛ www.pdfvce.com ▟ and search for { DEA-C02 } for free download 🏜DEA-C02 Exam Price
- 100% Pass Quiz Snowflake - Accurate DEA-C02 - Vce SnowPro Advanced: Data Engineer (DEA-C02) File 🦠 The page for free download of ➤ DEA-C02 ⮘ on 《 www.examcollectionpass.com 》 will open immediately 🪓DEA-C02 Valid Test Dumps
- Top Vce DEA-C02 File 100% Pass | Professional DEA-C02: SnowPro Advanced: Data Engineer (DEA-C02) 100% Pass 🔒 Simply search for ➽ DEA-C02 🢪 for free download on 【 www.pdfvce.com 】 🍬Upgrade DEA-C02 Dumps
- Latest SnowPro Advanced: Data Engineer (DEA-C02) vce dumps - DEA-C02 prep4sure exam 👜 Download ▶ DEA-C02 ◀ for free by simply entering ▷ www.torrentvce.com ◁ website 🎊DEA-C02 Reliable Test Simulator
- Upgrade DEA-C02 Dumps 👆 DEA-C02 Exam Discount 🐦 DEA-C02 Valid Test Dumps 🤣 Open website ⮆ www.pdfvce.com ⮄ and search for [ DEA-C02 ] for free download 😨DEA-C02 Test Pdf
- DEA-C02 Valid Test Dumps 🦗 DEA-C02 Vce Files 🍻 DEA-C02 Reliable Practice Materials 🏃 Search for ▛ DEA-C02 ▟ on ➡ www.easy4engine.com ️⬅️ immediately to obtain a free download ⌚DEA-C02 Valid Test Dumps
- Newest Vce DEA-C02 File - Pass DEA-C02 Exam 😖 The page for free download of ▛ DEA-C02 ▟ on ➤ www.pdfvce.com ⮘ will open immediately 🦥DEA-C02 Examcollection Questions Answers
- DEA-C02 Valid Test Topics 👴 Upgrade DEA-C02 Dumps 🕡 DEA-C02 Valid Test Topics 🤴 Immediately open 【 www.vce4dumps.com 】 and search for ➽ DEA-C02 🢪 to obtain a free download 😬Detailed DEA-C02 Answers
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, jacobscott67888.blogspot.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free 2026 Snowflake DEA-C02 dumps are available on Google Drive shared by DumpStillValid: https://drive.google.com/open?id=1ZXGnO0NycyJAZBLFAz4HWN0OJFZfuxLS