Microsoft 인증AI-103인증시험공부자료는ITDumpsKR에서 제공해드리는Microsoft 인증AI-103덤프가 가장 좋은 선택입니다. ITDumpsKR에서는 시험문제가 업데이트되면 덤프도 업데이트 진행하도록 최선을 다하여 업데이트서비스를 제공해드려 고객님께서소유하신 덤프가 시장에서 가장 최신버전덤프로 되도록 보장하여 시험을 맞이할수 있게 도와드립니다.
| Section | Objectives |
|---|---|
| Plan and Manage Azure AI Solutions | - Azure AI resource provisioning and configuration - Model selection and lifecycle management - Responsible AI principles and governance |
| Knowledge Mining and Information Retrieval | - Azure AI Search configuration - RAG (Retrieval Augmented Generation) patterns - Indexing and semantic search |
| Develop Generative AI Applications and Agents | - AI agents architecture
|
| Implement Computer Vision Solutions | - Image classification and object detection - OCR and document intelligence |
| Implement Natural Language Processing Solutions | - Language understanding and intent recognition - Translation and multilingual support - Text analytics and summarization |
Microsoft AI-103인증시험에 응시하고 싶으시다면 좋은 학습자료와 학습 가이드가 필요합니다.Microsoft AI-103시험은 it업계에서도 아주 중요한 인증입니다. 시험패스를 원하신다면 충분한 시험준비는 필수입니다.
질문 # 143
You have a Microsoft Foundry project that serves a high-volume chat app.
Most requests are simple FAQs, but some require advanced reasoning.
You need to reduce costs and latency for common queries, without degrading the quality of the responses to complex questions.
What should you do?
정답:C
설명:
The correct choice is to use a model cascade that routes the requests to different models . In Microsoft Foundry, this pattern aligns with model routing: simple, low-risk prompts can be handled by smaller, faster, lower-cost models, while complex prompts can be escalated to more capable or reasoning models. Microsoft's Foundry model router guidance states that the router optimizes cost and latency while maintaining comparable quality by using smaller, cheaper models when they are sufficient and larger or reasoning models when the task requires more advanced capability.
This directly matches the scenario: most traffic consists of simple FAQs, so routing those requests to efficient models reduces average latency and token-processing cost. Advanced reasoning requests still receive high- quality responses because they are routed to models with stronger reasoning capability. Microsoft's model router documentation also explains that routing decisions consider prompt difficulty, cost, quality, latency, and conversation context, making it suitable for diverse chat workloads.
Increasing max_tokens for all requests would usually increase cost and latency. Sending all requests to a smaller model risks poor quality for complex questions, while sending all requests to the most capable model wastes cost and latency on simple FAQs. Reference topics: Microsoft Foundry model routing, model selection, generative AI optimization, latency management, and cost-aware AI application design.
질문 # 144
You are developing a new sales system that will process user-generated video and text from a public-facing website.
You plan to notify users that their data has been processed by the sales system.
Which responsible AI principle does this help meet?
정답:B
설명:
Notifying users that their data has been processed by your sales system fulfills the Transparency responsible AI principle. Transparency ensures that users are informed about how their data is collected and processed, which helps foster understanding and build trust between users and technology providers.
Reference:
https://learn.microsoft.com/en-us/microsoft-copilot-studio/guidance/responsible-ai
질문 # 145
You have a Microsoft Foundry project that contains an agent. The agent has a Model Context Protocol (MCP) tool that queries a knowledge base stored in Azure AI Search.
Some agent runs return answers from the base model without invoking the knowledge base, which results in responses without grounded citations.
You are provided with the following code snippet that runs the agent.
run = project_client.agents.runs.create_and_process(
thread_id=thread.id,
agent_id=agent.id,
)
You need to add the correct tool_choice parameter to the code to deterministically force the agent to invoke the MCP tool on each run.
What should you add?
정답:D
설명:
The correct selection is D . In Microsoft Foundry Agent Service, tool_choice is the runtime control used to influence whether the model may answer directly or must invoke a tool. Microsoft's tool best-practice guidance states that auto lets the model decide whether to call tools, none prevents tool calls, and required means the model must call one or more tools. This directly addresses the issue where some runs answer from the base model and skip the knowledge base.
For an agentic retrieval solution backed by Azure AI Search through an MCP tool, Microsoft's tutorial states that setting tool_choice= " required " ensures the agent always uses the knowledge base tool when processing queries. This produces grounded answers because the run is forced into tool invocation before responding.
auto is incorrect because it preserves the nondeterministic behavior already causing missing citations. { " type
" : " knowledge_base " } is not a valid Foundry tool-choice type. { " type " : " mcp " } describes an MCP tool type in some Responses API schemas, but the deterministic guarantee for this agent run scenario is the required tool-call mode. Reference topics: Microsoft Foundry Agent Service, MCP tools, Azure AI Search agentic retrieval, tool_choice, and grounded citations.
질문 # 146
You have a Microsoft Foundry project.
You plan to build a customer support solution that contains an agent. The solution must meet the following requirements:
* Provide accurate, context-aware responses grounded in internal product documentation stored in Azure AI Search.
* Require deep, multi-step reasoning across long contexts.
* Generate detailed natural language responses.
Which type of model should you use to power the agent?
정답:D
설명:
The correct model type is a large language model (LLM) . The scenario requires an agent that can reason over retrieved documentation, synthesize context-aware answers, and generate detailed natural language responses. Microsoft Foundry RAG guidance defines Retrieval Augmented Generation as a pattern that combines search with large language models so responses are grounded in organizational data, which directly matches the use of Azure AI Search for internal product documentation.
An LLM is also the correct fit for deep, multi-step reasoning across long contexts. Azure AI Search agentic retrieval guidance states that complex chat and agent scenarios use an LLM to break a user query into smaller focused subqueries for better coverage over indexed content. Microsoft also describes Azure AI Search as a way to ground agents and chatbots in proprietary enterprise data for accurate, context-aware responses.
A multimodal model is unnecessary because the requirements are text-focused, not image, audio, or video based. A key phrase extraction model performs narrow text analytics and cannot generate detailed answers.
An SLM may reduce cost and latency, but the stated need for deep reasoning and long-context synthesis favors an LLM. Reference topics: Microsoft Foundry RAG, Azure AI Search grounding, agentic retrieval, and model selection for generative AI agents.
질문 # 147
You have a Microsoft Foundry project that contains a customer support agent grounded in internal documentation.
After a recent update, users report the following issues:
* Some answers are unsupported by retrieved documents.
* A small number of responses are flagged for policy violations.
You need to evaluate each issue.
Which observability signals should you use for each issue? To answer, drag the appropriate observability signals to the correct issues. Each observability signal may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.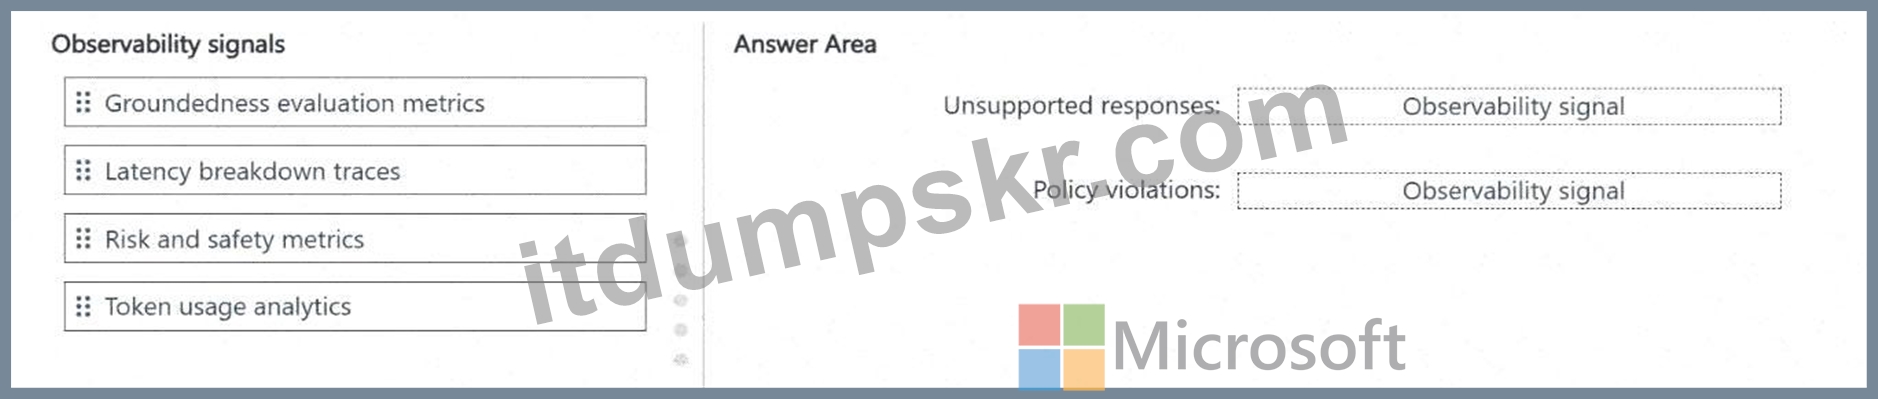
정답:
설명: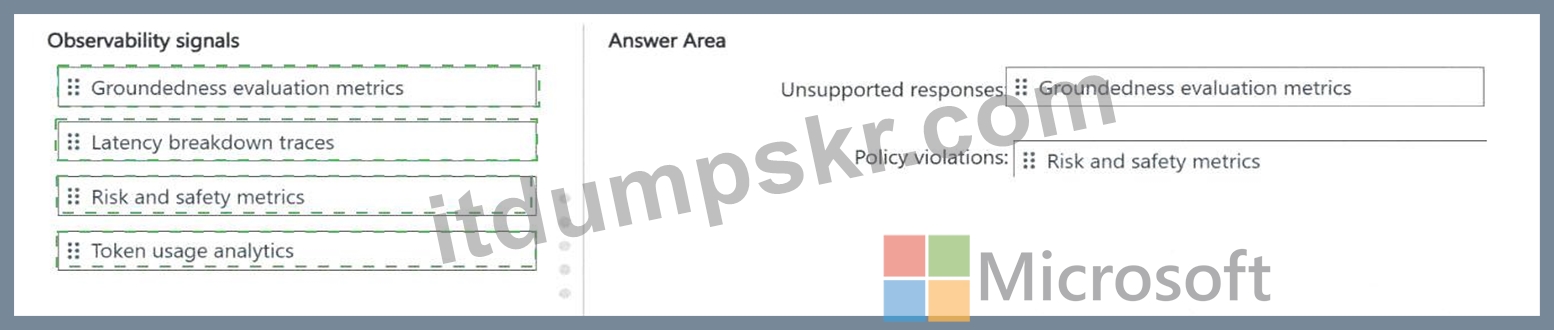
Explanation:
Unsupported responses: Groundedness evaluation metrics
Policy violations: Risk and safety metrics
For unsupported responses, use Groundedness evaluation metrics . In a Retrieval Augmented Generation scenario, the key question is whether the generated answer is supported by the retrieved context. Microsoft Foundry built-in evaluators define Groundedness as the RAG metric that measures how grounded a response is in retrieved context and returns a model-based score; Groundedness Pro evaluates whether the response is grounded in retrieved context by using Azure AI Content Safety. This directly matches answers that are unsupported by internal documentation.
For policy violations, use Risk and safety metrics . Microsoft Foundry risk and safety evaluators assess generated responses for safety risks such as hate and unfairness, sexual content, violence, self-harm, protected material, indirect attacks, code vulnerability, ungrounded attributes, prohibited actions, and sensitive data leakage. The guidance states that these evaluators assign risk and safety severity or pass/fail outcomes for AI responses and agent behavior.
Latency breakdown traces diagnose performance, not correctness or policy compliance. Token usage analytics diagnose cost and prompt/response size, not unsupported claims or safety violations. Reference topics:
Microsoft Foundry observability, RAG evaluators, groundedness, risk and safety evaluators, and agent quality evaluation.
질문 # 148
......
ITDumpsKR는 고품질의 IT Microsoft AI-103시험공부자료를 제공하는 차별화 된 사이트입니다. ITDumpsKR는Microsoft AI-103응시자들이 처음 시도하는Microsoft AI-103시험에서의 합격을 도와드립니다. 가장 적은 시간은 투자하여 어려운Microsoft AI-103시험을 통과하여 자격증을 많이 취득하셔서 IT업계에서 자신만의 가치를 찾으세요.
AI-103테스트자료: https://www.itdumpskr.com/AI-103-exam.html