DOWNLOAD the newest DumpsTorrent Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1veYnob3wFp3oQRxeTj8ACunDpm5bwVLj
You only need 20-30 hours to practice our software materials and then you can attend the exam. It costs you little time and energy. The Databricks-Generative-AI-Engineer-Associate exam questions are easy to be mastered and simplified the content of important information. The Databricks Certified Generative AI Engineer Associate test guide conveys more important information with amount of answers and questions, thus the learning for the examinee is easy and highly efficient. The language which is easy to be understood and simple, Databricks-Generative-AI-Engineer-Associate Exam Questions are suitable for any learners no matter he or she is a student or the person who have worked for many years with profound experiences. So it is convenient for the learners to master the Databricks-Generative-AI-Engineer-Associate guide torrent and pass the exam in a short time. The amount of the examinee is large.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> New Databricks-Generative-AI-Engineer-Associate Test Camp <<
Our Databricks-Generative-AI-Engineer-Associate practice materials have picked out all knowledge points for you, which helps you get rid of many problems. In addition, time is money in modern society. It is important achieve all things efficiently. So our Databricks-Generative-AI-Engineer-Associate study guide just needs less time input, which can suit all people’s demands. In the meantime, all knowledge points of our Databricks-Generative-AI-Engineer-Associate Preparation questions have been adapted and compiled carefully to ensure that you absolutely can understand it quickly.
NEW QUESTION # 45
A Generative AI Engineer has been asked to design an LLM-based application that accomplishes the following business objective: answer employee HR questions using HR PDF documentation.
Which set of high level tasks should the Generative AI Engineer's system perform?
Answer: B
Explanation:
To design an LLM-based application that can answer employee HR questions using HR PDF documentation, the most effective approach is option D. Here's why:
Chunking and Vector Store Embedding:
HR documentation tends to be lengthy, so splitting it into smaller, manageable chunks helps optimize retrieval. These chunks are then embedded into a vector store (a database that stores vector representations of text). Each chunk of text is transformed into an embedding using a transformer-based model, which allows for efficient similarity-based retrieval.
Using Vector Search for Retrieval:
When an employee asks a question, the system converts their query into an embedding as well. This embedding is then compared with the embeddings of the document chunks in the vector store. The most semantically similar chunks are retrieved, which ensures that the answer is based on the most relevant parts of the documentation.
LLM to Generate a Response:
Once the relevant chunks are retrieved, these chunks are passed into the LLM, which uses them as context to generate a coherent and accurate response to the employee's question.
Why Other Options Are Less Suitable:
A (Calculate Averaged Embeddings): Averaging embeddings might dilute important information. It doesn't provide enough granularity to focus on specific sections of documents.
B (Summarize HR Documentation): Summarization loses the detail necessary for HR-related queries, which are often specific. It would likely miss the mark for more detailed inquiries.
C (Interaction Matrix and ALS): This approach is better suited for recommendation systems and not for HR queries, as it's focused on collaborative filtering rather than text-based retrieval.
Thus, option D is the most effective solution for providing precise and contextual answers based on HR documentation.
NEW QUESTION # 46
A Generative Al Engineer is creating an LLM system that will retrieve news articles from the year 1918 and related to a user's query and summarize them. The engineer has noticed that the summaries are generated well but often also include an explanation of how the summary was generated, which is undesirable.
Which change could the Generative Al Engineer perform to mitigate this issue?
Answer: B
Explanation:
To mitigate the issue of the LLM including explanations of how summaries are generated in its output, the best approach is to adjust the training or prompt structure. Here's why Option D is effective:
* Few-shot Learning: By providing specific examples of how the desired output should look (i.e., just the summary without explanation), the model learns the preferred format. This few-shot learning approach helps the model understand not only what content to generate but also how to format its responses.
* Prompt Engineering: Adjusting the user prompt to specify the desired output format clearly can guide the LLM to produce summaries without additional explanatory text. Effective prompt design is crucial in controlling the behavior of generative models.
Why Other Options Are Less Suitable:
* A: While technically feasible, splitting the output by newline and truncating could lead to loss of important content or create awkward breaks in the summary.
* B: Tuning chunk sizes or changing embedding models does not directly address the issue of the model's tendency to generate explanations along with summaries.
* C: Revisiting document ingestion logic ensures accurate source data but does not influence how the model formats its output.
By using few-shot examples and refining the prompt, the engineer directly influences the output format, making this approach the most targeted and effective solution.
NEW QUESTION # 47
A Generative Al Engineer is setting up a Databricks Vector Search that will lookup news articles by topic within 10 days of the date specified An example query might be "Tell me about monster truck news around January 5th 1992". They want to do this with the least amount of effort.
How can they set up their Vector Search index to support this use case?
Answer: D
Explanation:
The task is to set up a Databricks Vector Search index for news articles, supporting queries like "monster truck news around January 5th, 1992," with minimal effort. The index must filter by topic and a 10-day date range. Let's evaluate the options.
Option A: Split articles by 10-day blocks and return the block closest to the query Pre-splitting articles into 10-day blocks requires significant preprocessing and index management (e.g., one index per block). It's effort-intensive and inflexible for dynamic date ranges.
Databricks Reference: "Static partitioning increases setup complexity; metadata filtering is preferred" ("Databricks Vector Search Documentation").
Option B: Include metadata columns for article date and topic to support metadata filtering Adding date and topic as metadata in the Vector Search index allows dynamic filtering (e.g., date ± 5 days, topic = "monster truck") at query time. This leverages Databricks' built-in metadata filtering, minimizing setup effort.
Databricks Reference: "Vector Search supports metadata filtering on columns like date or category for precise retrieval with minimal preprocessing" ("Vector Search Guide," 2023).
Option C: Pass the query directly to the vector search index and return the best articles Passing the full query (e.g., "Tell me about monster truck news around January 5th, 1992") to Vector Search relies solely on embeddings, ignoring structured filtering for date and topic. This risks inaccurate results without explicit range logic.
Databricks Reference: "Pure vector similarity may not handle temporal or categorical constraints effectively" ("Building LLM Applications with Databricks").
Option D: Create separate indexes by topic and add a classifier model to appropriately pick the best index Separate indexes per topic plus a classifier model adds significant complexity (index creation, model training, maintenance), far exceeding "least effort." It's overkill for this use case.
Databricks Reference: "Multiple indexes increase overhead; single-index with metadata is simpler" ("Databricks Vector Search Documentation").
Conclusion: Option B is the simplest and most effective solution, using metadata filtering in a single Vector Search index to handle date ranges and topics, aligning with Databricks' emphasis on efficient, low-effort setups.
NEW QUESTION # 48
After changing the response generating LLM in a RAG pipeline from GPT-4 to a model with a shorter context length that the company self-hosts, the Generative AI Engineer is getting the following error:
What TWO solutions should the Generative AI Engineer implement without changing the response generating model? (Choose two.)
Answer: A,D
Explanation:
Problem Context: After switching to a model with a shorter context length, the error message indicating that the prompt token count has exceeded the limit suggests that the input to the model is too large.
Explanation of Options:
Option A: Use a smaller embedding model to generate - This wouldn't necessarily address the issue of prompt size exceeding the model's token limit.
Option B: Reduce the maximum output tokens of the new model - This option affects the output length, not the size of the input being too large.
Option C: Decrease the chunk size of embedded documents - This would help reduce the size of each document chunk fed into the model, ensuring that the input remains within the model's context length limitations.
Option D: Reduce the number of records retrieved from the vector database - By retrieving fewer records, the total input size to the model can be managed more effectively, keeping it within the allowable token limits.
Option E: Retrain the response generating model using ALiBi - Retraining the model is contrary to the stipulation not to change the response generating model.
Options C and D are the most effective solutions to manage the model's shorter context length without changing the model itself, by adjusting the input size both in terms of individual document size and total documents retrieved.
NEW QUESTION # 49
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: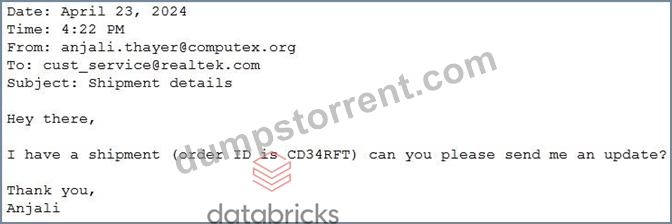
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: C
Explanation:
* Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM's responses.
* Explanation of Options:
Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore, Option B is optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 50
......
DumpsTorrent has made the Databricks-Generative-AI-Engineer-Associate exam dumps after consulting with professionals and getting positive feedback from customers. The team of DumpsTorrent has worked hard in making this product a successful Databricks Databricks-Generative-AI-Engineer-Associate Study Material. So we guarantee that you will not face issues anymore in passing the Databricks Databricks-Generative-AI-Engineer-Associate certification test with good grades.
Standard Databricks-Generative-AI-Engineer-Associate Answers: https://www.dumpstorrent.com/Databricks-Generative-AI-Engineer-Associate-exam-dumps-torrent.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by DumpsTorrent: https://drive.google.com/open?id=1veYnob3wFp3oQRxeTj8ACunDpm5bwVLj