Microsoft AI-500 덤프의 높은 적중율에 놀란 회원분들이 계십니다. 고객님들의 도와 Microsoft AI-500 시험을 쉽게 패스하는게 저희의 취지이자 최선을 다해 더욱 높은 적중율을 자랑할수 있다록 노력하고 있습니다. 뿐만 아니라 PassTIP에서는한국어 온라인서비스상담, 구매후 일년무료업데이트서비스, 불합격받을수 환불혹은 덤프교환 등탄탄한 구매후 서비스를 제공해드립니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize operational performance
|
| Topic 2: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security
|
| Topic 4: Develop multi-agent solutions in Azure | 30-35% | - Build and integrate tool ecosystems
|
PassTIP의 Microsoft인증 AI-500덤프를 공부하여Microsoft인증 AI-500시험을 패스하는건 아주 간단한 일입니다.저희 사이트에서 제작한Microsoft인증 AI-500덤프공부가이드는 실제시험의 모든 유형과 범위가 커버되어있어 높은 적중율을 자랑합니다.시험에서 불합격시 덤프비용은 환불신청 가능하기에 안심하고 시험준비하시면 됩니다.
질문 # 63
You have a multi-agent solution in a Microsoft Foundry project. The project connects to an Azure Storage account named stgaudit.
You plan to enable a storage-backed tool for the agent The tool will read and write blobs to stgaudit.
You need to create a role assignment for the agent. The solution must follow the principle of least privilege.
Which role should you use?
정답:C
질문 # 64
You have a Microsoft Foundry multi-agent solution that routes requests from an intake agent to a retrieval agent, and then to a resolution agent. The retrieval agent uses a knowledge search tool.
Security testing reveals the following recurring issues:
* Some users submit jailbreak-style prompts at the start of a conversation.
* Some retrieved documents contain hidden instructions intended to manipulate the downstream agent The legal department at your company requires that final responses be flagged for review if they contain protected text. You need to configure guardrails to resolve the security issues and meet the legal requirements.
What should you configure?
정답:A
설명:
The three risks occur at three different intervention points. Direct jailbreak attempts originate in the user prompt, so User input attacks should be evaluated at the User input boundary and blocked. Malicious instructions embedded in retrieved documents are indirect prompt-injection attacks and belong at the Tool response boundary before the retrieved content can influence downstream reasoning. Protected material in the final response must be flagged for legal review, not necessarily blocked, so an Output control using annotate- only behavior matches the requirement. Options A and B misplace at least one control or block content that the scenario says should only be flagged. Microsoft Foundry guardrails are explicitly designed around these intervention points, making C the configuration that aligns each risk with the stage where it can be detected and acted upon. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Microsoft Foundry guardrails - intervention points
질문 # 65
You have a LangGraph multi-agent workflow that uses Azure Cosmos DB as a checkpointer.
You plan to change the pruning rules for the running message list before the next release You need to implement evaluations tor memory. The solution must meet the following requirements:
* Verify that claim-related state values remain correct at transition points.
* Verify that conversation context is preserved after an interruption.
* Identify the source of any loss of continuity during a run
Which three actions should you perform Each correct answer presents part of the solution NOTE: Each correct selection is worth one point.
정답:A,B,E
설명:
Memory evaluation must verify persistence across interruption, correctness of checkpointed state, and enough telemetry to locate where continuity was lost. Running a scripted multi-turn case with one stable `thread_id` before and after a restart directly tests whether the Cosmos-backed LangGraph checkpointer restores the same conversation/workflow. Comparing persisted checkpoint documents with expected state values at each handoff verifies that claim-related state has not been corrupted by the new pruning rules. Correlating the evaluation run with trace spans then provides the diagnostic path to identify which agent transition or state- management operation caused a failure. Changing the thread ID each turn would intentionally create separate state scopes, and removing durable artifacts would defeat the persistence test. Tool-call arguments alone do not prove workflow-memory continuity. Therefore D, E, and F are the complementary actions required. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Azure Cosmos DB integrations for LangGraph and agent state
질문 # 66
You are designing a multitenant software as a service (SaaS) platform that uses multiple agents. Users will send latency-sensitive inference requests to the platform by using a shared API.
Initially, there will be 20 tenants, and the platform will expand to 200 tenants.
You need to identify the compute component for a production agent runtime. The solution must meet the following requirements:
Isolate workloads for each tenant by using containerization.
Dynamically scale based on demand.
Minimize administrative effort.
What should you use?
정답:A
설명:
Microsoft Foundry Agent Service is the managed option that best satisfies containerized production agent execution, dynamic scaling, and low administrative overhead. Hosted agents run in Foundry-managed container compute and scale according to workload demand while the platform manages much of the runtime, endpoint, identity, and operational plumbing. AKS could provide strong tenant/workload isolation and autoscaling, but it also requires Kubernetes cluster operations, policy, upgrades, node pools, and scaling configuration, which conflicts with the requirement to minimize administration as the tenant count grows.
Azure Container Instances is simpler but lacks the same managed autoscaling model, and GPU virtual machines create the highest infrastructure burden. Therefore C is the strongest fit for a SaaS platform that wants production agent compute without owning the orchestration platform. From an architecture perspective, the selection also creates explicit ownership and boundaries that can be tested independently. That matters in multi-agent systems because implicit sharing or loosely defined authority often becomes the source of cross- agent coupling, security drift, and difficult incident diagnosis.
Official Microsoft reference: Microsoft Foundry Agent Service overview
질문 # 67
You have a Microsoft Foundry multi-agent solution. The solution includes an orchestrator that uses Azure Al Search as a semantic cache to shortlist agents and invokes the top match.
You have a version-controlled repository that contains a curated dataset, expected routing, and expected responses. A pull request adds an agent named Agent 1, new sample utterances, and a changed selector prompt.
You need to configure an automated prerelease evaluation gate for the pull request. The solution must meet the following requirements:
* Validate the integrated system response after the new agent is available to orchestration.
* Validate the semantic cache retrieval quality against the expected results.
* Keep regression tests aligned with the pull request changes.
How should you configure the evaluation gate? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.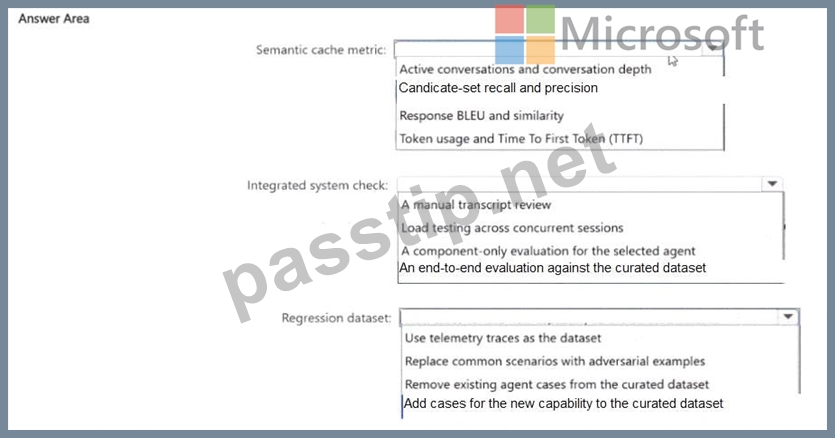
정답:
설명: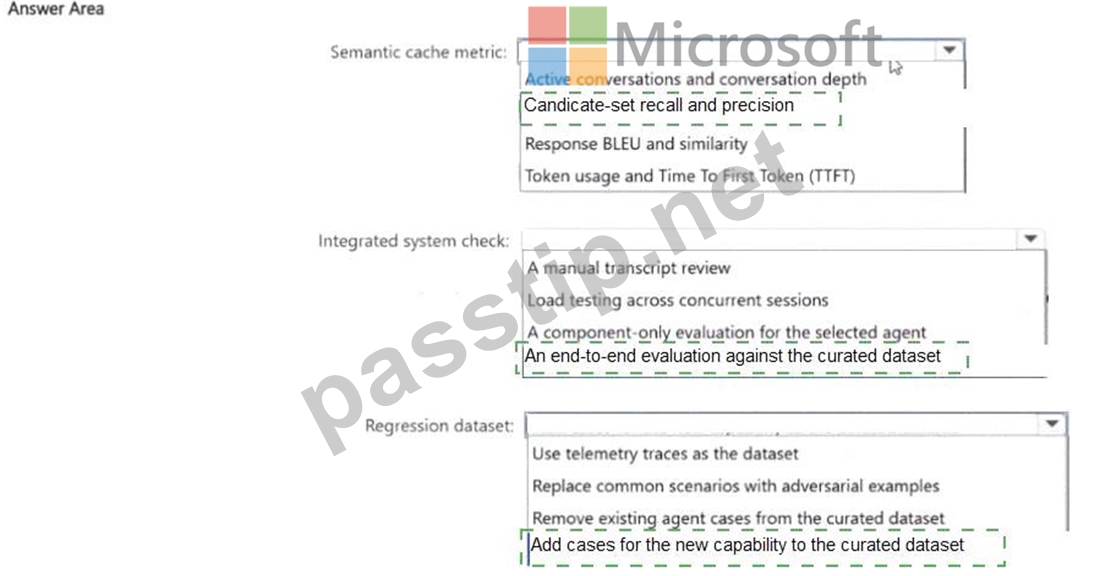
Explanation:
Semantic cache metric: Candidate-set recall and precision; Integrated system check: An end-to-end evaluation against the curated dataset; Regression dataset: Add cases for the new capability to the curated dataset.
The semantic cache is acting as a retrieval/shortlisting component, so recall and precision are the appropriate measures of whether expected agent candidates are surfaced and whether irrelevant candidates are avoided.
The pull request also changes the selector prompt and adds an agent, so component-only tests are insufficient; an end-to-end evaluation must exercise retrieval, routing, the new agent, and final response generation together. Finally, the version-controlled regression dataset should evolve with the capability. Adding representative cases for the new agent keeps expected routing and responses aligned with the code and prompt changes in the pull request. Microsoft Foundry evaluation guidance treats curated datasets as reusable regression assets for CI/CD quality gates. Together, these three selections test retrieval quality, integrated behavior, and regression coverage at the correct layers. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - evaluation datasets and CI/CD evaluation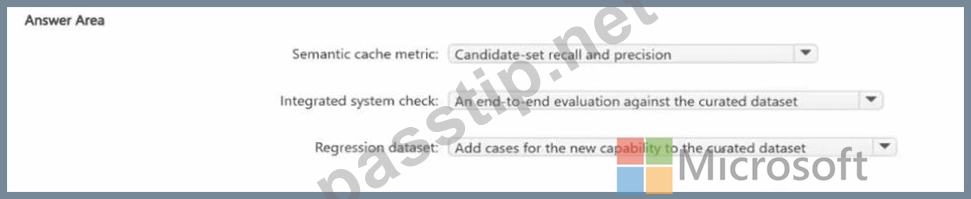
질문 # 68
......
우리PassTIP 에서 제공하는 학습가이드에는 IT전문가들이 만들어낸 시험대비 자료들과Microsoft AI-500인증시험의 완벽한 문제와 답들입니다. 그리고 우리PassTIP에서는 IT업계에서의 높은 신뢰감으로 여러분들한테 100%보장을 드립니다. 우리에 믿음을 드리기 위하여Microsoft AI-500관련자료의 일부분 문제와 답 등 샘플을 무료로 다운받아 체험해볼수 있게 제공합니다.
AI-500최고품질 시험덤프 공부자료: https://www.passtip.net/AI-500-pass-exam.html