Reliable Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions | Databricks-Certified-Data-Engineer-Professional Practice Exam
Our Databricks-Certified-Data-Engineer-Professional study materials have enough confidence to provide the best Databricks-Certified-Data-Engineer-Professional exam torrent for your study to pass it. With many years work experience, we have fast reaction speed to market change and need. In this way, we have the latest Databricks-Certified-Data-Engineer-Professional guide torrent. You don't worry about that how to keep up with the market trend, just follow us. We can say that our Databricks-Certified-Data-Engineer-Professional Test Questions are the most suitable for examinee to pass the Databricks-Certified-Data-Engineer-Professional exam, you will never regret to buy it.
| Section | Weight | Objectives |
|---|
| Ensuring Data Security and Compliance | 10% | - Implement access control and permissions
- Ensure data privacy and compliance
- Secure data at rest and in transit
|
| Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing
- Manage cross-platform data access
- Implement Lakehouse Federation
|
| Debugging and Deploying | 10% | - Deploy using Asset Bundles, CLI, and APIs
- Troubleshoot and debug pipelines
- Implement CI/CD and DevOps practices
|
| Monitoring and Alerting | 10% | - Set up alerts and notifications
- Monitor pipeline performance and health
- Track data lineage and metrics
|
| Data Governance | 7% | - Manage data assets and metadata
- Enforce data policies and standards
- Use Unity Catalog for governance
|
| Data Ingestion & Acquisition | 7% | - Ingest data from diverse sources
- Use Auto Loader and structured streaming
- Handle incremental and batch data loads
|
| Data Transformation, Cleansing, and Quality | 10% | - Enforce data quality standards
- Implement schema evolution and management
- Apply data cleansing and validation rules
|
| Data Modelling | 6% | - Optimize table design and partitioning
- Design Medallion Architecture
- Implement dimensional and relational models
|
| Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic
- Use Databricks-specific libraries and APIs
- Write efficient and maintainable code
|
| Cost & Performance Optimisation | 13% | - Apply cost management best practices
- Optimize compute and storage resources
- Improve query and pipeline performance
|
>> Reliable Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions <<
Databricks-Certified-Data-Engineer-Professional Practice Exam, Databricks-Certified-Data-Engineer-Professional Reliable Dumps
This confusion leads to choosing outdated material and ultimately failure in the test. The best way to avoid failure is using updated and real questions. ExamPrepAway has come up with real Databricks Databricks-Certified-Data-Engineer-Professional Questions for students so they can pass Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam in a single try and get to their destination. ExamPrepAway has made this study material after consulting with the professionals and getting their positive feedback.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q189-Q194):
NEW QUESTION # 189
In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone. A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.
Why are the cloned tables no longer working?
- A. Running vacuum automatically invalidates any shallow clones of a table; deep clone should always be used when a cloned table will be repeatedly queried.
- B. The metadata created by the clone operation is referencing data files that were purged as invalid by the vacuum command
- C. The data files compacted by vacuum are not tracked by the cloned metadata; running refresh on the cloned table will pull in recent changes.
- D. Because Type 1 changes overwrite existing records, Delta Lake cannot guarantee data consistency for cloned tables.
- E. Tables created with SHALLOW CLONE are automatically deleted after their default retention threshold of 7 days.
Answer: B
Explanation:
In Delta Lake, a shallow clone creates a new table by copying the metadata of the source table without duplicating the data files. When the vacuum command is run on the source table, it removes old data files that are no longer needed to maintain the transactional log's integrity, potentially including files referenced by the shallow clone's metadata. If these files are purged, the shallow cloned tables will reference non-existent data files, causing them to stop working properly. This highlights the dependency of shallow clones on the source table's data files and the impact of data management operations like vacuum on these clones.
NEW QUESTION # 190
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
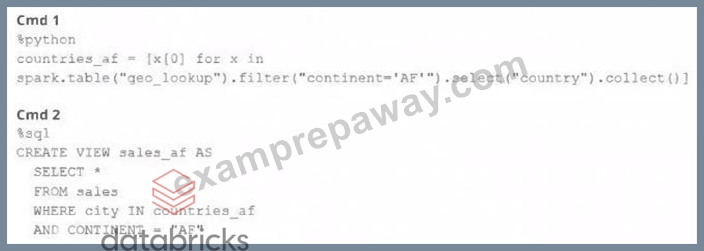
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
- A. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable representing a PySpark DataFrame.
- B. Both commands will fail. No new variables, tables, or views will be created.
- C. Both commands will succeed. Executing show tables will show that countries at and sales at have been registered as views.
- D. Cmd 1 will succeed. Cmd 2 will search all accessible databases for a table or view named countries af: if this entity exists, Cmd 2 will succeed.
- E. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable containing a list of strings.
Answer: E
Explanation:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view.
Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter.
NEW QUESTION # 191
A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.
A senior data engineer updates the Delta Table's schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays.
Which limitation will the team face while diagnosing this problem?
- A. New fields cannot be added to a production Delta table.
- B. Updating the table schema requires a default value provided for each file added.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from - C. Spark cannot capture the topic partition fields from the kafka source.
- D. Updating the table schema will invalidate the Delta transaction log metadata.
- E. New fields not be computed for historic records.
Answer: E
Explanation:
When adding new fields to a Delta table's schema, these fields will not be retrospectively applied to historical records that were ingested before the schema change. Consequently, while the team can use the new metadata fields to investigate transient processing delays moving forward, they will be unable to apply this diagnostic approach to past data that lacks these fields.
NEW QUESTION # 192
Each configuration below is identical to the extent that each cluster has 400 GB total of RAM 160 total cores and only one Executor per VM.
Given an extremely long-running job for which completion must be guaranteed, which cluster configuration will be able to guarantee completion of the job in light of one or more VM failures?
- A. - Total VMs: 4
- 100 GB per Executor
- 40 Cores / Executor - B. - Total VMs: 8
- 50 GB per Executor
- 20 Cores / Executor - C. - Total VMs: 1
- 400 GB per Executor
- 160 Cores/Executor - D. - Total VMs: 16
- 25 GB per Executor
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
- 10 Cores / Executor - E. - Total VMs: 2
- 200 GB per Executor
- 80 Cores / Executor
Answer: D
Explanation:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
NEW QUESTION # 193
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x- scala2.12' runtime. Which command should the data engineer use?
- A. databricks clusters add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- B. databricks compute add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- C. databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name Data Engineer_cluster
- D. databricks clusters create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name DataEngineer_cluster
Answer: D
Explanation:
The correct Databricks CLI command to create a new cluster is databricks clusters create. You specify the runtime with --spark-version (here '14.3.x-scala2.12'), the number of workers with -- num-workers, the node type with --node-type-id, and the cluster name with --cluster-name. This command properly initializes the cluster with the desired configuration.
NEW QUESTION # 194
......
It is generally acknowledged that candidates who earn the Databricks-Certified-Data-Engineer-Professional certification ultimately get high-paying jobs in the tech market. Success in the Databricks Databricks-Certified-Data-Engineer-Professional exam not only validates your skills but also helps you get promotions. To pass the Databricks-Certified-Data-Engineer-Professional test in a short time, you must prepare with Databricks-Certified-Data-Engineer-Professional exam questions that are real and updated. Without studying with Databricks Databricks-Certified-Data-Engineer-Professional actual questions, candidates fail and waste their time and money.
Databricks-Certified-Data-Engineer-Professional Practice Exam: https://www.examprepaway.com/Databricks/braindumps.Databricks-Certified-Data-Engineer-Professional.ete.file.html
- How Can You Pass Databricks Databricks-Certified-Data-Engineer-Professional Certification Exam With Flying Colors? 🐬 Enter ➠ www.examcollectionpass.com 🠰 and search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ to download for free 🧎Latest Databricks-Certified-Data-Engineer-Professional Exam Pattern
- Databricks-Certified-Data-Engineer-Professional Trusted Exam Resource 🩺 New Databricks-Certified-Data-Engineer-Professional Exam Papers ⚛ Databricks-Certified-Data-Engineer-Professional Trusted Exam Resource 🎨 Easily obtain free download of ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ by searching on ☀ www.pdfvce.com ️☀️ ⛲Reliable Databricks-Certified-Data-Engineer-Professional Exam Braindumps
- Databricks-Certified-Data-Engineer-Professional Free Exam Questions 🐢 Exam Dumps Databricks-Certified-Data-Engineer-Professional Zip ☘ New Databricks-Certified-Data-Engineer-Professional Exam Fee 🦦 Easily obtain ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ for free download through ➠ www.troytecdumps.com 🠰 🏉Databricks-Certified-Data-Engineer-Professional Practice Tests
- Databricks-Certified-Data-Engineer-Professional Latest Exam Preparation 🦼 Databricks-Certified-Data-Engineer-Professional Prepaway Dumps 🍾 Databricks-Certified-Data-Engineer-Professional Free Exam Questions 🤱 Open website ➽ www.pdfvce.com 🢪 and search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ for free download 😇New Databricks-Certified-Data-Engineer-Professional Exam Papers
- How Can You Pass Databricks Databricks-Certified-Data-Engineer-Professional Certification Exam With Flying Colors? 🏞 Download 【 Databricks-Certified-Data-Engineer-Professional 】 for free by simply entering ☀ www.examcollectionpass.com ️☀️ website 🐩Reliable Databricks-Certified-Data-Engineer-Professional Exam Braindumps
- Quiz Marvelous Databricks - Databricks-Certified-Data-Engineer-Professional - Reliable Databricks Certified Data Engineer Professional Exam Exam Questions 💯 Open website ➽ www.pdfvce.com 🢪 and search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ for free download 🥢New Databricks-Certified-Data-Engineer-Professional Exam Papers
- Databricks-Certified-Data-Engineer-Professional Practice Tests 🤠 Exam Databricks-Certified-Data-Engineer-Professional Blueprint 🛅 Databricks-Certified-Data-Engineer-Professional Free Exam Questions 🦚 Enter “ www.practicevce.com ” and search for ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ to download for free 💂Databricks-Certified-Data-Engineer-Professional Test Collection Pdf
- Useful Reliable Databricks-Certified-Data-Engineer-Professional Exam Questions Help You to Get Acquainted with Real Databricks-Certified-Data-Engineer-Professional Exam Simulation 🏩 Search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ on ➤ www.pdfvce.com ⮘ immediately to obtain a free download 🤶Databricks-Certified-Data-Engineer-Professional Instant Access
- Exam Databricks-Certified-Data-Engineer-Professional Blueprint 🔳 Databricks-Certified-Data-Engineer-Professional Test Collection Pdf 👣 Databricks-Certified-Data-Engineer-Professional Free Exam Questions 🍏 Easily obtain free download of 《 Databricks-Certified-Data-Engineer-Professional 》 by searching on ✔ www.practicevce.com ️✔️ ❇Databricks-Certified-Data-Engineer-Professional Exam Question
- Databricks-Certified-Data-Engineer-Professional Exam Question 🥧 Latest Databricks-Certified-Data-Engineer-Professional Exam Pattern 🔇 Latest Databricks-Certified-Data-Engineer-Professional Dumps Ppt 🏖 The page for free download of ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ on 《 www.pdfvce.com 》 will open immediately 🥤Exam Dumps Databricks-Certified-Data-Engineer-Professional Zip
- How Can You Pass Databricks Databricks-Certified-Data-Engineer-Professional Certification Exam With Flying Colors? 🔨 Open website “ www.verifieddumps.com ” and search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 for free download 🤺Databricks-Certified-Data-Engineer-Professional Trusted Exam Resource
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.dibiz.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, annualeventpost.com, p.me-page.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes