Snowflake SPS-C01權威認證 & SPS-C01題庫最新資訊

P.S. Fast2test在Google Drive上分享了免費的2026 Snowflake SPS-C01考試題庫:https://drive.google.com/open?id=1loKmimAqoirksaq85J8Rmecf_f54AxMp
在短短幾年中,Snowflake的SPS-C01考試認證在日常生活中給人們造成了影響,但未來的關鍵問題是如何更有效的第一次通過Snowflake的SPS-C01考試認證?回答這個問題就是利用Fast2test Snowflake的SPS-C01考試培訓資料,有了它便實現了你的第一次通過考試認證,你還在等什麼,去獲得Fast2test Snowflake的SPS-C01考試培訓資料,有了它將得到更多你想要的東西。
Snowflake SPS-C01 Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Testing, Debugging, and Deployment | - Production readiness
- 1. Debugging Snowpark applications
- 2. Deployment strategies
|
| Topic 2: Performance Optimization and Best Practices | - Efficient Snowpark execution
- 1. Resource utilization tuning
- 2. Pushdown optimization concepts
|
| Topic 3: DataFrame Operations and Data Processing | - Data transformation workflows
- 1. Filtering, selecting, and aggregations
- 2. Joins and window functions
|
| Topic 4: Snowpark Fundamentals | - Snowpark architecture and concepts
- 1. Snowpark APIs and supported languages
- 2. Snowflake execution model overview
|
| Topic 5: Data Engineering with Snowpark | - Pipeline development
- 1. Batch processing workflows
- 2. Integration with Snowflake data pipelines
|
| Topic 6: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
- 1. Python UDFs
- 2. Stored procedures in Snowpark
|
>> Snowflake SPS-C01權威認證 <<
SPS-C01題庫最新資訊 & SPS-C01認證指南
面對激烈競爭,每個大學生都在為使自己在人才市場上脫穎而出而努力,多一張國際通行證無疑是為他們在就業及其他競爭中在同學中脫穎而出的法寶。所以,通過 Snowflake 的 SPS-C01 考試認證是我人生中的一大挑戰,需要拼命的努力學習,不過不要緊,你可以購買Fast2test Snowflake 的 SPS-C01 考試認證培訓資料,幫你輕松通過考試。
最新的 Snowflake Certification SPS-C01 免費考試真題 (Q91-Q96):
問題 #91
You have a Snowpark application that processes sensor data from a large number of devices. You've implemented a scalar UDF in Python to calculate a complex statistical metric for each sensor reading. Initial tests show poor performance. Which of the following strategies would be MOST effective in improving the performance of this application, considering the nature of the computation and the data volume?
- A. Replace the Python scalar UDF with a Java scalar UDF, as Java typically offers better performance than Python in Snowflake.
- B. Increase the warehouse size significantly to provide more resources for the scalar UDF execution.
- C. Replace the Python scalar UDF with a Python vectorized UDF, ensuring the UDF processes data in batches instead of row-by-row.
- D. Implement caching for the UDF results, assuming the statistical metric calculations are frequently repeated for the same sensor readings.
- E. Rewrite the UDF logic directly in SQL, leveraging Snowflake's built-in functions for statistical calculations.
答案:C
解題說明:
Vectorized UDFs process data in batches (vectors), significantly reducing the overhead associated with individual row processing, which is the primary bottleneck of scalar UDFs. While increasing warehouse size (C) might provide some improvement, it doesn't address the fundamental inefficiency of scalar processing. Java might be faster (A), but the biggest gain comes from vectorization. Caching (D) is useful for repeated calculations, but doesn't address the inherent UDF overhead if computations are unique. SQL (E) is good, but might not be possible due to the complexity.
問題 #92
You've created a Snowpark Python stored procedure designed to perform sentiment analysis on customer reviews stored in a Snowflake table. This procedure utilizes a third-party Python library, 'transformers', for its sentiment analysis model. You need to operationalize this stored procedure for scheduled execution. Which of the following options represents the MOST efficient and reliable approach for deploying and managing the 'transformers' dependency within the Snowflake environment for your stored procedure, minimizing deployment complexity and potential runtime errors?
- A. Create a Snowflake Anaconda channel, upload the 'transformers' library to this channel, and specify the channel in the stored procedure definition using the packageS parameter.
- B. Include the 'transformers' library as a part of the task definition and make it available for the stored procedure that the task is invoking.
- C. Include the 'transformers' library directly within the stored procedure's Python code as a string literal and execute it using or 'eval()'.
- D. Upload the 'transformers' library as a zip file to a Snowflake stage and reference it in the 'imports' parameter when creating the stored procedure.
- E. Install the 'transformers' library on the Snowflake compute warehouse nodes directly using a startup script.
答案:A
解題說明:
Using Snowflake Anaconda channels (option C) is the recommended and most efficient way to manage Python dependencies for Snowpark stored procedures. It provides version control, dependency management, and ensures consistency across executions. Option A is highly discouraged due to security risks and maintainability issues. Option B can work, but it lacks proper dependency management and versioning. Option D is not possible, as you cannot directly modify the Snowflake compute warehouse nodes. Option E is incorrect. Task definititions does not have any mechanism to include the library
問題 #93
Consider the following Python code snippet using Snowpark:
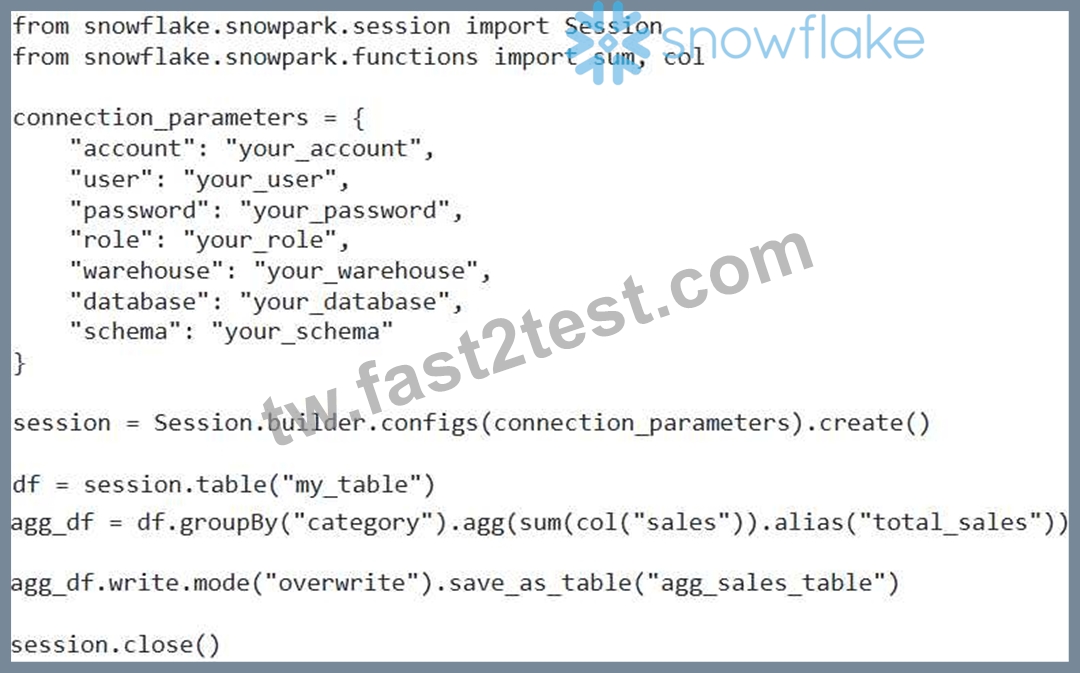
Which of the following statements are true regarding this Snowpark code?
- A. The code uses best practices by explicitly closing the Snowflake session, preventing resource leaks.
- B. The code calculates the sum of the 'sales' column, grouped by 'category' , and saves the result to a new table named , overwriting it if it exists.
- C. The code will fail because password authentication is deprecated and replaced by Key Pair authentication.
- D. The code establishes a connection to Snowflake using the provided credentials.
- E. The code reads data from a table named 'my_table' in Snowflake.
答案:A,B,D,E
解題說明:
The code correctly connects to Snowflake, reads data from 'my_table', performs aggregation, and saves the result to 'agg_sales_table' with overwrite mode, and closes the session. While password authentication is discouraged, it is still supported. The other options accurately describe the code's functionality. Closing the session is a best practice to release resources.
問題 #94
You are working with a Snowpark DataFrame containing product review data'. The DataFrame has a 'review_text' column containing unstructured text reviews. Your task is to perform sentiment analysis on these reviews using Snowpark for Python. However, you are restricted to using only Snowpark built-in functions and UDFs; you cannot use external libraries like NLTK or TextBlob directly within your Snowpark code. Given this contraint, what is a valid approach to enrich your dataframe?
- A. Develop a sentiment analysis microservice deployed outside Snowflake, then use Snowpark's 'call_udf function to invoke this service, passing the 'review_text' as input and receiving the sentiment score as output.
- B. Use Snowpark's 'transform' function with a custom Python transformer that leverages an internal vocabulary of positive and negative words to assign a sentiment score to each review based on word frequency. Then store the result in the column.
- C. Build a Snowpark Python UDF that uses regular expressions to identify keywords and phrases indicative of positive, negative, or neutral sentiment. Assign a score based on the presence and frequency of these keywords. You can then apply 'when' statements to get .
- D. Leverage Snowflake's external function capabilities to call a pre-trained sentiment analysis model hosted on a cloud ML platform (e.g., AWS SageMaker, Azure Machine Learning), passing the 'review_text' as input and receiving the sentiment score as output.
- E. Create a Java UDF within Snowflake that utilizes a Java-based sentiment analysis library (e.g., Stanford CoreNLP) to process the 'review_text' and return the sentiment score. Then, call this Java UDF from your Snowpark Python code.
答案:A,C,D,E
解題說明:
Options A, B, D and E are valid approaches given the constraints, since the task says enrich your dataframe, so we need some final column containing a score. Option A: The microservice approach, using 'call_udf and external function is a robust and scalable solution. It enables to leverage complex sentiment analysis models without directly integrating them into Snowflake. Option B: The Java UDF allows leveraging existing Java-based NLP libraries, extending the capabilities of Snowpark for sentiment analysis while adhering to the constraint of not using external Python libraries directly. Option D: Snowflake's External Functions are designed for calling external services. Passing 'review_text as an argument to pre-trained sentiment analysis model, and receive a result. Option E: This solution utilizes regular expression and UDFs. To search for sentiment indicative keywords and phrases and assigning the score using 'when' statements. Option C: This approach is the least efficient because it requires maintaining an internal vocabulary, which can be less accurate and harder to update compared to using pre-trained models or external services and it also does not generate a final new column to enrich the dataframe.
問題 #95
You have a Snowpark Python application that performs several data transformations on a DataFrame representing customer transactions. The application is experiencing performance issues, and you suspect that some transformations are unnecessarily expensive. Which of the following techniques can MOST effectively optimize the performance of your Snowpark application, specifically focusing on minimizing data movement and leveraging Snowflake's query optimization capabilities?
- A. Use User-Defined Functions (UDFs) written in Python for all transformations, regardless of their complexity.
- B. Always use the largest available Snowflake warehouse size to ensure sufficient compute resources.
- C. Take the dataframe to Pandas dataframe as soon as possible in between transformations, since Pandas dataframes will be faster.
- D. Explicitly call .cache()' on the DataFrame after each transformation to materialize intermediate results in memory.
- E. Leverage Snowpark's built-in DataFrame transformations (e.g., .groupBy()') to allow Snowflake to optimize the query execution plan. Avoid pulling large amounts of data into the client application for simple operations. Only call 'collect()' as the last and final option, as this is the most costly activity of all.
答案:E
解題說明:
Snowpark is designed to push down computations to Snowflake, allowing Snowflake's query optimizer to handle the execution. Using Snowpark's built-in DataFrame transformations allows Snowflake to understand the intent and optimize the query accordingly. Materializing intermediate results using .cache()' (A) can lead to unnecessary data movement. Python UDFs (B) can be useful for complex logic but should be avoided for simple transformations as they bypass Snowflake's optimization capabilities and are generally slower than native SQL functions. Warehouse size (E) is a factor, but optimizing the query logic is more crucial. Using Pandas dataframe is also costly and performance heavy.
問題 #96
......
人生充滿選擇,選擇不一定給你帶來絕對的幸福,但選擇給了你絕對的機會,而一旦錯過選擇,只能凝望。 Fast2test Snowflake的SPS-C01考試培訓資料是每個IT人士通過IT認證必須的培訓資料,有了這份考試資料就等於手握利刃,所有的考試難題將迎刃而解。 Fast2test Snowflake的SPS-C01考試培訓資料是針對性強,覆蓋面廣,更新快,最完整的培訓資料,有了它,所有的IT認證都不要害怕,你都會順利通過的。
SPS-C01題庫最新資訊: https://tw.fast2test.com/SPS-C01-premium-file.html
- SPS-C01題庫分享 🕥 SPS-C01題庫最新資訊 ↘ SPS-C01考試大綱 🌺 在“ tw.fast2test.com ”網站上免費搜索➡ SPS-C01 ️⬅️題庫SPS-C01熱門題庫
- 最新版的SPS-C01權威認證,Snowflake Snowflake Certification認證SPS-C01考試題庫提供免費下載 📫 在➽ www.newdumpspdf.com 🢪網站上免費搜索⇛ SPS-C01 ⇚題庫最新SPS-C01題庫資源
- SPS-C01 PDF ⚪ SPS-C01熱門考古題 🧬 SPS-C01熱門考古題 🚀 打開⏩ www.vcesoft.com ⏪搜尋▶ SPS-C01 ◀以免費下載考試資料SPS-C01考試指南
- 可靠的SPS-C01權威認證 |高通過率的考試材料|值得信賴的SPS-C01:Snowflake Certified SnowPro Specialty - Snowpark 🐵 ✔ www.newdumpspdf.com ️✔️上的免費下載{ SPS-C01 }頁面立即打開新版SPS-C01題庫上線
- Snowflake SPS-C01權威認證:Snowflake Certified SnowPro Specialty - Snowpark可靠的認證資源 🛒 在▛ www.vcesoft.com ▟上搜索【 SPS-C01 】並獲取免費下載SPS-C01考試指南
- SPS-C01考古题推薦 📝 SPS-C01考試指南 🛹 SPS-C01 PDF 🤤 免費下載➤ SPS-C01 ⮘只需進入《 www.newdumpspdf.com 》網站SPS-C01權威認證
- SPS-C01考古题推薦 ⚗ SPS-C01熱門考古題 ✳ 新版SPS-C01題庫上線 👊 ▶ www.pdfexamdumps.com ◀上的➥ SPS-C01 🡄免費下載只需搜尋最新SPS-C01考題
- SPS-C01考題套裝 👭 SPS-C01考試重點 🙋 SPS-C01考試重點 💺 立即打開【 www.newdumpspdf.com 】並搜索➤ SPS-C01 ⮘以獲取免費下載SPS-C01熱門題庫
- Snowflake SPS-C01權威認證:Snowflake Certified SnowPro Specialty - Snowpark可靠的認證資源 💋 ⮆ www.testpdf.net ⮄提供免費《 SPS-C01 》問題收集SPS-C01權威認證
- SPS-C01 PDF 🐷 SPS-C01考題套裝 🔻 最新SPS-C01考題 🚬 打開網站【 www.newdumpspdf.com 】搜索☀ SPS-C01 ️☀️免費下載SPS-C01考試資料
- 準確的SPS-C01權威認證和資格考試中的領導者和值得信賴的Snowflake Snowflake Certified SnowPro Specialty - Snowpark 🥝 打開網站➤ www.newdumpspdf.com ⮘搜索▛ SPS-C01 ▟免費下載SPS-C01考試大綱
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.bandlab.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
從Google Drive中免費下載最新的Fast2test SPS-C01 PDF版考試題庫:https://drive.google.com/open?id=1loKmimAqoirksaq85J8Rmecf_f54AxMp