
BTW, DOWNLOAD part of Prep4sureExam Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1v0lrGLVQrxRV13q8y_OYAg8_zoXLlhyc
Using Prep4sureExam you can pass the Amazon Data-Engineer-Associate exam easily. The first time you try to participate in Amazon Data-Engineer-Associate exam, selecting Prep4sureExam's Amazon Data-Engineer-Associate training tools and downloading Amazon Data-Engineer-Associate practice questions and answers will increase your confidence of passing the exam and will effectively help you pass the exam. Other online websites also provide training tools about Amazon certification Data-Engineer-Associate exam, but the quality of our products is very good. Our practice questions and answers have high accuracy. Our training materials have wide coverage of the content of the examination and constantly update and compile. Prep4sureExam can provide you with a very high accuracy of exam preparation. Selecting Prep4sureExam can save you a lot of time, so that you can get the Amazon Data-Engineer-Associate Certification earlier to allow you to become a Amazon IT professionals.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion and Transformation | 34% | - Ingest and transform data using AWS services - Build and manage data pipelines |
| Topic 2: Data Store Management | 26% | - Optimize storage performance and cost - Select appropriate data storage solutions |
| Topic 3: Data Security and Governance | 18% | - Implement data security controls - Apply governance and compliance best practices |
| Topic 4: Data Operations and Support | 22% | - Troubleshoot data workflow issues - Monitor and maintain data pipelines |
>> New Data-Engineer-Associate Exam Question <<
If you buy the Data-Engineer-Associate study materials online, you may concern the safety of your money. If you do have the concern, you can just choose us. We use the international recognition third party for the payment. It will ensure the safety of your money. We are pass guaranteed if you buy Data-Engineer-Associate Exam Dumps of us, we also money back guarantee if you fail to pass the exam. If you find that your rights haven’t got enough guaranteed, you can ask for refund, and the third party will protect your interests.
NEW QUESTION # 24
A company stores data from an application in an Amazon DynamoDB table that operates in provisioned capacity mode. The workloads of the application have predictable throughput load on a regular schedule.
Every Monday, there is an immediate increase in activity early in the morning. The application has very low usage during weekends.
The company must ensure that the application performs consistently during peak usage times.
Which solution will meet these requirements in the MOST cost-effective way?
Answer: D
Explanation:
Amazon DynamoDB is a fully managed NoSQL database service that provides fast and predictable performance with seamless scalability. DynamoDB offers two capacity modes for throughput capacity:
provisioned and on-demand. In provisioned capacity mode, you specify the number of read and write capacity units per second that you expect your application to require. DynamoDB reserves the resources to meet your throughput needs with consistent performance. In on-demand capacity mode, you pay per request and DynamoDB scales the resources up and down automatically based on the actual workload. On-demand capacity mode is suitable for unpredictable workloads that can vary significantly over time1.
The solution that meets the requirements in the most cost-effective way is to use AWS Application Auto Scaling to schedule higher provisioned capacity for peak usage times and lower capacity during off-peak times. This solution has the following advantages:
* It allows you to optimize the cost and performance of your DynamoDB table by adjusting the provisioned capacity according to your predictable workload patterns. You can use scheduled scaling to specify the date and time for the scaling actions, and the new minimum and maximum capacity limits. For example, you can schedule higher capacity for every Monday morning and lower capacity for weekends2.
* It enables you to take advantage of the lower cost per unit of provisioned capacity mode compared to on-demand capacity mode. Provisioned capacity mode charges a flat hourly rate for the capacity you reserve, regardless of how much you use. On-demand capacity mode charges for each read and write request you consume, with no minimum capacity required. For predictable workloads, provisioned capacity mode can be more cost-effective than on-demand capacity mode1.
* It ensures that your application performs consistently during peak usage times by having enough capacity to handle the increased load. You can also use auto scaling to automatically adjust the provisioned capacity based on the actual utilization of your table, and set a target utilization percentage for your table or global secondary index. This way, you can avoid under-provisioning or over- provisioning your table2.
Option A is incorrect because it suggests increasing the provisioned capacity to the maximum capacity that is currently present during peak load times. This solution has the following disadvantages:
* It wastes money by paying for unused capacity during off-peak times. If you provision the same high capacity for all times, regardless of the actual workload, you are over-provisioning your table and paying for resources that you don't need1.
* It does not account for possible changes in the workload patterns over time. If your peak load times increase or decrease in the future, you may need to manually adjust the provisioned capacity to match the new demand. This adds operational overhead and complexity to your application2.
Option B is incorrect because it suggests dividing the table into two tables and provisioning each table with half of the provisioned capacity of the original table. This solution has the following disadvantages:
* It complicates the data model and the application logic by splitting the data into two separate tables.
You need to ensure that the queries are evenly distributed across both tables, and that the data is consistent and synchronized between them. This adds extra development and maintenance effort to your application3.
* It does not solve the problem of adjusting the provisioned capacity according to the workload patterns.
You still need to manually or automatically scale the capacity of each table based on the actual utilization and demand. This may result in under-provisioning or over-provisioning your tables2.
Option D is incorrect because it suggests changing the capacity mode from provisioned to on-demand. This solution has the following disadvantages:
* It may incur higher costs than provisioned capacity mode for predictable workloads. On-demand capacity mode charges for each read and write request you consume, with no minimum capacity required. For predictable workloads, provisioned capacity mode can be more cost-effective than on- demand capacity mode, as you can reserve the capacity you need at a lower rate1.
* It may not provide consistent performance during peak usage times, as on-demand capacity mode may take some time to scale up the resources to meet the sudden increase in demand. On-demand capacity mode uses adaptive capacity to handle bursts of traffic, but it may not be able to handle very large spikes or sustained high throughput. In such cases, you may experience throttling or increased latency.
:
1: Choosing the right DynamoDB capacity mode - Amazon DynamoDB
2: Managing throughput capacity automatically with DynamoDB auto scaling - Amazon DynamoDB
3: Best practices for designing and using partition keys effectively - Amazon DynamoDB
[4]: On-demand mode guidelines - Amazon DynamoDB
[5]: How to optimize Amazon DynamoDB costs - AWS Database Blog
[6]: DynamoDB adaptive capacity: How it works and how it helps - AWS Database Blog
[7]: Amazon DynamoDB pricing - Amazon Web Services (AWS)
NEW QUESTION # 25
A company loads transaction data for each day into Amazon Redshift tables at the end of each day. The company wants to have the ability to track which tables have been loaded and which tables still need to be loaded.
A data engineer wants to store the load statuses of Redshift tables in an Amazon DynamoDB table. The data engineer creates an AWS Lambda function to publish the details of the load statuses to DynamoDB.
How should the data engineer invoke the Lambda function to write load statuses to the DynamoDB table?
Answer: B
Explanation:
The Amazon Redshift Data API enables you to interact with your Amazon Redshift data warehouse in an easy and secure way. You can use the Data API to run SQL commands, such as loading data into tables, without requiring a persistent connection to the cluster. The Data API also integrates with Amazon EventBridge, which allows you to monitor the execution status of your SQL commands and trigger actions based on events. By using the Data API to publish an event to EventBridge, the data engineer can invoke the Lambda function that writes the load statuses to the DynamoDB table. This solution is scalable, reliable, and cost-effective. The other options are either not possible or not optimal. You cannot use a second Lambda function to invoke the first Lambda function based on CloudWatch or CloudTrail events, as these services do not capture the load status of Redshift tables. You can use the Data API to publish a message to an SQS queue, but this would require additional configuration and polling logic to invoke the Lambda function from the queue. This would also introduce additional latency and cost. Reference:
Using the Amazon Redshift Data API
Using Amazon EventBridge with Amazon Redshift
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 2: Data Store Management, Section 2.2: Amazon Redshift
NEW QUESTION # 26
A data engineer needs to build a data pipeline to process medical records from 50 hospitals. The pipeline must ingest 5 GB of data from each hospital and remove personally identifiable information (PII). The pipeline must then transform the data and save the data in a central store. The pipeline must automatically retry after transient failures without manual intervention.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: B
Explanation:
The correct answer is A because the pipeline requires scalable ingestion, PII removal, ETL transformation, centralized storage, and automatic retry handling. Amazon S3 is the correct landing and central storage layer for large hospital data files. AWS Glue ETL is appropriate for managed data transformation at this scale, and AWS Glue DataBrew is the best fit among the options for low-code data preparation and PII handling. Step Functions is the correct orchestration service because it supports retry policies for task states, parallel states, and map states without manual intervention. EC2 custom scripts and AWS Batch add more operational work. Lambda is not suitable for 5 GB per hospital with heavier transformation steps. Therefore, S3, Glue, DataBrew, and Step Functions is the least-operational-overhead design.
NEW QUESTION # 27
A data engineer must orchestrate a data pipeline that consists of one AWS Lambda function and one AWS Glue job. The solution must integrate with AWS services.
Which solution will meet these requirements with the LEAST management overhead?
Answer: B
Explanation:
AWS Step Functions is a service that allows you to coordinate multiple AWS services into serverless workflows. You can use Step Functions to create state machines that define the sequence and logic of the tasks in your workflow. Step Functions supports various types of tasks, such as Lambda functions, AWS Glue jobs, Amazon EMR clusters, Amazon ECS tasks, etc. You can use Step Functions to monitor and troubleshoot your workflows, as well as to handle errors and retries.
Using an AWS Step Functions workflow that includes a state machine to run the Lambda function and then the AWS Glue job will meet the requirements with the least management overhead, as it leverages the serverless and managed capabilities of Step Functions. You do not need to write any code to orchestrate the tasks in your workflow, as you can use the Step Functions console or the AWS Serverless Application Model (AWS SAM) to define and deploy your state machine. You also do not need to provision or manage any servers or clusters, as Step Functions scales automatically based on the demand.
The other options are not as efficient as using an AWS Step Functions workflow. Using an Apache Airflow workflow that is deployed on an Amazon EC2 instance or on Amazon Elastic Kubernetes Service (Amazon EKS) will require more management overhead, as you will need to provision, configure, and maintain the EC2 instance or the EKS cluster, as well as the Airflow components. You will also need to write and maintain the Airflow DAGs to orchestrate the tasks in your workflow. Using an AWS Glue workflow to run the Lambda function and then the AWS Glue job will not work, as AWS Glue workflows only support AWS Glue jobs and crawlers as tasks, not Lambda functions. Reference:
AWS Step Functions
AWS Glue
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 6: Data Integration and Transformation, Section 6.3: AWS Step Functions
NEW QUESTION # 28
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?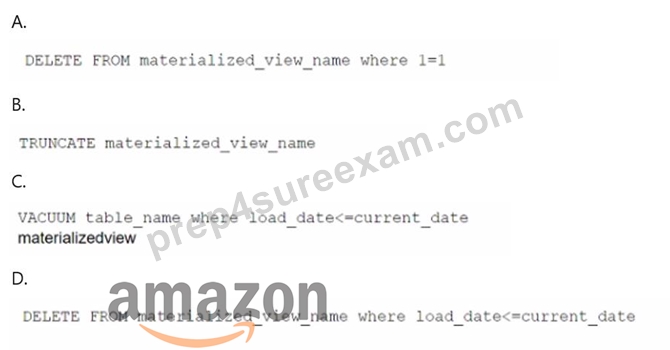
Answer: D
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
Option A: DELETE FROM materialized_view_name WHERE 1=1;
This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
Reference:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
NEW QUESTION # 29
......
Prep4sureExam offers authentic and actual Data-Engineer-Associate dumps that every candidate can rely on for good preparation. Our top priority is to give you the most reliable prep material that helps you pass the Data-Engineer-Associate Exam on the first attempt. In addition, we offer up to three months of free AWS Certified Data Engineer - Associate (DEA-C01) questions updates.
Data-Engineer-Associate Reliable Test Prep: https://www.prep4sureexam.com/Data-Engineer-Associate-dumps-torrent.html
P.S. Free & New Data-Engineer-Associate dumps are available on Google Drive shared by Prep4sureExam: https://drive.google.com/open?id=1v0lrGLVQrxRV13q8y_OYAg8_zoXLlhyc