2026 Latest Real4Prep Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1eNhk0Zb7BLsx2U0GHMHpu7JqLroe3Qkt
Getting Google certification is a good way for you to access to IT field. But you may find that real test questions are difficult and professional and you have no time to prepare the Professional-Machine-Learning-Engineer valid test. So it is time that our latest dumps torrent and training materials help you get high passing score in the process of Professional-Machine-Learning-Engineer practice test at your first attempt.
Google Professional Machine Learning Engineer Certification Exam is a test designed to validate advanced skills in machine learning. Professional-Machine-Learning-Engineer Exam is intended for professionals who want to demonstrate their ability to design and develop machine learning models on the Google Cloud platform. Google Professional Machine Learning Engineer certification exam is a great way for professionals to showcase their expertise in developing and deploying machine learning models.
>> Professional-Machine-Learning-Engineer Test Questions Answers <<
The pass rate is 98.75%, and we will ensure you pass the exam if you buy Professional-Machine-Learning-Engineer exam torrent from us. Since the high pass rate, we have received many good feedbacks from candidates. What’s more, we pass guarantee and money back guarantee if you fail to pass the exam after purchasing Professional-Machine-Learning-Engineer Exam Torrent from us. We have online and offline chat service stuff, and they possess the professional knowledge about the Professional-Machine-Learning-Engineer exam dumps, if you have any questions, just have a chat with them.
The Google Professional-Machine-Learning-Engineer exam consists of multiple-choice and multiple-select questions, as well as case studies and hands-on labs. Professional-Machine-Learning-Engineer exam duration is two hours, and the passing score is 70%. Professional-Machine-Learning-Engineer exam fee is $200, and it can be taken remotely or at a testing center.
Google Professional Machine Learning Engineer Exam is a certification exam offered by Google Cloud for professionals who demonstrate mastery in designing, building, and deploying scalable machine learning models. Professional-Machine-Learning-Engineer Exam is designed to assess the candidate's ability to use Google Cloud's machine learning technologies to develop and deploy production-grade ML models, as well as to optimize and maintain them to ensure their reliability, accuracy, and scalability.
NEW QUESTION # 263
You received a training-serving skew alert from a Vertex Al Model Monitoring job running in production.
You retrained the model with more recent training data, and deployed it back to the Vertex Al endpoint but you are still receiving the same alert. What should you do?
Answer: C
Explanation:
The best option for resolving the training-serving skew alert is to update the model monitoring job to use the more recent training data that was used to retrain the model. This option can help align the baseline distribution of the model monitoring job with the current distribution of the production data, and eliminate the false positive alerts. Model Monitoring is a service that can track and compare the results of multiple machine learning runs. Model Monitoring can monitor the model's prediction input data for feature skew and drift.
Training-serving skew occurs when the feature data distribution in production deviates from the feature data distribution used to train the model. If the original training data is available, you can enable skew detection to monitor your models for training-serving skew. Model Monitoring uses TensorFlow Data Validation (TFDV) to calculate the distributions and distance scores for each feature, and compares them with a baseline distribution. The baseline distribution is the statistical distribution of the feature's values in the training data. If the distance score for a feature exceeds an alerting threshold that you set, Model Monitoring sends you an email alert. However, if you retrain the model with more recent training data, and deploy it back to the Vertex AI endpoint, the baseline distribution of the model monitoring job may become outdated and inconsistent with the current distribution of the production data. This can cause the model monitoring job to generate false positive alerts, even if the model performance is not deteriorated. To avoid this problem, you need to update the model monitoring job to use the more recent training data that was used to retrain the model. This can help the model monitoring job to recalculate the baseline distribution and the distance scores, and compare them with the current distribution of the production data. This can also help the model monitoring job to detect any true positive alerts, such as a sudden change in the production data that causes the model performance to degrade1.
The other options are not as good as option B, for the following reasons:
* Option A: Updating the model monitoring job to use a lower sampling rate would not resolve the training-serving skew alert, and could reduce the accuracy and reliability of the model monitoring job.
The sampling rate is a parameter that determines the percentage of prediction requests that are logged and analyzed by the model monitoring job. Using a lower sampling rate can reduce the storage and computation costs of the model monitoring job, but also the quality and validity of the data. Using a lower sampling rate can introduce sampling bias and noise into the data, and make the model monitoring job miss some important features or patterns of the data. Moreover, using a lower sampling rate would not address the root cause of the training-serving skew alert, which is the mismatch between the baseline distribution and the current distribution of the production data2.
* Option C: Temporarily disabling the alert, and enabling the alert again after a sufficient amount of new production traffic has passed through the Vertex AI endpoint, would not resolve the training-serving skew alert, and could expose the model to potential risks and errors. Disabling the alert would stop the model monitoring job from sending email notifications when the distance score for a feature exceeds the alerting threshold, but it would not stop the model monitoring job from calculating and comparing the distributions and distance scores. Therefore, disabling the alert would not address the root cause of the training-serving skew alert, which is the mismatch between the baseline distribution and the current distribution of the production data. Moreover, disabling the alert would prevent the model monitoring job from detecting any true positive alerts, such as a sudden change in the production data that causes the model performance to degrade. This can expose the model to potential risks and errors, and affect the user satisfaction and trust1.
* Option D: Temporarily disabling the alert until the model can be retrained again on newer training data, and retraining the model again after a sufficient amount of new production traffic has passed through the Vertex AI endpoint, would not resolve the training-serving skew alert, and could cause unnecessary costs and efforts. Disabling the alert would stop the model monitoring job from sending email notifications when the distance score for a feature exceeds the alerting threshold, but it would not stop the model monitoring job from calculating and comparing the distributions and distance scores.
Therefore, disabling the alert would not address the root cause of the training-serving skew alert, which is the mismatch between the baseline distribution and the current distribution of the production data.
Moreover, disabling the alert would prevent the model monitoring job from detecting any true positive alerts, such as a sudden change in the production data that causes the model performance to degrade.
This can expose the model to potential risks and errors, and affect the user satisfaction and trust.
Retraining the model again on newer training data would create a new model version, but it would not
* update the model monitoring job to use the newer training data as the baseline distribution. Therefore, retraining the model again on newer training data would not resolve the training-serving skew alert, and could cause unnecessary costs and efforts1.
References:
* Preparing for Google Cloud Certification: Machine Learning Engineer, Course 3: Production ML Systems, Week 4: Evaluation
* Google Cloud Professional Machine Learning Engineer Exam Guide, Section 3: Scaling ML models in production, 3.3 Monitoring ML models in production
* Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6:
Production ML Systems, Section 6.3: Monitoring ML Models
* Using Model Monitoring
* Understanding the score threshold slider
* Sampling rate
NEW QUESTION # 264
Your team has been tasked with creating an ML solution in Google Cloud to classify support requests for one of your platforms. You analyzed the requirements and decided to use TensorFlow to build the classifier so that you have full control of the model's code, serving, and deployment. You will use Kubeflow pipelines for the ML platform. To save time, you want to build on existing resources and use managed services instead of building a completely new model.
How should you build the classifier?
Answer: A
Explanation:
It allows you to build a classifier quickly and easily without having to build a new model from scratch. Transfer learning is a technique that can be used to transfer the knowledge from a pre- trained model to a new model. In this case, you would use an established text classification model that has been trained on a large dataset of text documents. You would then fine-tune the model on your dataset of support requests.
NEW QUESTION # 265
You are working with a dataset that contains customer transactions. You need to build an ML model to predict customer purchase behavior You plan to develop the model in BigQuery ML, and export it to Cloud Storage for online prediction You notice that the input data contains a few categorical features, including product category and payment method You want to deploy the model as quickly as possible. What should you do?
Answer: C
Explanation:
The best option for building an ML model to predict customer purchase behavior in BigQuery ML is to use the transform clause with the ML.ONE_HOT_ENCODER function on the categorical features at model creation and select the categorical and non-categorical features. This option allows you to encode the categorical features as one-hot vectors, which are binary vectors that have only one non-zero element. One-hot encoding is a common technique for handling categorical features in ML models, as it can reduce the dimensionality and sparsity of the data, and avoid the ordinality problem that arises when using numerical labels for categorical values1. The transform clause is a feature of BigQuery ML that lets you apply SQL expressions to transform the input data at model creation time. The transform clause can perform feature engineering, such as one-hot encoding, on the fly, without requiring you to create and store a new table with the transformed data2. By using the transform clause with the ML.ONE_HOT_ENCODER function, you can create and train an ML model in BigQuery ML with a single SQL statement, and export it to Cloud Storage for online prediction.
The other options are not as good as option A, for the following reasons:
* Option B: Using the ML.ONE_HOT_ENCODER function on the categorical features, and selecting the encoded categorical features and non-categorical features as inputs to create your model, would require more steps and storage than using the transform clause. The ML.ONE_HOT_ENCODER function is a BigQuery ML function that returns a one-hot encoded vector for a given categorical value. However, using this function alone would not apply the one-hot encoding to the input data at model creation time.
You would need to create a new table with the encoded features, and use that table as the input to create your model. This would incur additional storage costs and reduce the performance of the queries.
* Option C: Using the create model statement and selecting the categorical and non-categorical features, would not handle the categorical features properly and could result in a poor model performance. The create model statement is a BigQuery ML statement that creates and trains an ML model from a SQL query. However, if the input data contains categorical features, you need to encode them as one-hot vectors or use the category_count option to specify the number of categories for each feature. Otherwise, BigQuery ML would treat the categorical features as numerical values, which can introduce bias and noise into the model3.
* Option D: Using the ML.ONE_HOT_ENCODER function on the categorical features, and selecting the encoded categorical features and non-categorical features as inputs to create your model, is the same as option B, and has the same drawbacks.
References:
* Preparing for Google Cloud Certification: Machine Learning Engineer, Course 2: Data Engineering for
* ML on Google Cloud, Week 2: Feature Engineering
* Google Cloud Professional Machine Learning Engineer Exam Guide, Section 1: Architecting low-code ML solutions, 1.1 Developing ML models by using BigQuery ML
* Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 3: Data Engineering for ML, Section 3.2: BigQuery for ML
* One-hot encoding
* Using the TRANSFORM clause for feature engineering
* Creating a model
* ML.ONE_HOT_ENCODER function
NEW QUESTION # 266
You are training an LSTM-based model on Al Platform to summarize text using the following job submission script: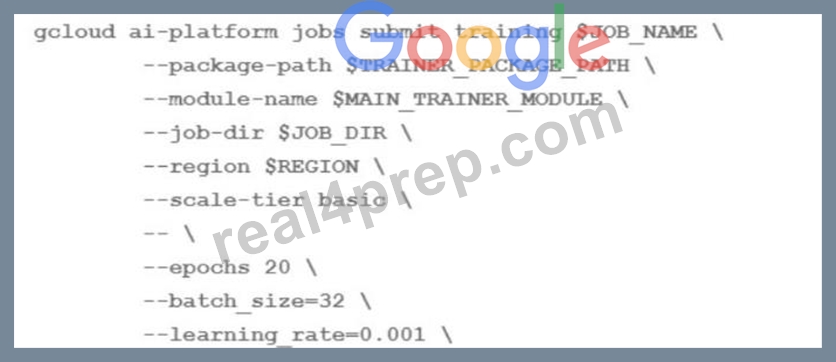
You want to ensure that training time is minimized without significantly compromising the accuracy of your model. What should you do?
Answer: B
NEW QUESTION # 267
You work for a delivery company. You need to design a system that stores and manages features such as parcels delivered and truck locations over time. The system must retrieve the features with low latency and feed those features into a model for online prediction. The data science team will retrieve historical data at a specific point in time for model training. You want to store the features with minimal effort. What should you do?
Answer: D
NEW QUESTION # 268
......
Professional-Machine-Learning-Engineer Reliable Test Materials: https://www.real4prep.com/Professional-Machine-Learning-Engineer-exam.html
BONUS!!! Download part of Real4Prep Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1eNhk0Zb7BLsx2U0GHMHpu7JqLroe3Qkt