Databricks Certified-Data-Engineer-Professional Reliable Mock Test | Actual Certified-Data-Engineer-Professional Test Pdf

They work together and put all their expertise, knowledge, and experience and make sure the top standard of Actual4test Certified-Data-Engineer-Professional exam questions all the time. So we can say that the Actual4test Certified-Data-Engineer-Professional exam practice test questions are the ideal study material for quick Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam preparation. The Actual4test Certified-Data-Engineer-Professional exam questions are real, valid, and updated as per the latest Databricks Certified-Data-Engineer-Professional exam syllabus and you can trust it and start Databricks Certified-Data-Engineer-Professional exam preparation right now.
| Section | Objectives |
|---|
| Topic 1: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 2: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 3. Create pipeline components using control flow operators such as if/else and foreach
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 6. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 7. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 8. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Develop User-Defined Functions using Pandas/Python UDF
|
| Topic 3: Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Topic 4: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
|
| Topic 5: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 6: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Topic 7: Cost & Performance Optimization | - Optimize cost and performance
- 1. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
| Topic 8: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Use row filters and column masks to protect sensitive table data
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Topic 9: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 10: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
|
>> Databricks Certified-Data-Engineer-Professional Reliable Mock Test <<
Quiz 2026 Certified-Data-Engineer-Professional: High Pass-Rate Databricks Certified Data Engineer Professional Reliable Mock Test
Certified-Data-Engineer-Professional questions and answers are written to the highest standards of technical accuracy by our professional experts. With our Certified-Data-Engineer-Professional free demo, you can check out the questions quality, validity of our Databricks practice torrent before you choose to buy it. You just need 20-30 hours to study with our Certified-Data-Engineer-Professional practice dumps, and you can attend the actual test and successfully pass. The Certified-Data-Engineer-Professional vce torrent will be the best and valuable study tool for your preparation.
Databricks Certified Data Engineer Professional Sample Questions (Q154-Q159):
NEW QUESTION # 154
Which statement regarding spark configuration on the Databricks platform is true?
- A. Spark configuration properties can only be set for an interactive cluster by creating a global init script.
- B. Spark configuration properties set for an interactive cluster with the Clusters UI will impact all notebooks attached to that cluster.
- C. Spark configuration set within an notebook will affect all SparkSession attached to the same interactive cluster
- D. The Databricks REST API can be used to modify the Spark configuration properties for an interactive cluster without interrupting jobs.
- E. When the same spar configuration property is set for an interactive to the same interactive cluster.
Answer: B
Explanation:
When Spark configuration properties are set for an interactive cluster using the Clusters UI in Databricks, those configurations are applied at the cluster level. This means that all notebooks attached to that cluster will inherit and be affected by these configurations. This approach ensures consistency across all executions within that cluster, as the Spark configuration properties dictate aspects such as memory allocation, number of executors, and other vital execution parameters. This centralized configuration management helps maintain standardized execution environments across different notebooks, aiding in debugging and performance optimization.
NEW QUESTION # 155
What statement is true regarding the retention of job run history?
- A. It is retained for 30 days, during which time you can deliver job run logs to DBFS or S3
- B. It is retained for 90 days or until the run-id is re-used through custom run configuration
- C. It is retained for 60 days, during which you can export notebook run results to HTML
- D. It is retained until you export or delete job run logs
- E. It is retained for 60 days, after which logs are archived
Answer: C
Explanation:
https://docs.databricks.com/en/workflows/jobs/monitor-job-runs.html
NEW QUESTION # 156
A data engineer is creating a daily reporting job. There are two reporting notebooks--one for weekdays and one for weekends. An "if/else condition" task is configured as
{{job.start_time.is_weekday}} == true to route the job to either the weekday or weekend notebook tasks. The same job would be used across multiple time zones. Which action should a senior data engineer take upon reviewing the job to merge or reject the pull request?
- A. Reject, as the {{job.start_time.is_weekday}} is for the UTC timezone.
- B. Reject, as the {{job.start_time.is_weekday}} is not a valid value reference.
- C. Merge, as the job configuration looks good.
- D. Reject, as they should use {{job.trigger_time.is_weekday}} instead.
Answer: A
Explanation:
Databricks parameter templates like {{job.start_time.is_weekday}} evaluate in UTC time by default, not in local workspace or regional time zones. Therefore, when jobs are configured to run across different time zones, relying on is_weekday using UTC may cause scheduling and task routing mismatches (for example, triggering the weekday notebook in one region while it's still the weekend locally).
Databricks recommends adjusting conditional logic or pipeline parameters explicitly to handle time zone conversions if business requirements depend on local times. Because the engineer's configuration does not account for this behavior, a senior data engineer should reject the pull request and suggest time-zone-aware logic before merging.
NEW QUESTION # 157
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.
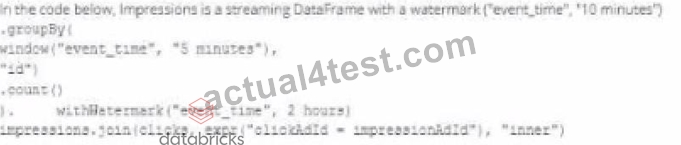
Which solution would improve the performance?
Answer: A
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 158
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
- A. Access the event_log_table, filter for events where event_type = 'flow_progress', and parse details.flow_progress.data_quality.expectations field to extract the required metrics.
- B. Use the Lakeflow Declarative Pipelines UI to navigate to the specific pipeline, select the dataset, and view the Data Quality tab to manually retrieve the expectation metrics.
- C. Access the event_log_table, filter for events where event_type = 'expectation_result', and extract the expectation metrics from the details field.
- D. Query the event_log_table for events with event_type = 'data_quality' and directly select the passed_records and failed_records fields.
Answer: C
Explanation:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = 'expectation_result' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
NEW QUESTION # 159
......
Our Certified-Data-Engineer-Professional training materials are famous at home and abroad, the main reason is because we have other companies that do not have core competitiveness, there are many complicated similar products on the market, if you want to stand out is the selling point of needs its own. Our Certified-Data-Engineer-Professional test question with other product of different thing is we have the most core expert team to update our Certified-Data-Engineer-Professional Study Materials, the Certified-Data-Engineer-Professional practice test materials give supervision and update the progress every day, it emphasized the key selling point of the product.
Actual Certified-Data-Engineer-Professional Test Pdf: https://www.actual4test.com/Certified-Data-Engineer-Professional_examcollection.html
- Certified-Data-Engineer-Professional Reliable Mock Test - 100% 100% Pass-Rate Questions Pool 💄 Easily obtain free download of ⮆ Certified-Data-Engineer-Professional ⮄ by searching on ✔ www.testkingpass.com ️✔️ 😌Certified-Data-Engineer-Professional Dump Collection
- Well-Prepared Certified-Data-Engineer-Professional Reliable Mock Test - Leading Offer in Qualification Exams - Updated Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 💾 Immediately open ➡ www.pdfvce.com ️⬅️ and search for ⇛ Certified-Data-Engineer-Professional ⇚ to obtain a free download 🐔Valid Certified-Data-Engineer-Professional Test Objectives
- Certified-Data-Engineer-Professional Valid Test Objectives 🔫 Certified-Data-Engineer-Professional Trustworthy Exam Content 👗 Certified-Data-Engineer-Professional Reliable Exam Dumps 🐝 Download { Certified-Data-Engineer-Professional } for free by simply entering ( www.verifieddumps.com ) website 😱Latest Certified-Data-Engineer-Professional Test Dumps
- Latest Certified-Data-Engineer-Professional Test Dumps 🍁 Exam Certified-Data-Engineer-Professional Simulator Online ✌ Exam Certified-Data-Engineer-Professional Simulator Online 🐸 Copy URL ▛ www.pdfvce.com ▟ open and search for ( Certified-Data-Engineer-Professional ) to download for free 👓Braindumps Certified-Data-Engineer-Professional Downloads
- Similar features as the desktop-based Databricks Certified-Data-Engineer-Professional practice test 💒 Easily obtain ➠ Certified-Data-Engineer-Professional 🠰 for free download through ➥ www.prepawaypdf.com 🡄 🛢Valid Certified-Data-Engineer-Professional Test Objectives
- Certified-Data-Engineer-Professional Dump Collection ⌛ Certified-Data-Engineer-Professional Study Reference 🐢 Latest Certified-Data-Engineer-Professional Test Dumps 🤙 Easily obtain free download of ➠ Certified-Data-Engineer-Professional 🠰 by searching on { www.pdfvce.com } 🏟Latest Certified-Data-Engineer-Professional Test Dumps
- Certified-Data-Engineer-Professional Reliable Exam Dumps ☑ Certified-Data-Engineer-Professional Reliable Exam Dumps 🔆 Certified-Data-Engineer-Professional Reliable Exam Test ⚡ Easily obtain “ Certified-Data-Engineer-Professional ” for free download through ➤ www.prepawaypdf.com ⮘ 🌤Valid Certified-Data-Engineer-Professional Test Objectives
- Certified-Data-Engineer-Professional Latest Test Cost 📆 Certified-Data-Engineer-Professional Reliable Exam Dumps 🦟 Certified-Data-Engineer-Professional Reliable Study Guide 👺 Simply search for ▛ Certified-Data-Engineer-Professional ▟ for free download on ⇛ www.pdfvce.com ⇚ 🆚Certified-Data-Engineer-Professional Interactive Questions
- Technical Certified-Data-Engineer-Professional Training 🥓 Certified-Data-Engineer-Professional Valid Exam Format 🤞 Certified-Data-Engineer-Professional Best Study Material 🔙 The page for free download of ☀ Certified-Data-Engineer-Professional ️☀️ on { www.pdfdumps.com } will open immediately 🔒Certified-Data-Engineer-Professional Reliable Exam Test
- Well-Prepared Certified-Data-Engineer-Professional Reliable Mock Test - Leading Offer in Qualification Exams - Updated Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 📝 ▷ www.pdfvce.com ◁ is best website to obtain { Certified-Data-Engineer-Professional } for free download 👴Certified-Data-Engineer-Professional Reliable Exam Braindumps
- Certified-Data-Engineer-Professional Reliable Exam Braindumps 🕸 Latest Certified-Data-Engineer-Professional Test Dumps 📆 Latest Certified-Data-Engineer-Professional Test Dumps 🔁 Search for { Certified-Data-Engineer-Professional } and easily obtain a free download on ▛ www.pdfdumps.com ▟ 🤗Certified-Data-Engineer-Professional Reliable Study Guide
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes



