Our professionals have gained an in-depth understanding of the fundamental elements that combine to produce world class AI-300 practice materials for all customers. So we can promise that our study materials will be the best study materials in the world. Our products have a high quality. If you decide to buy our AI-300 Exam Braindumps, we can make sure that you will have the opportunity to enjoy the AI-300 study guide from team of experts.
| Section | Objectives |
|---|---|
| Operationalizing machine learning solutions | - ML lifecycle management
|
| Design and implement generative AI solutions | - Large language model integration
|
| Implement secure and scalable AI systems | - Security and governance
|
| Plan and design AI solutions using Azure AI services | - Responsible AI design
|
You can easily assess yourself with the help of our AI-300 practice software, as it records all your previous results for future use. You can easily judge whether you can pass Operationalizing Machine Learning and Generative AI Solutions (AI-300) on the first attempt or not, and if you don't, you can use this software to strengthen your preparation.
NEW QUESTION # 116
You are training machine learning models in Azure Machine Learning. You use Hyperdrive to tune the hyperparameters.
In previous model training and tuning runs, many models showed similar performance.
You need to select an early termination policy that meets the following requirements:
- accounts for the performance of all previous runs when evaluating the current run
- avoids comparing the current run with only the best performing run to date Which two early termination policies should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,D
Explanation:
The Median Stopping Policy and the Truncation Selection Policy are the most appropriate early termination policies for this scenario. Both evaluate runs based on the performance of all previous runs instead of strictly benchmarking against the single best run.
Median Stopping Policy: This policy calculates the running averages of the primary metric across all historical and current training runs at each evaluation interval. It terminates any ongoing run if its performance is worse than the median of those averages. This directly accounts for all previous run performances rather than just the single best run.
Truncation Selection Policy: This policy evaluates all active runs at each interval and terminates a specified bottom percentage (X%) of the lowest-performing runs. Because it aggregates and compares the entire cohort of runs, it avoids making narrow comparisons against only the best- performing run.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-tune-hyperparameters
NEW QUESTION # 117
A team deploys a generative AI application that uses a model deployed in Microsoft Foundry.
The application must support latency monitoring under production load.
You need to enable performance observability.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.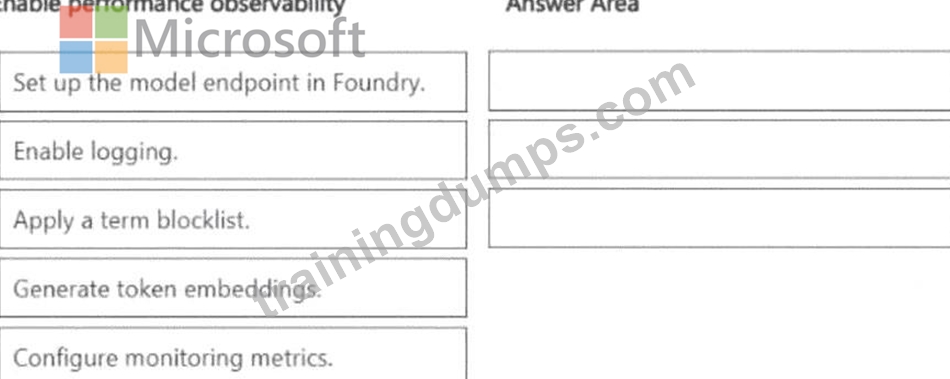
Answer:
Explanation: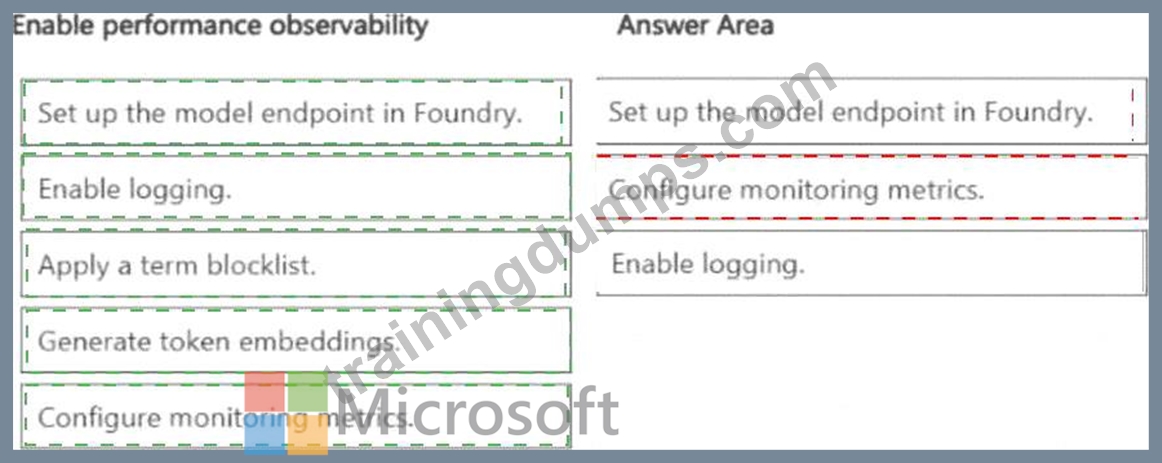
Explanation:
Microsoft ' s observability guidance for Azure AI Foundry applications describes a three-stage activation sequence. First, enable Tracing in the Microsoft Foundry project settings before deployment - Tracing instruments the application ' s LLM calls with OpenTelemetry-compatible spans that capture timing data for each step in the flow. Second, deploy the application to a production endpoint so that real traffic flows through the instrumented code path - without actual production traffic, there is no latency data to observe.
Third, configure Azure Monitor and Application Insights to receive, aggregate, and visualize the telemetry emitted by Tracing. Azure Monitor ' s metrics explorer and Application Insights ' performance views display p50, p95, and p99 latency distributions over time, enabling the team to identify latency regressions and set alert thresholds. This sequence - instrument, deploy, visualize - is the canonical Microsoft path to production AI performance observability.
Microsoft Learn Reference Topic: Monitor generative AI applications with Azure Monitor and Microsoft Foundry Tracing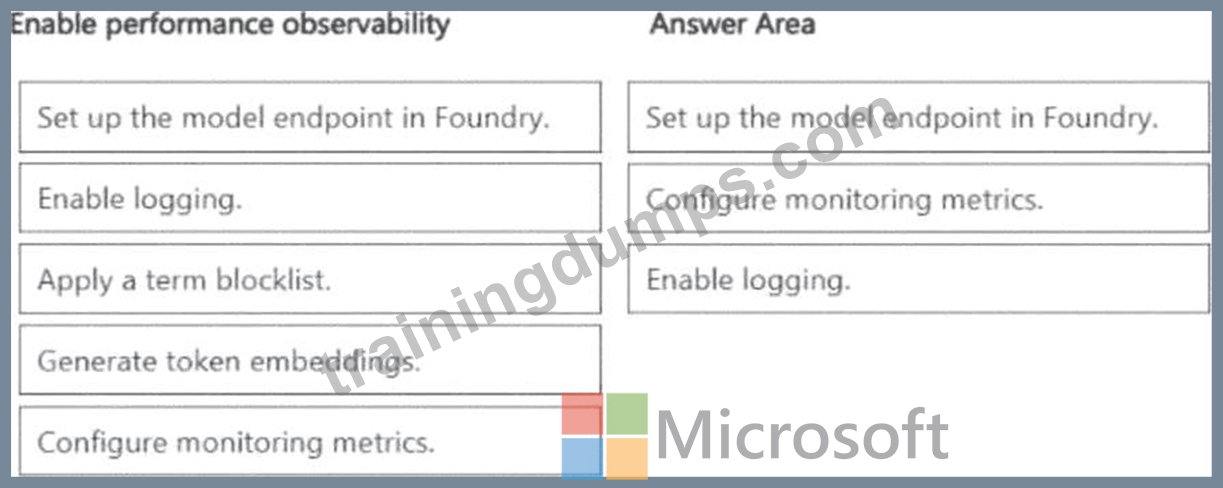
NEW QUESTION # 118
Fabrikam Inc. must improve its deployment process because traditional machine learning models are deployed manually and the organization has limited rollback capability .
You need to recommend a deployment approach that supports staged rollout and rollback while minimizing operational overhead.
Which deployment approach should you recommend?
Answer: A
Explanation:
Managed online endpoints with traffic splitting are the best fit because Azure Machine Learning supports multiple deployments behind a single online endpoint and allows production traffic to be distributed between them. This enables a blue-green or progressive rollout strategy : deploy the new model version alongside the current version, validate it independently, send a small percentage of production traffic to it, monitor behavior, and then gradually increase traffic. If problems occur, traffic can be redirected immediately to the previous deployment, providing a practical rollback mechanism.
This approach also aligns with Fabrikam's requirement to favor managed services and automation because the team has limited Azure DevOps experience. Managed online endpoints handle much of the serving, scaling, security, and monitoring infrastructure automatically and support both traffic splitting and mirrored traffic for safer validation.
Option B can also implement blue-green deployment, but AKS introduces substantially more infrastructure and operational management than Fabrikam requires. Option A would require custom deployment, routing, scaling, and rollback logic. Option D is intended for asynchronous batch inference rather than staged real-time production serving.
Study Guide Reference: Implement machine learning model lifecycle and operations - managed online endpoints, multiple deployments, traffic splitting, blue-green deployment, staged rollout, monitoring, and rollback.
NEW QUESTION # 119
When comparing prompt variants, the team plans to assess whether the generated responses are grammatically correct.
You need to evaluate the quality of the language from the generated responses.
Which evaluator should you use?
Answer: D
Explanation:
In Microsoft Foundry ' s built-in evaluation framework, each evaluator measures a specific dimension of language quality. Fluency evaluates the grammatical correctness, sentence structure, and overall linguistic smoothness of generated text. A high fluency score means the response reads naturally, with proper grammar, punctuation, and sentence construction - regardless of factual accuracy or relevance to the topic. Coherence (option A) measures whether ideas flow logically from one sentence to the next - it is about logical structure, not grammar. Textual Similarity (option B) measures how closely the generated text matches a reference text using metrics like ROUGE or BLEU - it is a comparison metric, not a standalone quality dimension. Groundedness (option C) measures whether claims are supported by the provided context - it is a factual fidelity metric. For grammatical correctness specifically, Fluency is the correct evaluator.
Microsoft Learn Reference Topic: Built-in AI evaluators in Microsoft Foundry - Fluency, Coherence, Groundedness, and Similarity
NEW QUESTION # 120
A team runs training and inference jobs in Azure Machine Learning.
The team experiences inconsistent runtime dependencies that cause variation in results.
You need to ensure that all jobs use the same execution dependencies.
Which asset should you define?
Answer: A
Explanation:
To guarantee consistent runtime dependencies in Azure Machine Learning, you must use Azure ML Environments configured with custom Docker images or pinned Conda dependencies.
An Environment asset encapsulates the exact Python packages, environment variables, and software settings for your training and inference workloads.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-set-up-training-targets
NEW QUESTION # 121
......
Are you ready to accept this challenge? Looking for the simple, quick, and easiest way to pass the career advancement Operationalizing Machine Learning and Generative AI Solutions (AI-300) certification exam? If your answer is yes then you do not need to worry about it. Just visit the TrainingDumps and explore the top features of Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam practice test questions offered by the trusted platform TrainingDumps. With TrainingDumps AI-300 Dumps questions you can easily prepare well and feel confident to pass the final Operationalizing Machine Learning and Generative AI Solutions exam easily.
Valid AI-300 Mock Test: https://www.trainingdumps.com/AI-300_exam-valid-dumps.html