DOWNLOAD the newest ActualVCE DP-800 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1BgNjV9ORipunxMCBlPylHRJl2GwB5HMp
We have free demos of our DP-800 exam questions for your information and the demos offer details of real exam contents. All contents of DP-800 practice quiz contain what need to be mastered. And not only the content is contained that you can free download from the website, also you can find that the displays of the DP-800 Study Materials can be tried as well for we have three versions, according we also have three kinds of free demos.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Training DP-800 Material <<
We offer you free update for one year for DP-800 study guide, namely, in the following year, you can obtain the latest version for free. And the latest version for DP-800 exam dumps will be sent to your email automatically. In addition, DP-800 exam materials are high quality, since we have experienced experts to compile and verify them, therefore the quality and accuracy can be guaranteed, so you can use them at ease. We have online and offline chat service, and if you have any questions about DP-800 Exam Dumps, you can consult us, and we will give you reply as quickly as possible.
NEW QUESTION # 22
You have an Azure SQL database that contains a table named Customer. Customer contains the following columns:
NationalIDNumber is unique per customer.
InvestigationNotes contains free-form text.
You have a stored procedure that performs point lookups by NationalIDNumber and returns InvestigationNotes in the query results without filtering on InvestigationNotes.
You need to encrypt both columns by using Always Encrypted and the highest security possible.
Which type of Always Encrypted encryption should you use for each column?
Answer: D
NEW QUESTION # 23
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders.
dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.Orders.
Solution: Identify the partition number for the oldest month, and then run the following Transact- SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
Does this meet the goal?
Answer: B
Explanation:
Correct:
* Identify the partition number for the oldest month, and then run the following Transact-SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
The best Transact-SQL statement to remove all rows for the oldest month while minimizing the impact on other queries is TRUNCATE TABLE with a WITH (PARTITIONS (...)) clause.
Why TRUNCATE TABLE ... WITH (PARTITIONS (...)) is Best
Efficiency: TRUNCATE TABLE is a Data Definition Language (DDL) operation that removes data by deallocating the data pages, which is a metadata operation and is very fast, regardless of the amount of data in the partition.
Minimal Logging: It uses less transaction log space compared to a DELETE statement, which logs each row deletion individually.
Low Impact on Concurrency: It performs a quick, partition-specific operation. A row-by-row DELETE would be a long-running transaction and could cause locking and blocking issues for other queries accessing the table.
Data Integrity: Because the table has a clustered index and is partitioned by the same column (aligned indexes), the TRUNCATE PARTITION operation is a fast, partition-level maintenance operation that targets only that specific data subset.
Incorrect:
* : Identify the partition scheme for the oldest month, and then run the following Transact-SQL statement.
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME (partition_scheme_name);
The DROP PARTITION SCHEME statement removes the partition scheme object from the database but does not remove the data itself or free up the space, and it requires all tables to be moved off the scheme first, which is a complex operation. This does not meet the goal of removing the data efficiently.
* Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
A standard DELETE statement, even with a WHERE clause that uses the partition column, can be a time-consuming, logged operation that causes locking and blocking on the main table, negatively impacting performance.
Reference:
https://stackoverflow.com/questions/63632963/truncate-partition-vs-drop-partition-performace- wise-which-one-is-efficient-an
NEW QUESTION # 24
You have a database named db1. The schema is stored in a Git repository as an SDK-style SQL database project The repository Contains the following GitHub Action workflow.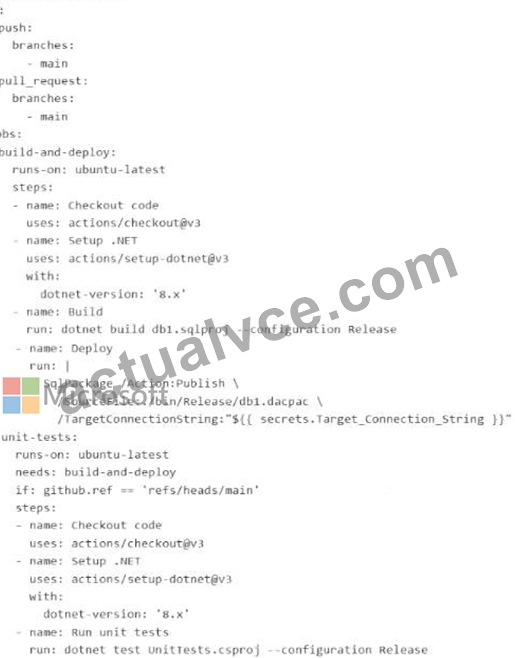
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.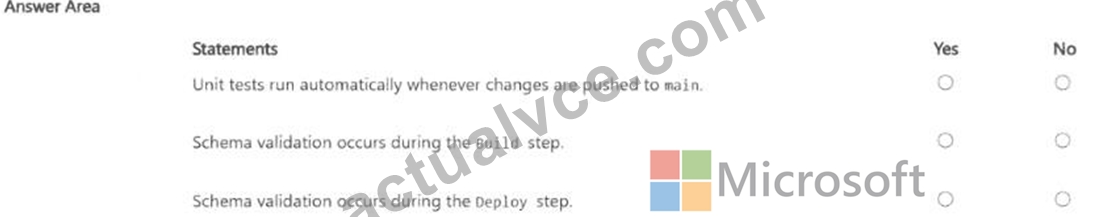
Answer:
Explanation: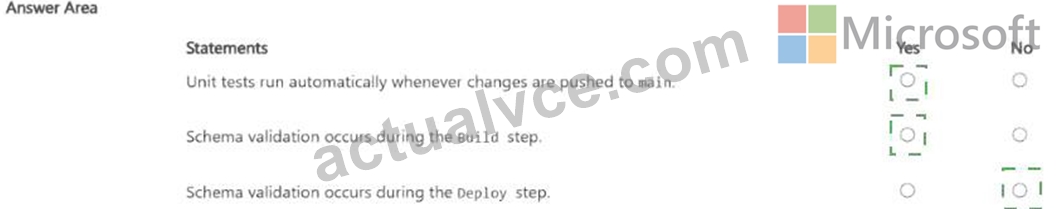
Explanation:
* Unit tests run automatically whenever changes are pushed to main. # Yes
* Schema validation occurs during the Build step. # Yes
* Schema validation occurs during the Deploy step. # No
The first statement is Yes . The workflow is configured to trigger on both push to main and pull_request targeting main. The unit-tests job has this condition:
if: github.ref == ' refs/heads/main '
On a push to main , GitHub sets github.ref to refs/heads/main, so the condition is true and the unit-tests job runs. GitHub's workflow syntax documentation confirms that push.branches: [main] triggers on pushes to main, and the github.ref value for branch pushes is the fully qualified ref such as refs/heads/main.
The second statement is Yes . The Build step runs:
dotnet build db1.sqlproj --configuration Release
For an SDK-style SQL database project, the build process produces a .dacpac and validates the database project model as part of compilation/build. Microsoft's SQL database project documentation describes SDK- style SQL projects as the project format used for SQL Database Projects, and Microsoft's command-line build documentation is specifically about building a .dacpac from that SQL project. That means schema-level project validation happens during build.
The third statement is No . The Deploy step uses:
SqlPackage /Action:Publish ...
Microsoft documents that SqlPackage Publish incrementally updates the target database schema to match the source .dacpac. That is a deployment operation, not the primary schema-validation stage of the SQL project source itself. In this workflow, the schema is validated when the SQL project is built into the .dacpac; the deploy step applies that built artifact to the target database.
NEW QUESTION # 25
You need to recommend a solution to lesolve the slow dashboard query issue. What should you recommend?
Answer: B
Explanation:
The best recommendation is B because the slow query filters on FleetId and returns LastUpdatedUtc , EngineStatus , and BatteryHealth . A nonclustered index with FleetId as the key column allows the optimizer to perform an index seek instead of a clustered index scan, and including the other selected columns makes the index covering , which reduces extra lookups and I/O. Microsoft's SQL Server indexing guidance states that a nonclustered index with included columns can significantly improve performance when all query columns are available in the index, because the optimizer can satisfy the query directly from the index.
The query is:
SELECT VehicleId, LastUpdatedUtc, EngineStatus, BatteryHealth
FROM dbo.VehicleHealthSummary
WHERE FleetId = @FleetId
ORDER BY LastUpdatedUtc DESC;
Among the given choices, FleetId is the most important search argument because it appears in the WHERE predicate. Microsoft's index design guidance recommends putting columns used for searching in the key and using nonkey included columns to cover the rest of the query efficiently.
Why the other options are weaker:
* A is not appropriate because changing the clustered index to LastUpdatedUtc would not target the main filter predicate on FleetId, and a table can have only one clustered index.
* C makes LastUpdatedUtc the key, which is poor for a query whose primary filter is FleetId.
* D is not the right answer here because the query requirement does not specify only recent rows, and filtered indexes are meant for a well-defined subset; this option also uses a time-based expression that is not aligned to the stated query pattern.
Strictly speaking, the most optimal design for both filtering and ordering would usually be a composite key like (FleetId, LastUpdatedUtc), but since that is not one of the available options, B is the correct exam answer.
NEW QUESTION # 26
You have an Azure SQL database named SalesDB that contains a table named dbo. Articles, dbo.Articles contains two million articles with embeddmgs. The articles are updated frequently throughout the day.
You query the embeddings by using VECTOR_SEARQi
Users report that semantic search results do NOT reflect the updates until the following day.
Vou need to ensure that the embeddings are updated whenever the articles change. The solution must minimize CPU usage on SalesDB Which embedding maintenance method should you implement?
Answer: B
Explanation:
The correct answer is B because the problem is not the vector search operator itself. The problem is that embeddings are becoming stale when article content changes . Microsoft documents that change data capture (CDC) tracks insert, update, and delete operations on source tables, which makes it the right mechanism to identify only the rows that changed.
This also best satisfies the requirement to minimize CPU usage on SalesDB . With CDC, the database only records the row changes, and the embedding regeneration work can be moved to an external process such as an Azure Functions app. That avoids running embedding generation inline inside the database for every update and avoids repeatedly recalculating embeddings for unchanged rows. In contrast, an hourly full-table regeneration would be extremely wasteful on a table with two million frequently updated articles, and a trigger that calls embedding generation per row would push expensive AI work into the transactional path of the database.
Option A is incorrect because changing from VECTOR_SEARCH to VECTOR_DISTANCE does not regenerate embeddings; it only changes the retrieval method. Microsoft states that VECTOR_SEARCH is the ANN search function, while VECTOR_DISTANCE performs exact distance calculation, so neither option addresses stale embedding data.
So the right design is:
* use CDC to detect only changed articles,
* process those changes outside the database,
* regenerate embeddings only for changed rows,
* write back the refreshed embeddings for current semantic search results.
NEW QUESTION # 27
......
If you are lack of skills in the preparation of getting the certification, our DP-800 study materials are the best choice for you. Many people have successfully realized economic freedom after getting the DP-800 certificate and changing a high salary job. So you need to act from now, come to join us and struggle together. Our DP-800 Study Materials will help you change into social elite and you will never feel dispointed.
DP-800 Reliable Dumps Ebook: https://www.actualvce.com/Microsoft/DP-800-valid-vce-dumps.html
BONUS!!! Download part of ActualVCE DP-800 dumps for free: https://drive.google.com/open?id=1BgNjV9ORipunxMCBlPylHRJl2GwB5HMp