2026 VCESoft最新的SPS-C01 PDF版考試題庫和SPS-C01考試問題和答案免費分享:https://drive.google.com/open?id=122ibdhEubsmTCilzGB2Y1DojRCKaag5V
我相信不論在哪個行業工作的人都希望自己有很好的職業前景。當然在競爭激烈的IT行業裏面也不例外。在IT行業中工作的專業人士也希望自己有個很好的提升機會和很大的提升空間。很多專業的IT人士都知道Snowflake SPS-C01 認證考試可以幫你滿足這些願望的。而VCESoft是一個能幫助你成功通過Snowflake SPS-C01 的網站。
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and DataFrame Operations | 35% | - Window functions - Complex data pipelines - Persisting transformed data - Using built-in functions - Filtering, Aggregating, and Joining DataFrames |
| Snowpark Concepts | 15% | - Snowpark architecture and core concepts - Stored procedures and conditional logic - Transformations vs. Actions - Snowpark DataFrames and query plans - Client-side vs. Server-side execution - Snowpark Sessions and connection management |
| Performance Optimization and Best Practices | 20% | - Vectorized UDFs - Minimizing data transfer - Caching strategies - Debugging and explain plans - Query pushdown and optimization - Warehouse sizing for Snowpark |
| Snowpark API for Python | 30% | - DataFrame creation and manipulation - Reading and writing data - Establishing connections and session management - User-Defined Functions (UDFs) and Stored Procedures - Working with Semi-structured data |
VCESoft有很好的的售後服務。如果你選擇購買VCESoft的產品,VCESoft將為你提供每天24小時的線上客戶服務和提供一年的免費更新服務,及時的通知顧客最新的考試資訊讓客戶有充分準備。我們可以讓你花費少量的時間和金錢就可以通過IT認證考試。選擇VCESoft的產品幫助你的第一次參加的Snowflake SPS-C01 認證考試是很划算的。
問題 #273
You have a Snowpark DataFrame 'sales df with columns 'product_id' (INTEGER), 'sale date' (DATE), and 'sale_amount' (DOUBLE). You need to filter the DataFrame to include only sales that occurred in the year 2023 and where the 'sale_amount' is greater than the average 'sale_amount' for that specific 'product id'. Which of the following Snowpark Python code snippets will correctly achieve this?





答案:B
解題說明:
Option C is the most efficient and correct. It calculates the average sale amount per product ID using a window function and then filters the DataFrame based on both the year and the comparison with the average. It avoids joins and 'collect()' which can be inefficient. Option A doesn't import Window or properly use avg over a window, causing an error. Option B requires a join, which is less efficient. Option D uses "mean' which is available but 'avg' is preferrable. Option E 'collects data to the client which is also generally avoided in Snowpark.
問題 #274
You are tasked with building a machine learning pipeline in Snowpark to predict customer churn. You plan to use the scikit-learn library for model training and want to deploy the trained model as a Snowpark UDF for real-time scoring. Consider the following code snippet:
答案:D
解題說明:
The primary issue is that the 'model' object, which is a trained scikit-learn model, cannot be directly serialized and passed as an argument to the UDF. Snowpark's UDF serialization mechanism doesn't automatically handle complex Python objects like scikit-learn models. You'll need to use a serialization method like 'pickle' to serialize the model into a byte stream, and then deserialize it within the UDF. The other options are less likely to cause the code to fail if serialization is handled, assuming the snowpark library is imported and available, and a return type is correctly defined.
問題 #275
You are working with a Snowpark DataFrame 'df that contains user profile data'. A column named 'profile' stores user information as JSON, including 'age' (which can be a number or a string), 'is active' (which can be a boolean or a string 'true'/'false'), and registration date' (stored as a string in 'YYYY-MM-DD' format). You need to perform the following data transformations: 1. Cast the 'age' to an integer, defaulting to -1 if casting fails. 2. Cast 'is active' to a boolean, treating 'true' (case-insensitive) as true and any other string as false. 3. Convert 'registration_date' to a date object. Select the code snippets (multiple answers can be correct) that correctly accomplish these tasks using Snowpark DataFrame transformations.





答案:B,E
解題說明:
Options A and D are both correct. Option A : Uses lit(-l for handling age casting failures. This is good because it can handle errors and provides null safe casting. try to cast to a number, and if it fails, return null, then coalesce use -1 instead. Option A : Correctly converts to a boolean using 'when' and 'lower' for case-insensitive matching. If it's the string 'true', returns 'true'. Otherwise, returns 'false'. Option A : Uses 'to_date' for 'registration_date' since the column stores date. Option D is not supported. It should be 'is_number' for the age field. Option D : Correctly converts to a boolean using 'when' and 'lower' for case-insensitive matching. If it's the string 'true , returns 'true. Otherwise, returns 'false. Option D : Uses 'to_date' for 'registration_date' since the column stores date. Option B 'try_cast' does not exist in Snowpark. Option C 'Trye' is never equal to 'True'. Option E: The 'registration_date' needs to be converted with 'to date' and not 'to_timestamp'.
問題 #276
You are using Snowpark for Python to process a large dataset of website clickstream data'. The dataset contains columns such as 'session_id', 'user_id', 'timestamp', 'page_url', and 'event_type' (e.g., 'click', 'pageview', 'purchase'). You want to identify fraudulent user sessions based on the following criteria: A user session is considered fraudulent if it contains more than 100 clicks within a I-minute window. A user session is considered fraudulent if it contains more than 5 purchase events within a 5-minute window. Which of the following code snippets demonstrates the most efficient way to identify fraudulent sessions using Snowpark for Python? Select two that apply.
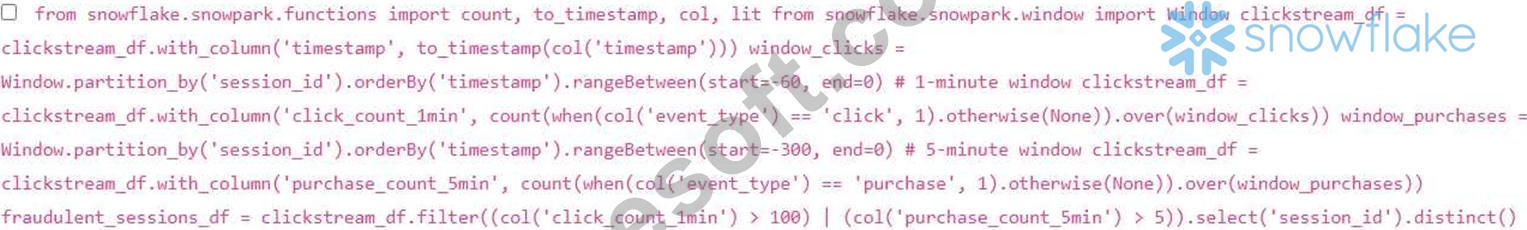
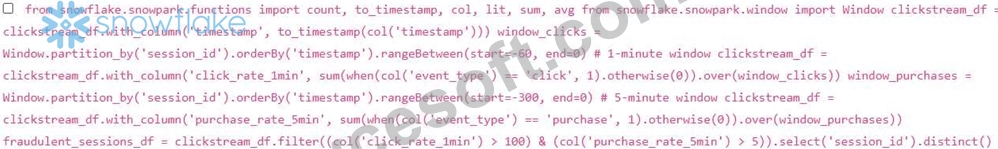
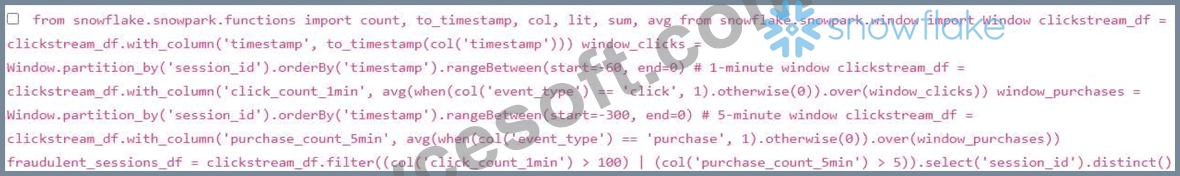
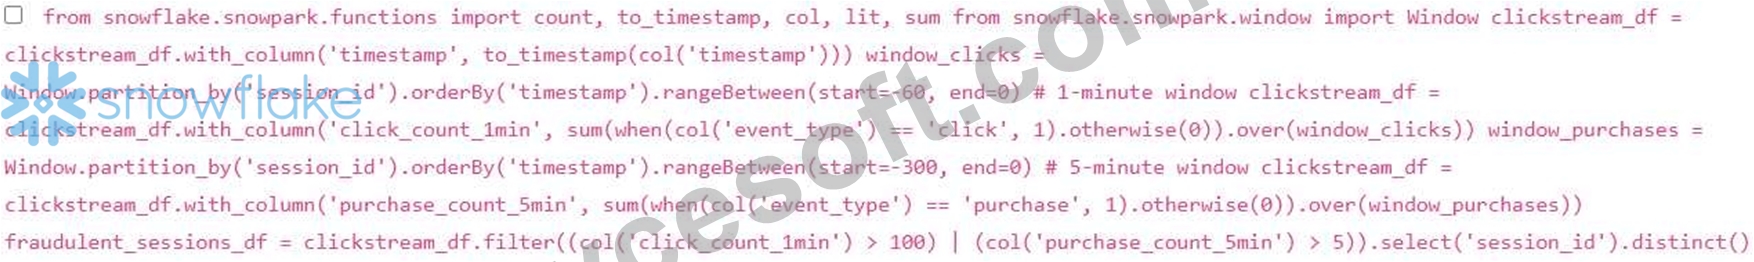

答案:A,D
解題說明:
Options A and E are the most efficient and correct because they use window functions to calculate the click and purchase counts within the specified time windows and then filter the results based on the fraud criteria. Option A uses 'sum' on a conditional aggregation to count clicks and purchases. Option E Uses 'Count' and 'Otherwise(None)'. Option B is inefficient because it uses a UDF, which is slower than using built-in window functions. Options C and D are incorrect because 'click_rate_1min','purchase_rate_5min' are calculated incorrectly by making comparison, furthermore Option D uses average instead of SUM.
問題 #277
You have configured your Snowpark application to use a '.env' file for storing connection parameters. The ' .env' file contains the following:
Which of the following code snippets demonstrates the most secure and recommended method for creating a Snowpark session using these environment variables and also ensuring the file exists?


答案:D
解題說明:
Option D is the most robust because it explicitly checks for the existence of the .env' file using 'pathlib' before attempting to load it, raising a FileNotFoundError' if it's missing, AND it utilizes 'os.environ.get()' which is safer than directly accessing 'os.environ[]" because it returns if the environment variable doesn't exist, preventing 'KeyError' exceptions, although in this case the .env' file not being present is detected. Options A, B, C and E don't proactively check for file existence prior to opening, and could thus potentially fail or crash the Snowpark session, or could inadvertently utilize invalid default values, which could lead to unexpected or incorrect behavior. Providing default values (Option E) might mask configuration errors.
問題 #278
......
在VCESoft網站上你可以免費下載我們提供的關於Snowflake SPS-C01認證考試的部分考題及答案測驗我們的可靠性。VCESoft提供的產品是可以100%把你推上成功,那麼IT行業的巔峰離你又近了一步。
SPS-C01認證指南: https://www.vcesoft.com/SPS-C01-pdf.html
從Google Drive中免費下載最新的VCESoft SPS-C01 PDF版考試題庫:https://drive.google.com/open?id=122ibdhEubsmTCilzGB2Y1DojRCKaag5V