
2026 Latest PracticeTorrent MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1020f0tsQyrfbFdjcszijkcrbSX_XfBv_
With all the information, we can say that your focus should be on real Amazon MLA-C01 questions of PracticeTorrent to clear the AWS Certified Machine Learning Engineer - Associate (MLA-C01) test. Three formats of the MLA-C01 exam dumps shall collectively contribute to your success in this regard. In addition, this MLA-C01 prep material comes with up to 365 days of free Amazon Dumps updates and a free demo.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Real Exam Qty: | 85 |
| Exam Price: | 150 USD |
| Exam Format: | Multiple response, Multiple choice |
| Related Certifications: | AWS Certified Developer - Associate AWS Certified Solutions Architect - Associate AWS Certified Data Engineer - Associate |
| Certificate Validity Period: | 3 years |
| Passing Score: | 1000-2000 scaled score (passing score approximately 720) |
| Exam Duration: | 170 minutes |
| Available Languages: | Simplified Chinese, Traditional Chinese, English, Korean, Japanese |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored (Pearson VUE) or in-person testing center |
| Pre Condition: | Recommended: 2+ years of ML engineering experience, familiarity with AWS ML services |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-machine-learning-engineer-associate/ |
>> MLA-C01 Examcollection Dumps Torrent <<
According to the statistic about candidates, we find that some of them take part in the MLA-C01 exam for the first time. Considering the inexperience of most candidates, we provide some free trail for our customers to have a basic knowledge of the MLA-C01 exam guide and get the hang of how to achieve the MLA-C01 exam certification in their first attempt. We also welcome the suggestions from our customers, as long as our clients propose rationally. We will adopt and consider it into the renovation of the MLA-C01 Exam Guide. Anyway, after your payment, you can enjoy the one-year free update service with our guarantee.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 213
A company is developing an ML model for a customer. The training data is stored in an Amazon S3 bucket in the customer ' s AWS account (Account A). The company runs Amazon SageMaker AI training jobs in a separate AWS account (Account B).
The company defines an S3 bucket policy and an IAM policy to allow reads to the S3 bucket.
Which additional steps will meet the cross-account access requirement?
Answer: A
Explanation:
For cross-account Amazon S3 access, AWS requires two components:
An S3 bucket policy in the owning account (Account A) that grants access to a principal in another account An IAM role policy in the consuming account (Account B) that allows the service to access the bucket Amazon SageMaker training jobs assume an IAM role in the account where the job runs-in this case, Account B. Therefore, the IAM policy must be attached to the SageMaker execution role in Account B.
The S3 bucket policy must reside in Account A because bucket policies are owned and enforced by the bucket owner. This policy explicitly allows the IAM role from Account B to read the training data.
Any other combination fails either because the policy is in the wrong account or because the role is not the one used by SageMaker.
AWS documentation clearly describes this pattern as the correct way to grant cross-account access for SageMaker training jobs.
Therefore, Option B is the correct and AWS-aligned solution.
NEW QUESTION # 214
A company needs to create a central catalog for all the company's ML models. The models are in AWS accounts where the company developed the models initially. The models are hosted in Amazon Elastic Container Registry (Amazon ECR) repositories.
Which solution will meet these requirements?
Answer: B
Explanation:
The Amazon SageMaker Model Registry is designed to manage and catalog ML models, including those hosted in Amazon ECR. By creating a model group for each model in the SageMaker Model Registry and setting up cross-account resource policies, the company can establish a central catalog in a new AWS account.
This allows all models from the initial accounts to be accessible in a unified, centralized manner for better organization, management, and governance. This solution leverages existing AWS services and ensures scalability and minimal operational overhead.
NEW QUESTION # 215
A company wants to host an ML model on Amazon SageMaker. An ML engineer is configuring a continuous integration and continuous delivery (Cl/CD) pipeline in AWS CodePipeline to deploy the model. The pipeline must run automatically when new training data for the model is uploaded to an Amazon S3 bucket.
Select and order the pipeline ' s correct steps from the following list. Each step should be selected one time or not at all. (Select and order three.)
* An S3 event notification invokes the pipeline when new data is uploaded.
* S3 Lifecycle rule invokes the pipeline when new data is uploaded.
* SageMaker retrains the model by using the data in the S3 bucket.
* The pipeline deploys the model to a SageMaker endpoint.
* The pipeline deploys the model to SageMaker Model Registry.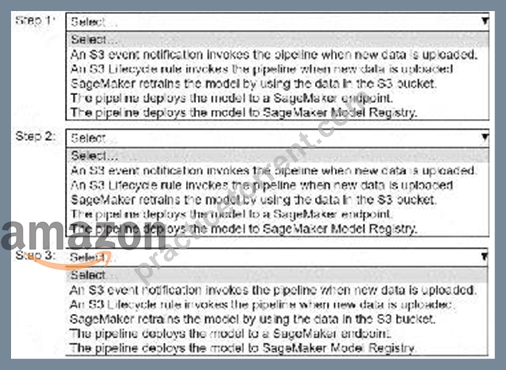
Answer:
Explanation: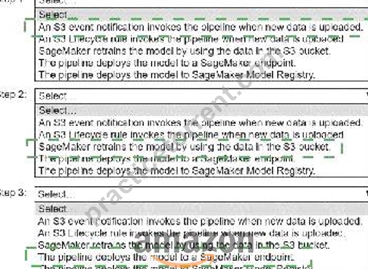
Explanation:
Step 1: An S3 event notification invokes the pipeline when new data is uploaded.
Step 2: SageMaker retrains the model by using the data in the S3 bucket.
Step 3: The pipeline deploys the model to a SageMaker endpoint.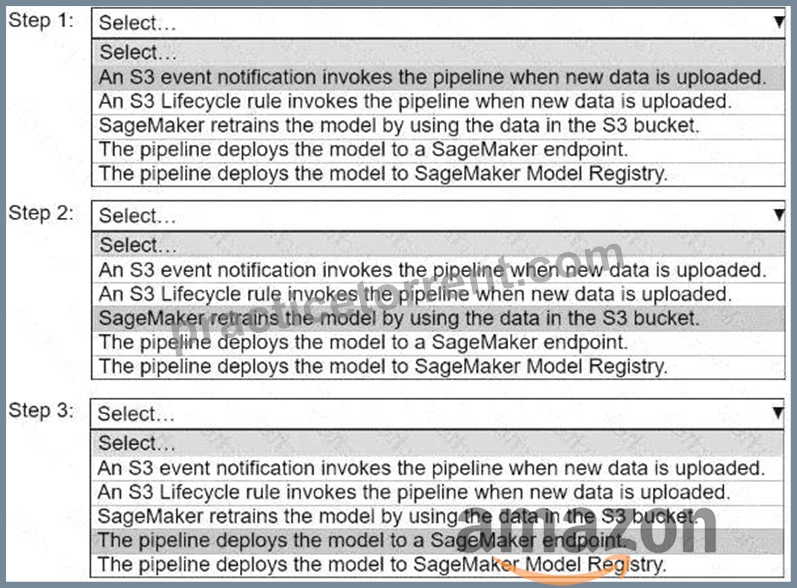
Step 1: An S3 Event Notification Invokes the Pipeline When New Data is Uploaded Why? The CI/CD pipeline should be triggered automatically whenever new training data is uploaded to Amazon S3. S3 event notifications can be configured to send events to AWS services like Lambda, which can then invoke AWS CodePipeline.
How? Configure the S3 bucket to send event notifications (e.g., s3:ObjectCreated:*) to AWS Lambda, which in turn triggers the CodePipeline.
Step 2: SageMaker Retrains the Model by Using the Data in the S3 Bucket Why? The uploaded data is used to retrain the ML model to incorporate new information and maintain performance. This step is critical to updating the model with fresh data.
How? Define a SageMaker training step in the CI/CD pipeline, which reads the training data from the S3 bucket and retrains the model.
Step 3: The Pipeline Deploys the Model to a SageMaker Endpoint
Why? Once retrained, the updated model must be deployed to a SageMaker endpoint to make it available for real-time inference.
How? Add a deployment step in the CI/CD pipeline, which automates the creation or update of the SageMaker endpoint with the retrained model.
Order Summary:
An S3 event notification invokes the pipeline when new data is uploaded.
SageMaker retrains the model by using the data in the S3 bucket.
The pipeline deploys the model to a SageMaker endpoint.
This configuration ensures an automated, efficient, and scalable CI/CD pipeline for continuous retraining and deployment of the ML model in Amazon SageMaker.
NEW QUESTION # 216
A construction company is using Amazon SageMaker AI to train specialized custom object detection models to identify road damage. The company uses images from multiple cameras. The images are stored as JPEG objects in an Amazon S3 bucket.
The images need to be pre-processed by using computationally intensive computer vision techniques before the images can be used in the training job. The company needs to optimize data loading and pre-processing in the training job. The solution cannot affect model performance or increase compute or storage resources.
Which solution will meet these requirements?
Answer: B
Explanation:
AWS documentation recommends using RecordIO format with lazy loading to optimize data input pipelines for image-based training workloads. RecordIO is a binary data format that enables sequential reads, reducing I
/O overhead and improving throughput during training.
By converting JPEG images into RecordIO format, the training job can read data more efficiently from Amazon S3. Lazy loading ensures that only the required data is loaded into memory when needed, which optimizes CPU utilization during computationally intensive preprocessing steps.
Option A (file mode) results in many small S3 GET requests, which can become a bottleneck for large image datasets. Option B changes training behavior and can negatively affect convergence and performance. Option C reduces image quality, which directly impacts model accuracy and violates the requirement.
AWS SageMaker documentation explicitly highlights RecordIO and lazy loading as best practices for high- performance image training pipelines, especially when preprocessing is CPU-intensive.
Therefore, Option D is the correct and AWS-aligned solution.
NEW QUESTION # 217
A retail company is analyzing customer purchase data to develop personalized product recommendations. The company wants to use Amazon SageMaker Clarify to assess fairness metrics across different customer groups to avoid potential bias in the recommendation system.
The recommendation system needs to identify if certain customer segments are underrepresented in the training data. The company needs to choose a pre-training bias metric in SageMaker Clarify.
Which metric meets these requirements?
Answer: D
Explanation:
The correct answer is C. Class imbalance ratio.
Amazon SageMaker Clarify provides both pre-training and post-training bias detection capabilities to help data scientists ensure fairness in ML models. Pre-training bias metrics specifically analyze the training dataset to detect underrepresentation of certain groups or features before a model is trained. The class imbalance ratio measures how evenly different classes or sensitive attributes are represented in the dataset. A high imbalance indicates that a particular segment of customers (e.g., certain age groups, genders, or ethnicities) may be underrepresented, which could lead to biased predictions when the model is deployed.
Feature attribution bias (Option B) and prediction distribution skew (Option A) are post-training metrics.
Feature attribution bias evaluates whether the model relies disproportionately on certain features for predictions, while prediction distribution skew examines whether the model's outputs are skewed for specific groups. Model performance gap (Option D) is also a post-training measure, focusing on differences in accuracy or other performance metrics between groups.
By using the class imbalance ratio during pre-training analysis, the company can identify and mitigate underrepresentation before training the model. Actions may include resampling the dataset, weighting underrepresented classes, or applying synthetic data augmentation to ensure that the model is trained on a balanced, fair dataset. This aligns with AWS best practices for ML solution monitoring, maintenance, and security, particularly for responsible AI and fairness assessment.
In summary, the class imbalance ratio allows proactive bias detection at the dataset level, preventing unfair recommendations and ensuring equitable treatment across all customer segments in the recommendation system.
NEW QUESTION # 218
......
MLA-C01 Certification Exam Dumps: https://www.practicetorrent.com/MLA-C01-practice-exam-torrent.html
DOWNLOAD the newest PracticeTorrent MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1020f0tsQyrfbFdjcszijkcrbSX_XfBv_