
What's more, part of that DumpStillValid MLA-C01 dumps now are free: https://drive.google.com/open?id=1zDdZ8EhuIUF6z1_8X8O3RVQci7vCMYMb
We keep raising the bar of our MLA-C01 real exam for we hold the tenet of clientele orientation. According to former exam candidates, more than 98 percent of customers culminate in success by their personal effort as well as our MLA-C01 study materials. So indiscriminate choice may lead you suffer from failure. As a representative of clientele orientation, we promise if you fail the practice exam after buying our MLA-C01 training quiz, we will give your compensatory money full back.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Amazon MLA-C01 Latest Exam Experience <<
Get the test MLA-C01 certification requires the user to have extremely high concentration will all test sites in mind, and this is definitely a very difficult. Our MLA-C01 learning questions can successfully solve this question for you for the content are exactly close to the changes of the MLA-C01 Real Exam. When you grasp the key points, nothing will be difficult for you anymore. Our professional experts are good at compiling the MLA-C01 training guide with the most important information. Believe in us, and your success is 100% guaranteed!
NEW QUESTION # 153
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
* Embedding
* Retrieval Augmented Generation (RAG)
* Temperature
* Token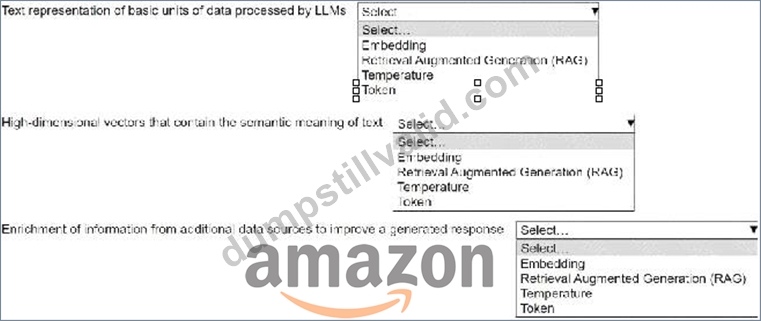
Answer:
Explanation: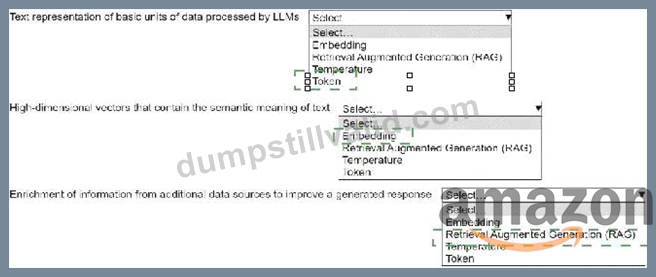
Explanation: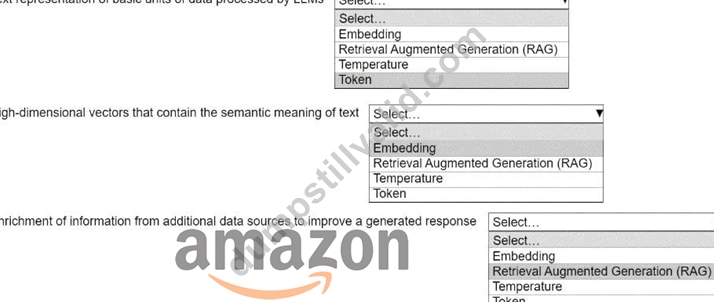
* Text representation of basic units of data processed by LLMs:Token
* High-dimensional vectors that contain the semantic meaning of text:Embedding
* Enrichment of information from additional data sources to improve a generated response:
Retrieval Augmented Generation (RAG)
Comprehensive Detailed Explanation
* Token:
* Description: A token represents the smallest unit of text (e.g., a word or part of a word) that an LLM processes. For example, "running" might be split into two tokens: "run" and "ing."
* Why?Tokens are the fundamental building blocks for LLM input and output processing, ensuring that the model can understand and generate text efficiently.
* Embedding:
* Description: High-dimensional vectors that encode the semantic meaning of text. These vectors are representations of words, sentences, or even paragraphs in a way that reflects their relationships and meaning.
* Why?Embeddings are essential for enabling similarity search, clustering, or any task requiring semantic understanding. They allow the model to "understand" text contextually.
* Retrieval Augmented Generation (RAG):
* Description: A technique where information is enriched or retrieved from external data sources (e.g., knowledge bases or document stores) to improve the accuracy and relevance of a model's generated responses.
* Why?RAG enhances the generative capabilities of LLMs by grounding their responses in factual and up-to-date information, reducing hallucinations in generated text.
By matching these terms to their respective descriptions, the ML engineer can effectively leverage these concepts to build robust and contextually aware generative AI applications on Amazon Bedrock.
NEW QUESTION # 154
A company is using ML to predict the presence of a specific weed in a farmer's field. The company is using the Amazon SageMaker linear learner built-in algorithm with a value of multiclass_dassifier for the predictorjype hyperparameter.
What should the company do to MINIMIZE false positives?
Answer: C
NEW QUESTION # 155
A company uses Amazon SageMaker for its ML process. A compliance audit discovers that an Amazon S3 bucket for training data uses server-side encryption with S3 managed keys (SSE- S3).
The company requires customer managed keys. An ML engineer changes the S3 bucket to use server-side encryption with AWS KMS keys (SSE-KMS). The ML engineer makes no other configuration changes.
After the change to the encryption settings, SageMaker training jobs start to fail with AccessDenied errors.
What should the ML engineer do to resolve this problem?
Answer: A
NEW QUESTION # 156
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company is experimenting with consecutive training jobs.
How can the company MINIMIZE infrastructure startup times for these jobs?
Answer: B
Explanation:
When running consecutive training jobs in Amazon SageMaker, infrastructure provisioning can introduce latency, as each job typically requires the allocation and setup of compute resources. To minimize this startup time and enhance efficiency, Amazon SageMaker offersManaged Warm Pools.
Key Features of Managed Warm Pools:
* Reduced Latency: Reusing existing infrastructure significantly reduces startup time for training jobs.
* Configurable Retention Period: Allows retention of resources after training jobs complete, defined by the KeepAlivePeriodInSeconds parameter.
* Automatic Matching: Subsequent jobs with matching configurations (e.g., instance type) can reuse retained infrastructure.
Implementation Steps:
* Request Warm Pool Quota Increase: Increase the default resource quota for warm pools through AWS Service Quotas.
* Configure Training Jobs:
* Set KeepAlivePeriodInSeconds for the first training job to retain resources.
* Ensure subsequent jobs match the retained pool's configuration to enable reuse.
* Monitor Warm Pool Usage: Track warm pool status through the SageMaker console or API to confirm resource reuse.
Considerations:
* Billing: Resources in warm pools are billable during the retention period.
* Matching Requirements: Jobs must have consistent configurations to use warm pools effectively.
Alternative Options:
* Managed Spot Training: Reduces costs by using spare capacity but doesn't address startup latency.
* SageMaker Training Compiler: Optimizes training time but not infrastructure setup.
* SageMaker Distributed Data Parallelism Library: Enhances training efficiency but doesn't reduce setup time.
By usingManaged Warm Pools, the company can significantly reduce startup latency for consecutive training jobs, ensuring faster experimentation cycles with minimal operational overhead.
References:
* AWS Documentation: Managed Warm Pools
* AWS Blog: Reduce ML Model Training Job Startup Time
NEW QUESTION # 157
A company runs an ML model on Amazon SageMaker AI. The company uses an automatic process that makes API calls to create training jobs for the model. The company has new compliance rules that prohibit the collection of aggregated metadata from training jobs.
Which solution will prevent SageMaker AI from collecting metadata from the training jobs?
Answer: B
Explanation:
Amazon SageMaker AI automatically collects aggregated metadata from training jobs to improve service reliability, performance, and operational insights. This metadata can include information such as algorithm usage, instance types, resource utilization, and job configuration details. However, AWS documentation clearly states that customers can opt out of SageMaker metadata collection to meet regulatory or compliance requirements.
SageMaker provides a supported mechanism to disable metadata tracking at the training job level. By explicitly opting out of metadata tracking when submitting training jobs-either through the AWS Management Console, AWS CLI, or SDK-the service will stop collecting aggregated metadata for those jobs. This option is specifically designed for customers with strict compliance, data residency, or regulatory constraints.
Option B is incorrect because running training jobs in a private subnet within a custom VPC controls network isolation, not service-level telemetry or metadata collection. Metadata collection occurs at the SageMaker service layer and is independent of VPC configuration.
Option C is also incorrect because encrypting training data with a customer-managed AWS KMS key protects data at rest and in transit but does not prevent SageMaker from collecting operational metadata about training jobs.
Option D is incorrect because AWS Nitro instances provide enhanced security and performance isolation at the infrastructure level but have no impact on SageMaker's metadata collection mechanisms.
Therefore, opting out of metadata tracking for training jobs is the only solution that directly addresses the compliance requirement and is explicitly supported by AWS documentation.
NEW QUESTION # 158
......
If you are occupied with your work or study and have little time to prepare for your exam, and you should choose us. Since MLA-C01 exam bootcamp is high-quality, and you just need to spend about 48 to 72 hours on studying, and you can pass the exam in your first attempt. We are pass guarantee and money back guarantee, and if you fail to pass the exam by using MLA-C01 Exam Dumps, we will give you full refund. In order to let you obtain the latest information for MLA-C01 exam braibdumps, we offer you free update for one year after purchasinhg, and the update version will be sent to your email automatically.
MLA-C01 Valid Test Format: https://www.dumpstillvalid.com/MLA-C01-prep4sure-review.html
What's more, part of that DumpStillValid MLA-C01 dumps now are free: https://drive.google.com/open?id=1zDdZ8EhuIUF6z1_8X8O3RVQci7vCMYMb