With online test engine, you will feel the atmosphere of Microsoft valid test. You can set limit-time when you do the DP-800 test questions so that you can control your time in DP-800 practice exam. Online version can point out your mistakes and remind you to practice it every day. What's more, you can practice DP-800 Pdf Torrent anywhere and anytime.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
Would you like to attend Microsoft DP-800 certification exam? Certainly a lot of people around you attend this exam. Microsoft DP-800 test is an important certification exam. If you obtain DP-800 certificate, you can get a lot of benefits. Then you pick other people's brain how to put through the test. There are several possibilities to get ready for DP-800 test, but using good tools is the most effective method. Well, what is the good tool? Of course, PracticeVCE Microsoft DP-800 exam dumps are the best tool.
NEW QUESTION # 23
Hotspot Question
You have an Azure SQL database that has Query Store enabled.
Query Performance Insight shows that one stored procedure has the longest runtime. The procedure runs the following parameterized query.
The dbo.Orders table has approximately 120 million rows. CustomerId is highly selective, and OrderDate is used for range filtering and sorting.
You have the following indexes:
- Clustered index: PK_Orders on (OrderId)
- Nonclustered index: IX_Orders_OrderDate on (OrderDate) with no
included columns
An actual execution plan captured from Query Store for slow runs shows the following:
- An index seek on IX_Orders_OrderDate followed by a Key Lookup
(Clustered) on PK_Orders for CustomerId, Status, and TotalAmount
- A sort operator before Top (50), because the results are ordered by
OrderDate DESC
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 24
You have an Azure SQL database that contains tables named dbo.ProductDocs and dbo.ProductDocsEmbeddings. dbo.ProductDocs contains product documentation and the following columns:
- DocID (int)
- Title (nvarchar(200))
- Body (nvarchar(max))
- LastModified (datetime2)
The documentation is edited throughout the day.
dbo.ProductDocsEmbeddings contains the following columns:
- DocID (int)
- ChunkOrder (int)
- ChunkText (nvarchar(max))
- Embedding (vector(1536))
The current embedding pipeline runs once per night.
You need to ensure that embeddings are updated every time the underlying documentation content changes. The solution must NOT require a nightly batch process.
What should you include in the solution?
Answer: C
Explanation:
To ensure embeddings are updated immediately when the product information table changes, you should implement Azure SQL Database Change Tracking combined with Azure Functions triggered via Event Grid. This approach eliminates daily batch processes by enabling an event- driven architecture that triggers embedding regeneration only for modified rows.
Reference:
https://medium.com/@granthgharewal/why-change-tracking-needs-to-be-enabled-for-sql-trigger- azure-functions-7d230a669fb8
NEW QUESTION # 25
Vou have a Microsoft Fabric workspace named Workspace1 that contains a SQL database named SalesDB and an API for GraphQL tern named SalesApi.
You have a Microsoft Entra group named SqlUsers.
From Workspace1, you assign permission to SalesApi as shown in the following exhibit.
The connection to SalesDB has the connectivity option configured as shown in the following exhibit.
SqlUsers has the Viewer role for Workspace1.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
The members of SqlUsers can modify the data in SalesDB via SalesApi. # No The members of SqlUsers can view the data in SalesDB via SalesApi. # No The members of SqlUsers can change the field mappings of SalesApi. # Yes For both viewing and modifying data through SalesApi, the key missing permission is Run Queries and Mutations. Microsoft's Fabric GraphQL documentation states that callers need Execute permissions for the GraphQL API, which correspond to the Run Queries and Mutations option, and with SSO connectivity they also need appropriate permissions on the underlying data source. In the exhibit, SqlUsers has View and Edit GraphQL item selected, but Run Queries and Mutations is not selected, so members cannot query or mutate data through the API.
The third statement is Yes because the group was explicitly granted View and Edit GraphQL item. That permission is the one that allows users to open and modify the GraphQL item itself, including schema-related configuration such as field mappings in the API item. The workspace Viewer role does not by itself grant query execution through the API, but the direct GraphQL item permission shown does allow editing the item.
NEW QUESTION # 26
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.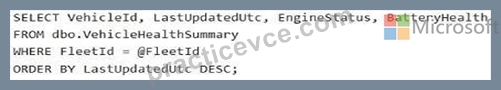
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
Hotspot Question
You need to create a table in the database to store the telemetry data.
You have the following Transact-SQL code.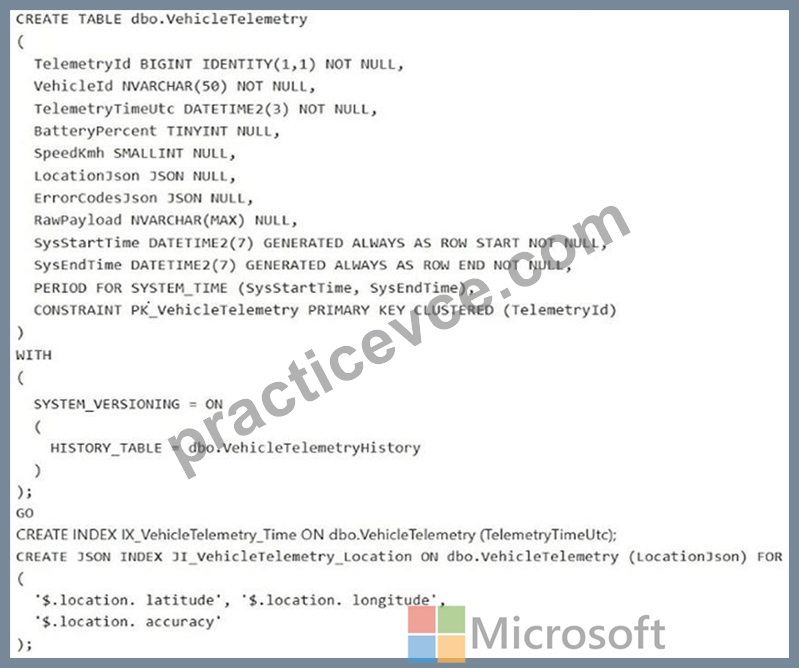
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 27
You have a database named DB1. The schema is stored in a GitHub repository as an SDK style SQL database project.
You use a feature branch workflow to deploy changes to DB1
You need to update the local feature branch with the latest changes to main, and then create a pull request to merge the feature branch into main for review.
How should you complete the GitHub CLI script? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.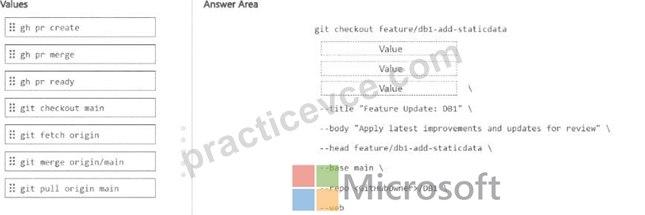
Answer:
Explanation:
Explanation:
The correct sequence is:
git fetch origin
git merge origin/main
gh pr create
This is the right workflow because the script starts on the local feature branch:
git checkout feature/db1-add-staticdata
To update that local feature branch with the latest changes from main, you first fetch the latest remote refs with git fetch origin, then merge the updated remote main branch into the current feature branch with git merge origin/main. After the feature branch is up to date, the correct GitHub CLI command to open the pull request is gh pr create. GitHub's CLI documentation shows that gh pr create is the command used to create a pull request, and supports flags such as --title, --body, --head, --base, --repo, and --web, which match the script shown in the question.
The other commands are not the best fit here:
git checkout main would move you off the feature branch, which is not what you want before merging main into the feature branch.
git pull origin main could update from remote main, but the script pattern here clearly separates fetching and then merging.
gh pr merge merges an existing pull request, not create one.
gh pr ready marks a draft PR as ready for review, but does not create the PR.
NEW QUESTION # 28
......
If you fail to get success in the Microsoft DP-800 test, you can claim your money back according to some terms and conditions. If you want to practice offline, use our Microsoft DP-800 desktop practice test software. Windows computers support this software. The DP-800 web-based practice exam is compatible with all browsers and operating systems.
Reasonable DP-800 Exam Price: https://www.practicevce.com/Microsoft/DP-800-practice-exam-dumps.html