ユニーク-正確的なDP-100関連復習問題集試験-試験の準備方法DP-100全真模擬試験

無料でクラウドストレージから最新のJPTestKing DP-100 PDFダンプをダウンロードする:https://drive.google.com/open?id=1GRikl6xJiM4_noDMq0PEE0DIMhVML57r
お客様の暇が少ないので、勉強する時間が少ないことを考えています。DP-100試験資料は便利で、覚えやすいです。また、もう一つの特徴は時間を節約することです。つまり、DP-100試験資料を短い時間で勉強すると、DP-100試験を受けることができます。大切なのはDP-100試験資料の的中率が高いです。
Microsoft DP-100 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Explore data and run experiments | 20-25% | - Run experiments
- 1. Use automated machine learning
- 2. Configure experiment runs
- 3. Track runs with MLflow
- 4. Define parameters and configurations
- Implement pipelines
- 1. Build reusable components
- 2. Create and publish pipelines
- 3. Pass data between steps
- 4. Schedule and monitor pipelines
- Explore and visualize data
- 1. Identify features and relationships
- 2. Profile and validate data
- 3. Detect anomalies and outliers
|
| Topic 2: Optimize language models for AI applications | 25-30% | - Implement generative AI solutions
- 1. Use Azure AI Foundry
- 2. Build prompt flows
- 3. Apply prompt engineering
- Optimize with Retrieval Augmented Generation
- 1. Configure Azure AI Search
- 2. Create vector stores and indexes
- 3. Prepare and process data
- Evaluate and improve models
- 1. Test and evaluate responses
- 2. Apply responsible generative AI
- 3. Optimize for accuracy and safety
|
| Topic 3: Train and deploy models | 25-30% | - Monitor and maintain models
- 1. Update and retrain models
- 2. Implement MLOps practices
- 3. Monitor performance and data drift
- Manage models
- 1. Interpret models and explain predictions
- 2. Package and validate models
- 3. Register and version models
- Deploy models
- 1. Secure endpoints and manage access
- 2. Deploy to batch endpoints
- 3. Configure compute and scaling
- 4. Deploy to online endpoints
- Train models
- 1. Use HyperDrive for hyperparameter tuning
- 2. Run training scripts
- 3. Apply responsible AI principles
- 4. Configure jobs and environments
|
| Topic 4: Design and prepare a machine learning solution | 20-25% | - Manage compute resources
- 1. Attach and monitor compute
- 2. Create and configure compute targets
- 3. Select environments
- Manage data assets
- 1. Select storage services
- 2. Register and manage datastores
- 3. Create and maintain data assets
- Design a machine learning solution
- 1. Plan model deployment requirements
- 2. Define compute specifications for workloads
- 3. Determine dataset structure and format
- 4. Select development approach
- Manage Azure Machine Learning workspace
- 1. Set up Git integration
- 2. Create and configure workspace
- 3. Work with registries
- 4. Use developer tools and CLI
|
>> DP-100関連復習問題集 <<
試験の準備方法-効率的なDP-100関連復習問題集試験-実用的なDP-100全真模擬試験
JPTestKingが提供するDP-100試験の質問は、Microsoft専門家によって精巧にコンパイルされ、さまざまなバージョン(PDFバージョン、ソフトバージョン、APPバージョン)を強化します。 君は。 DP-100トレーニングブレインダンプは、他のダンプよりも安価であるだけでなく、より効果的です。 当社のDP-100学習教材の高い合格率は、数千人の候補者によって承認されており、彼らは当社のウェブサイトをDP-100のDesigning and Implementing a Data Science Solution on Azure試験に合格する唯一の学習ツールとして認識しています。
Microsoft Designing and Implementing a Data Science Solution on Azure 認定 DP-100 試験問題 (Q36-Q41):
質問 # 36
A coworker registers a datastore in a Machine Learning services workspace by using the following code:
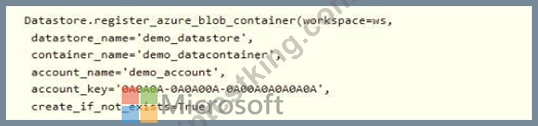
You need to write code to access the datastore from a notebook.
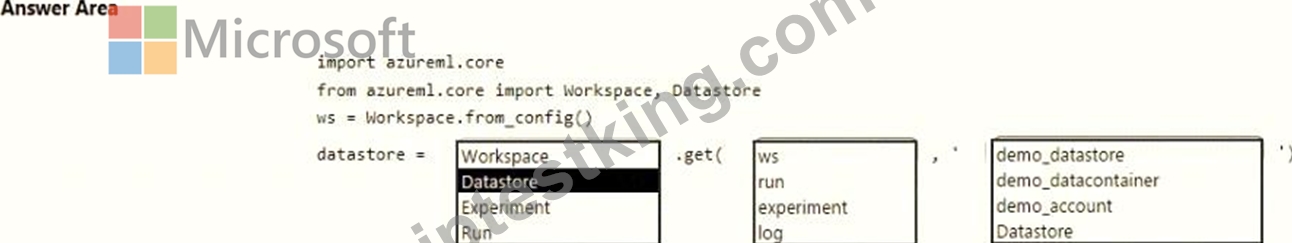
正解:
解説:
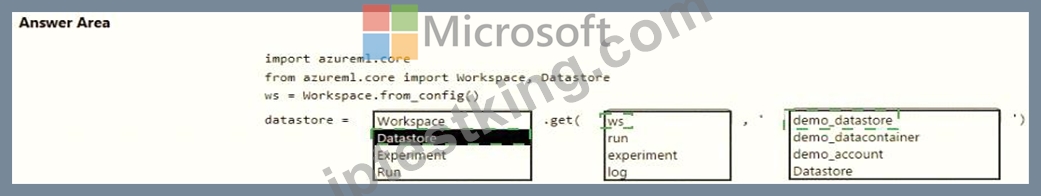
Explanation:
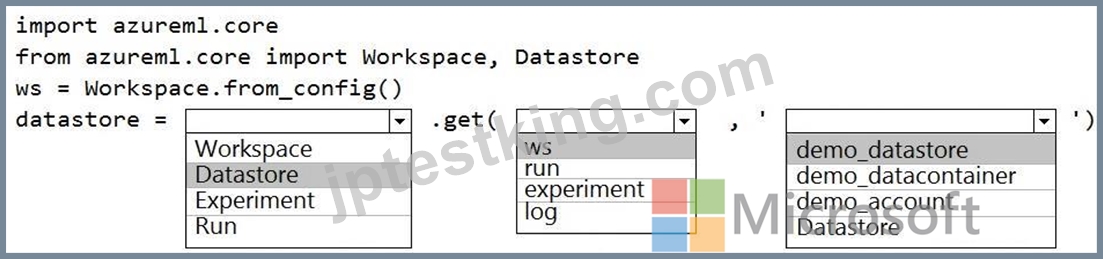
Box 1: DataStore
To get a specific datastore registered in the current workspace, use the get() static method on the Datastore class:
# Get a named datastore from the current workspace
datastore = Datastore.get(ws, datastore_name='your datastore name')
Box 2: ws
Box 3: demo_datastore
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-access-data
質問 # 37
You create an Azure Machine Learning workspace. The workspace contains a dataset named sample.dataset, a compute instance, and a compute cluster. You must create a two-stage pipeline that will prepare data in the dataset and then train and register a model based on the prepared data. The first stage of the pipeline contains the following code:

You need to identify the location containing the output of the first stage of the script that you can use as input for the second stage. Which storage location should you use?
- A. workspaceblobstore datastore
- B. compute instance
- C. workspacefi lest ore datastore
正解:B
質問 # 38
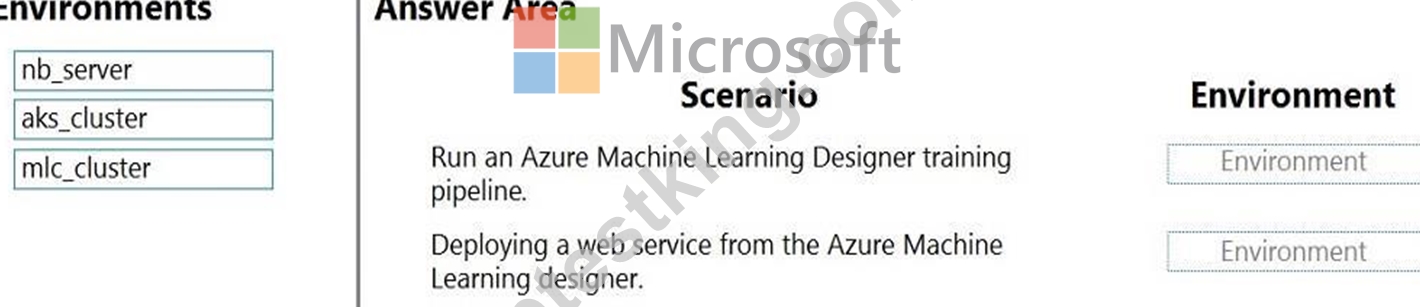
Drag and Drop Question
An organization uses Azure Machine Learning service and wants to expand their use of machine learning.
You have the following compute environments. The organization does not want to create another compute environment.

You need to determine which compute environment to use for the following scenarios.
Which compute types should you use? To answer, drag the appropriate compute environments to the correct scenarios. Each compute environment may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
正解:
解説:
Explanation:
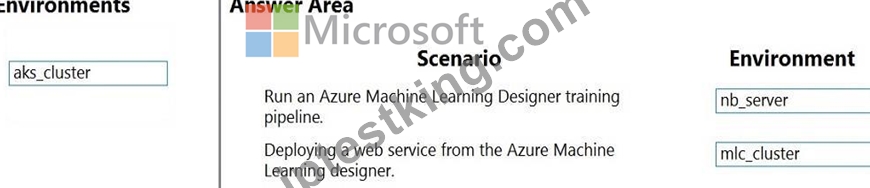
Box 1: nb_server
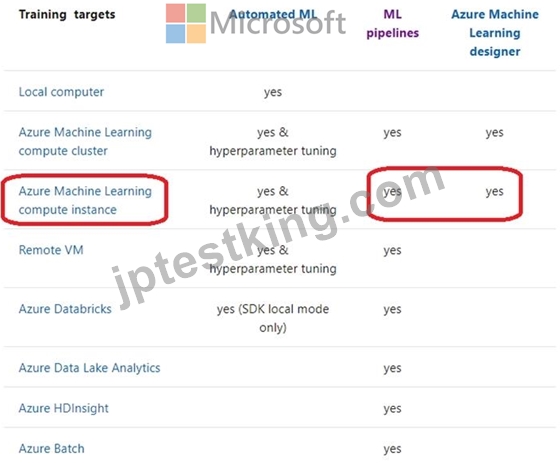
Box 2: mlc_cluster
With Azure Machine Learning, you can train your model on a variety of resources or environments, collectively referred to as compute targets. A compute target can be a local machine or a cloud resource, such as an Azure Machine Learning Compute, Azure HDInsight or a remote virtual machine.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/concept-compute-target
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-set-up-training-targets
質問 # 39
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
The default datastore of workspace1 contains a folder named sample_data. The folder structure contains the following content:
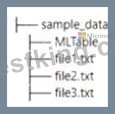
You write Python SDK v2 code to materialize the data from the files in the sample.data folder into a Pandas data frame. You need to complete the Python SDK v2 code to use the MLTaWe folder as the materialization blueprint. How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
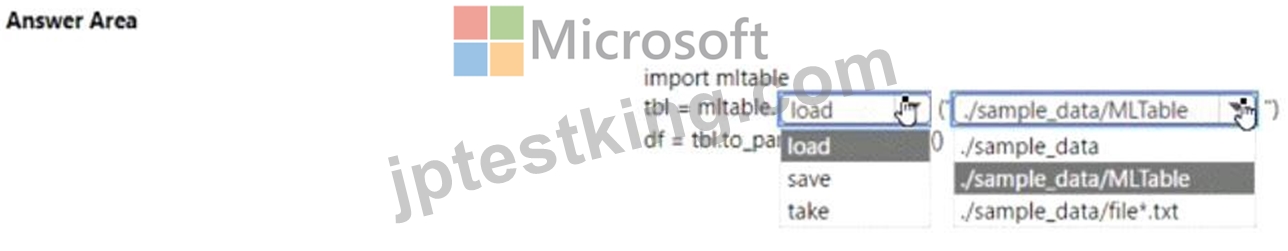
正解:
解説:
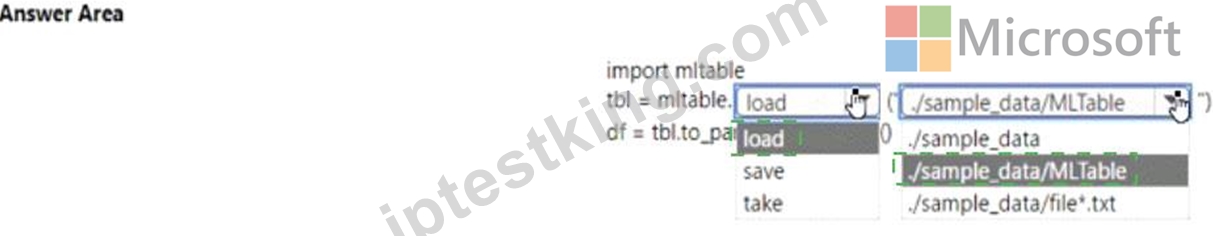
Explanation

質問 # 40
You are implementing hyperparameter tuning for a model training from a notebook. The notebook is in an Azure Machine Learning workspace. You add code that imports all relevant Python libraries.
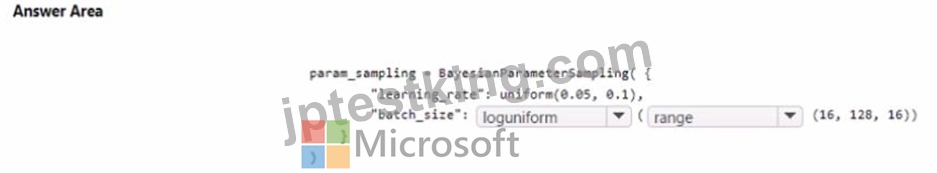
You must configure Bayesian sampling over the search space for the num_hidden_layers and batch_size hyperparameters.
You need to complete the following Python code to configure Bayesian sampling.
Which code segments should you use? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.
正解:
解説:

質問 # 41
......
MicrosoftのDP-100認定試験はJPTestKingの最優秀な専門家チームが自分の知識と業界の経験を利用してどんどん研究した、満足Microsoft認証受験生の需要に満たすの書籍がほかのサイトにも見えますが、JPTestKingの商品が最も保障があって、君の最良の選択になります。
DP-100全真模擬試験: https://www.jptestking.com/DP-100-exam.html
- DP-100試験の準備方法|効果的なDP-100関連復習問題集試験|高品質なDesigning and Implementing a Data Science Solution on Azure全真模擬試験 💈 サイト⮆ www.passtest.jp ⮄で⇛ DP-100 ⇚問題集をダウンロードDP-100受験料過去問
- DP-100オンライン試験 🐨 DP-100問題と解答 🌁 DP-100受験料 🦅 ウェブサイト{ www.goshiken.com }を開き、《 DP-100 》を検索して無料でダウンロードしてくださいDP-100試験参考書
- DP-100受験料 🐖 DP-100オンライン試験 🚝 DP-100受験料過去問 🟥 【 www.passtest.jp 】で使える無料オンライン版➡ DP-100 ️⬅️ の試験問題DP-100試験勉強書
- DP-100試験の準備方法|効果的なDP-100関連復習問題集試験|高品質なDesigning and Implementing a Data Science Solution on Azure全真模擬試験 🙌 ▛ www.goshiken.com ▟で使える無料オンライン版( DP-100 ) の試験問題DP-100オンライン試験
- 有難いMicrosoft DP-100 | 真実的なDP-100関連復習問題集試験 | 試験の準備方法Designing and Implementing a Data Science Solution on Azure全真模擬試験 😭 ▶ DP-100 ◀を無料でダウンロード➽ www.jpshiken.com 🢪で検索するだけDP-100日本語受験教科書
- DP-100試験の準備方法|効果的なDP-100関連復習問題集試験|高品質なDesigning and Implementing a Data Science Solution on Azure全真模擬試験 📷 ▶ DP-100 ◀を無料でダウンロード⇛ www.goshiken.com ⇚ウェブサイトを入力するだけDP-100 PDF問題サンプル
- DP-100 PDF 🥧 DP-100復習テキスト ⚽ DP-100 PDF 🧼 { www.it-passports.com }サイトにて➽ DP-100 🢪問題集を無料で使おうDP-100受験料過去問
- DP-100試験の準備方法|有効的なDP-100関連復習問題集試験|信頼的なDesigning and Implementing a Data Science Solution on Azure全真模擬試験 🔚 今すぐ☀ www.goshiken.com ️☀️で{ DP-100 }を検索して、無料でダウンロードしてくださいDP-100最新問題
- 素晴らしいDP-100関連復習問題集一回合格-信頼できるDP-100全真模擬試験 🚹 ☀ www.goshiken.com ️☀️で《 DP-100 》を検索して、無料で簡単にダウンロードできますDP-100試験番号
- DP-100試験の準備方法|完璧なDP-100関連復習問題集試験|実際的なDesigning and Implementing a Data Science Solution on Azure全真模擬試験 🥣 ✔ www.goshiken.com ️✔️サイトにて最新《 DP-100 》問題集をダウンロードDP-100模擬モード
- 無料PDFDP-100関連復習問題集 | 最初の試行で簡単に勉強して試験に合格する - 更新のDP-100: Designing and Implementing a Data Science Solution on Azure 🛩 今すぐ⏩ www.xhs1991.com ⏪で▶ DP-100 ◀を検索して、無料でダウンロードしてくださいDP-100試験勉強書
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, youemerge.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
さらに、JPTestKing DP-100ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1GRikl6xJiM4_noDMq0PEE0DIMhVML57r