Databricks Certified Machine Learning Professional exam collection,Databricks-Machine-Learning-Professional actual test

What's more, part of that TestPDF Databricks-Machine-Learning-Professional dumps now are free: https://drive.google.com/open?id=1rKf8r9zFNw8FKDTDm3SgGQKPjR6CdwWa
TestPDF is the leading position in this field and famous for high pass rate of the Databricks-Machine-Learning-Professional learning guide. If you are headache about your qualification exams, our Databricks-Machine-Learning-Professional learning guide materials will be a great savior for you. Now it is your opportunity that we provide the best valid and professional Databricks-Machine-Learning-Professional Study Guide materials which have 100% pass rate. If you really want to clear exam and gain success one time, choosing us will be the wise thing for you. If you hesitate about us please pay attention on below about our satisfying service and high-quality Databricks-Machine-Learning-Professional guide torrent.
Databricks Databricks-Machine-Learning-Professional Exam Overview:
>> Databricks-Machine-Learning-Professional Reliable Exam Camp <<
Databricks-Machine-Learning-Professional Exam Questions - To Gain Brilliant Result
After our unremitting efforts, Databricks-Machine-Learning-Professional learning guide comes in everybody's expectation. Our professional experts not only have simplified the content and grasp the key points for our customers, but also recompiled the Databricks-Machine-Learning-Professional preparation materials into simple language so that all of our customers can understand easily no matter which countries they are from. In such a way, you will get a leisure study experience as well as a doomed success on your coming Databricks-Machine-Learning-Professional Exam.
| Topic | Details |
|---|
| Topic 1 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 2 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 3 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Topic 4 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 5 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 6 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Topic 7 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 8 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 9 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 10 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
Databricks Certified Machine Learning Professional Sample Questions (Q45-Q50):
NEW QUESTION # 45
A Data Scientist is tasked with developing models to forecast product demand. The company offers 5000 different product types, and the Data Scientist must generate weekly forecasts for each type. They have access to two years of historical purchase data and are given ample project budget.
For their next project, they want to build 5000 separate Random Forest models, one for each product type. They aim to train all the models as quickly as possible with minimal setup.
Which approach meets these requirements?
- A. Leverage the pandas function API (Grouped map) to group the data by product type and apply a custom model training function to each group.
- B. Use the RandomForest method from MLlib. This will leverage Spark's parallel processing capability to train 5000 different models.
- C. Create a Databricks Workflow with 5000 tasks. Each task is configured to accept a product ID as a parameter which will then train a model based on the specified product ID.
- D. Use the DeepSpeed library to distribute the data by product across different nodes to enable the parallel training of multiple models.
Answer: A
Explanation:
The pandas function API with grouped map allows data to be grouped by product type and applies a custom training function independently to each group. This approach enables massive parallelism across the cluster with minimal orchestration or setup, making it well suited for rapidly training thousands of independent models in parallel.
NEW QUESTION # 46
A machine learning engineer has developed a random forest model using scikit-learn, logged the model using MLflow as random_forest_model, and stored its run ID in the run_id Python variable.
They now want to deploy that model by performing batch inference on a Spark DataFrame spark_df. Which of the following code blocks can they use to create a function called predict that they can use to complete the task?
- A.
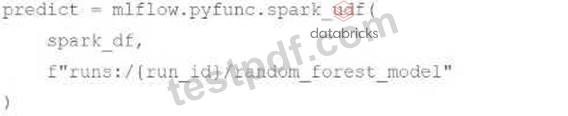
- B.
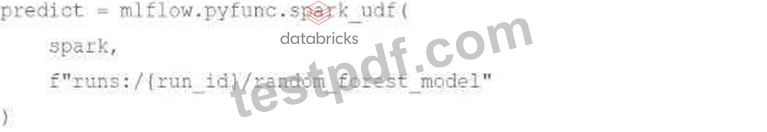
- C. It is not possible to deploy a scikit-learn model on a Spark DataFrame.
- D.
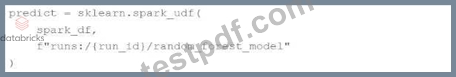
- E.
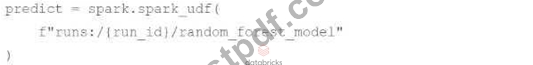
Answer: E
NEW QUESTION # 47
A machine learning engineer has developed a model and registered it using the FeatureStoreClient fs. The model has model URI model_uri. The engineer now needs to perform batch inference on customer-level Spark DataFrame spark_df, but it is missing a few of the static features that were used when training the model. The customer_id column is the primary key of spark_df and the training set used when training and logging the model.
Which of the following code blocks can be used to compute predictions for spark_df when the missing feature values can be found in the Feature Store by searching for features by customer_id?
- A. df = fs.get_missing_features(spark_df, model_uri)
fs.score_model(model_uri, df) - B. fs.score_batch(model_uri, spark_df)
- C. df = fs.get_missing_features(spark_df)
fs.score_batch(model_uri, df) - D. df = fs.get_missing_features(spark_df, model_uri)
fs.score_batch(model_uri, df) - E. fs.score_model(model_uri, spark_df)
Answer: B
NEW QUESTION # 48
Which MLflow operation can be used to log a plot that was generated during an MLflow run?
- A. mlflow.log_figure
- B. None of these operations can accomplish the task.
- C. mlflow.log_metric
- D. mlflow.log_visualization
Answer: A
Explanation:
The mlflow.log_figure() operation is used to log plots or figures generated during an MLflow run. It takes a Matplotlib, Plotly, or similar figure object and saves it as an artifact in the MLflow tracking server, enabling visualization and later retrieval from the MLflow UI.
NEW QUESTION # 49
Which is a benefit of logging an input example with an MLflow model?
- A. An example record is available to test serving applications
- B. The model evaluation metrics are stored with the model
- C. An example prediction is available to test post-inference pipelines
- D. The environment requirements are packaged with the MLmodel file
Answer: A
Explanation:
Logging an input example with an MLflow model provides a concrete sample of the data format expected by the model. This helps serving applications and users understand the model's input structure and verify that inference requests are properly formatted when deploying or testing the model in production.
NEW QUESTION # 50
......
Databricks-Machine-Learning-Professional Latest Test Report: https://www.testpdf.com/Databricks-Machine-Learning-Professional-exam-braindumps.html
- Quiz Newest Databricks - Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional Reliable Exam Camp 🔷 Simply search for 《 Databricks-Machine-Learning-Professional 》 for free download on 【 www.examdiscuss.com 】 📙Databricks-Machine-Learning-Professional Examcollection Free Dumps
- Databricks-Machine-Learning-Professional PDF VCE 🧐 Databricks-Machine-Learning-Professional Exam Tips 🌎 Reliable Databricks-Machine-Learning-Professional Test Braindumps 🐞 Enter ➽ www.pdfvce.com 🢪 and search for ➠ Databricks-Machine-Learning-Professional 🠰 to download for free 🎱Databricks-Machine-Learning-Professional Real Brain Dumps
- Databricks-Machine-Learning-Professional Latest Mock Test ⛴ Databricks-Machine-Learning-Professional Examcollection Free Dumps 🍍 Valid Braindumps Databricks-Machine-Learning-Professional Ppt 👵 Enter ⮆ www.prepawayexam.com ⮄ and search for ▛ Databricks-Machine-Learning-Professional ▟ to download for free 🦹Real Databricks-Machine-Learning-Professional Exam Answers
- Real Databricks-Machine-Learning-Professional Exam Answers 🧖 Valid Braindumps Databricks-Machine-Learning-Professional Ppt 🧿 Databricks-Machine-Learning-Professional Latest Test Simulations ⭐ Search for “ Databricks-Machine-Learning-Professional ” and download exam materials for free through ⇛ www.pdfvce.com ⇚ 😋Databricks-Machine-Learning-Professional Latest Mock Test
- Quiz Newest Databricks - Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional Reliable Exam Camp 🎡 Search for ( Databricks-Machine-Learning-Professional ) and easily obtain a free download on ➡ www.exam4labs.com ️⬅️ 👯Databricks-Machine-Learning-Professional Test Duration
- Pass Guaranteed Quiz Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional –High Pass-Rate Reliable Exam Camp 🔛 Open “ www.pdfvce.com ” and search for “ Databricks-Machine-Learning-Professional ” to download exam materials for free 🕥Databricks-Machine-Learning-Professional Latest Exam Notes
- Pass Guaranteed Professional Databricks - Databricks-Machine-Learning-Professional Reliable Exam Camp ☘ 「 www.examcollectionpass.com 」 is best website to obtain ⇛ Databricks-Machine-Learning-Professional ⇚ for free download 😖Reliable Databricks-Machine-Learning-Professional Test Braindumps
- Databricks-Machine-Learning-Professional Real Brain Dumps ✔ Databricks-Machine-Learning-Professional Latest Test Simulations 🍄 Databricks-Machine-Learning-Professional New Real Exam 🌲 Open [ www.pdfvce.com ] enter 【 Databricks-Machine-Learning-Professional 】 and obtain a free download 🌴Reliable Databricks-Machine-Learning-Professional Test Braindumps
- Databricks-Machine-Learning-Professional Latest Exam Notes 🍊 Databricks-Machine-Learning-Professional Test Duration 🐁 Exam Databricks-Machine-Learning-Professional Guide 🥠 Enter ➥ www.practicevce.com 🡄 and search for { Databricks-Machine-Learning-Professional } to download for free 🔥Exam Databricks-Machine-Learning-Professional Bootcamp
- 2026 100% Free Databricks-Machine-Learning-Professional –Perfect 100% Free Reliable Exam Camp | Databricks-Machine-Learning-Professional Latest Test Report 👦 Download ▛ Databricks-Machine-Learning-Professional ▟ for free by simply entering ➥ www.pdfvce.com 🡄 website 🍨Databricks-Machine-Learning-Professional Examcollection Free Dumps
- Databricks-Machine-Learning-Professional Exam Tips 😈 Exam Databricks-Machine-Learning-Professional Guide 🐏 Databricks-Machine-Learning-Professional Latest Test Simulations 🏧 Search for ☀ Databricks-Machine-Learning-Professional ️☀️ and download it for free on 【 www.vce4dumps.com 】 website 🔮Databricks-Machine-Learning-Professional Latest Test Simulations
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, jacobscott67888.blogspot.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
DOWNLOAD the newest TestPDF Databricks-Machine-Learning-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1rKf8r9zFNw8FKDTDm3SgGQKPjR6CdwWa