21世紀には、{Examcode}認定は受験者の特定の能力を表すため、社会でますます認知されるようになりました。ただし、{Examcode}認定を取得するには、DP-750試験の準備に多くの時間を費やす必要があります。合格しなくても、DP-750模擬試験の価格を支払う必要はありません。私たちがあなたに感銘を与えるのに十分な誠意を持っていることを望みます。
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
DP-750模擬試験は、緊急の課題に対処するための最適な選択および有用なツールとなります。 10年以上の努力により、当社のDP-750トレーニング資料は、業界で最も広く称賛され、待望の製品になりました。革新メカニズムを近代化し、専門家の強力なプールを育成することにより、DP-750試験問題の3つのバージョンがあります。したがって、DP-750模擬テストの計画と設計において、プロのエリートからの完全な技術サポートをご安心ください。
質問 # 16
You have an Azure Databricks workspace that uses Databricks SQL.
You have a table named sales_goals_source that contains the following columns:
* Salesperson
* Item
* 2019
* 2020
* 2021
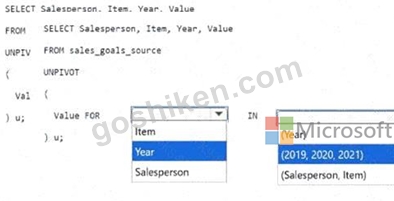
You need to transform the year columns into rows and return the columns Salesperson, Item, Year, and Value.
How should you complete the SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
SELECT Salesperson, Item, Year, Value
FROM sales_goals_source
UNPIVOT
(
Value FOR [first dropdown] IN [second dropdown]
);
正解:
解説: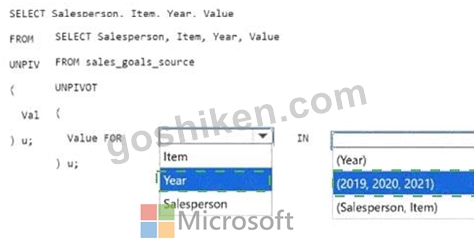
Explanation:
First dropdown: Year
Second dropdown: (2019, 2020, 2021)
The UNPIVOT operator converts the separate 2019, 2020, and 2021 columns into rows. Value becomes the output column containing the values previously stored in those year columns. Year becomes the output name column that identifies the original column from which each value came. Therefore, the expression must use Value FOR Year IN (2019, 2020, 2021). The Salesperson and Item columns are not included in the IN list because they remain identifier columns and are repeated for every resulting year row. A single source row consequently produces three output rows-one for each listed year. Selecting (Year) would reference an output name rather than the source columns that must be rotated.
質問 # 17
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
正解:A
解説:
The correct answer is A. Photon is Azure Databricks' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso's requirement for 'fast and consistent performance for BI workloads' and 'production ingestion workloads that can scale automatically during telemetry spikes.' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what's needed - telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
質問 # 18
You need to deploy Declarative Automation Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
正解:A
解説:
The Databricks CLI contains the bundle command group for validating, deploying, and running Declarative Automation Bundles. CLI commands can be executed consistently from developer terminals or CI/CD pipelines, making deployments automated, repeatable, and suitable for multiple target environments. The Databricks SDK for Python can manage workspace APIs programmatically, but it is not the standard bundle deployment interface required here. Git folders provide source-control integration inside the workspace but do not deploy bundle-defined resources. The Jobs UI supports interactive creation and management of jobs, which introduces manual steps and does not provide the same infrastructure-as-code workflow. Using commands such as databricks bundle validate and databricks bundle deploy -t dev directly satisfies the automated development deployment requirement. Microsoft Learn
質問 # 19
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Payments.
Payments stores transaction data and contains a column named payment_amount of the Decimal data type.
You must enforce the following business rule:
payment_amount must be between 0 and 10,000, inclusive
You need to ensure that records that violate the rule are rejected when data is written to the Payments table.
What should you do?
正解:D
解説:
A CHECK constraint enforces a Boolean condition whenever data is inserted or updated. The constraint can require payment_amount > = 0 AND payment_amount < = 10000, causing a transaction containing an invalid value to fail instead of allowing the record into Payments. This provides storage-level data-quality enforcement regardless of which pipeline, notebook, or SQL statement performs the write. Row-level security controls which existing records users can see; it does not reject invalid writes. SELECT statements filter results only when they are executed and therefore cannot protect the underlying table. Table update triggers are not the standard Delta Lake mechanism for this requirement. Azure Databricks classifies CHECK constraints as enforced constraints and rejects transactions when their conditions are violated. Microsoft Learn
質問 # 20
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
* Ensure that amount is always greater than 0.
* Fail the pipeline update for Table1 when data that violates rule1 is detected.
Which statement should you execute?
正解:C
解説:
The expect_or_fail decorator validates every incoming record against the expression amount > 0 and stops the table update when a violation occurs. This exactly meets the requirement that invalid data cause the pipeline update to fail. Option A applies multiple expectations and drops violating records instead of failing the update. Option B also discards invalid records while allowing valid records to continue processing. Option D records expectation metrics but retains invalid records and allows the update to continue. These alternative behaviors are useful when invalid data can be tolerated, quarantined, or monitored, but they do not satisfy strict enforcement. The fail action provides transactional protection because the affected update does not successfully publish data that violates the stated quality rule.
質問 # 21
......
GoShikenすべての賞賛と高い価値は、DP-750練習エンジンのより高い標準へと導きます。 そのため、試験の受験者の関心を高く評価するあなたの関心に対して、私たちの労働倫理が強く強調されています。 私たちMicrosoftの実践教材は、Implementing Data Engineering Solutions Using Azure Databricks専門知識の本質を捉えて、あなたを楽に望ましい結果に導きます。 そこで、DP-750学習教材の利点を引き続き参照しましょう。
DP-750試験復習: https://www.goshiken.com/Microsoft/DP-750-mondaishu.html