For quick and complete Developing AI-Enabled Database Solutions (DP-800) exam preparation you can trust TestPassKing Microsoft DP-800 Exam Questions. With the Microsoft DP-800 practice test questions you can ace your Developing AI-Enabled Database Solutions (DP-800) exam preparation and be ready to perform well in the final Microsoft DP-800 certification exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Microsoft DP-800 Online Training <<
Propulsion occurs when using our DP-800 practice materials. They can even broaden amplitude of your horizon in this line. Of course, knowledge will accrue to you from our DP-800 practice materials. There is no inextricably problem within our DP-800 practice materials. Motivated by them downloaded from our website, more than 98 percent of clients conquered the difficulties. So can you.
NEW QUESTION # 49
You have a database named DB1. The schema is stored in a GitHub repository as an SDK style SQL database project.
You use a feature branch workflow to deploy changes to DB1
You need to update the local feature branch with the latest changes to main, and then create a pull request to merge the feature branch into main for review.
How should you complete the GitHub CLI script? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.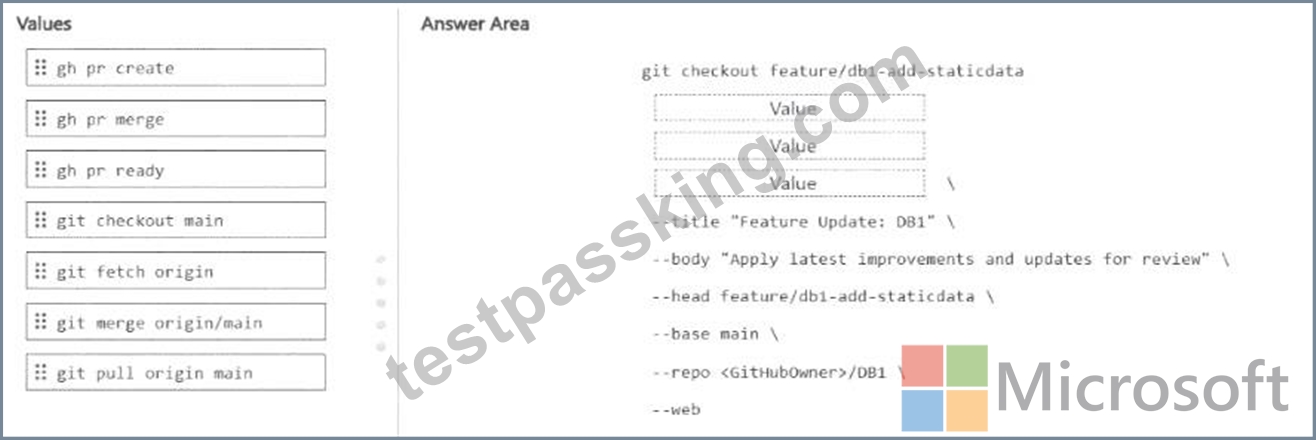
Answer:
Explanation: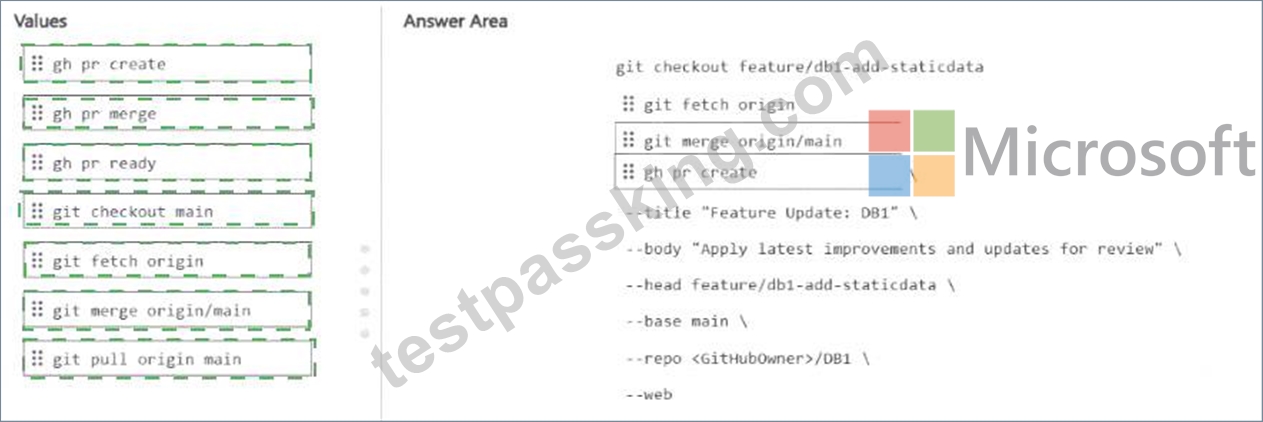
Explanation: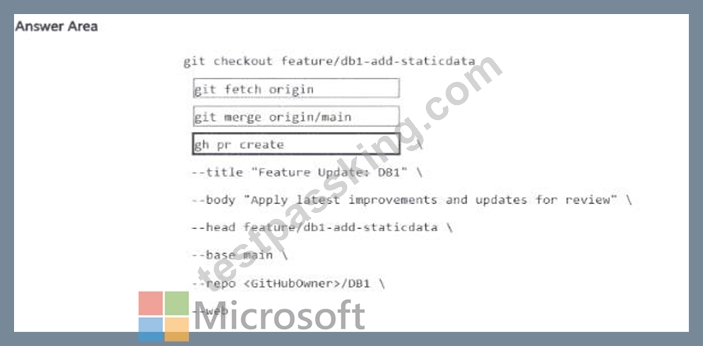
The correct sequence is:
* git fetch origin
* git merge origin/main
* gh pr create
This is the right workflow because the script starts on the local feature branch:
git checkout feature/db1-add-staticdata
To update that local feature branch with the latest changes from main, you first fetch the latest remote refs with git fetch origin , then merge the updated remote main branch into the current feature branch with git merge origin/main . After the feature branch is up to date, the correct GitHub CLI command to open the pull request is gh pr create . GitHub's CLI documentation shows that gh pr create is the command used to create a pull request, and supports flags such as --title, --body, --head, --base, --repo, and --web, which match the script shown in the question.
The other commands are not the best fit here:
* git checkout main would move you off the feature branch, which is not what you want before merging main into the feature branch.
* git pull origin main could update from remote main, but the script pattern here clearly separates fetching and then merging.
* gh pr merge merges an existing pull request, not create one.
* gh pr ready marks a draft PR as ready for review, but does not create the PR.
NEW QUESTION # 50
You have an Azure SQL database that contains a table named knowledgebase, knowledgebase stores human resources (HR) policy documents and contains columns named title, content, category, and embedding.
You have an application named App1. App1 queries two relational tables named employee_pnofiles and benefits_enrollnent that contain HR data. App1 hosts a chatbot that calls a large language model (LLM) directly.
Users report that the chatbot answers general HR questions correctly but provides outdated or incorrect answers when policies change. The chatbot also fails to answer questions that reference internal policy documents by title or category.
You need to recommend a Retrieval Augmented Generation (RAG) solution to resolve the chatbot issues.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.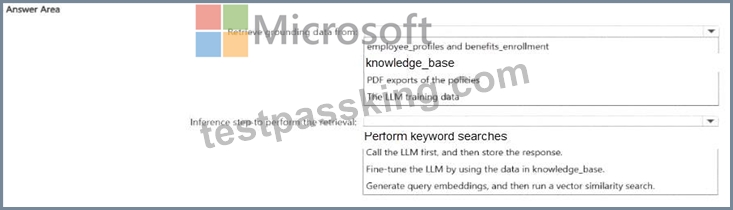
Answer:
Explanation: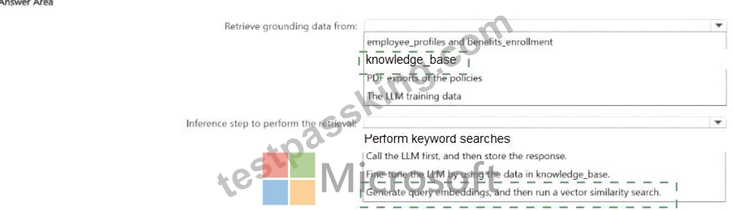
Explanation: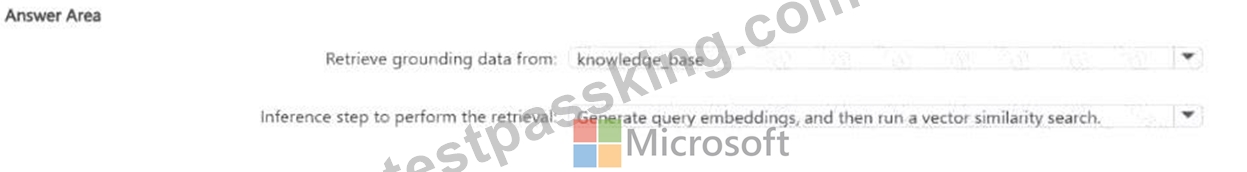
The correct recommendation is to retrieve grounding data from knowledge_base and, at inference time, generate query embeddings and run a vector similarity search .
The chatbot currently answers some general HR questions but fails when policies change and when users ask about internal policy documents by title or category . That is exactly the kind of problem RAG is meant to solve: ground the LLM in the organization's proprietary content instead of relying on the model's training data or unrelated transactional tables. Microsoft's RAG guidance states that RAG extends LLMs by grounding responses in your own content and that, for agentic retrieval, knowledge bases unify knowledge sources for retrieval.
So the grounding data should come from knowledge_base , because that table stores the HR policy documents and already includes fields like title, content, category, and embedding. Those are the fields directly tied to the missing and outdated policy answers. By contrast:
* employee_profiles and benefits_enrollment are operational HR tables, not the authoritative store for policy-document grounding.
* PDF exports of the policies would be inferior to querying the indexed/structured knowledge base already prepared for retrieval.
* The LLM training data is specifically the wrong source when the issue is outdated internal content.
For the retrieval step, Microsoft's guidance says to use embeddings for vector queries and notes that vector similarity search matches concepts, not exact terms . This is especially important because users ask about policy documents by title or category and also phrase questions in ways that might not exactly match document wording. Generating a query embedding and then running a vector similarity search is the appropriate retrieval step in a RAG pipeline.
NEW QUESTION # 51
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.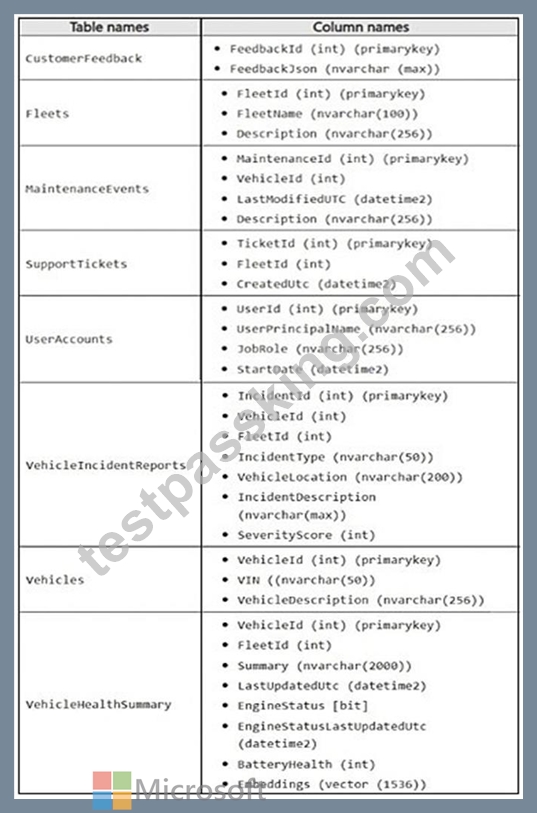
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.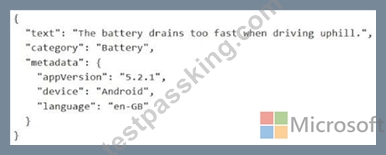
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.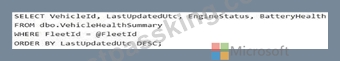
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to recommend a solution for the development team to retrieve the live metadata. The solution must meet the development requirements. What should you include in the recommendation?
Answer: A
Explanation:
Scenario: Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
To retrieve live metadata from Azure SQL databases and use it with GitHub Copilot in Visual Studio Code (VS Code), you must use the SQL Server (mssql) extension. This extension provides the native capability to extract a database schema as a .dacpac file directly within the editor.
1. Export the Schema as a .dacpac File
You can extract the schema of your live Azure SQL database using the SQL Server (mssql) extension.
2. Load the .dacpac into GitHub Copilot Context
Once the .dacpac file is saved in your VS Code workspace, you can provide it as context to GitHub Copilot Chat using #-mentions or Drag & Drop.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sql-database-projects/concepts/data-tier- applications/extract-dacpac-from-database
NEW QUESTION # 52
You are developing an Azure SQL solution by using Microsoft Visual Studio 2026. The solution uses a GitHub repository.
You plan to use GitHub Copilot Chat to access the GitHub repository tools by connecting to the GitHub MCP Server.
You need to configure Visual Studio to support the planned configuration. The solution must rely on OAuth to access the MCP server.
What should you create?
Answer: A
Explanation:
In this scenario, you need to create an mcp.json file. This file acts as the configuration bridge that tells Visual Studio 2026 and GitHub Copilot Chat how to connect to and communicate with the GitHub MCP Server.
Key Configuration Details
The mcp.json file is typically placed in your solution's root directory or a specific .mcp folder to enable project-specific tools Configuration Steps
1. Create the MCP Configuration File
You must define the connection to the GitHub MCP server so Copilot Chat can interact with your repository tools.
File Name: mcp.json
Location: Usually placed in %AppData%\Microsoft\VisualStudio\2026\mcp.json (or the project root depending on your specific extension settings).
Content:
{
"mcpServers": {
"github": {
"url": "https://api.githubcopilot.com/mcp/",
"auth": "OAuth"
}
}
}
2. Authenticate via OAuth
3. Connect Azure SQL in VS 2026
Reference:
https://www.workato.com/the-connector/mcp-server-tutorial/
NEW QUESTION # 53
You have an Azure SQL database named SalesDB that contains a table named dbo. Articles, dbo.Articles contains two million articles with embeddmgs. The articles are updated frequently throughout the day.
You query the embeddings by using VECTOR_SEARQi
Users report that semantic search results do NOT reflect the updates until the following day.
Vou need to ensure that the embeddings are updated whenever the articles change. The solution must minimize CPU usage on SalesDB Which embedding maintenance method should you implement?
Answer: D
Explanation:
The correct answer is B because the problem is not the vector search operator itself. The problem is that embeddings are becoming stale when article content changes . Microsoft documents that change data capture (CDC) tracks insert, update, and delete operations on source tables, which makes it the right mechanism to identify only the rows that changed.
This also best satisfies the requirement to minimize CPU usage on SalesDB . With CDC, the database only records the row changes, and the embedding regeneration work can be moved to an external process such as an Azure Functions app. That avoids running embedding generation inline inside the database for every update and avoids repeatedly recalculating embeddings for unchanged rows. In contrast, an hourly full-table regeneration would be extremely wasteful on a table with two million frequently updated articles, and a trigger that calls embedding generation per row would push expensive AI work into the transactional path of the database.
Option A is incorrect because changing from VECTOR_SEARCH to VECTOR_DISTANCE does not regenerate embeddings; it only changes the retrieval method. Microsoft states that VECTOR_SEARCH is the ANN search function, while VECTOR_DISTANCE performs exact distance calculation, so neither option addresses stale embedding data.
So the right design is:
* use CDC to detect only changed articles,
* process those changes outside the database,
* regenerate embeddings only for changed rows,
* write back the refreshed embeddings for current semantic search results.
NEW QUESTION # 54
......
Learning knowledge is just like building a house, our DP-800 training materials serve as making the solid foundation from the start with higher efficiency. Even if this is just the first time you are preparing for the exam, you can expect high grade. Taking full advantage of our DP-800 Preparation exam and getting to know more about them means higher possibility of it. And if you have a try on our DP-800 exam questions, you will love them.
DP-800 Exam Tips: https://www.testpassking.com/DP-800-exam-testking-pass.html