100% Pass-Rate Reliable Databricks-Machine-Learning-Professional Guide Files | Accurate 100% Databricks-Machine-Learning-Professional Exam Coverage: Databricks Certified Machine Learning Professional

BONUS!!! Download part of PracticeMaterial Databricks-Machine-Learning-Professional dumps for free: https://drive.google.com/open?id=1Qj_d0OFjytggLWu1O2I1iknmVDPF1dhU
Our Databricks-Machine-Learning-Professional practice materials compiled by the most professional experts can offer you with high quality and accuracy practice materials for your success. Up to now, we have more than tens of thousands of customers around the world supporting our Databricks-Machine-Learning-Professional exam torrent. If you are unfamiliar with our Databricks-Machine-Learning-Professional Study Materials, please download the Databricks-Machine-Learning-Professional free demos for your reference, and to some unlearned exam candidates, you can master necessities by our Databricks-Machine-Learning-Professional practice materials quickly. So our Databricks-Machine-Learning-Professional materials are elemental materials you cannot miss.
| Topic | Details |
|---|
| Topic 1 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 2 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 3 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Topic 4 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 5 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 6 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 7 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 8 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 9 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
>> Reliable Databricks-Machine-Learning-Professional Guide Files <<
Databricks Databricks-Machine-Learning-Professional Practice Test (Web-Based)
Our website always checks the update of Databricks-Machine-Learning-Professional test questions to ensure the accuracy of our study materials and keep the most up-to-dated exam requirements. There are Databricks-Machine-Learning-Professional free demo in our exam page for your reference and one-year free update are waiting for you. Valid Databricks-Machine-Learning-Professional Real Dumps will the guarantee of your success and make you more confident in your career.
Databricks Certified Machine Learning Professional Sample Questions (Q94-Q99):
NEW QUESTION # 94
A Machine Learning Engineer has previously built a feature table for model training and inference using a batch mode approach:
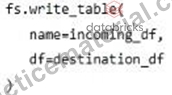
They have been informed that they now require these features to be available in "real-time", with latency on the order of a minute. Their manager has informed them there is now a Kafka stream from which they can stream live data, and they need to have this ingested and available for low- latency feature lookups.
Which change to their existing code will achieve this?
- A. Change the incoming_df to be a dataframe based on a readStream() from the kafka source, the write_table() method will provide a low-latency lookup on this data.
- B. Change the incoming_df to be a dataframe based on a readStream() from the Kafka source and publish the table as an online table with the streaming option set to True.
- C. Create a custom pyfunc MLflow model which processes results of the Kafka stream for on demand feature calculation.
- D. Run a triggered workflow to ingest the Kafka data to a dataframe that they can use with their existing write_table() command.
Answer: B
Explanation:
To achieve real-time availability with minute-level latency, the feature data must be continuously ingested from Kafka and published to an online table. Using a streaming DataFrame created with readStream from the Kafka source and enabling the online table with streaming allows incremental updates to be synchronized to the online store, supporting low-latency feature lookups for real-time inference.
NEW QUESTION # 95
A Machine Learning Engineer needs a continuous deployment pipeline for their models hosted on Databricks Model Serving. The deployment automation should execute after a model is trained and registered using MLflow. The goal of the automation is to deploy the latest version of the model from the MLflow Model Registry only if the model can meet the company's strict latency requirements (P95 < 300ms) while serving production traffic. How can the engineer validate that new models meet their latency requirements when served in production?
- A. Use the MLflow Get Run API to retrieve the model metrics from MLflow Tracking and verify that the model_latency metric is less than 300ms.
- B. A/B test the latest model with Databricks Model Serving so that the latest model receives 5% of production traffic and the current model receives the rest. Use inference tables to calculate P95 latency and verify it is less than 300ms.
- C. Use the MLflow Get Run API to retrieve the model metrics from MLflow Tracking and verify that the inference_latency metric is less than 300ms.
- D. Serve the latest model on Databricks Model Serving and use a load testing client to generate requests at the production request rate. Use the load testing client to calculate P95 latency and verify it is less than 300ms.
Answer: B
Explanation:
Validating latency requirements must be done under real production serving conditions. Routing a small percentage of live production traffic to the new model using Databricks Model Serving allows accurate measurement of end-to-end serving latency. Inference tables capture request latency metrics, enabling calculation of the P95 latency and ensuring it meets the strict production threshold before full rollout.
NEW QUESTION # 96
What is commonly monitored in deployed ML models?
- A. Notebook formatting
- B. Code style
- C. Model drift and prediction quality
- D. GPU usage only
Answer: C
Explanation:
Production ML systems monitor:
data drift
model drift
prediction accuracy.
NEW QUESTION # 97
How can you save a trained Spark ML PipelineModel?
- A. pipeline.persist()
- B. pipeline.save()
- C. pipelineModel.write().save()
- D. pipeline.store()
Answer: C
Explanation:
Example:
pipelineModel.write().overwrite().save("/model")
NEW QUESTION # 98
A Machine Learning Engineer has deployed a fraud detection model in Databricks Model Serving to detect fraudulent transactions. The engineer wants to compare the model's predictions with the actual fraud classifications from the Fraud Ops team to monitor model performance. The Fraud Ops team uses a unique transaction_id to investigate fraudulent activity and persist their findings to a fraud_findings table. The engineer enabled inference tables on the endpoint, but they are not sure how to map the models' predictions to the Fraud Ops team's classifications. How can the engineer uniquely join the models' prediction to the fraud_findings table with the fewest code changes?
- A. Populate the client_request_id field with the transaction_id in the model serving request body.
Join the inference table with the fraud_findings table using client_request_id (which contains the transaction_id) as the join key. - B. Store databricks_request_id returned from each model serving request and persist it to the fraud_findings table. Join the inference table with the fraud_findings table using databricks_request_id as the join key.
- C. Join the inference table with the fraud_findings table using timestamp_ms as the join key.
- D. Modify the model to include an additional input: transaction_id. Log, register and deploy the new model. In the model serving request body, add transaction_id as an additional input feature. Join the inference table with the fraud_findings table using transaction_id as the join key.
Answer: A
Explanation:
Databricks Model Serving inference tables automatically log the client_request_id field for each request. By populating this field with the existing transaction_id in the request body, the engineer can directly and uniquely join inference predictions with the fraud_findings table using the same identifier, achieving accurate performance monitoring with minimal code changes and no model retraining or redeployment.
NEW QUESTION # 99
......
The best investment for the future is improving your professional ability and obtaining Databricks-Machine-Learning-Professional certification exam will bring you great benefits for you. For most IT candidates, passing Databricks-Machine-Learning-Professional actual test will make you stand out from the other people in the interview and offer you more opportunity. The matter now is how to prepare the Databricks-Machine-Learning-Professional Questions and answers in a short time, our Databricks-Machine-Learning-Professional study guide is the best effective way to get through the exam and obtain the certification.
100% Databricks-Machine-Learning-Professional Exam Coverage: https://www.practicematerial.com/Databricks-Machine-Learning-Professional-exam-materials.html
- Latest Databricks-Machine-Learning-Professional Cram Materials 🐲 Databricks-Machine-Learning-Professional Exam Book 🔧 New Databricks-Machine-Learning-Professional Test Sample 📕 Easily obtain free download of ⇛ Databricks-Machine-Learning-Professional ⇚ by searching on ☀ www.exam4labs.com ️☀️ 🚦Trustworthy Databricks-Machine-Learning-Professional Exam Torrent
- Databricks-Machine-Learning-Professional Reliable Test Preparation 🐥 Databricks-Machine-Learning-Professional Dumps PDF 🧓 Latest Databricks-Machine-Learning-Professional Mock Exam 🐇 Download ➽ Databricks-Machine-Learning-Professional 🢪 for free by simply entering ➽ www.pdfvce.com 🢪 website 🗓Databricks-Machine-Learning-Professional Test Assessment
- Databricks-Machine-Learning-Professional Test Assessment ⏰ Databricks-Machine-Learning-Professional Latest Dumps Free 🐨 Latest Databricks-Machine-Learning-Professional Mock Exam 😒 Open ✔ www.examdiscuss.com ️✔️ enter ✔ Databricks-Machine-Learning-Professional ️✔️ and obtain a free download 🚢Databricks-Machine-Learning-Professional Reliable Test Preparation
- Updated Databricks-Machine-Learning-Professional Test Cram 🌺 Databricks-Machine-Learning-Professional Exam Book ☘ Databricks-Machine-Learning-Professional Valid Braindumps Files 🥥 Search for ▶ Databricks-Machine-Learning-Professional ◀ and easily obtain a free download on 「 www.pdfvce.com 」 💷Databricks-Machine-Learning-Professional Pdf Version
- Exam Dumps Databricks-Machine-Learning-Professional Pdf 🖋 VCE Databricks-Machine-Learning-Professional Exam Simulator 🗼 Databricks-Machine-Learning-Professional Latest Dumps Free 🥨 Go to website 【 www.easy4engine.com 】 open and search for ✔ Databricks-Machine-Learning-Professional ️✔️ to download for free 🌯Databricks-Machine-Learning-Professional Latest Dumps Free
- Features of Databricks Databricks-Machine-Learning-Professional Desktop and Web-based Practice Exams 🔣 Immediately open 「 www.pdfvce.com 」 and search for 《 Databricks-Machine-Learning-Professional 》 to obtain a free download 🍤Study Databricks-Machine-Learning-Professional Group
- Test Databricks-Machine-Learning-Professional Valid 🥿 Test Databricks-Machine-Learning-Professional Valid 🌜 Databricks-Machine-Learning-Professional Test Assessment ⤵ { www.examcollectionpass.com } is best website to obtain ▶ Databricks-Machine-Learning-Professional ◀ for free download 📧Databricks-Machine-Learning-Professional Dumps PDF
- Databricks-Machine-Learning-Professional Test Pattern 🚚 Trustworthy Databricks-Machine-Learning-Professional Exam Torrent 🕢 New Databricks-Machine-Learning-Professional Test Sample 🈺 Search for ➠ Databricks-Machine-Learning-Professional 🠰 on ▶ www.pdfvce.com ◀ immediately to obtain a free download ☃Databricks-Machine-Learning-Professional Exam Book
- Databricks-Machine-Learning-Professional Dumps PDF 🙂 Databricks-Machine-Learning-Professional Test Pattern 🖋 Study Databricks-Machine-Learning-Professional Group 🧜 Open website ➡ www.exam4labs.com ️⬅️ and search for ⇛ Databricks-Machine-Learning-Professional ⇚ for free download 🦒Latest Databricks-Machine-Learning-Professional Cram Materials
- Databricks-Machine-Learning-Professional latest study torrent - Databricks-Machine-Learning-Professional practice download pdf 🙁 Immediately open 《 www.pdfvce.com 》 and search for ▶ Databricks-Machine-Learning-Professional ◀ to obtain a free download 🖋New Databricks-Machine-Learning-Professional Test Sample
- Databricks-Machine-Learning-Professional Dumps PDF 🔙 Databricks-Machine-Learning-Professional Test Assessment 🐫 Trustworthy Databricks-Machine-Learning-Professional Exam Torrent 🥑 Enter ⇛ www.practicevce.com ⇚ and search for “ Databricks-Machine-Learning-Professional ” to download for free 🎿Databricks-Machine-Learning-Professional Valid Braindumps Files
- onlyfans.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.grunnboek.nl, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, onlyfans.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! Download part of PracticeMaterial Databricks-Machine-Learning-Professional dumps for free: https://drive.google.com/open?id=1Qj_d0OFjytggLWu1O2I1iknmVDPF1dhU