Databricks-Machine-Learning-Professional最新資料 & Databricks-Machine-Learning-Professional的中関連問題

2026年PassTestの最新Databricks-Machine-Learning-Professional PDFダンプおよびDatabricks-Machine-Learning-Professional試験エンジンの無料共有:https://drive.google.com/open?id=1yqyO7-XTG_GbbsLx8-8Y0Hs9sFhCop5j
DatabricksのDatabricks-Machine-Learning-Professional認定試験に合格することはきっと君の職業生涯の輝い将来に大変役に立ちます。PassTestを選ぶなら、君がDatabricksのDatabricks-Machine-Learning-Professional認定試験に合格するということできっと喜んでいます。PassTestのDatabricksのDatabricks-Machine-Learning-Professional問題集を購入するなら、君がDatabricksのDatabricks-Machine-Learning-Professional認定試験に合格する率は100パーセントです。あなたはPassTestの学習教材を購入した後、私たちは一年間で無料更新サービスを提供することができます。
Databricks Databricks-Machine-Learning-Professional 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - 構造化ストリーミングではデータが順不同で到着する可能性があることを特定する
- モデル サービングがモデルのデプロイメントに 1 つの汎用クラスターをどのように使用するかを特定する
|
| トピック 2 | - 機械学習ワークフローでのフィーチャー ストア テーブルの作成、上書き、マージ、読み取り
- デルタ テーブル履歴の表示と以前のバージョンのデルタ テーブルの読み込み
|
| トピック 3 | - pyfunc MLflow フレーバーを使用する利点について説明する
- MLflow を使用してパラメーター、モデル、評価メトリクスを手動でログに記録する
|
| トピック 4 | - 表示された Webhook をトリガーするコード ブロックを特定する
- 基本的な目的とモデル レジストリとのユーザー インタラクションを説明する
|
| トピック 5 | - 更新されたモデルのパフォーマンスがより最近のデータで向上するかどうかをテストする
- 更新されたモデルを再トレーニングしてデプロイすることがドリフトの解決策となる可能性がある時期を特定する
|
| トピック 6 | - 事前計算されたバッチ予測をクエリすることのライブ サービングの利点を特定する
- ETL パイプラインの一般的な処理ツールとしての構造化ストリーミングについて説明する
|
| トピック 7 | - 他のユースケースのソリューションとしてパフォーマンスの低いデータ ストレージを特定する
- ストリーミング展開で複雑なビジネス ロジックを処理する必要がある理由を説明する
|
>> Databricks-Machine-Learning-Professional最新資料 <<
Databricks Databricks-Machine-Learning-Professional的中関連問題、Databricks-Machine-Learning-Professional受験準備
PassTestのDatabricks-Machine-Learning-Professional問題集を入手してから、非常に短い時間で試験に準備しても、あなたは順調に試験に合格することができます。PassTestの問題集には、実際の試験に出る可能性がある問題が全部含まれていますから、問題集における問題を覚える限り、簡単に試験に合格することができます。これは試験に合格する最速のショートカットです。仕事に忙しいから試験の準備をする時間はあまりないとしたら、絶対PassTestのDatabricks-Machine-Learning-Professional問題集を見逃すことはできないです。これはあなたがDatabricks-Machine-Learning-Professional試験に合格できる最善で、しかも唯一の方法ですから。
Databricks Certified Machine Learning Professional 認定 Databricks-Machine-Learning-Professional 試験問題 (Q26-Q31):
質問 # 26
A machine learning engineer is converting a Hyperopt-based hyperparameter tuning process from manual MLflow logging to MLflow Autologging. They notice that not all details and objects are automatically logged, and they will need to manually log some things. Which of the following will need to be manually logged when performing nested runs with Hyperopt and MLflow Autologging?
- A. Best trial evaluation metric
- B. Trial models
- C. Evaluation metrics
- D. Trial status
- E. Hyperparameter values
正解:A
解説:
When using MLflow Autologging with Hyperopt and nested runs, the best trial evaluation metric is not automatically logged and must be logged manually. Autologging captures trial-level details like hyperparameters and evaluation metrics, but summarizing and logging the overall best trial's result is a manual responsibility of the engineer.
質問 # 27
Why is Delta Lake time travel useful in ML pipelines?
- A. Smaller datasets
- B. Model tuning
- C. Reproducible training datasets
- D. Faster model inference
正解:C
解説:
Time travel allows training on exact historical datasets.
質問 # 28
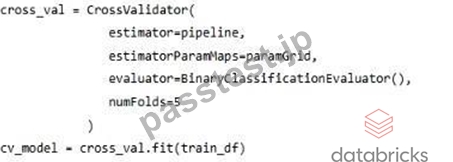
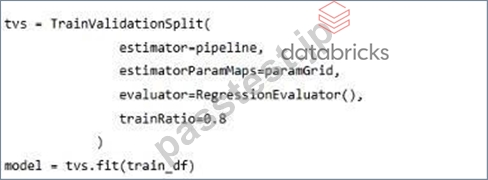
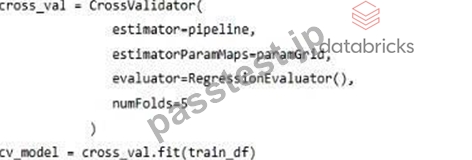
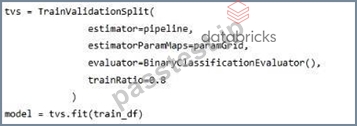
A Data Scientist is using Spark ML to train a model for detecting fraudulent transactions (1:
fraudulent, 0: non-fraudulent). To maximize the model's overall AUC (ROC) score, the Data Scientist wants to perform hyperparameter tuning on a Random Forest classifier. Due to budget constraints, the tuning process must be completed efficiently to avoid excessive compute costs.
Which approach will fulfill their needs?
正解:D
解説:
TrainValidationSplit evaluates each hyperparameter combination using a single train/validation split, which is significantly more compute-efficient than k-fold cross-validation. Using a BinaryClassificationEvaluator aligns directly with optimizing AUC (ROC) for a binary fraud detection task, making this approach well suited for maximizing model performance under budget and compute constraints.
質問 # 29
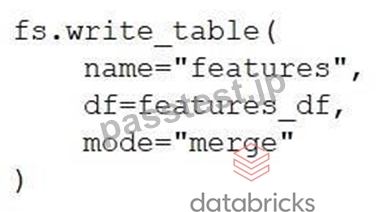
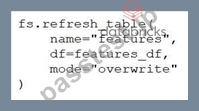
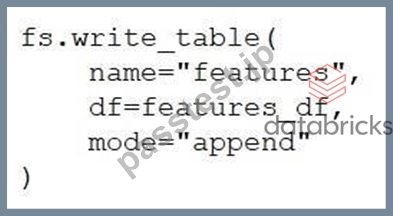
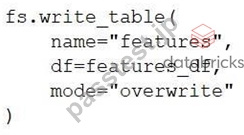
A data scientist has computed updated rows that contain new feature values for primary keys already stored in the Feature Store table features. The updated feature values are stored in the DataFrame features_df. They want to update the rows in features if the associated primary key is in features_df. If a row's primary key is not in features_df, they want the row to remain unchanged in features. Which code block can they use to perform this task using the Feature Store Client fs?
正解:A
解説:
To update existing rows based on primary keys while leaving other rows unchanged, the correct mode to use with fs.write_table() is "merge". This performs an upsert operation - updating rows where keys match and keeping others intact - making it ideal for updating feature values in a Feature Store table.
質問 # 30
Which MLflow operation can be used to log a plot that was generated during an MLflow run?
- A. mlflow.log_visualization
- B. None of these operations can accomplish the task.
- C. mlflow.log_metric
- D. mlflow.log_figure
正解:D
解説:
The mlflow.log_figure() operation is used to log plots or figures generated during an MLflow run. It takes a Matplotlib, Plotly, or similar figure object and saves it as an artifact in the MLflow tracking server, enabling visualization and later retrieval from the MLflow UI.
質問 # 31
......
多くの人々は高い難度のDatabricks認証Databricks-Machine-Learning-Professional試験に合格するのは専門の知識が必要だと思います。それは確かにそうですが、その知識を身につけることは難しくないとといわれています。Databricks業界ではさらに強くなるために強い専門知識が必要です。
Databricks-Machine-Learning-Professional的中関連問題: https://www.passtest.jp/Databricks/Databricks-Machine-Learning-Professional-shiken.html
- 試験の準備方法-認定するDatabricks-Machine-Learning-Professional最新資料試験-高品質なDatabricks-Machine-Learning-Professional的中関連問題 📟 { www.jpexam.com }には無料の[ Databricks-Machine-Learning-Professional ]問題集がありますDatabricks-Machine-Learning-Professional認定試験
- 実際的なDatabricks-Machine-Learning-Professional最新資料 - 合格スムーズDatabricks-Machine-Learning-Professional的中関連問題 | 検証するDatabricks-Machine-Learning-Professional受験準備 🐯 ➽ www.goshiken.com 🢪にて限定無料の➽ Databricks-Machine-Learning-Professional 🢪問題集をダウンロードせよDatabricks-Machine-Learning-Professional練習問題集
- Databricks-Machine-Learning-Professional問題数 🐘 Databricks-Machine-Learning-Professional無料サンプル 🐲 Databricks-Machine-Learning-Professional問題数 📔 時間限定無料で使える「 Databricks-Machine-Learning-Professional 」の試験問題は➥ www.it-passports.com 🡄サイトで検索Databricks-Machine-Learning-Professional模擬問題
- Databricks Databricks-Machine-Learning-Professional認定試験に対する素晴らしい教育資料 🍄 ➽ www.goshiken.com 🢪を開いて➤ Databricks-Machine-Learning-Professional ⮘を検索し、試験資料を無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional専門知識
- Databricks-Machine-Learning-Professional問題集無料 😨 Databricks-Machine-Learning-Professional無料試験 ➕ Databricks-Machine-Learning-Professional的中関連問題 🧛 ウェブサイト( www.jptestking.com )から⏩ Databricks-Machine-Learning-Professional ⏪を開いて検索し、無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional日本語版参考資料
- 最高のDatabricks Databricks-Machine-Learning-Professional最新資料 - 合格スムーズDatabricks-Machine-Learning-Professional的中関連問題 | 大人気Databricks-Machine-Learning-Professional受験準備 👨 ➤ Databricks-Machine-Learning-Professional ⮘を無料でダウンロード⇛ www.goshiken.com ⇚で検索するだけDatabricks-Machine-Learning-Professional日本語版参考資料
- Databricks-Machine-Learning-Professional的中関連問題 🐒 Databricks-Machine-Learning-Professional問題集無料 🔄 Databricks-Machine-Learning-Professional最新受験攻略 🌵 [ www.mogiexam.com ]は、「 Databricks-Machine-Learning-Professional 」を無料でダウンロードするのに最適なサイトですDatabricks-Machine-Learning-Professional最新受験攻略
- 実際的なDatabricks-Machine-Learning-Professional最新資料 - 合格スムーズDatabricks-Machine-Learning-Professional的中関連問題 | 検証するDatabricks-Machine-Learning-Professional受験準備 🍖 ➠ www.goshiken.com 🠰から➽ Databricks-Machine-Learning-Professional 🢪を検索して、試験資料を無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional模擬問題
- 完璧Databricks-Machine-Learning-Professional|便利なDatabricks-Machine-Learning-Professional最新資料試験|試験の準備方法Databricks Certified Machine Learning Professional的中関連問題 😛 時間限定無料で使える➽ Databricks-Machine-Learning-Professional 🢪の試験問題は[ www.mogiexam.com ]サイトで検索Databricks-Machine-Learning-Professional日本語版参考資料
- Databricks-Machine-Learning-Professional的中合格問題集 💱 Databricks-Machine-Learning-Professional資格認定 🏰 Databricks-Machine-Learning-Professional無料サンプル 🥭 ➽ www.goshiken.com 🢪サイトで➡ Databricks-Machine-Learning-Professional ️⬅️の最新問題が使えるDatabricks-Machine-Learning-Professional最新受験攻略
- Databricks-Machine-Learning-Professional最新資料はDatabricks Certified Machine Learning Professionalに合格するのがより便利になります 🥢 ✔ www.topexam.jp ️✔️を入力して「 Databricks-Machine-Learning-Professional 」を検索し、無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional無料試験
- www.stes.tyc.edu.tw, mayagriffiths253.blogspot.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, fortunetelleroracle.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! PassTest Databricks-Machine-Learning-Professionalダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1yqyO7-XTG_GbbsLx8-8Y0Hs9sFhCop5j