2026 Die neuesten Pass4Test Databricks-Certified-Professional-Data-Engineer PDF-Versionen Prüfungsfragen und Databricks-Certified-Professional-Data-Engineer Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1BHQuMoi9gp2zvwildRAZmBr7mHkJqhr7
Tun Sie, was Sie gesagt haben, was Beginn des Erfolgs ist. Weil Sie die schwierige IT-Zertifizierungsprüfung ablegen wollen, sollen Sie sich bemühen, um das Zertifikat zu bekommen. Die Fragenkataloge zur Databricks Databricks-Certified-Professional-Data-Engineer Prüfung von Pass4Test sind sehr gut. Mit Ihr können Sie Ihren Erfolg ganz leicht erzielen. Sie sind ganz zuverlässig. Ich glaube, Sie werden die Prüfung 100% bestehen.
| Section | Objectives |
|---|---|
| Topic 1: Data Ingestion and Transformation | - Handle batch and streaming data pipelines - Ingest data using Apache Spark and Databricks - Transform and clean datasets using Spark SQL and DataFrame APIs |
| Topic 2: Data Modeling and Storage | - Design scalable data lakehouse architectures - Schema evolution and data partitioning strategies - Delta Lake table design and optimization |
| Topic 3: Production Pipelines and Orchestration | - Build and manage workflows using Databricks Jobs - Automate ETL pipelines and scheduling - Pipeline reliability and fault tolerance |
| Topic 4: Security, Governance, Monitoring, and Optimization | - Implement Unity Catalog governance and access control - Monitor and optimize Spark workloads - Cost optimization and performance tuning |
>> Databricks-Certified-Professional-Data-Engineer Prüfungsfrage <<
Pass4Test bietet Ihnen die neuesten Schulungsunterlagen zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung. Die fleißigen IT-Experten von Pass4Test aktualisieren ständig Schulungsunterlagen durch ihre eigene Kompetenz und Erfahrung, so dass die IT-Fachleute die Prüfung mühlos bestehen können. Das Databricks Databricks-Certified-Professional-Data-Engineer Zertifikat stellt eine immer wichtigere Stelle in der IT-Branche dar. Und immer mehr Leute haben sich an dieser Prüfung beteiligt. Und viele davon benutzen unsere Produkte von Pass4Test und haben die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung bestanden. Die Feedbacks von diesen Leute haben bewiesen, dass unsere Produkte von Pass4Test eher zuverlässig sind.
85. Frage
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs UI. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.
What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
Antwort: D
Begründung:
This is the correct answer because it is the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data. Notebook permissions are used to control access to notebooks in Databricks workspaces. There are four types of notebook permissions: Can Manage, Can Edit, Can Run, and Can Read. Can Manage allows full control over the notebook, including editing, running, deleting, exporting, and changing permissions. Can Edit allows modifying and running the notebook, but not changing permissions or deleting it. Can Run allows executing commands in an existing cluster attached to the notebook, but not modifying or exporting it. Can Read allows viewing the notebook content, but not running or modifying it. In this case, granting Can Read permission to the user will allow them to review the production logic in the notebook without allowing them to make any changes to it or run any commands that may affect production data. Verified Reference: [Databricks Certified Data Engineer Professional], under "Databricks Workspace" section; Databricks Documentation, under "Notebook permissions" section.
86. Frage
A data engineer is designing an append-only pipeline that needs to handle both batch and streaming data in Delta Lake. The team wants to ensure that the streaming component can efficiently track which data has already been processed.
Which configuration should be set to enable this?
Antwort: A
Begründung:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
When working with Delta Lake streaming ingestion, checkpointing is critical for maintaining fault tolerance and ensuring exactly-once data processing semantics.
The checkpointLocation parameter defines the directory where Spark Structured Streaming stores progress information, offsets, and metadata. This allows the engine to resume processing from the last committed offset without reprocessing previously ingested data.
Without checkpointing, each stream restart would reprocess all data, leading to duplicates. Parameters like partitionBy or schema options (mergeSchema / overwriteSchema) affect table structure, not data lineage tracking. Therefore, the correct and required configuration for efficient streaming state management is checkpointLocation.
87. Frage
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
Antwort: A
Begründung:
Comprehensive and Detailed Explanation from Databricks Documentation:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration. Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
88. Frage
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFramedf. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFramedfhas the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: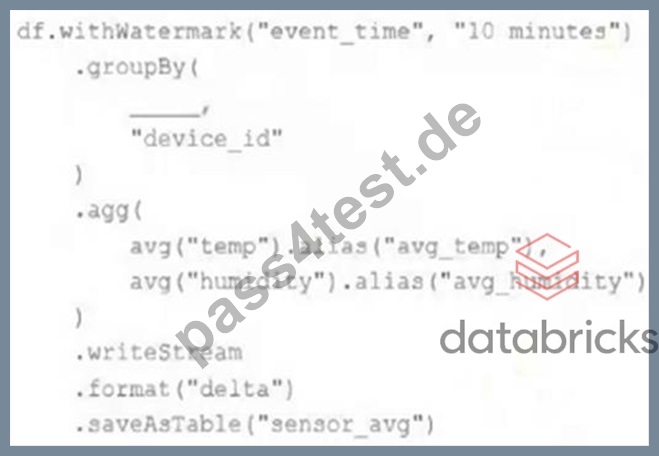
Choose the response that correctly fills in the blank within the code block to complete this task.
Antwort: A
Begründung:
Explanation
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five-minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window.
The alias function is used to rename the struct column as "time". Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under
"WINDOW" section.
89. Frage
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
Antwort: A
Begründung:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
Reference:
Databricks documentation on using SQL views in Delta Lake: https://docs.databricks.com/delta/quick-start.html#sql-views
90. Frage
......
Als Anbieter des Databricks Databricks-Certified-Professional-Data-Engineer (Databricks Certified Professional Data Engineer Exam) IT-Prüfungskompendium bieten IT-Experten von Pass4Test ständig die Produkte von guter Qualität. Sie bieten den Kunden kostenlosen Online-Service rund um die Uhr und aktualisieren Databricks Databricks-Certified-Professional-Data-Engineer (Databricks Certified Professional Data Engineer Exam) Prüfungsfragen und Antworten auch am schnellsten.
Databricks-Certified-Professional-Data-Engineer Lerntipps: https://www.pass4test.de/Databricks-Certified-Professional-Data-Engineer.html
Laden Sie die neuesten Pass4Test Databricks-Certified-Professional-Data-Engineer PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1BHQuMoi9gp2zvwildRAZmBr7mHkJqhr7