Choosing our DP-800 exam quiz will be a wise decision that you make, because this decision may have a great impact in your future development. Having the certificate may be something you have always dreamed of, because it can prove that you have certain strength. Our DP-800 exam questions can provide you with services with pretty quality and help you obtain a certificate. Our DP-800 Learning Materials are made after many years of practical efforts and their quality can withstand the test of practice. And you will obtain the DP-800 certification just for our DP-800 study guide.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Developing AI-Enabled Database Solutions |
| Exam Number: | DP-800 |
| Exam Format: | Multiple choice, Active screen, Drag and drop, Multiple select, Case studies |
| Available Languages: | German, Japanese, Spanish, Korean, French, Chinese (Simplified), English, Portuguese (Brazil) |
| Real Exam Qty: | 40-60 |
| Certificate Validity Period: | 1 year (renewable annually via free online assessment) |
| Exam Duration: | 100 minutes |
| Passing Score: | 700 (on a scale of 1-1000) |
| Exam Price: | $165 USD |
| Recommended Training: | Microsoft Learn DP-800 Learning Path |
| Exam Registration: | Pearson VUE Registration |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE test centers |
| Pre Condition: | No mandatory prerequisites; recommended experience: T-SQL development, SQL Server/Azure SQL, CI/CD practices, basic AI concepts |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/dp-800 |
Often candidates fail the DP-800 exam due to the fact that they do not know the tactics of attempting the Developing AI-Enabled Database Solutions (DP-800) exam in an ideal way. The decisive part is often effective time management. Some Microsoft DP-800 Exam Questions demand more attention than others, which disturbs the time allotted to each topic. The best way to counter them is to use an updated DP-800 Dumps.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 20
You have an Azure SQL database that contains a table named Table1. Table1 contains 25,000,000 rows of data and a datetime2 column named DateKey. The data in Table1 spans the years 2020 through 2021.
You need to partition the data in Table1 by year. The solution must minimize how long it takes to rebuild or reindex the table.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Partition range # RANGE RIGHT
Boundary values # ' 2020-01-01 00:00:00 ' , ' 2021-01-01 00:00:00 '
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents: = The correct configuration is to use RANGE RIGHT with boundary values at the start of each year:
CREATE PARTITION FUNCTION PartitionByYear (datetime2)
AS RANGE RIGHT
FOR VALUES (
' 2020-01-01 00:00:00 ' ,
' 2021-01-01 00:00:00 '
);
Microsoft documents that with RANGE RIGHT, each boundary value belongs to the partition on its right. For date-based partitioning, this is the natural pattern because a boundary such as 2021-01-01 becomes the lower boundary of the 2021 partition.
With these boundaries, the resulting ranges are effectively:
Partition 1: dates before 2020-01-01
Partition 2: 2020-01-01 through before 2021-01-01
Partition 3: 2021-01-01 and later
This cleanly separates the 2020 and 2021 data into year-aligned partitions. Microsoft specifically recommends RANGE RIGHT for date-based boundaries because the first day of a period remains in the same partition as the rest of that period.
The other boundary choices are incorrect or less appropriate:
Using year-end timestamps with RANGE LEFT is more cumbersome and can be sensitive to datetime2 precision.
Monthly boundaries would partition by month, not year.
Including 2019 and a 2021-12-31 23:59:59 boundary creates unnecessary partitions and is not the cleanest year-based design.
Therefore:
First dropdown: RANGE RIGHT
Second dropdown: ' 2020-01-01 00:00:00 ' , ' 2021-01-01 00:00:00 '
NEW QUESTION # 21
You have an Azure SQL database that contains the following tables and columns.
Embeddings in the NotesEnbeddings and DescriptionEabeddings tables have been generated from values in the Description and notes columns of the Articles table by using different chunk sizes.
You need to perform approximate nearest neighbor (ANN) queries across both embedding tables. The solution must minimize the impact of using different chunk sizes.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.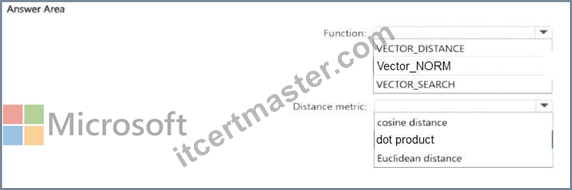
Answer:
Explanation:
Explanation:
The correct function is VECTOR_SEARCH because the requirement is to perform approximate nearest neighbor (ANN) queries. Microsoft's SQL documentation states that VECTOR_SEARCH is the function used for vector similarity search, and that an ANN index is used only with VECTOR_SEARCH when a compatible vector index exists on the target column. By contrast, VECTOR_DISTANCE calculates an exact distance and does not use a vector index for ANN retrieval.
The correct distance metric is cosine distance. Microsoft documents that VECTOR_SEARCH supports cosine, dot, and euclidean metrics, and Microsoft guidance specifically notes that cosine similarity is commonly used for text embeddings. It also states that retrieval of the most similar texts to a given text typically functions better with cosine similarity, and that Azure OpenAI embeddings rely on cosine similarity to compute similarity between a query and documents. Since both NotesEmbeddings and DescriptionEmbeddings are text-derived embeddings and the goal is to minimize the impact of different chunk sizes, cosine is the best choice because it compares direction/angle rather than being as sensitive to vector magnitude as Euclidean distance.
NEW QUESTION # 22
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders. dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.Orders.
Solution: Identify the partition scheme for the oldest month, and then run the following Transact-SQL statement:
SQL
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME {partition_scheme_name};
Does this meet the goal?
Answer: B
NEW QUESTION # 23
You are creating a table that will store customer profiles.
You have the following Transact-SQL code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection Is worth one point.
Answer:
Explanation:
Explanation:
The schema meets the security requirements for PII data. # Yes
Administrators of the Azure SQL server can see all the rows in dbo.CustomerProfiles when they use an application. # No The masking rules will apply even when row-level security (RLS) filters out rows. # No The first statement is Yes because the design combines two relevant SQL security controls for personally identifiable information: Dynamic Data Masking (DDM) on sensitive columns such as FullName, EmailAddress, and PhoneNumber, and Row-Level Security (RLS) to restrict which rows a user can access based on RegionCode. Microsoft documents that DDM limits sensitive data exposure for nonprivileged users, while RLS restricts row access according to the user executing the query. Together, these are valid and appropriate controls for protecting PII in Azure SQL Database.
The second statement is No. Administrative users can view unmasked data because administrative roles effectively have CONTROL, which includes UNMASK. However, that does not mean they automatically see all rows through the application query path defined by the RLS policy. The security policy filters rows based on SUSER_SNAME() and matching RegionCode, so row visibility is governed by the predicate unless the policy is altered or bypassed administratively. DDM and RLS solve different problems: DDM affects how returned values are shown, while RLS affects which rows are returned at all.
The third statement is No because masking only applies to data that is actually returned in the query result set.
Microsoft describes DDM as hiding sensitive data in the result set of a query. If RLS filters a row out, that row is not returned, so there is nothing left for masking to act on. In other words, RLS eliminates inaccessible rows first from the user's perspective, and DDM masks sensitive column values only on rows the user is allowed to see.
NEW QUESTION # 24
You have an Azure SQL database that supports an AI-driven product search API.
You need to identify the top CPU-consuming queries from the last two hours by using Query Store data. The solution must aggregate CPU consumption across executions and return only the top 15 query hashes.
How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all.
NOTE: Each correct selection is worth one point.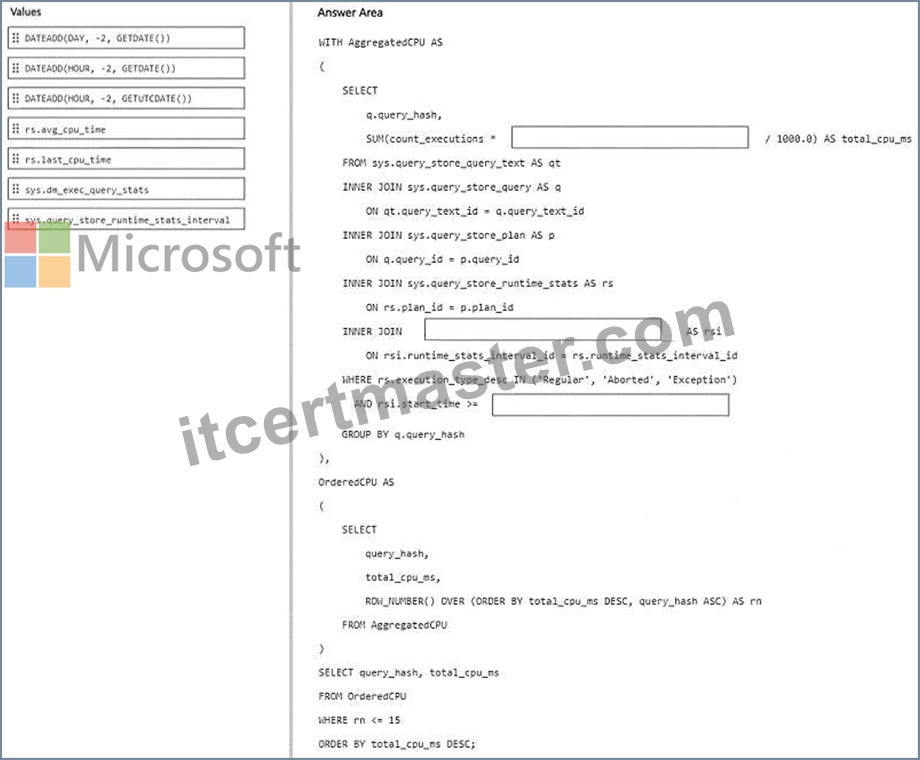
Answer:
Explanation: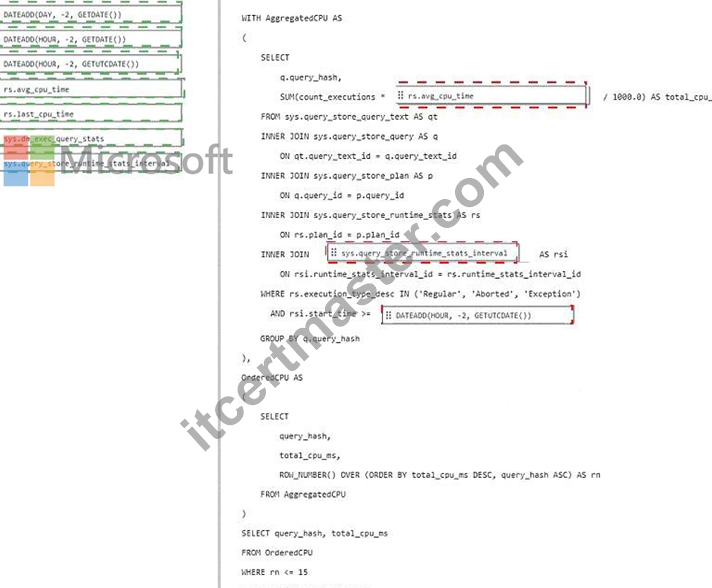
Explanation:
Verified Answer : =
* CPU aggregation expression # rs.avg_cpu_time
* Runtime interval source # sys.query_store_runtime_stats_interval
* Last two hours filter # DATEADD(HOUR, -2, GETUTCDATE())
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = The first correct selection is rs.avg_cpu_time . Query Store stores CPU statistics per aggregation interval, and Microsoft documents avg_cpu_time as the average CPU time per execution, in microseconds . To calculate total CPU consumption across all executions, multiply count_executions by avg_cpu_time , then divide by
1000.0 to convert microseconds to milliseconds:
SUM(count_executions * rs.avg_cpu_time / 1000.0)
This is the exact pattern Microsoft uses in its documented query for identifying the top 15 CPU-consuming queries by query hash .
The second selection is sys.query_store_runtime_stats_interval because sys.query_store_runtime_stats.
runtime_stats_interval_id is a foreign key to this view. The interval view provides start_time and end_time , allowing Query Store data to be limited to the required time window.
The third selection is DATEADD(HOUR, -2, GETUTCDATE()) . Microsoft's own Azure SQL performance- monitoring example for the last two hours uses exactly:
rsi.start_time > = DATEADD(HOUR, -2, GETUTCDATE())
and then ranks by total CPU descending to return the top 15 query hashes.
Final drag-and-drop selections:
* First target: rs.avg_cpu_time
* Second target: sys.query_store_runtime_stats_interval
* Third target: DATEADD(HOUR, -2, GETUTCDATE())
NEW QUESTION # 25
......
DP-800 Exam Cram Review: https://www.itcertmaster.com/DP-800.html