CompTIA DY0-001 Latest Exam Papers - DY0-001 Latest Questions

BTW, DOWNLOAD part of Pass4SureQuiz DY0-001 dumps from Cloud Storage: https://drive.google.com/open?id=1akcI6G_-3cAT7OcWGLVQG8huQF8uMvBl
Do you often envy the colleagues around you can successfully move to a larger company to achieve the value of life? Are you often wondering why your classmate, who has scores similar to yours, can receive a large company offer after graduation and you are rejected? In fact, what you lack is not hard work nor luck, but DY0-001 Guide question. With DY0-001 question torrent, you will suddenly find the joy of learning and you will pass the professional qualification exam very easily.
| Section | Weight | Objectives |
|---|
| Topic 1: Operations and Processes | 22% | - MLOps & Deployment
- 1. Workflow models, Version control, Clean code, Unit tests
- 2. CI/CD, Model deployment, Container orchestration
- 3. Deployment environments (Cloud, Hybrid, Edge, On-premises)
- Business & Data Lifecycle
- 1. Data types (Synthetic, Public data)
- 2. Data wrangling, Cleaning, Imputation, Ground truth labeling
- 3. Compliance, KPIs, Requirements gathering
- 4. Ingestion pipelines, Streaming, Batching, Data lineage
|
| Topic 2: Mathematics and Statistics | 17% | - Statistical Methods and Concepts
- 1. Distributions, Skewness, Kurtosis
- 2. Gini index, Entropy, Information gain
- 3. Central limit theorem, Law of large numbers
- 4. Correlation coefficients (Pearson, Spearman)
- 5. Regression performance metrics (R2, RMSE, F statistic)
- 6. Confidence intervals, p-value, Type I and Type II errors
- 7. t-tests, Chi-squared test, ANOVA, Hypothesis testing
- 8. Confusion matrix and Classifier metrics (Accuracy, Recall, Precision, F1, MCC)
- Applied Mathematics
- 1. Probability Density Function (PDF), PMF, CDF
- 2. Linear Algebra
- 3. Calculus
|
| Topic 3: Machine Learning | 24% | - Deep Learning & Unsupervised Learning
- 1. Backpropagation, Deep-learning frameworks, Optimizers
- 2. Artificial Neural Networks (ANN), Dropout, Batch Normalization
- 3. Clustering (K-Means, DBSCAN), Dimensionality Reduction (PCA, t-SNE)
- Supervised & Tree-based Learning
- 1. Linear/Logistic Regression, KNN, Naive Bayes, Association rules
- 2. Decision Trees, Random Forest, Boosting, Bagging
- Foundational Concepts
- 1. Data leakage prevention
- 2. Cross-validation, Ensemble models, Hyperparameter tuning
- 3. Loss functions, Bias-variance tradeoff, Regularization
|
| Topic 4: Modeling, Analysis, and Outcomes | 24% | - Data Analysis Techniques
- 1. Exploratory Data Analysis (EDA)
- 2. Univariate and Multivariate Analysis
- 3. Visualization (Box plots, Scatter plots, Heatmaps, Sankey diagrams)
- Model Lifecycle
- 1. Time Series, Longitudinal Studies, Causal Inference
- 2. Model Selection and Requirements Validation
- 3. Performance Evaluation and Benchmarking
- Feature Engineering & Transformation
- 1. Handling missingness and Oversampling
- 2. Feature type identification
- 3. Data transformation (Geocoding, Scaling, Standardization)
|
| Topic 5: Specialized Applications of Data Science | 13% | - Specialized Domains
- 1. Computer Vision
- 2. Natural Language Processing (NLP)
- 3. Anomaly Detection
|
>> CompTIA DY0-001 Latest Exam Papers <<
Pass Guaranteed 2026 DY0-001: CompTIA DataAI Certification Exam –High Pass-Rate Latest Exam Papers
The CompTIA DataAI Certification Exam DY0-001 exam dumps are top-rated and real CompTIA DataAI Certification Exam DY0-001 practice questions that will enable you to pass the final CompTIA DataAI Certification Exam DY0-001 exam easily. With the CompTIA DataAI Certification Exam Exam Questions you can make this task simple, quick, and instant. Using the CompTIA DataAI Certification Exam DY0-001 can help you success in your exam. Pass4SureQuiz offers reliable guide files and reliable exam guide materials for 365 days free updates.
CompTIA DataAI Certification Exam Sample Questions (Q69-Q74):
NEW QUESTION # 69
A data analyst is examining the correlation matrix of a new data set to identify issues that could adversely impact model performance. Which of the following is the analyst most likely checking for?
- A. Overfitting
- B. Oversampling
- C. Undersampling
- D. Multicollinearity
Answer: D
Explanation:
# Multicollinearity occurs when independent variables are highly correlated with each other. This can distort coefficient estimates and reduce model interpretability. A correlation matrix is the primary tool used to detect it.
Why the other options are incorrect:
* A & C: Under/oversampling relate to class imbalance, not variable correlation.
* D: Overfitting is related to model complexity, not directly observable via a correlation matrix.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"Correlation matrices are used to detect multicollinearity - high correlations among predictors that may destabilize models."
NEW QUESTION # 70
Which of the following techniques enables automation and iteration of code releases?
- A. Code isolation
- B. CI/CD
- C. Virtualization
- D. Markdown
Answer: B
Explanation:
# CI/CD (Continuous Integration / Continuous Deployment) is a DevOps methodology that automates the building, testing, and deployment of code. It allows teams to iteratively release updates and improvements in a reliable and scalable manner.
Why the other options are incorrect:
* A: Virtualization provides environment emulation but doesn't manage code releases.
* B: Markdown is a documentation tool - unrelated to deployment automation.
* C: Code isolation refers to modular programming, not automation pipelines.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 5.3:"CI/CD pipelines streamline model deployment through automation, allowing continuous integration and delivery of updates."
* DevOps for Data Science, Chapter 4:"CI/CD supports fast and reliable code iterations by automatically testing and deploying to production environments."
-
NEW QUESTION # 71
Which of the following does k represent in the k-means model?
- A. Number of model tests
- B. Number of data splits
- C. Distance between features
- D. Number of clusters
Answer: D
Explanation:
# In k-means clustering, k represents the number of clusters that the algorithm will attempt to form. The algorithm partitions the dataset into k distinct, non-overlapping clusters based on feature similarity. Each cluster has a centroid, and the algorithm aims to minimize the intra-cluster variance.
Why the other options are incorrect:
* A: Number of tests is unrelated to the k-means algorithm.
* B: Data splits refer to cross-validation or train/test splits, not k in k-means.
* D: Distance between features is computed during clustering but is not what "k" represents.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.2:"In k-means clustering, k denotes the number of clusters into which the dataset will be partitioned."
* Introduction to Machine Learning, Chapter 6:"The 'k' in k-means specifies how many groupings the algorithm will seek to discover based on proximity in feature space."
-
NEW QUESTION # 72
A statistician notices gaps in data associated with age-related illnesses and wants to further aggregate these observations. Which of the following is the best technique to achieve this goal?
- A. Label encoding
- B. Binning
- C. Imputing
- D. Linearization
Answer: B
Explanation:
Binning groups continuous age values into discrete intervals (e.g., age ranges), filling gaps by aggregating observations into broader categories. This directly addresses uneven or sparse age data by creating consistent age groups.
NEW QUESTION # 73
A data scientist is developing a model to predict the outcome of a vote for a national mascot. The choice is between tigers and lions. The full data set represents feedback from individuals representing 17 professions and 12 different locations. The following rank aggregation represents 80% of the data set:
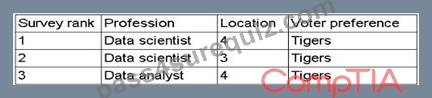
(Screenshot shows survey rankings for just two professions and a few locations, all voting for "Tigers") Which of the following is the most likely concern about the model's ability to predict the outcome of the vote?
- A. Extrapolated data
- B. Interpolated data
- C. In-sample data
- D. Out-of-sample data
Answer: A
Explanation:
# Extrapolated data refers to making predictions about data points that fall outside the observed range or distribution. Since the sample data (80%) is heavily skewed toward a small subset of professions and locations, predicting results for the remaining, unrepresented professions and regions involves extrapolation.
Why the other options are incorrect:
* A: Interpolation occurs within the bounds of observed data - not the issue here.
* C: In-sample data refers to training data, which is overrepresented in this case.
* D: Out-of-sample data is a concern in generalization but extrapolation is more specific here.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"Extrapolation introduces risk when models are used outside the range of data they were trained on, especially if certain subgroups are underrepresented."
-
NEW QUESTION # 74
......
CompTIA Certification exams are essential to move ahead, because being certified professional a well-off career would be in your hand. CompTIA is among one of the strong certification provider, who provides massively rewarding pathways with a plenty of work opportunities to you and around the world. But the mystery is quite challenging to pass DY0-001 exam unless you have an updated exam material. Thousands of people attempt DY0-001 Exam but majorly fails despite of having good professional experience, because only practice and knowledge isn’t enough a person needs to go through the exam material designed by CompTIA, otherwise there is no escape out of reading. Well, you have landed at the right place; Pass4SureQuiz offers your experts designed material which will gauge your understanding of various topics.
DY0-001 Latest Questions: https://www.pass4surequiz.com/DY0-001-exam-quiz.html
- Pass Guaranteed CompTIA - Unparalleled DY0-001 - CompTIA DataAI Certification Exam Latest Exam Papers 🔀 Copy URL [ www.vce4dumps.com ] open and search for ☀ DY0-001 ️☀️ to download for free 🧾DY0-001 Test Dump
- CompTIA - DY0-001 - Reliable CompTIA DataAI Certification Exam Latest Exam Papers 👺 Open 「 www.pdfvce.com 」 enter ▷ DY0-001 ◁ and obtain a free download 🐻Study DY0-001 Materials
- DY0-001 Reliable Exam Simulations 👡 DY0-001 Exam Tests 👤 DY0-001 Exam Tests 🔑 The page for free download of ▶ DY0-001 ◀ on “ www.dumpsquestion.com ” will open immediately 🏐Latest DY0-001 Demo
- CompTIA - DY0-001 - Reliable CompTIA DataAI Certification Exam Latest Exam Papers 🦩 Open { www.pdfvce.com } enter 《 DY0-001 》 and obtain a free download ⌨Valid DY0-001 Practice Materials
- DY0-001 Associate Level Exam 🎃 DY0-001 Valid Braindumps Questions 🎣 DY0-001 Exam Tests 🐈 The page for free download of ▷ DY0-001 ◁ on [ www.prep4sures.top ] will open immediately 🎮Study DY0-001 Materials
- Quiz CompTIA - DY0-001 - Fantastic CompTIA DataAI Certification Exam Latest Exam Papers 🆓 Open website ⏩ www.pdfvce.com ⏪ and search for ( DY0-001 ) for free download 📸Valid DY0-001 Practice Materials
- Valid DY0-001 Test Sample 😓 DY0-001 Exam Tests 📍 DY0-001 New Real Test 🦞 Search on 【 www.pass4test.com 】 for ✔ DY0-001 ️✔️ to obtain exam materials for free download 🎧Updated DY0-001 Demo
- Top DY0-001 Exam Dumps 🕙 Top DY0-001 Exam Dumps 📒 DY0-001 Associate Level Exam 📿 Immediately open “ www.pdfvce.com ” and search for 「 DY0-001 」 to obtain a free download ⬆Latest Real DY0-001 Exam
- Quiz CompTIA - DY0-001 - Fantastic CompTIA DataAI Certification Exam Latest Exam Papers 🔀 Immediately open ➽ www.easy4engine.com 🢪 and search for ⇛ DY0-001 ⇚ to obtain a free download ✳DY0-001 Actual Exam
- CompTIA Valid DY0-001 Latest Exam Papers – Pass DY0-001 First Attempt 🌾 Search for ⏩ DY0-001 ⏪ and obtain a free download on { www.pdfvce.com } 🏪Reliable DY0-001 Braindumps Questions
- Valid DY0-001 Test Sample 🕔 Top DY0-001 Exam Dumps 🚦 Valid DY0-001 Practice Materials 👶 Search on ➥ www.pdfdumps.com 🡄 for ⇛ DY0-001 ⇚ to obtain exam materials for free download 🎐Updated DY0-001 Demo
- disqus.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.impactio.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, app.parler.com, Disposable vapes
What's more, part of that Pass4SureQuiz DY0-001 dumps now are free: https://drive.google.com/open?id=1akcI6G_-3cAT7OcWGLVQG8huQF8uMvBl