DOWNLOAD the newest ExamBoosts DOP-C02 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1sEJWMf4RuRfX5uUWzwJ7mUTPtheZewXc
The language in our DOP-C02 test guide is easy to understand that will make any learner without any learning disabilities, whether you are a student or a in-service staff, whether you are a novice or an experienced staff who has abundant experience for many years. It should be a great wonderful idea to choose our DOP-C02 Guide Torrent for sailing through the difficult test. On the whole, nothing is unbelievable, to do something meaningful from now, success will not wait for a hesitate person, go and purchase!
| Section | Weight | Objectives |
|---|---|---|
| Security and Compliance Automation | 13% | - Security automation in CI/CD and infrastructure
|
| Monitoring and Logging | 15% | - Observability and metrics
|
| SDLC Automation | 22% | - CI/CD pipeline design and implementation
|
| Incident and Event Management | 18% | - Operational response and recovery
|
| Resilient Cloud Solutions | 15% | - High availability and fault tolerance design
|
| Configuration Management and Infrastructure as Code | 17% | - Infrastructure provisioning and automation
|
In this way, the Amazon DOP-C02 certified professionals can not only validate their skills and knowledge level but also put their careers on the right track. By doing this you can achieve your career objectives. To avail of all these benefits you need to pass the AWS Certified DevOps Engineer - Professional (DOP-C02) exam which is a difficult exam that demands firm commitment and complete Amazon DOP-C02 exam questions preparation.
NEW QUESTION # 319
A company needs to implement failover for its application. The application includes an Amazon CloudFront distribution and a public Application Load Balancer (ALB) in an AWS Region. The company has configured the ALB as the default origin for the distribution.
After some recent application outages, the company wants a zero-second RTO. The company deploys the application to a secondary Region in a warm standby configuration. A DevOps engineer needs to automate the failover of the application to the secondary Region so that HTTP GET requests meet the desired R TO.
Which solution will meet these requirements?
Answer: B
Explanation:
Explanation
To implement failover for the application to the secondary Region so that HTTP GET requests meet the desired RTO, the DevOps engineer should use the following solution:
Create a new origin on the distribution for the secondary ALB. A CloudFront origin is the source of the content that CloudFront delivers to viewers. By creating a new origin for the secondary ALB, the DevOps engineer can configure CloudFront to route traffic to the secondary Region when the primary Region is unavailable1 Create a new origin group. Set the original ALB as the primary origin. Configure the origin group to fail over for HTTP 5xx status codes. An origin group is a logical grouping of two origins: a primary origin and a secondary origin. By creating an origin group, the DevOps engineer can specify which origin CloudFront should use as a fallback when the primary origin fails. The DevOps engineer can also define which HTTP status codes should trigger a failover from the primary origin to the secondary origin. By setting the original ALB as the primary origin and configuring the origin group to fail over for HTTP
5xx status codes, the DevOps engineer can ensure that CloudFront will switch to the secondary ALB when the primary ALB returns server errors2 Update the default behavior to use the origin group. A behavior is a set of rules that CloudFront applies when it receives requests for specific URLs or file types. The default behavior applies to all requests that do not match any other behaviors. By updating the default behavior to use the origin group, the DevOps engineer can enable failover routing for all requests that are sent to the distribution3 This solution will meet the requirements because it will automate the failover of the application to the secondary Region with zero-second RTO. When CloudFront receives an HTTP GET request, it will first try to route it to the primary ALB in the primary Region. If the primary ALB is healthy and returns a successful response, CloudFront will deliver it to the viewer. If the primary ALB is unhealthy or returns an HTTP 5xx status code, CloudFront will automatically route the request to the secondary ALB in the secondary Region and deliver its response to the viewer.
The other options are not correct because they either do not provide zero-second RTO or do not work as expected. Creating a second CloudFront distribution that has the secondary ALB as the default origin and creating Amazon Route 53 alias records that have a failover policy is not a good option because it will introduce additional latency and complexity to the solution. Route 53 health checks and DNS propagation can take several minutes or longer, which means that viewers might experience delays or errors when accessing the application during a failover event. Creating Amazon Route 53 alias records that have a failover policy and Evaluate Target Health set to Yes for both ALBs and setting the TTL of both records to O is not a valid option because it will not work with CloudFront distributions. Route 53 does not support health checks for alias records that point to CloudFront distributions, so it cannot detect if an ALB behind a distribution is healthy or not. Creating a CloudFront function that detects HTTP 5xx status codes and returns a 307 Temporary Redirect error response to the secondary ALB is not a valid option because it will not provide zero-second RTO. A 307 Temporary Redirect error response tells viewers to retry their requests with a different URL, which means that viewers will have to make an additional request and wait for another response from CloudFront before reaching the secondary ALB.
References:
1: Adding, Editing, and Deleting Origins - Amazon CloudFront
2: Configuring Origin Failover - Amazon CloudFront
3: Creating or Updating a Cache Behavior - Amazon CloudFront
NEW QUESTION # 320
A DevOps engineer is building a solution that uses Amazon Simple Queue Service (Amazon SQS) standard queues. The solution also includes an AWS Lambda function and an Amazon DynamoDB table. The Lambda function pulls content from the SQS queue and writes the content to the DynamoDB table.
The solution must maximize the scalability of the Lambda function and must prevent successfully processed SQS messages from being processed multiple times.
Which solution will meet these requirements?
Answer: A
Explanation:
When a Lambda function processes an SQS batch and a subset of messages fail, the default behavior re- queues the entire batch, causing already-successfully-processed messages to be delivered and processed again.
The ReportBatchItemFailures feature in the Lambda event source mapping allows the function to return a partial failure response, indicating only the specific message IDs that failed. Lambda then deletes the successfully processed messages from the queue and re-queues only the failed items, preventing duplicate processing of successful messages. This approach maintains high concurrency because it does not restrict parallelism. Setting batch size to 1 (Option B) avoids batching entirely but eliminates the concurrency and throughput benefits. Reserved concurrency of 1 (Option D) severely restricts scalability. A 1-second batch window (Option A) affects how long Lambda waits to form a batch but does not prevent duplicate processing.
NEW QUESTION # 321
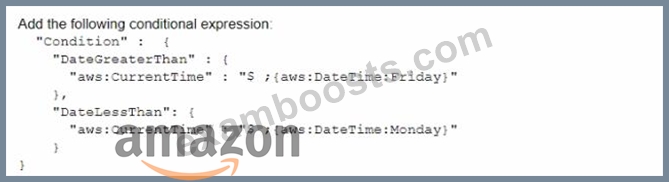
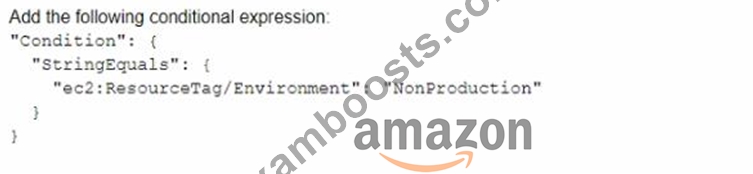


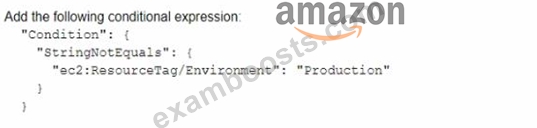
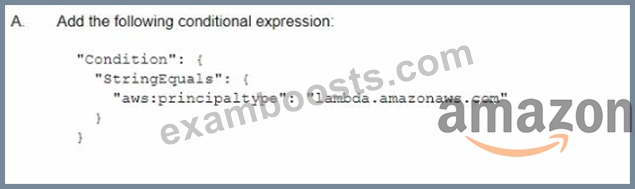
Answer: B,C,D,E,F,J
Explanation:
The engineer should make the following changes to achieve a policy of least permission:
A: Add a condition to ensure that the principal making the request is an AWS Lambda function. This ensures that only Lambda functions can execute this policy.
B: Narrow down the resources by specifying the ARN of EC2 instances instead of allowing all resources. This ensures that the policy only affects EC2 instances.
D: Add a condition to ensure that this policy only applies to EC2 instances tagged with "Environment: NonProduction". This ensures that production environments are not affected by this policy.
Reference:
AWS Identity and Access Management (IAM) - AWS Documentation
Certified DevOps Engineer - Professional (DOP-C02) Study Guide (page 179)
NEW QUESTION # 322
A DevOps engineer is setting up a container-based architecture. The engineer has decided to use AWS CloudFormation to automatically provision an Amazon ECS cluster and an Amazon EC2 Auto Scaling group to launch the EC2 container instances. After successfully creating the CloudFormation stack, the engineer noticed that, even though the ECS cluster and the EC2 instances were created successfully and the stack finished the creation, the EC2 instances were associating with a different cluster.
How should the DevOps engineer update the CloudFormation template to resolve this issue?
Answer: C
Explanation:
The UserData property of the AWS: AutoScaling: LaunchConfiguration resource can be used to specify a script that runs when the EC2 instances are launched. This script can include the ECS cluster name as an environment variable for the ECS agent running on the EC2 instances. This way, the EC2 instances will register with the correct ECS cluster. Option A is incorrect because the AWS: ECS: Cluster resource does not have a property to reference the EC2 instances. Option C is incorrect because the EC2 instances are launched by the Auto Scaling group, not by the AWS: EC2: Instance resource. Option D is incorrect because using a custom resource and a Lambda function is unnecessary and overly complex for this scenario. References: AWS::AutoScaling::LaunchConfiguration, Amazon ECS Container Agent Configuration
NEW QUESTION # 323
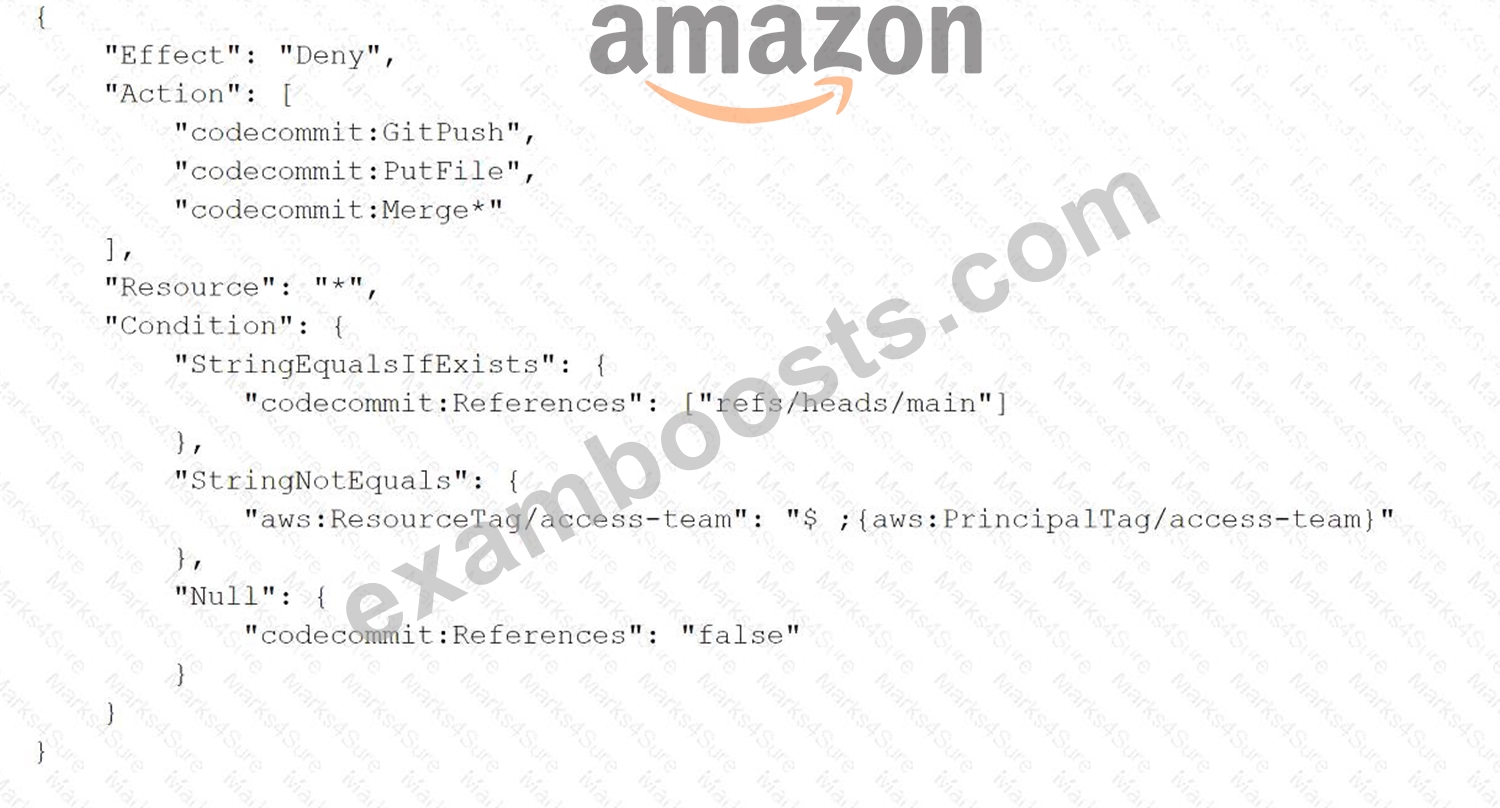
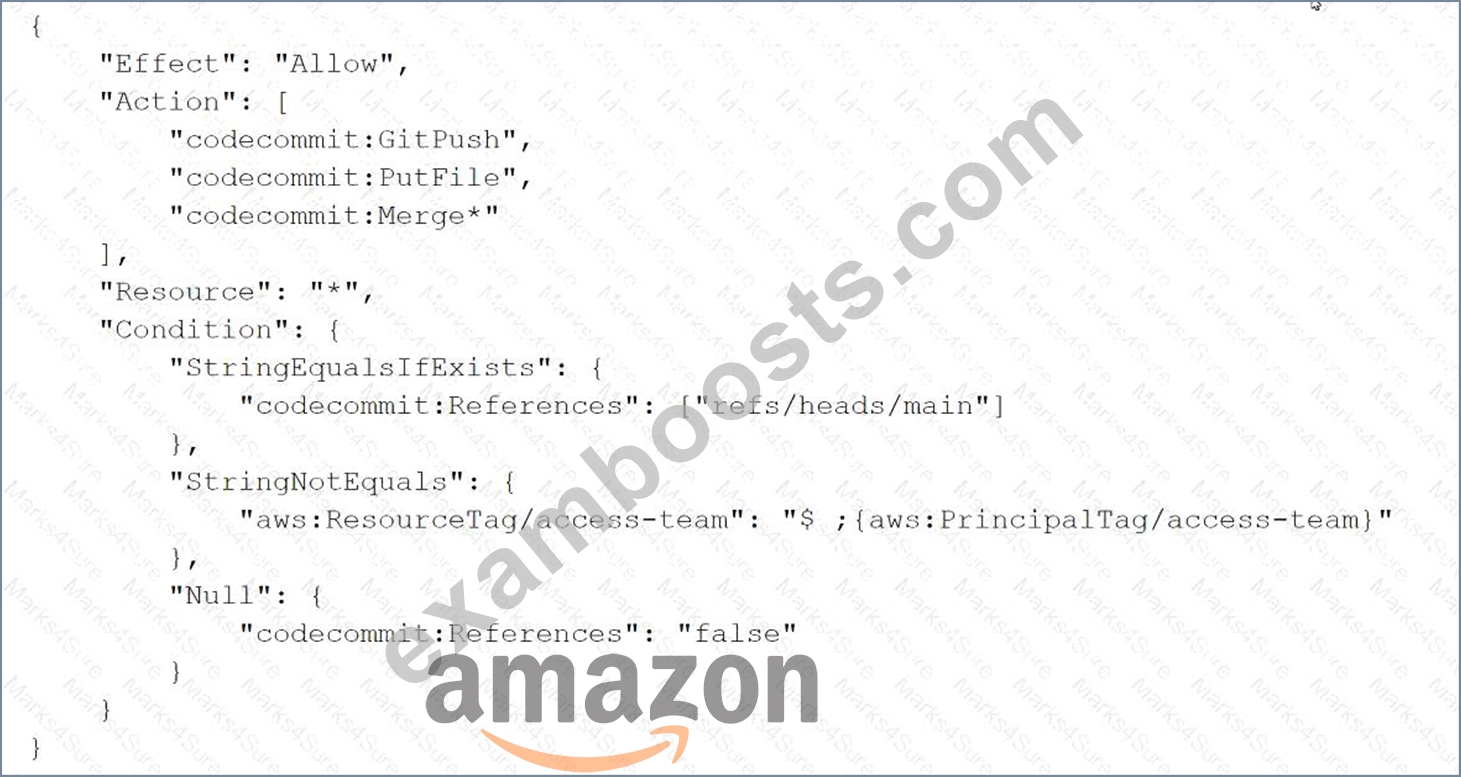
A company's application teams use AWS CodeCommit repositories for their applications. The application teams have repositories in multiple AWS accounts. All accounts are in an organization in AWS Organizations.
Each application team uses AWS IAM Identity Center (AWS Single Sign-On) configured with an external IdP to assume a developer IAM role. The developer role allows the application teams to use Git to work with the code in the repositories.
A security audit reveals that the application teams can modify the main branch in any repository. A DevOps engineer must implement a solution that allows the application teams to modify the main branch of only the repositories that they manage.
Which combination of steps will meet these requirements? (Select THREE.)
Answer: A,C,E
Explanation:
Explanation
Short Explanation: To meet the requirements, the DevOps engineer should update the SAML assertion to pass the user's team name, update the IAM role's trust policy to add an access-team session tag that has the team name, create an IAM permissions boundary in each account, and for each CodeCommit repository, add an access-team tag that has the value set to the name of the associated team.
References:
* Updating the SAML assertion to pass the user's team name allows the DevOps engineer to use IAM tags to identify which team a user belongs to. This can help enforce fine-grained access control based on the user's team membership1.
* Updating the IAM role's trust policy to add an access-team session tag that has the team name allows the DevOps engineer to use IAM condition keys to restrict access based on the session tag value2. For example, the DevOps engineer can use the aws:PrincipalTag condition key to match the access-team tag of the user with the access-team tag of the repository3.
* Creating an IAM permissions boundary in each account allows the DevOps engineer to set the maximum permissions that an identity-based policy can grant to an IAM entity. An entity's permissions boundary allows it to perform only the actions that are allowed by both its identity-based policies and its permissions boundaries4. For example, the DevOps engineer can use a permissions boundary policy to limit the actions that a user can perform on CodeCommit repositories based on their access-team tag5.
* For each CodeCommit repository, adding an access-team tag that has the value set to the name of the associated team allows the DevOps engineer to use resource tags to identify which team manages a repository. This can help enforce fine-grained access control based on the resource tag value6.
* The other options are incorrect because:
* Creating an approval rule template for each team in the Organizations management account is not a valid option, as approval rule templates are not supported by AWS Organizations. Approval rule templates are specific to CodeCommit and can only be associated with one or more repositories in the same AWS Region where they are created7.
* Creating an approval rule template for each account is not a valid option, as approval rule templates are not designed to restrict access to modify branches. Approval rule templates are designed to require approvals from specified users or groups before merging pull requests8.
* Attaching an SCP to the accounts is not a valid option, as SCPs are not designed to restrict access based on tags. SCPs are designed to restrict access based on service actions and resources across all users and roles in an organization's account9.
NEW QUESTION # 324
......
If you are preparing the exam, you will save a lot of troubles with the guidance of our DOP-C02 training engine. Our company is aimed at relieving your pressure from heavy study load. So we strongly advise you to have a try on our DOP-C02 Study Guide. If you want to know them before your purchase, you can free download the demos of our DOP-C02 exam braindumps on the website, which are the small part of the learning questions.
DOP-C02 Certified: https://www.examboosts.com/Amazon/DOP-C02-practice-exam-dumps.html
What's more, part of that ExamBoosts DOP-C02 dumps now are free: https://drive.google.com/open?id=1sEJWMf4RuRfX5uUWzwJ7mUTPtheZewXc