Databricks Databricks-Certified-Data-Analyst-Associate Exam Questions In 3 User-Friendly Formats
P.S. Free 2026 Databricks Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by Free4Dump: https://drive.google.com/open?id=1FXQitypYtX-r-hnNrDEygR67hHo0zbAe
Sharp tools make good work. Valid Databricks-Certified-Data-Analyst-Associate test questions and answers will make your exam easily. If you still feel difficult in passing exam, our products are suitable for you. Databricks-Certified-Data-Analyst-Associate test questions and answers are worked out by Free4Dump professional experts who have more than 8 years in this field. With so many years' development, we can keep stable high passing rate for Databricks Databricks-Certified-Data-Analyst-Associate Exam. You will only spend dozens of money and 20-30 hours' preparation on our Databricks-Certified-Data-Analyst-Associate test questions, passing exam is easy for you.
| Topic | Details |
|---|
| Topic 1 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
| Topic 2 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| Topic 3 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
| Topic 4 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
| Topic 5 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
>> Databricks-Certified-Data-Analyst-Associate Verified Answers <<
Study Anywhere, Anytime With Databricks-Certified-Data-Analyst-Associate PDF Dumps File
With the number of people who take the exam increasing, the Databricks-Certified-Data-Analyst-Associate exam has become more and more difficult for many people. A growing number of people have had difficulty in preparing for the Databricks-Certified-Data-Analyst-Associate exam, and they have a tendency to turn to the study materials. However, a lot of people do not know how to choose the suitable study materials. We are willing to recommend the Databricks-Certified-Data-Analyst-Associate Study Materials from our company to you.
Databricks Certified Data Analyst Associate Exam Sample Questions (Q83-Q88):
NEW QUESTION # 83
A data scientist wants to tune a set of hyperparameters for a machine learning model. They have wrapped a Spark ML model in the objective function objective_function, and they have defined the search space search_space.
As a result, they have the following code block:
num_evals = 100
trials = SparkTrials()
best_hyperparam = fmin(
fn=objective_function,
space=search_space,
algo=tpe.suggest,
max_evals=num_evals,
trials=trials
)
Which of the following changes do they need to make to the above code block in order to accomplish the task?
- A. Change SparkTrials() to Trials()
- B. Remove the algo=tpe.suggest argument
- C. Reduce num_evals to be less than 10
- D. Remove the trials=trials argument
- E. Change fmin() to fmax()
Answer: A
Explanation:
Option A is correct. The model being tuned is a Spark ML model, which is already distributed. SparkTrials is intended to distribute independent single-machine trials across Spark workers. For distributed ML algorithms such as Spark MLlib/Spark ML, Hyperopt should run trials from the driver so each trial can access the full cluster resources. Therefore, SparkTrials() should be changed to Trials(). Official Databricks documentation explains that this setup works for distributed machine learning algorithms including Apache Spark MLlib, and the Databricks notebook guidance states that SparkTrials is incompatible for that distributed-training pattern because each trial must be evaluated on the driver node.
NEW QUESTION # 84
A data analyst has been asked to count the number of customers in each region and has written the following query:
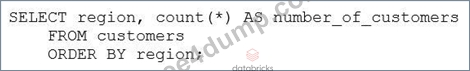
If there is a mistake in the query, which of the following describes the mistake?
- A. The query is using ORDER BY. which is not allowed in an aggregation.
- B. The query is using count('). which will count all the customers in the customers table, no matter the region.
- C. The query is missing a GROUP BY region clause.
- D. There are no mistakes in the query.
- E. The query is selecting region but region should only occur in the ORDER BY clause.
Answer: C
Explanation:
In the provided SQL query, the data analyst is trying to count the number of customers in each region. However, they made a mistake by not including the "GROUP BY" clause to group the results by region. Without this clause, the query will not return counts for each distinct region but rather an error or incorrect result. Reference: The need for a GROUP BY clause in such queries can be understood from Databricks SQL documentation: Databricks SQL.
I also noticed that you uploaded an image with your question. The image shows a snippet of an SQL query written in plain text on a white background. The query is attempting to select regions and count customers from a "customers" table and order the results by region. There's no visible syntax highlighting or any other color - it's monochromatic. The query is the same as the one in your question. I'm not sure why you included the image, but maybe you wanted to show me the exact format of your query. If so, you can also use code blocks to display formatted content such as SQL queries. For example, you can write:
SELECT region, count(*) AS number_of_customers
FROM customers
ORDER BY region;
This way, you can avoid uploading images and make your questions more clear and concise. I hope this helps.
NEW QUESTION # 85
A data analyst wants to create a Databricks SQL dashboard with multiple data visualizations and multiple counters. What must be completed before adding the data visualizations and counters to the dashboard?
- A. A markdown-based tile must be added to the top of the dashboard displaying the dashboard ' s name.
- B. A SQL warehouse (formerly known as SQL endpoint) must be turned on and selected.
- C. All data visualizations and counters must be created using Queries.
- D. The dashboard owner must also be the owner of the queries, data visualizations, and counters.
Answer: C
Explanation:
In Databricks SQL, when creating a dashboard that includes multiple data visualizations and counters, it is imperative that each visualization and counter is based on a query. The process involves the following steps:
* Develop Queries:
* For each desired visualization or counter, write a SQL query that retrieves the necessary data.
* Create Visualizations and Counters:
* After executing each query, utilize the results to create corresponding visualizations or counters.
Databricks SQL offers a variety of visualization types to represent data effectively.
* Assemble the Dashboard:
* Add the created visualizations and counters to your dashboard, arranging them as needed to convey the desired insights.
By ensuring that all components of the dashboard are derived from queries, you maintain consistency, accuracy, and the ability to refresh data as needed. This approach also facilitates easier maintenance and updates to the dashboard elements.
Reference: Visualization in Databricks SQL
NEW QUESTION # 86
A distributed team of data analysts share computing resources on an interactive cluster with autoscaling configured. In order to better manage costs and query throughput, the workspace administrator is hoping to evaluate whether cluster upscaling is caused by many concurrent users or resource-intensive queries.
In which location can one review the timeline for cluster resizing events?
- A. Cluster Event Log
- B. Driver's log file
- C. Workspace audit logs
- D. Ganglia
- E. Executor's log file
Answer: A
Explanation:
Option D is correct. Cluster resizing caused by autoscaling is recorded as a cluster activity event, so the administrator should review the Cluster Event Log. Driver and executor logs are useful for application
/runtime troubleshooting, not for the cluster resizing timeline. Ganglia shows metrics but is not the event timeline. Official Databricks documentation identifies cluster activity events as the place to retrieve cluster activity, and Databricks autoscaling documentation describes resize events such as "Cluster resize request started."
NEW QUESTION # 87
A data analysis team has noticed that their Databricks SQL queries are running too slowly when connected to their always-on SQL endpoint. They claim that this issue is present when many members of the team are running small queries simultaneously. They ask the data engineering team for help. The data engineering team notices that each of the team's queries uses the same SQL endpoint.
Which of the following approaches can the data engineering team use to improve the latency of the team's queries?
- A. They can turn on the Serverless feature for the SQL endpoint and change the Spot Instance Policy to
"Reliability Optimized." - B. They can turn on the Auto Stop feature for the SQL endpoint.
- C. They can increase the cluster size of the SQL endpoint.
- D. They can turn on the Serverless feature for the SQL endpoint.
- E. They can increase the maximum bound of the SQL endpoint's scaling range.
Answer: E
Explanation:
Option B is correct. The problem is many users running small queries simultaneously, which is a concurrency issue. Increasing the maximum number of clusters lets the SQL warehouse scale out to serve more concurrent queries. Increasing cluster size is more useful for complex or resource-heavy queries, not necessarily many small simultaneous queries. Auto Stop reduces cost but does not improve active-query latency. Official Databricks extract: "You can increase the maximum clusters if you want to handle more concurrent users," and Databricks recommends monitoring queued queries and adjusting maximum clusters.
NEW QUESTION # 88
......
Our Databricks-Certified-Data-Analyst-Associate exam torrent is famous for instant download, and we will send the downloading link and password to you within ten minutes after purchasing. You can start your learning immediately, and if you don’t receive Databricks-Certified-Data-Analyst-Associate exam torrent, just contact us, we will solve this problem for you. What’s more, with the skilled professionals to compile the Databricks-Certified-Data-Analyst-Associate Exam Dumps, quality and accuracy can be guaranteed. Therefore, you can use the Databricks-Certified-Data-Analyst-Associate exam dumps of us with ease. We have online and offline chat service stuff, if any questions bother you, just consult us.
Certification Databricks-Certified-Data-Analyst-Associate Exam Dumps: https://www.free4dump.com/Databricks-Certified-Data-Analyst-Associate-braindumps-torrent.html
- Free PDF Quiz Databricks - Databricks-Certified-Data-Analyst-Associate - Fantastic Databricks Certified Data Analyst Associate Exam Verified Answers 👄 Search for ⮆ Databricks-Certified-Data-Analyst-Associate ⮄ and easily obtain a free download on ➤ www.practicevce.com ⮘ 🏫Databricks-Certified-Data-Analyst-Associate Visual Cert Exam
- Accurate Databricks-Certified-Data-Analyst-Associate Study Material 🔇 Accurate Databricks-Certified-Data-Analyst-Associate Study Material ▛ Databricks-Certified-Data-Analyst-Associate Visual Cert Exam 🧪 Search for ▛ Databricks-Certified-Data-Analyst-Associate ▟ on “ www.pdfvce.com ” immediately to obtain a free download 🍃Databricks-Certified-Data-Analyst-Associate Sample Test Online
- Free PDF 2026 Databricks Databricks-Certified-Data-Analyst-Associate Authoritative Verified Answers 🚻 Search for ➡ Databricks-Certified-Data-Analyst-Associate ️⬅️ on “ www.exam4labs.com ” immediately to obtain a free download 🤲Dumps Databricks-Certified-Data-Analyst-Associate Cost
- Databricks-Certified-Data-Analyst-Associate PDF Questions with A Guaranteed Success 2026 🗻 Open website 【 www.pdfvce.com 】 and search for “ Databricks-Certified-Data-Analyst-Associate ” for free download 😯Databricks-Certified-Data-Analyst-Associate Exam Simulator Fee
- Databricks-Certified-Data-Analyst-Associate Latest Version ☁ Databricks-Certified-Data-Analyst-Associate Reliable Source 🥯 Reliable Databricks-Certified-Data-Analyst-Associate Mock Test 🚟 Easily obtain ➤ Databricks-Certified-Data-Analyst-Associate ⮘ for free download through 《 www.vceengine.com 》 🏅Accurate Databricks-Certified-Data-Analyst-Associate Study Material
- Databricks-Certified-Data-Analyst-Associate PDF Download 🦦 Databricks-Certified-Data-Analyst-Associate Sample Test Online 🐾 Databricks-Certified-Data-Analyst-Associate Exam Simulator Fee 🍚 Search for ⏩ Databricks-Certified-Data-Analyst-Associate ⏪ and easily obtain a free download on ➤ www.pdfvce.com ⮘ 🔄Valid Databricks-Certified-Data-Analyst-Associate Exam Bootcamp
- Databricks-Certified-Data-Analyst-Associate PDF Questions with A Guaranteed Success 2026 🕓 Open 《 www.examdiscuss.com 》 enter “ Databricks-Certified-Data-Analyst-Associate ” and obtain a free download 🌟Guide Databricks-Certified-Data-Analyst-Associate Torrent
- Guide Databricks-Certified-Data-Analyst-Associate Torrent 🥰 Accurate Databricks-Certified-Data-Analyst-Associate Study Material 🚗 Valid Databricks-Certified-Data-Analyst-Associate Exam Bootcamp 🍉 Simply search for ⏩ Databricks-Certified-Data-Analyst-Associate ⏪ for free download on ( www.pdfvce.com ) 🤿Dumps Databricks-Certified-Data-Analyst-Associate Cost
- Test Databricks-Certified-Data-Analyst-Associate Dumps 🧾 Databricks-Certified-Data-Analyst-Associate Accurate Study Material 🍝 Reliable Databricks-Certified-Data-Analyst-Associate Mock Test 🍕 Search for ⮆ Databricks-Certified-Data-Analyst-Associate ⮄ and download exam materials for free through 【 www.vce4dumps.com 】 🍄Databricks-Certified-Data-Analyst-Associate Visual Cert Exam
- 100% Pass Quiz 2026 Databricks-Certified-Data-Analyst-Associate: Databricks Certified Data Analyst Associate Exam – Efficient Verified Answers 🐬 Easily obtain free download of [ Databricks-Certified-Data-Analyst-Associate ] by searching on ⇛ www.pdfvce.com ⇚ 😈Databricks-Certified-Data-Analyst-Associate Accurate Study Material
- Databricks-Certified-Data-Analyst-Associate PDF Questions with A Guaranteed Success 2026 ✍ Search for ☀ Databricks-Certified-Data-Analyst-Associate ️☀️ and obtain a free download on 「 www.examcollectionpass.com 」 ❕Accurate Databricks-Certified-Data-Analyst-Associate Study Material
- www.notebook.ai, justpaste.me, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.fanart-central.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, telegra.ph, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
DOWNLOAD the newest Free4Dump Databricks-Certified-Data-Analyst-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1FXQitypYtX-r-hnNrDEygR67hHo0zbAe