無料でクラウドストレージから最新のCertJuken Professional-Machine-Learning-Engineer PDFダンプをダウンロードする:https://drive.google.com/open?id=1b6h5g8sKEJ6LQXA37Nc3sr5_og6XJJ0l
Google Professional Machine Learning Engineerテストの準備は、主に当社のクライアントは、Professional-Machine-Learning-Engineer試験に合格するのを助けると認証を得ることができます。この認証は、クライアントに大きなメリットをもたらします。クライアントは大企業に参入し、高給を稼ぐことができます。 Professional-Machine-Learning-Engineer試験に合格すると、給与を2倍にすることができます。認定資格を所有している場合、Professional-Machine-Learning-Engineerクイズトレントを十分にマスターし、優れた能力を所有していることを証明し、会社または工場で尊敬されます。あなたの仕事を変えたいなら、それはあなたにとっても良いことです。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Scale prototypes into AI models | 18% | - Work with foundation models and generative AI techniques - Select appropriate model architectures and frameworks - Optimize model performance and generalization - Design and run experiments |
| Topic 2: Train and deploy models | 20% | - Deploy models for online, batch, and streaming prediction - Implement generative AI deployment patterns - Use Vertex AI deployment features and infrastructure - Configure training jobs and environments |
| Topic 3: Monitor and optimize AI solutions | 16% | - Optimize cost, latency, and resource usage - Troubleshoot and maintain production systems - Monitor data quality and pipeline health - Monitor model performance, fairness, and drift |
| Topic 4: Collaborate to manage data and models | 16% | - Address data privacy, compliance, and governance - Manage datasets and features in Vertex AI - Organize and prepare enterprise data
|
| Topic 5: Architect low-code AI solutions | 12% | - Apply responsible AI principles to low-code designs - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder - Identify use cases for low-code/no-code AI tools |
| Topic 6: Automate and orchestrate ML pipelines | 18% | - Use Vertex AI Pipelines, TFX, and other orchestration tools - Design end-to-end ML workflows - Implement CI/CD for ML systems - Automate retraining and model updates |
>> Professional-Machine-Learning-Engineer資格トレーリング <<
Professional-Machine-Learning-Engineer試験に合格したい場合、Professional-Machine-Learning-Engineer練習問題は欠席できない基本的な試験資料です。 忠実なお客様からは、Professional-Machine-Learning-Engineer練習教材の合格率がこれまでに98〜100%に達していることが証明されています。 また、Professional-Machine-Learning-Engineer試験トレントの無料アップデートが1年間無料でメールボックスに送信されます。Professional-Machine-Learning-Engineer練習資料の使用中に素晴らしい経験ができることを願っています。
質問 # 247
A Data Scientist received a set of insurance records, each consisting of a record ID, the final outcome among
200 categories, and the date of the final outcome. Some partial information on claim contents is also provided, but only for a few of the 200 categories. For each outcome category, there are hundreds of records distributed over the past 3 years. The Data Scientist wants to predict how many claims to expect in each category from month to month, a few months in advance.
What type of machine learning model should be used?
正解:C
解説:
Explanation
質問 # 248
A Machine Learning Specialist is training a model to identify the make and model of vehicles in images. The Specialist wants to use transfer learning and an existing model trained on images of general objects. The Specialist collated a large custom dataset of pictures containing different vehicle makes and models.
What should the Specialist do to initialize the model to re-train it with the custom data?
正解:B
質問 # 249
You are going to train a DNN regression model with Keras APIs using this code: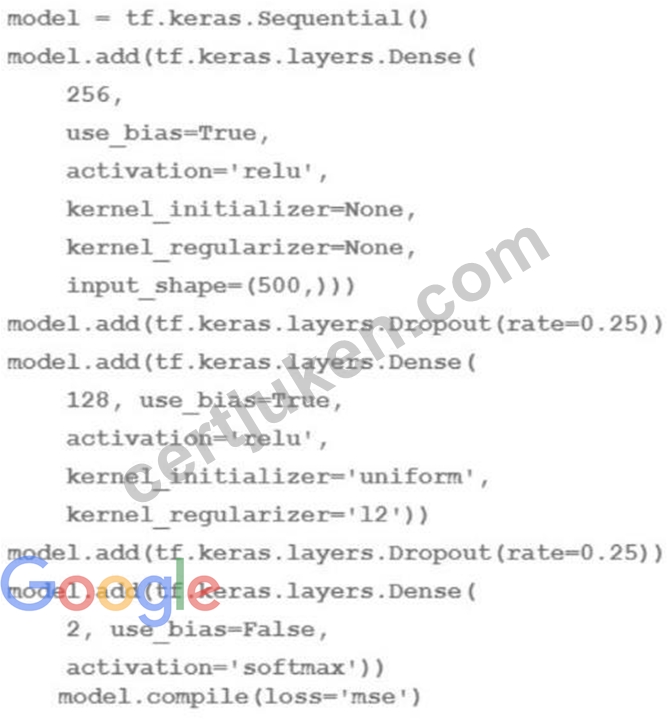
How many trainable weights does your model have? (The arithmetic below is correct.)
正解:D
解説:
The number of trainable weights in a DNN regression model with Keras APIs can be calculated by multiplying the number of input units by the number of output units for each layer, and adding the number of bias units for each layer. The bias units are usually equal to the number of output units, except for the last layer, which does not have bias units if the activation function is softmax 1 . In this code, the model has three layers: a dense layer with 256 units and relu activation, a dropout layer with 0.25 rate, and a dense layer with
2 units and softmax activation. The input shape is 500. Therefore, the number of trainable weights is:
* For the first layer: 500 input units * 256 output units + 256 bias units = 128256
* For the second layer: The dropout layer does not have any trainable weights, as it only randomly sets some of the input units to zero to prevent overfitting 2 .
* For the third layer: 256 input units * 2 output units + 0 bias units = 512 The total number of trainable weights is 128256 + 512 = 161024. Therefore, the correct answer is B.
References:
How to calculate the number of parameters for a Convolutional Neural Network?
Dropout (keras.io)
質問 # 250
You need to build classification workflows over several structured datasets currently stored in BigQuery.
Because you will be performing the classification several times, you want to complete the following steps without writing code: exploratory data analysis, feature selection, model building, training, and hyperparameter tuning and serving. What should you do?
正解:B
解説:
AutoML Tables is a service that allows you to automatically build and deploy state-of-the-art machine learning models on structured data without writing code. You can use AutoML Tables to perform the following steps for the classification task:
* Exploratory data analysis: AutoML Tables provides a graphical user interface (GUI) and a command-line interface (CLI) to explore your data, visualize statistics, and identify potential issues.
* Feature selection: AutoML Tables automatically selects the most relevant features for your model based on the data schema and the target column. You can also manually exclude or include features, or create new features from existing ones using feature engineering.
* Model building: AutoML Tables automatically builds and evaluates multiple machine learning models using different algorithms and architectures. You can also specify the optimization objective, the budget, and the evaluation metric for your model.
* Training and hyperparameter tuning: AutoML Tables automatically trains and tunes your model using the best practices and techniques from Google's research and engineering teams. You can monitor the training progress and the performance of your model on the GUI or the CLI.
* Serving: AutoML Tables automatically deploys your model to a fully managed, scalable, and secure environment. You can use the GUI or the CLI to request predictions from your model, either online
* (synchronously) or offline (asynchronously).
References:
* [AutoML Tables documentation]
* [AutoML Tables overview]
* [AutoML Tables how-to guides]
質問 # 251
You work for a company that is developing a new video streaming platform. You have been asked to create a recommendation system that will suggest the next video for a user to watch.
After a review by an AI Ethics team, you are approved to start development. Each video asset in your company's catalog has useful metadata (e.g., content type, release date, country), but you do not have any historical user event data. How should you build the recommendation system for the first version of the product?
正解:C
解説:
https://developers.google.com/machine-learning/guides/rules-of-ml
質問 # 252
......
変化する地域に対応するには、問題を解決する効率を改善する必要があります。これは、試験に対処するだけでなく、多くの側面を反映しています。 Professional-Machine-Learning-Engineer実践教材は、あなたがそれを実現するのに役立ちます。これらの時間に敏感な試験の受験者にとって、重要なニュースで構成される高効率のProfessional-Machine-Learning-Engineer実際のテストは、最高の助けになります。定期的にそれらを練習することによってのみ、あなたはあなたに明らかな進歩が起こったのを見るでしょう。それに、Professional-Machine-Learning-Engineer練習教材の利益を待つのではなく、支払い後すぐにダウンロードできるので、今すぐ成功への旅を始めましょう。
Professional-Machine-Learning-Engineer PDF: https://www.certjuken.com/Professional-Machine-Learning-Engineer-exam.html
さらに、CertJuken Professional-Machine-Learning-Engineerダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1b6h5g8sKEJ6LQXA37Nc3sr5_og6XJJ0l