P.S. Free & New AIF-C01 dumps are available on Google Drive shared by ActualCollection: https://drive.google.com/open?id=1BJewAs8sRId4K1AB2VUTGsqJ4WLXBV-j
Our AIF-C01 exam torrent is available in PDF, software, and online three modes, which allowing you to switch learning materials on paper, on your phone or on your computer, and to study anywhere and anytime with the according version of AIF-C01 practice test. Before you purchase the system, AIF-C01 Practice Test provides you with a free trial service, so that customers can fully understand our system before buying; after the online payment is successful, you can receive mail from customer service in 5 to 10 minutes, and then immediately begin to learn AIF-C01 training prep.
| Section | Weight | Objectives |
|---|---|---|
| Guidelines for Responsible AI | 14% | - Describe ethical and societal impacts of AI - Explain bias detection and reduction - Define responsible AI principles: fairness, transparency, privacy, safety - Identify risks and mitigation strategies for AI systems |
| Fundamentals of Generative AI | 24% | - Describe concepts: prompts, embeddings, fine-tuning, retrieval-augmented generation (RAG) - Define generative AI and foundation models - Differentiate between generative AI and traditional ML - Explain capabilities and use cases of generative AI |
| Fundamentals of AI and ML | 20% | - Identify types of ML: supervised, unsupervised, reinforcement learning - Define artificial intelligence (AI), machine learning (ML), and deep learning - Describe common ML workflows and lifecycle - Recognize key concepts: data, models, training, inference, evaluation |
| Security, Compliance, and Governance for AI Solutions | 14% | - Governance frameworks for AI lifecycle - Data protection and privacy in AI workflows - Compliance requirements and regulations - Security controls for AI data and models |
| Applications of Foundation Models | 28% | - Recognize tools for building and deploying generative AI solutions - Describe use cases for text, image, video, and code generation - Explain integration of foundation models into applications - Identify AWS services for generative AI: Amazon Bedrock, Amazon Titan |
>> Amazon AIF-C01 Exam Exercise <<
Our Amazon AIF-C01 real test can bring you the most valid and integrated content to ensure that what you study with is totally in accordance with the real Amazon AIF-C01 Exam. And we give sincere and suitable after-sales service to all our customers to provide you a 100% success guarantee to pass your exams on your first attempt.
NEW QUESTION # 14
Which prompting technique can protect against prompt injection attacks?
Answer: A
Explanation:
The correct answer is A because adversarial prompting is a defensive technique used to identify and protect against prompt injection attacks in large language models (LLMs). In adversarial prompting, developers intentionally test the model with manipulated or malicious prompts to evaluate how it behaves under attack and to harden the system by refining prompts, filters, and validation logic.
From AWS documentation:
"Adversarial prompting is used to evaluate and defend generative AI models against harmful or manipulative inputs (prompt injections). By testing with adversarial examples, developers can identify vulnerabilities and apply safeguards such as Guardrails or context filtering to prevent model misuse." Prompt injection occurs when an attacker tries to override system or developer instructions within a prompt, leading the model to disclose restricted information or behave undesirably. Adversarial prompting helps uncover and mitigate these risks before deployment.
Explanation of other options:
B). Zero-shot prompting provides no examples and does not protect against injection attacks.
C). Least-to-most prompting is a reasoning technique used to break down complex problems step-by-step, not a security measure.
D). Chain-of-thought prompting encourages detailed reasoning by the model but can actually increase exposure to prompt injection if not properly constrained.
Referenced AWS AI/ML Documents and Study Guides:
* AWS Responsible AI Practices - Prompt Injection and Safety Testing
* Amazon Bedrock Developer Guide - Secure Prompt Design and Evaluation
* AWS Generative AI Security Whitepaper - Adversarial Testing and Guardrails
NEW QUESTION # 15
An AI practitioner is using an Amazon Bedrock base model to summarize session chats from the customer service department. The AI practitioner wants to store invocation logs to monitor model input and output data.
Answer: C
Explanation:
The correct answer is B - Enable model invocation logging in Amazon Bedrock. AWS Bedrock provides native functionality to log all model invocations, including input prompts, parameters, and generated outputs, to Amazon CloudWatch Logs or S3. According to AWS documentation, this feature helps developers monitor model usage, analyze errors, and audit for compliance. Unlike CloudTrail or Audit Manager, which record API events and compliance data respectively, invocation logging captures real inference transactions.
EventBridge is used for event routing, not persistent log storage. Bedrock's logging feature ensures complete traceability for debugging, usage analytics, and governance in accordance with Responsible AI principles.
Referenced AWS AI/ML Documents and Study Guides:
Amazon Bedrock Developer Guide - Model Invocation Logging
AWS Responsible AI Documentation - Monitoring and Auditability
NEW QUESTION # 16
A company wants to customize a foundation model (FM). The company wants to understand the customization methods and data types that are available.
Select the correct customization method from the following list for each description. Select each customization method one time. (Select THREE.) Customization methods:
* Continued pre-training
* Distillation
* Fine-tuning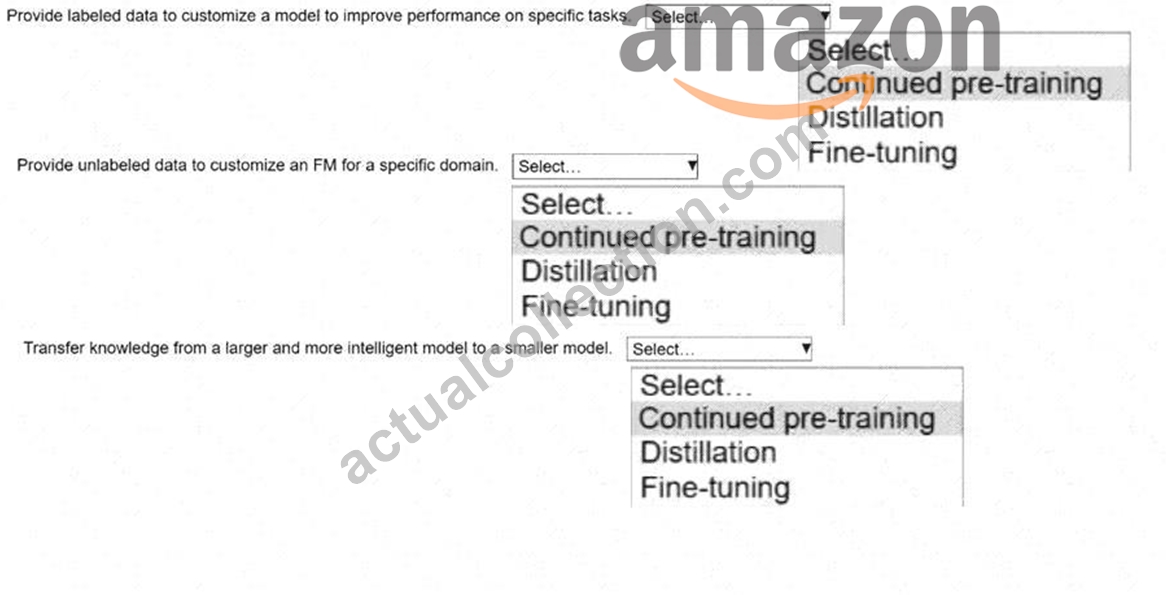
Answer:
Explanation: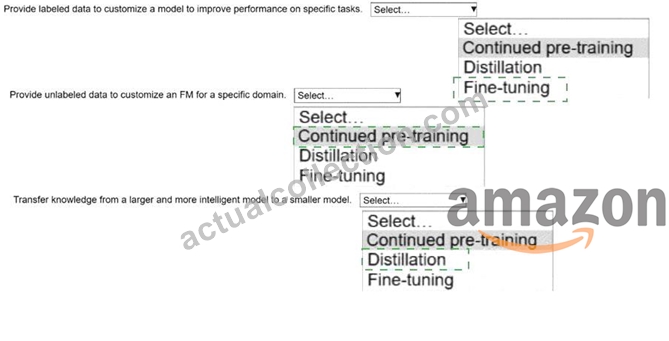
Explanation:
Provide labeled data to customize a model to improve performance on specific tasks.
answer: Fine-tuning
Comprehensive and Detailed Explanation (AWS AI documents):
AWS generative AI guidance defines fine-tuning as the process of adapting a pre-trained foundation model using labeled, task-specific data. Fine-tuning adjusts the model's parameters so it performs better on a particular task, such as classification, summarization, or domain-specific reasoning.
Fine-tuning is commonly used when:
* High-quality labeled data is available
* The goal is to improve accuracy on a specific task
* The base FM already has strong general capabilities
AWS AI Study Guide References:
* AWS foundation model customization methods
* AWS fine-tuning concepts for generative AI
Provide unlabeled data to customize a foundation model for a specific domain.
answer: Continued pre-training
Comprehensive and Detailed Explanation (AWS AI documents):
AWS documentation describes continued pre-training as extending the training of a foundation model using large volumes of unlabeled, domain-specific data. This method helps the model better understand domain vocabulary, structure, and context without requiring labeled datasets.
Continued pre-training is useful when:
* Large amounts of unlabeled domain data are available
* The goal is to improve domain understanding rather than a single task
* Labeling data would be expensive or impractical
AWS AI Study Guide References:
* AWS generative AI training lifecycle
* AWS guidance on domain adaptation using unlabeled data
Transfer knowledge from a larger and more intelligent model to a smaller model.
answer: Distillation
Comprehensive and Detailed Explanation (AWS AI documents):
AWS generative AI materials define distillation as a technique where a smaller model (student) learns to replicate the behavior of a larger, more capable model (teacher). The goal is to retain most of the performance while reducing model size, cost, and inference latency.
Distillation is commonly used to:
* Reduce operational costs
* Improve inference speed
* Deploy models to resource-constrained environments
AWS AI Study Guide References:
* AWS model optimization techniques
* AWS knowledge distillation concepts
NEW QUESTION # 17
A company is implementing intelligent agents to provide conversational search experiences for its customers.
The company needs a database service that will support storage and queries of embeddings from a generative AI model as vectors in the database.
Which AWS service will meet these requirements?
Answer: B
Explanation:
The requirement is to identify an AWS database service that supports the storage and querying of embeddings (from a generative AI model) as vectors. Embeddings are typically high-dimensional numerical representations of data (e.g., text, images) used in AI applications like conversational search. The database must support vector storage and efficient vector similarity searches. Let's evaluate each option:
A). Amazon Athena: Amazon Athena is a serverless query service for analyzing data in Amazon S3 using SQL. It is designed for ad-hoc querying of structured data but does not natively support vector storage or vector similarity searches, making it unsuitable for this use case.
B). Amazon Aurora PostgreSQL: Amazon Aurora PostgreSQL is a fully managed relational database compatible with PostgreSQL. With the pgvector extension (available in PostgreSQL and supported by Aurora PostgreSQL), it can store and query vector embeddings efficiently. The pgvector extension enables vector similarity searches (e.g., using cosine similarity or Euclidean distance), which is critical for conversational search applications using embeddings from generative AI models.
C). Amazon Redshift: Amazon Redshift is a data warehousing service optimized for analytical queries on large datasets. While it supports machine learning features and can store numerical data, it does not have native support for vector embeddings or vector similarity searches as of May 17, 2025, making it less suitable for this use case.
D). Amazon EMR: Amazon EMR is a managed big data platform for processing large-scale data using frameworks like Apache Hadoop and Spark. It is not a database service and is not designed for storing or querying vector embeddings in the context of a conversational search application.
Exact Extract Reference: According to the AWS documentation, "Amazon Aurora PostgreSQL-Compatible Edition supports the pgvector extension, which enables efficient storage and similarity searches for vector embeddings. This makes it suitable for AI/ML workloads such as natural language processing and recommendation systems that rely on vector data." (Source: AWS Aurora Documentation - Using pgvector with Aurora PostgreSQL, https://docs.aws.amazon.com/AmazonRDS/latest/AuroraUserGuide
/PostgreSQLpgvector.html). Additionally, the pgvector extension supports operations like nearest-neighbor searches, which are essential for querying embeddings in a conversational search system.
Amazon Aurora PostgreSQL with the pgvector extension directly meets the requirement for storing and querying embeddings as vectors, making B the correct answer.
References:
AWS Aurora Documentation: Using pgvector with Aurora PostgreSQL (https://docs.aws.amazon.com
/AmazonRDS/latest/AuroraUserGuide/PostgreSQLpgvector.html)
AWS AI Practitioner Study Guide (focus on data engineering for AI, including vector databases) AWS Blog on Vector Search with Aurora (https://aws.amazon.com/blogs/database/using-vector-search-with- amazon-aurora-postgresql/)
NEW QUESTION # 18
A publishing company built a Retrieval Augmented Generation (RAG) based solution to give its users the ability to interact with published content. New content is published daily. The company wants to provide a near real-time experience to users.
Which steps in the RAG pipeline should the company implement by using offline batch processing to meet these requirements? (Select TWO.)
Answer: A,B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In a RAG (Retrieval Augmented Generation) architecture, there are steps that can be optimized using offline batch processing, particularly for operations that do not require real-time updates:
* A. Generation of content embeddings:When new content is published, it can be processed in batches to generate embeddings (vector representations) offline. These embeddings are then used at query time for similarity search. As new documents come in daily, batch processing is ideal for generating embeddings for all new content together.
"Content/document embeddings are typically generated offline, as this operation can be computationally expensive and does not need to happen in real-time." (Reference: AWS GenAI RAG Blog, Amazon Bedrock RAG Pattern)
* C. Creation of the search index:After generating the content embeddings, these are indexed in a vector database or search service. This indexing is also typically performed in batch as part of the offline pipeline.
"Building or updating the vector index is often performed as a batch operation, reflecting the latest state of the content repository." (Reference: AWS RAG Pattern Whitepaper) B, D, and E are real-time steps. Embeddings for user queries (B), retrieval of relevant content (D), and response generation (E) must be processed in real-time to provide an interactive experience.
References:
Retrieval Augmented Generation (RAG) on AWS
Amazon Bedrock RAG Documentation
NEW QUESTION # 19
......
The passing rate of our AIF-C01 training quiz is high as 98% to 100% and the hit rate is also high. Our professional expert team seizes the focus of the exam and chooses the most important questions and answers which has simplified the important information and follow the latest trend to make the client learn easily and efficiently on our AIF-C01 Study Guide. YOu can also free download the demos of our AIF-C01 learning materials to have a check.
AIF-C01 Study Reference: https://www.actualcollection.com/AIF-C01-exam-questions.html
What's more, part of that ActualCollection AIF-C01 dumps now are free: https://drive.google.com/open?id=1BJewAs8sRId4K1AB2VUTGsqJ4WLXBV-j