그 외, Itexamdump Databricks-Certified-Professional-Data-Engineer 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1FIxDEMhgsRKFdZnC5f-03oNj_4AIR_cg
Databricks Databricks-Certified-Professional-Data-Engineer인증시험도 어려울 뿐만 아니라 신청 또한 어렵습니다.Databricks Databricks-Certified-Professional-Data-Engineer시험은 IT업계에서도 권위가 있고 직위가 있으신 분들이 응시할 수 있는 시험이라고 알고 있습니다. 우리 Itexamdump에서는Databricks Databricks-Certified-Professional-Data-Engineer관련 학습가이드를 제동합니다. Itexamdump 는 우리만의IT전문가들이 만들어낸Databricks Databricks-Certified-Professional-Data-Engineer관련 최신, 최고의 자료와 학습가이드를 준비하고 있습니다. 여러분의 편리하게Databricks Databricks-Certified-Professional-Data-Engineer응시하는데 많은 도움이 될 것입니다.
데이터 브릭스 인증 전문 데이터 엔지니어 인증 시험은 데이터 수집, 데이터 처리, 데이터 저장 및 데이터 분석을 포함한 다양한 주제를 다룹니다. 후보자는 데이터브릭스를 이용한 데이터 솔루션 설계 및 구현 능력과 데이터 엔지니어링에 대한 최상의 실천 방법에 대한 이해를 증명해야 합니다. 시험은 객관식 문제로 구성되며 약 2시간 소요됩니다.
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) 자격증 시험은 Databricks를 사용하여 신뢰성 높고 확장성과 성능이 우수한 데이터 파이프라인을 구축하는 전문성을 입증하고자 하는 개인들에게 매우 인기 있는 자격증입니다. 이 자격증은 Databricks를 사용하여 대용량 데이터 처리를 위한 데이터 파이프라인을 설계, 구현 및 유지 관리하는 데 필요한 기술과 지식을 검증하기 위해 설계되었습니다.
>> Databricks-Certified-Professional-Data-Engineer최고덤프문제 <<
근 몇년간IT산업이 전례없이 신속히 발전하여 IT업계에 종사하는 분들이 여느때보다 많습니다. 경쟁이 이와같이 치열한 환경속에서 누구도 대체할수 없는 자기만의 자리를 찾으려면 IT인증자격증취득은 무조건 해야 하는것이 아닌가 싶습니다. Databricks인증 Databricks-Certified-Professional-Data-Engineer시험은 IT인증시험중 가장 인기있는 시험입니다. Itexamdump에서는 여러분이Databricks인증 Databricks-Certified-Professional-Data-Engineer시험을 한방에 패스하도록 실제시험문제에 대비한Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프를 발췌하여 저렴한 가격에 제공해드립니다.시험패스 못할시 덤프비용은 환불처리 해드리기에 고객님께 아무런 페를 끼치지 않을것입니다.
Databricks Certified Professional Data Engineer 시험을 준비하려면, 지원자들은 Databricks에서 제공하는 자원들을 활용할 수 있습니다. 이 회사는 훈련 과정, 인증 공부 안내서 및 연습 시험을 제공하여 시험 대비에 도움을 줍니다. 이러한 자원들은 시험 주제에 대한 개괄을 제공하며 Databricks 플랫폼에 대한 실제 경험을 제공합니다.
질문 # 89
Direct query on external files limited options, create external tables for CSV files with header and pipe delimited CSV files, fill in the blanks to complete the create table statement CREATE TABLE sales (id int, unitsSold int, price FLOAT, items STRING)
________
________
LOCATION "dbfs:/mnt/sales/*.csv"
정답:D
설명:
Explanation
Answer is
USING CSV
OPTIONS ( header ="true", delimiter = "|")
Here is the syntax to create an external table with additional options
CREATE TABLE table_name (col_name1 col_typ1,..)
USING data_source
OPTIONS (key='value', key2=vla2)
LOCATION = "/location"
질문 # 90
A data engineer is implementing Unity Catalog governance for a multi-team environment. Data scientists need interactive clusters for basic data exploration tasks, while automated ETL jobs require dedicated processing.
How should the data engineer configure cluster isolation policies to enforce least privilege and ensure Unity Catalog compliance?
정답:D
설명:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Unity Catalog enforces governance and data isolation through cluster access modes and compute policies. According to Databricks documentation, "Interactive clusters that multiple users share should use Standard access mode, while automated jobs and production pipelines should use Dedicated access mode for stricter isolation." Standard access mode allows multiple users to share the same compute resources but still respects Unity Catalog permissions. Dedicated access mode isolates the job run's execution environment, ensuring that data access is limited to the job's identity. Configuring these modes within compute policies enforces least privilege and ensures all compute complies with Unity Catalog security standards. Options A and C are incorrect because using only Dedicated clusters reduces resource efficiency, while "No isolation" clusters are not Unity Catalog compliant.
질문 # 91
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalidlatitudeandlongitudevalues in theactivity_detailstable have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to addCHECKconstraints to the Delta Lake table: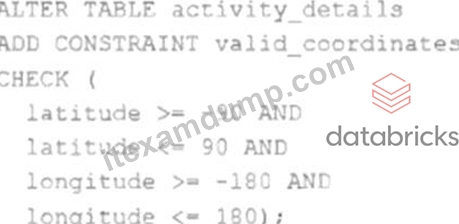
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
정답:E
설명:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and 180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Add a CHECK constraint to an existing table" section.
https://docs.databricks.com/en/sql/language-manual/sql-ref-syntax-ddl-alter-table.html#add-constraint
질문 # 92
A data team ' s Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.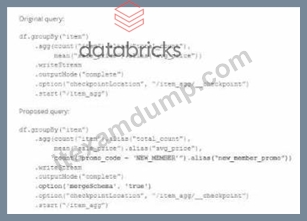
Which step must also be completed to put the proposed query into production?
정답:A
설명:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
:
Databricks documentation on Structured Streaming: https://docs.databricks.com/spark/latest/structured- streaming/index.html Databricks documentation on streaming checkpoints: https://docs.databricks.com/spark/latest/structured- streaming/production.html#checkpointing
질문 # 93
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.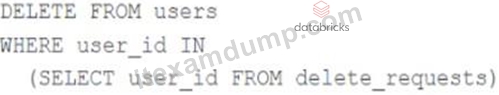
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
정답:A
설명:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under "Remove files no longer referenced by a Delta table" section.
질문 # 94
......
Databricks-Certified-Professional-Data-Engineer최신버전 덤프문제: https://www.itexamdump.com/Databricks-Certified-Professional-Data-Engineer.html
참고: Itexamdump에서 Google Drive로 공유하는 무료 2026 Databricks Databricks-Certified-Professional-Data-Engineer 시험 문제집이 있습니다: https://drive.google.com/open?id=1FIxDEMhgsRKFdZnC5f-03oNj_4AIR_cg