What's more, part of that ActualVCE DEA-C02 dumps now are free: https://drive.google.com/open?id=1CdubdJ4Vk0vXW26lVsPuxKI2xjS0_OOn
To let the clients have an understanding of their mastery degree of our DEA-C02 study materials and get a well preparation for the test, we provide the test practice software to the clients. The test practice software of DEA-C02 study materials is based on the real test questions and its interface is easy to use. The test practice software boosts the test scheme which stimulate the real test and boost multiple practice models, the historical records of the practice of DEA-C02 Study Materials and the self-evaluation function.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Sharing and Collaboration | 5-10% | - Implement secure data sharing and data exchanges - Work with Snowflake Data Marketplace and external data providers - Design multi-tenant and cross-account data architectures |
| Topic 2: Data Governance, Security, and Compliance | 10-15% | - Manage data lineage, cataloging, and compliance policies - Apply data protection: encryption, masking, row-level security - Implement access control: RBAC, authentication, authorization - Enforce data quality and governance standards |
| Topic 3: Data Transformation and Processing | 20-25% | - Manage data quality, validation, and deduplication - Implement ELT/ETL workflows using Streams, Tasks, and Dynamic Tables - Transform and enrich data using SQL, JavaScript, Python, and Snowpark - Process semi-structured data: JSON, Avro, Parquet, ORC |
| Topic 4: Data Ingestion and Sourcing | 20-25% | - Design and implement continuous and batch ingestion pipelines - Ingest data from various sources: data lakes, APIs, on-premises systems, cloud storage - Handle different data formats: structured, semi-structured, unstructured - Use Snowflake ingestion methods: Snowpipe, COPY INTO, External Functions |
| Topic 5: Performance Optimization and Compute Management | 15-20% | - Monitor and tune workloads and resource utilization - Manage virtual warehouses: sizing, scaling, multi-cluster, cost control - Use search optimization and query acceleration services - Optimize query performance: clustering, partitioning, materialized views |
| Topic 6: Data Pipeline Architecture and Design | 15-20% | - Integrate with external tools and platforms: orchestration, BI, ML - Build end-to-end near real-time streaming solutions - Apply design patterns for data engineering workloads - Design scalable, reliable, and maintainable data pipelines |
>> DEA-C02 Valid Exam Testking <<
If you are worrying about that there is no enough time to prepare for DEA-C02 exam, or you can't find the authoritative study materials about DEA-C02 exam, but when you read this article, your worries will be deleted completely. The latest DEA-C02 exam review materials offered by our ActualVCE will help you complete the DEA-C02 Exam Preparation in short time. We have the authority of the exam materials and experienced team with rich sense of responsibility. All that we have done is just to help you easily pass the DEA-C02 exam.
NEW QUESTION # 28
You are performing a series of complex data transformations on a large table named 'TRANSACTIONS' in Snowflake. After running several DML statements, you realize that an earlier transformation step introduced incorrect data into the table. You want to rollback the table to a state before that specific transformation occurred. Which of the following methods could be used to achieve this rollback, assuming you know the exact timestamp or query ID of the state you want to revert to? Select all that apply.
Answer: A,D
Explanation:
Options B and E are the correct methods for rolling back changes using Time Travel. Option B clones the table to the desired state and replaces the original, effectively rolling it back. Option E directly overwrites the original table with the historical data obtained through Time Travel. Option A is an extreme measure. Option C is for recovering dropped tables, not rolling back changes within a table. Option D does not directly rollback the table to the previous state, the correct data has to be loaded, that will take more time.
NEW QUESTION # 29
You are implementing row access policies on a 'SALES DATA table to restrict access based on the 'REGION' column. Different users are allowed to see data only for specific regions. You have a mapping table 'USER REGION MAP' with columns 'USERNAME' and 'REGION'. You want to create a row access policy that dynamically filters the 'SALES DATA' based on the user and their allowed region. Which of the following options represents a correct approach to create and apply this row access policy?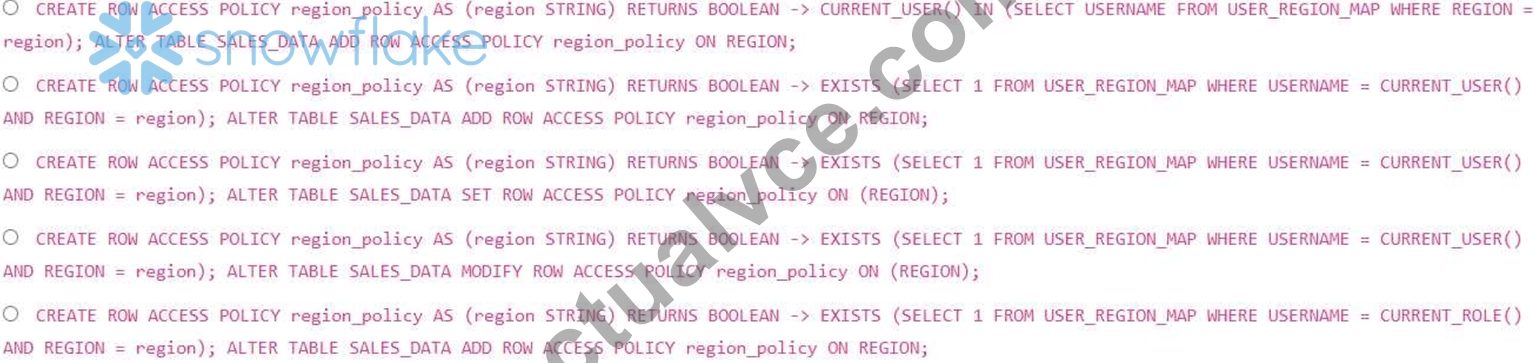
Answer: B
Explanation:
Option B is the correct approach. It creates a row access policy that checks if a row exists in the where the username matches the current user and the region matches the 'REGION' column in the 'SALES_DATR table. 'ADD ROW ACCESS POLICY is the correct command to apply the policy. Options A is incorrect as it uses IN clause, which can become inefficient with large datasets. Option C uses 'SET' which is not a valid operation, and Option D uses 'MODIFY which is used for masking policy and not row access policy. Option E uses 'CURRENT ROLE instead of 'CURRENT USER' which is not the appropriate filter criteria.
NEW QUESTION # 30
You are tasked with implementing a data loading process for a table 'CUSTOMER DATA' in Snowflake. The source data is in Parquet format on Azure Blob Storage and contains personally identifiable information (PII). You must ensure that the data is loaded securely, masked during the loading process, and that only authorized users can access the unmasked data after the load. Assume you have already created a stage pointing to the Azure Blob Storage. Which of the following steps should you take to achieve this?
Answer: E
Explanation:
Option B is the most comprehensive solution for secure data loading and PII protection. 'TRANSFORM' and JavaScript UDF masking during load prevent PII from being stored unmasked, enhancing security. Implementing masking policies provides granular control over access to the sensitive data post-load. It's more secure to avoid storing sensitive information even temporarily. Option A encrypts the data in transit but doesn't address masking. Option C requires dynamic data masking, but masking during copy is optimal. The correct way to copy and mask PII data is using a JavaScript UDF to mask the PII data during the load process, and then implement Masking Policies on the table.
NEW QUESTION # 31
You're tasked with building a data pipeline using Snowpark Python to incrementally load data into a target table 'SALES SUMMARY from a source table 'RAW SALES. The pipeline needs to ensure that only new or updated records from 'RAW SALES are merged into 'SALES SUMMARY' based on a 'TRANSACTION ID'. You want to use Snowpark's 'MERGE' operation for this, but you also need to handle potential conflicts and log any rejected records to an error table 'SALES SUMMARY ERRORS'. Which of the following approaches offers the MOST robust and efficient solution for handling errors and ensuring data integrity within the MERGE statement?
Answer: C
Explanation:
Option E provides the most robust solution. Using a stored procedure to execute the MERGE allows for more complex error handling logic. Critically, the result_scan function of the MERGE query can then be used to identify and analyze the success or failure of each individual record processed within the MERGE. This avoids separate processes or post-merge comparisons and is therefore more robust. Option A requires a separate process for inconsistency checking, which is less efficient and may miss real-time errors. Options B, C, and D do not offer a reliable and atomic way to capture and log all rejected records. The SYSTEM$PIPE_STATUS function is relevant for Snowpipe, not direct MERGE operations.
NEW QUESTION # 32
A financial institution needs to tokenize sensitive customer data (credit card numbers) stored in a Snowflake table named 'CUSTOMER_DATA before it's consumed by a downstream reporting application. The institution uses an external tokenization service accessible via a REST API. Which of the following approaches is the MOST secure and scalable way to implement tokenization during data loading, minimizing exposure of the raw credit card data within Snowflake?
Answer: A
Explanation:
Option E is the most secure and scalable approach. It tokenizes the data during the load process, minimizing the amount of time the raw data resides in Snowflake. Using a UDF in a masking policy (options A and C) tokenizes the data on read, meaning the raw data is stored in Snowflake. Option B, using a stored procedure and , can be less efficient for large datasets. Data sharing raw data (Option D) defeats the purpose of tokenization for the source environment.
NEW QUESTION # 33
......
In real life, every great career must have the confidence to take the first step. When you suspect your level of knowledge, and cramming before the exam, do you think of how to pass the Snowflake DEA-C02 exam with confidence? Do not worry, ActualVCE is the only provider of training materials that can help you to pass the exam. Our training materials, including questions and answers, the pass rate can reach 100%. With ActualVCE Snowflake DEA-C02 Exam Training materials, you can begin your first step forward. When you get the certification of Snowflake DEA-C02 exam, the glorious period of your career will start.
Latest DEA-C02 Material: https://www.actualvce.com/Snowflake/DEA-C02-valid-vce-dumps.html
What's more, part of that ActualVCE DEA-C02 dumps now are free: https://drive.google.com/open?id=1CdubdJ4Vk0vXW26lVsPuxKI2xjS0_OOn