Databricks-Certified-Professional-Data-Engineer인증시험인기덤프문제시험준비에가장좋은기출문제모음자료

그리고 ExamPassdump Databricks-Certified-Professional-Data-Engineer 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1OebAJoABYNjvc106MgXlY4MAucP8Cw7L
안심하시고ExamPassdump 를 선택하게 하기 위하여, ExamPassdump에서는 이미Databricks Databricks-Certified-Professional-Data-Engineer인증시험의 일부 문제와 답을 사이트에 올려놨으니 체험해보실 수 있습니다. 그러면 저희한테 신뢰가 갈 것이며 또 망설임 없이 선택하게 될 것입니다. 저희 덤프로 여러분은 한번에 시험을 패스할 수 있으며 또 개인시간도 절약하고 무엇보다도 금전상으로 절약이 제일 크다고 봅니다. ExamPassdump는 여러분들한테 최고의Databricks Databricks-Certified-Professional-Data-Engineer문제와 답을 제공함으로 100%로의 보장 도를 자랑합니다, 여러분은Databricks Databricks-Certified-Professional-Data-Engineer인증시험의 패스로 IT업계여서도 또 직장에서도 한층 업그레이드되실 수 있습니다. 여러분의 미래는 더욱더 아름다울 것입니다.
Databricks Databricks-Certified-Professional-Data-Engineer Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Ensuring Data Security and Compliance | 10% | - Compliance standards implementation
- Data encryption and masking
- Access control and permissions
|
| Topic 2: Cost & Performance Optimisation | 13% | - Query optimization and caching
- Cluster configuration and scaling
- Storage optimization (partitioning, Z-order, indexing)
|
| Topic 3: Data Modelling | 6% | - Delta Lake table design
- Medallion Architecture implementation
- Schema design and management
|
| Topic 4: Data Governance | 7% | - Data lineage and metadata tracking
- Unity Catalog management
- Policy enforcement
|
| Topic 5: Debugging and Deploying | 10% | - CI/CD and DevOps practices
- Troubleshooting pipelines and errors
- Deployment using bundles, CLI, and APIs
|
| Topic 6: Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data
- Standardization and normalization
- Data validation and quality checks
|
| Topic 7: Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion
- Schema inference and evolution
- Connecting to diverse data sources
|
| Topic 8: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access
- Unity Catalog data sharing
|
| Topic 9: Monitoring and Alerting | 10% | - Pipeline observability and logging
- Setting up alerts and notifications
- Performance and health monitoring
|
| Topic 10: Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools
- Batch and incremental processing logic
- Data transformation and aggregation
|
>> Databricks-Certified-Professional-Data-Engineer인증시험 인기 덤프문제 <<
시험대비 Databricks-Certified-Professional-Data-Engineer인증시험 인기 덤프문제 덤프 최신 샘플
Databricks인증 Databricks-Certified-Professional-Data-Engineer시험은 IT인증자격증중 가장 인기있는 자격증을 취득하는 필수시험 과목입니다. Databricks인증 Databricks-Certified-Professional-Data-Engineer시험을 패스해야만 자격증 취득이 가능합니다. ExamPassdump의Databricks인증 Databricks-Certified-Professional-Data-Engineer는 최신 시험문제 커버율이 높아 시험패스가 아주 간단합니다. Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프만 공부하시면 아무런 우려없이 시험 보셔도 됩니다. 시험합격하면 좋은 소식 전해주세요.
최신 Databricks Certification Databricks-Certified-Professional-Data-Engineer 무료샘플문제 (Q199-Q204):
질문 # 199
A data engineer is designing a pipeline in Databricks that processes records from a Kafka stream where late-arriving data is common.
Which approach should the data engineer use?
- A. Implement a custom solution using Databricks Jobs to periodically reprocess all historical data.
- B. Use an Auto CDC pipeline with batch tables to simplify late data handling.
- C. Use batch processing and overwrite the entire output table each time to ensure late data is incorporated correctly.
- D. Use a watermark to specify the allowed lateness to accommodate records that arrive after their expected window, ensuring correct aggregation and state management.
정답:D
설명:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
In Structured Streaming, event-time watermarks control how long the engine waits for late-arriving data before finalizing aggregations. By setting an appropriate watermark, Databricks can handle late data gracefully - incorporating records that arrive within the defined window while discarding excessively delayed events.
This approach ensures accurate aggregations, minimizes state size, and prevents memory leaks.
Manual reprocessing (A) or overwriting entire datasets (B) is inefficient and costly, while Auto CDC (C) is used for change tracking in Delta tables, not for streaming event lateness.
Thus, using watermarking is the recommended and official approach for managing late data in streaming pipelines.
질문 # 200
Which of the following describes a scenario in which a data engineer will want to use a Job cluster instead of
an all-purpose cluster?
- A. A Databricks SQL query needs to be scheduled for upward reporting
- B. A data engineer needs to manually investigate a production error
- C. An automated workflow needs to be run every 30 minutes
- D. An ad-hoc analytics report needs to be developed while minimizing compute costs
- E. A data team needs to collaborate on the development of a machine learning model
정답:C
질문 # 201
The business intelligence team has a dashboard configured to track various summary metrics for retail stories.
This includes total sales for the previous day alongside totals and averages for a variety of time periods. The fields required to populate this dashboard have the following schema:

For Demand forecasting, the Lakehouse contains a validated table of all itemized sales updated incrementally in near real-time. This table named products_per_order, includes the following fields:

Because reporting on long-term sales trends is less volatile, analysts using the new dashboard only require data to be refreshed once daily. Because the dashboard will be queried interactively by many users throughout a normal business day, it should return results quickly and reduce total compute associated with each materialization.
Which solution meets the expectations of the end users while controlling and limiting possible costs?
- A. Define a view against the products_per_order table and define the dashboard against this view.
- B. Use the Delta Cache to persists the products_per_order table in memory to quickly the dashboard with each query.
- C. Populate the dashboard by configuring a nightly batch job to save the required to quickly update the dashboard with each query.
- D. Use Structure Streaming to configure a live dashboard against the products_per_order table within a Databricks notebook.
정답:C
질문 # 202
A data engineer has written the following query:
1. SELECT *
2. FROM json.`/path/to/json/file.json`;
The data engineer asks a colleague for help to convert this query for use in a Delta Live Tables (DLT)
pipeline. The query should create the first table in the DLT pipeline.
Which of the following describes the change the colleague needs to make to the query?
- A. They need to add a CREATE LIVE TABLE table_name AS line at the beginning of the query
- B. They need to add a CREATE DELTA LIVE TABLE table_name AS line at the beginning of the query
- C. They need to add a live. prefix prior to json. in the FROM line
- D. They need to add the cloud_files(...) wrapper to the JSON file path
- E. They need to add a COMMENT line at the beginning of the query
정답:A
질문 # 203
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.
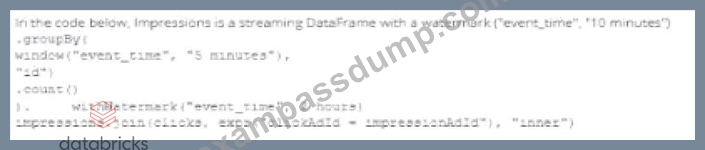
Which solution would improve the performance?
정답:B
설명:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time.
However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
질문 # 204
......
ExamPassdump의Databricks인증 Databricks-Certified-Professional-Data-Engineer시험대비 덤프는 가격이 착한데 비하면 품질이 너무 좋은 시험전 공부자료입니다. 시험문제적중율이 높아 패스율이 100%에 이르고 있습니다.다른 IT자격증에 관심이 있는 분들은 온라인서비스에 문의하여 덤프유무와 적중율등을 확인할수 있습니다. Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프로 어려운 시험을 정복하여 IT업계 정상에 오릅시다.
Databricks-Certified-Professional-Data-Engineer유효한 최신덤프자료: https://www.exampassdump.com/Databricks-Certified-Professional-Data-Engineer_valid-braindumps.html
- Databricks-Certified-Professional-Data-Engineer인증시험 인기 덤프문제 시험준비에 가장 좋은 인기시험 덤프자료 🛴 무료 다운로드를 위해 지금⇛ www.dumptop.com ⇚에서☀ Databricks-Certified-Professional-Data-Engineer ️☀️검색Databricks-Certified-Professional-Data-Engineer유효한 덤프자료
- Databricks-Certified-Professional-Data-Engineer인기자격증 시험덤프공부 🏗 Databricks-Certified-Professional-Data-Engineer인증덤프공부 ⭐ Databricks-Certified-Professional-Data-Engineer인증덤프 샘플체험 👡 시험 자료를 무료로 다운로드하려면⮆ www.itdumpskr.com ⮄을 통해⮆ Databricks-Certified-Professional-Data-Engineer ⮄를 검색하십시오Databricks-Certified-Professional-Data-Engineer퍼펙트 최신버전 덤프
- Databricks-Certified-Professional-Data-Engineer 100%시험패스 공부자료 💏 Databricks-Certified-Professional-Data-Engineer최신버전 시험대비자료 🦍 Databricks-Certified-Professional-Data-Engineer최신 업데이트버전 덤프문제공부 ⚜ ⇛ www.pass4test.net ⇚을 통해 쉽게➥ Databricks-Certified-Professional-Data-Engineer 🡄무료 다운로드 받기Databricks-Certified-Professional-Data-Engineer인기자격증 시험덤프공부
- Databricks-Certified-Professional-Data-Engineer시험패스 가능한 공부 📸 Databricks-Certified-Professional-Data-Engineer유효한 덤프문제 🟤 Databricks-Certified-Professional-Data-Engineer최신 업데이트버전 덤프문제공부 🛰 ( www.itdumpskr.com )에서 검색만 하면➤ Databricks-Certified-Professional-Data-Engineer ⮘를 무료로 다운로드할 수 있습니다Databricks-Certified-Professional-Data-Engineer인증덤프 샘플체험
- Databricks-Certified-Professional-Data-Engineer인기자격증 시험덤프공부 🎁 Databricks-Certified-Professional-Data-Engineer최신 업데이트버전 덤프문제공부 💨 Databricks-Certified-Professional-Data-Engineer인기자격증 시험덤프공부 👬 ⏩ www.dumptop.com ⏪에서⮆ Databricks-Certified-Professional-Data-Engineer ⮄를 검색하고 무료 다운로드 받기Databricks-Certified-Professional-Data-Engineer인기자격증 덤프자료
- Databricks-Certified-Professional-Data-Engineer인증시험 인기 덤프문제 인기시험덤프 🔏 무료 다운로드를 위해 지금▶ www.itdumpskr.com ◀에서【 Databricks-Certified-Professional-Data-Engineer 】검색Databricks-Certified-Professional-Data-Engineer인기자격증 덤프자료
- Databricks-Certified-Professional-Data-Engineer 100%시험패스 공부자료 🪐 Databricks-Certified-Professional-Data-Engineer유효한 최신덤프공부 🥃 Databricks-Certified-Professional-Data-Engineer시험패스 가능한 공부 🖐 ⮆ www.passtip.net ⮄에서 검색만 하면➡ Databricks-Certified-Professional-Data-Engineer ️⬅️를 무료로 다운로드할 수 있습니다Databricks-Certified-Professional-Data-Engineer유효한 최신덤프공부
- Databricks-Certified-Professional-Data-Engineer인증시험 인기 덤프문제 덤프데모문제 🚠 “ www.itdumpskr.com ”을(를) 열고[ Databricks-Certified-Professional-Data-Engineer ]를 검색하여 시험 자료를 무료로 다운로드하십시오Databricks-Certified-Professional-Data-Engineer인기자격증
- Databricks-Certified-Professional-Data-Engineer인기자격증 👍 Databricks-Certified-Professional-Data-Engineer인기자격증 시험덤프공부 🏴 Databricks-Certified-Professional-Data-Engineer유효한 덤프자료 📯 지금⇛ www.koreadumps.com ⇚에서⇛ Databricks-Certified-Professional-Data-Engineer ⇚를 검색하고 무료로 다운로드하세요Databricks-Certified-Professional-Data-Engineer인증덤프공부
- 최신버전 Databricks-Certified-Professional-Data-Engineer인증시험 인기 덤프문제 완벽한 시험 최신버전 덤프 🚚 ▛ www.itdumpskr.com ▟에서{ Databricks-Certified-Professional-Data-Engineer }를 검색하고 무료로 다운로드하세요Databricks-Certified-Professional-Data-Engineer합격보장 가능 시험
- Databricks-Certified-Professional-Data-Engineer인증시험 인기 덤프문제 인증시험정보 🙆 ➡ www.koreadumps.com ️⬅️웹사이트에서➤ Databricks-Certified-Professional-Data-Engineer ⮘를 열고 검색하여 무료 다운로드Databricks-Certified-Professional-Data-Engineer인기자격증 시험덤프공부
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
참고: ExamPassdump에서 Google Drive로 공유하는 무료 2026 Databricks Databricks-Certified-Professional-Data-Engineer 시험 문제집이 있습니다: https://drive.google.com/open?id=1OebAJoABYNjvc106MgXlY4MAucP8Cw7L



