Microsoft DP-800 Dumps von ExamFragen sind ganz gleich wie die richtigen Zertifizierungsprüfungen. Die beinhalten alle Prüfungsfragen und Testantworten in aktueller Prüfung. Und die Software-Version simuliert die gleiche Atmosphäre der aktuellen Prüfungen. Bei der Nutzung der ExamFragen Dumps, können Sie ganz sorglos die Microsoft DP-800 Prüfung ablegen und sehr gute Note bekommen.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
>> Microsoft DP-800 Prüfungsfrage <<
Wollen Sie den Plan machen, dass Sie Microsoft DP-800 Zertifizierungsprüfung ablegen, um Ihre Fähigkeit zu entwickeln. Wenn Sie Microsoft DP-800 Prüfung ablegen, ob Sie die geeigneten Lernhilfe finden? Und welche Unterlage sind wertvoll? Haben Sie Microsoft DP-800 Dumps gewählt? Wenn ja, sorgen Sie sich bitte nicht um den Misserfolg.
43. Frage
You have a database named DB1. The schema is stored in a GitHub repository as an SDK style SQL database project.
You use a feature branch workflow to deploy changes to DB1
You need to update the local feature branch with the latest changes to main, and then create a pull request to merge the feature branch into main for review.
How should you complete the GitHub CLI script? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.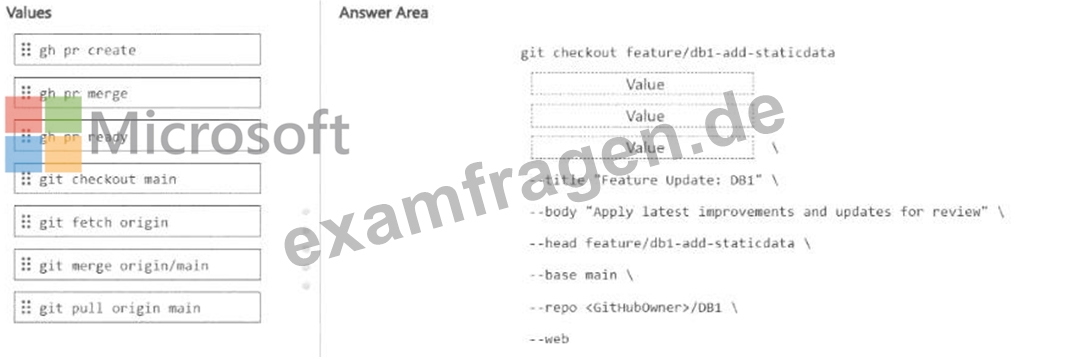
Antwort:
Begründung: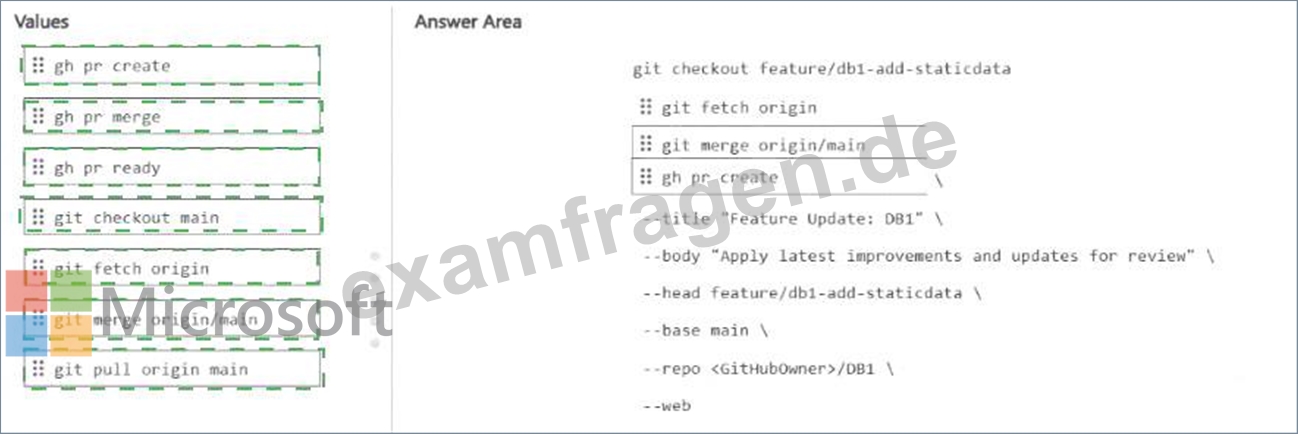
Explanation: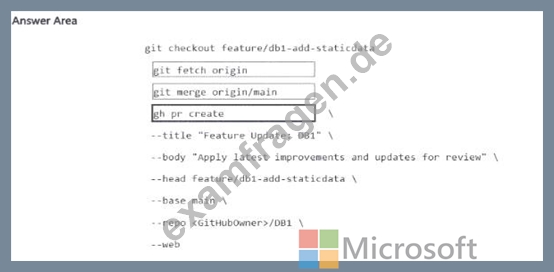
The correct sequence is:
* git fetch origin
* git merge origin/main
* gh pr create
This is the right workflow because the script starts on the local feature branch:
git checkout feature/db1-add-staticdata
To update that local feature branch with the latest changes from main, you first fetch the latest remote refs with git fetch origin , then merge the updated remote main branch into the current feature branch with git merge origin/main . After the feature branch is up to date, the correct GitHub CLI command to open the pull request is gh pr create . GitHub's CLI documentation shows that gh pr create is the command used to create a pull request, and supports flags such as --title, --body, --head, --base, --repo, and --web, which match the script shown in the question.
The other commands are not the best fit here:
* git checkout main would move you off the feature branch, which is not what you want before merging main into the feature branch.
* git pull origin main could update from remote main, but the script pattern here clearly separates fetching and then merging.
* gh pr merge merges an existing pull request, not create one.
* gh pr ready marks a draft PR as ready for review, but does not create the PR.
44. Frage
You have an Azure SQL database named DB1 that contains two tables named knowledgebase and query_cache. knowledge_base contains support articles and embeddings. query_cache contains chat questions, responses, and embeddings DB1 supports an Al-enabled chat agent.
You need to design a solution that meets the following requirements:
* Serializes the retrieved rows from knowledee_base
* Extracts the answer field from the response
* Extracts the embeddings to store in query_cache
You will call the external large language model (LLM) by using the sp_irwoke_external_re standpoint stored procedure.
Which Transact-SGL commands should you use for each requirement? To answer, drag the appropriate commands to the correct requirements. Each command may be used once, mote than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.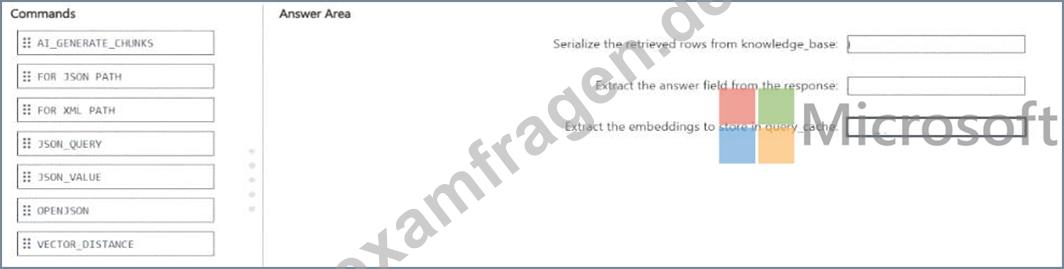
Antwort:
Begründung: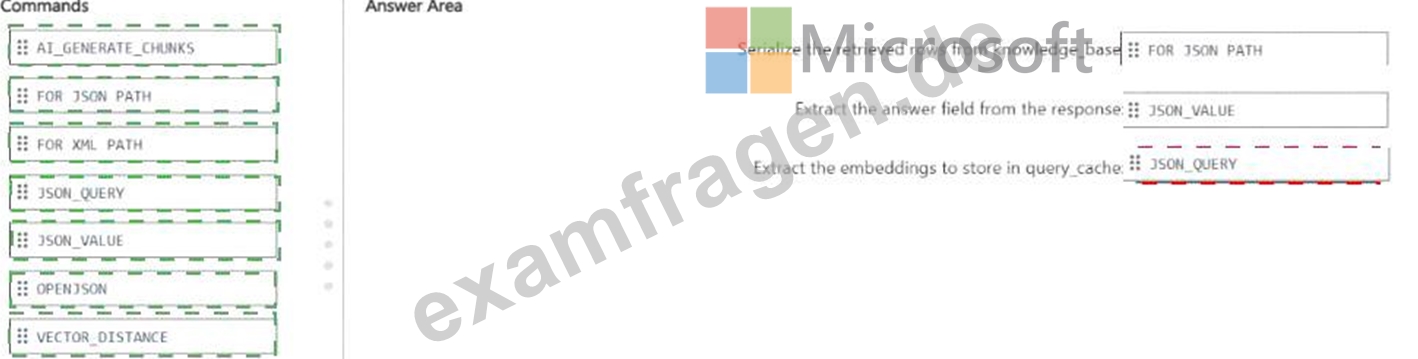
Explanation: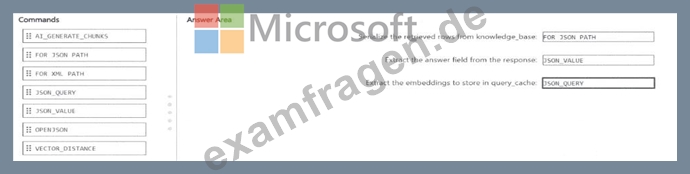
The correct mapping is:
* FOR JSON PATH
* JSON_VALUE
* JSON_QUERY
To serialize the retrieved rows from knowledge_base , the correct command is FOR JSON PATH .
Microsoft documents that FOR JSON formats query results as JSON, and PATH mode is the standard way to shape relational rows into JSON for downstream application or AI use.
To extract the answer field from the response , the correct command is JSON_VALUE because answer is a single scalar field . Microsoft states that JSON_VALUE is used to extract a scalar value from JSON text.
To extract the embeddings to store in query_cache , the correct command is JSON_QUERY because embeddings are returned as a JSON array , not a scalar. Microsoft states that JSON_QUERY extracts an object or array from JSON text, which is exactly the right behavior for an embeddings payload.
The unused options are not the best fit here:
* OPENJSON is mainly for shredding JSON into rows and columns.
* AI_GENERATE_CHUNKS is for chunking text, not extracting fields from a response payload.
* VECTOR_DISTANCE computes similarity between vectors and is unrelated to JSON extraction.
* FOR XML PATH produces XML, not JSON.
45. Frage
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders, dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.orders.
Solution: Identify the partition number for the oldest month, and then run the following Transact-SQL statement.
TRUNCATE TABIE dbo.Orders
WITH (PARTITIONS (partition number));
Does this meet the goal?
Antwort: A
Begründung:
Yes, this meets the goal. Microsoft documents that on a partitioned table , you can use TRUNCATE TABLE ... WITH (PARTITIONS (...)) to remove data from a specific partition, and that this is an efficient maintenance operation that targets only that data subset rather than the whole table. Microsoft's partitioning guidance explicitly lists truncating a single partition as an example of a fast partition-level maintenance or retention operation.
That matches the requirement to remove the oldest month while minimizing impact on other queries.
Because the table is already partitioned by month on OrderDate , identifying the partition number for that oldest month and truncating only that partition is the correct low-impact approach, assuming the table and indexes are aligned as required for partition truncation.
46. Frage
What is a common pattern for integrating LLMs with SQL?
Antwort: A
Begründung:
RAG ensures accurate, up-to-date responses using SQL data.
47. Frage
You need to recommend a solution that will resolve the ingestion pipeline failure issues. Which two actions should you recommend? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
Antwort: C,D
Begründung:
The two correct actions are D and E because the ingestion failures are caused by malformed JSON and duplicate payloads , and these two controls address those two problems directly. Microsoft's JSON documentation states that SQL Server and Azure SQL support validating JSON with ISJSON , and Microsoft specifically recommends using a CHECK constraint to ensure JSON text stored in a column is properly formatted.
For the duplicate-payload issue, creating a unique index on a hash of the payload is the appropriate design.
Microsoft documents using hashing functions such as HASHBYTES to hash column values, and SQL Server allows a deterministic computed column to be used as a key column in a UNIQUE constraint or unique index . That makes a persisted hash-based computed column plus a unique index a practical and exam- consistent way to reject duplicate payloads efficiently.
The other options do not solve the stated root causes:
* Snapshot isolation addresses concurrency behavior, not malformed JSON or duplicate payload detection.
* A trigger to rewrite malformed JSON is not the right integrity control and is brittle.
* Foreign key constraints enforce referential integrity, not JSON validity or duplicate-payload prevention
Topic 1, Contoso Case Study
Existing Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure. The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.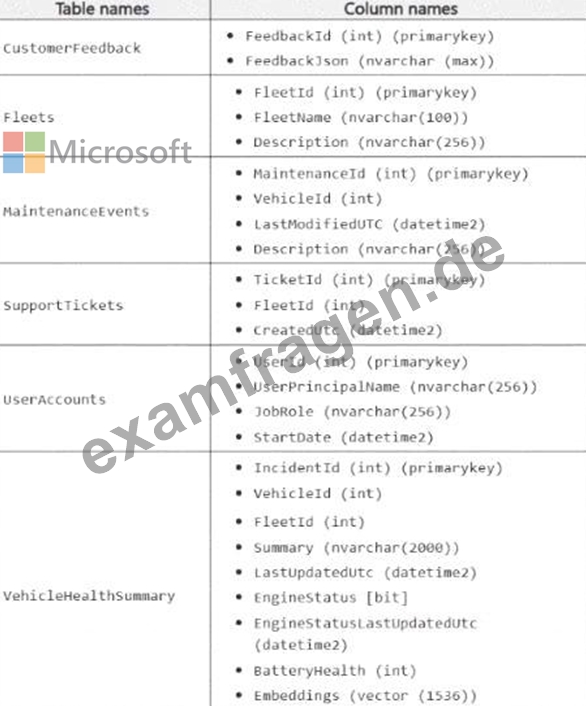
The FeedbackJson column has a full-text index and stores JSON documents in the following format.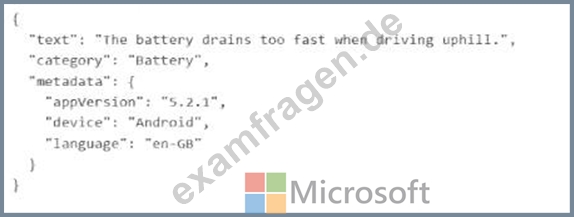
The support staff at Contoso never has the unmask permission.
Requirements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following;
* Al workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
SELECT VehicleTd, Lastupdatedutc, EngineStatus, BatteryHealth FROM dbo.VehicleHealthSumary where fleetld - gFleetld ORDER BV LastUpdatedUtc DESC; You review the execution plan and discover that the plan shows a clustered index scan.
vehicleincidentReports often contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support Al-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracy JSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEvents table updates the corresponding value in the LastModif reduce column to the time of the change.
* Avoid recursive updates.
AI Search, Embedding's, and Vector indexing
The development learn at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases. Contoso identifies the following requirements for querying data in the FeedbackJson column of the customer-Feedback table:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
48. Frage
......
Die Microsoft DP-800 Zertifizierungsprüfung ist heutztage in der konkurrenzfähigen IT-Branche immer beliebter geworden. Immer mehr Leute haben die Microsoft DP-800 Prüfung abgelegt. Aber ihre Schwierigkeit nimmt doch nicht ab. Es ist schwer, die Microsoft DP-800 Prüfung zu bestehen, weil sie sowieso eine autoritäre Prüfung ist, die Computerfachkenntnisse und die Fähigkeiten zur Informationstechnik prüft. Viele Leute haben viel Zeit und Energie auf die Microsoft DP-800 Zertifizierungsprüfung aufgewendet.
DP-800 PDF: https://www.examfragen.de/DP-800-pruefung-fragen.html