Successful people are those who never stop advancing. They are interested in new things and making efforts to achieve their goals. If you still have dreams and never give up, you just need our AI-200 actual test guide to broaden your horizons and enrich your experienceyou can enjoy the first-class after sales service. Whenever you have questions about our AI-200 Actual Test guide, you will get satisfied answers from our online workers through email. We are responsible for all customers. All of our AI-200 question materials are going through strict inspection. The quality completely has no problem. The good chance will slip away if you still hesitate.
| Section | Objectives |
|---|---|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Connect to and consume Azure services | - Integrate Azure services
|
>> AI-200 Reliable Learning Materials <<
One of the most effective strategies to prepare for the Developing AI Cloud Solutions on Azure (AI-200) exam successfully is to prepare with actual Microsoft AI-200 exam questions. It would be difficult for the candidates to pass the Microsoft exam on the first try if the AI-200 study materials they use are not updated. Studying with invalid AI-200 practice material results in a waste of time and money. Therefore, updated Microsoft AI-200 practice questions are essential for the preparation of the AI-200 exam.
NEW QUESTION # 92
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to optimize vector search queries based on the technical requirements. What should you do?
Answer: B
Explanation:
Scenario: Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
*-> Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
To optimize vector similarity queries that must be performed only against products satisfying mandatory metadata constraints, you should Create a B-tree index on metadata filter columns.
1. Evaluate Query Execution OrderIn PostgreSQL with pgvector, combining metadata filters with vector similarity searches often triggers a multi-stage execution plan. When metadata filtering is highly restrictive, creating a B-tree index allows the database engine to quickly narrow down the row scanned before or during the vector evaluation, preventing a costly full-table scan.
2. Assess Indexing Trade-offs
B-tree Index (Metadata): Directly addresses the requirement that vector calculations must be performed only against products satisfying mandatory metadata constraints. It optimizes the metadata filtering step, significantly reducing compute overhead and isolating the target rows for vector processing.
IVFFlat Index (Vector): While an IVFFlat index speeds up high-dimensional approximate nearest neighbor (ANN) searches, it divides vectors into lists. If a metadata filter is applied after an IVFFlat index scan, it can lead to severe recall degradation or inaccurate results because rows matching the metadata might reside in unsearched vector lists. (Note: For newer workloads, HNSW is generally preferred over IVFFlat for better recall and performance, but regular B-trees remain vital for the metadata layer).
3. Ensure Index Residency in RAM
By isolating the dataset using a compact B-tree index on metadata columns, you minimize the active working set. This helps fulfill your operational requirement to ensure that high-dimensional vector indexes and target rows remain resident in RAM for efficient mathematical throughput.
Reference:
https://www.applied-ai.com/briefings/enterprise-rag-architecture/
NEW QUESTION # 93
You are designing a messaging solution by using Service Bus for AI document processing.
You need to ensure that a published message is delivered to multiple independent consumers.
Each consumer must receive their own copy of the message.
Which two Service Bus entities should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,D
Explanation:
Topics and Subscriptions are the two Azure Service Bus entities that fit this scenario.
Topics: The publisher sends the document processing message to a single topic, which acts as the central distribution hub.
Subscriptions: Each independent consumer creates its own individual subscription under that topic. When a message arrives, a copy is forwarded to every independent subscription so each consumer can process their own copy safely and separately.
Reference:
https://learn.microsoft.com/en-us/azure/service-bus-messaging/service-bus-queues-topics-subscriptions
NEW QUESTION # 94
You plan to deploy a web app to App Service on Linux. You create an App Service plan. You create and push a custom Docker image that contains the web app to Azure Container Registry.
You need to access the console logs generated from inside the container in real-time.
How should you complete the Azure CLI command? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.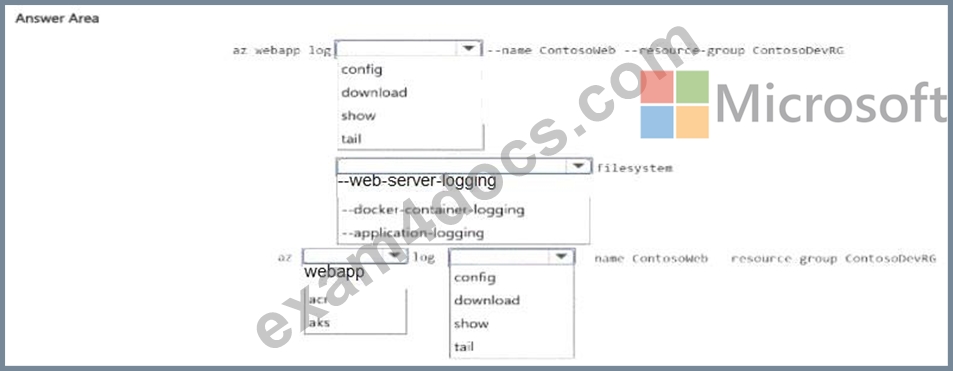
Answer:
Explanation: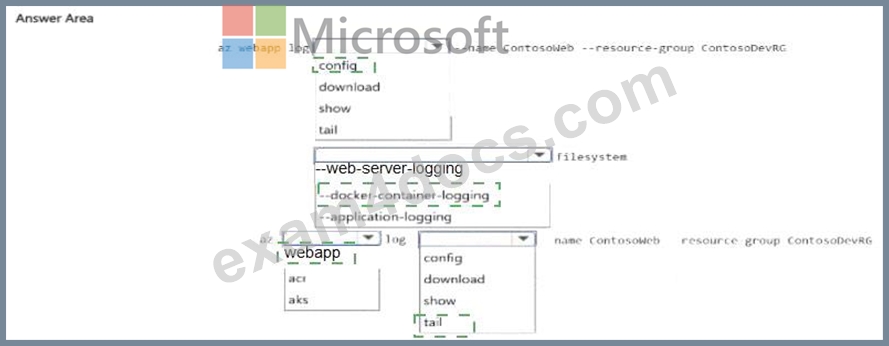
Explanation: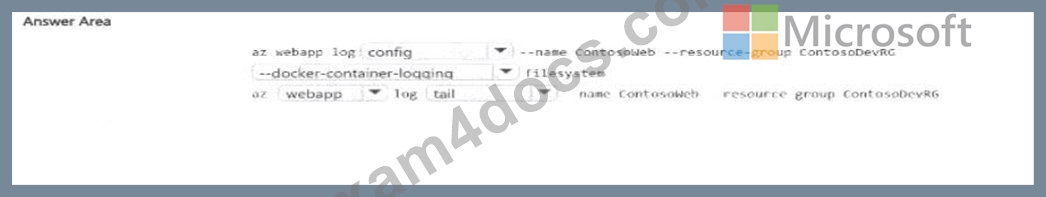
nable container logging with `az webapp log config --docker-container-logging filesystem`, then stream it with `az webapp log tail`.
Detailed Explanation: The Azure CLI exposes separate operations for enabling App Service container logging and viewing the live stream. For a custom Linux container, docker/container logging must first be written to the App Service filesystem. The `az webapp log tail` command then starts real-time log tracing.
Commands such as `show` or `download` inspect configuration or retrieve historical files; they do not provide the requested live stream from the running container.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Azure CLI: az webapp log
NEW QUESTION # 95
You have an Azure Service Bus namespace with a partitioned queue named queue1.
You plan to send a large number of messages through queue1 over the next few weeks. The order of messages will be random. You must minimize the possibility of message transmission interruption by transient failures of individual partitions.
You need to use the optimal configuration of the partition key in the messages.
Which configuration should you use?
Answer: C
NEW QUESTION # 96
You are investigating high latency in an AI search application that processes millions of requests daily.
Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
* Include only data from the last 24 hours.
* Filter for failed requests only.
* Calculate the average duration of dependencies, grouped by operation.
The query must follow best practice to optimize the performance by minimizing the initial data scan.
You need to create the query.
In which order should perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.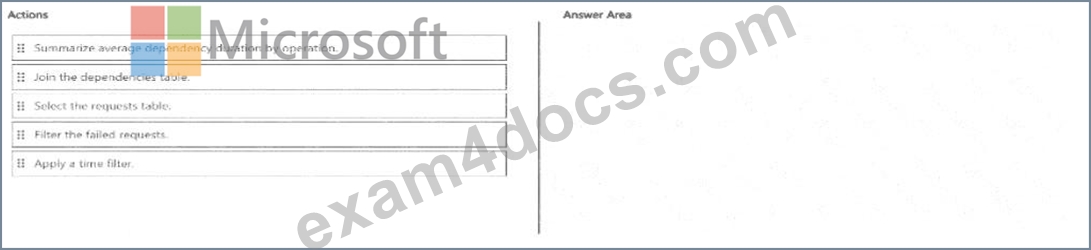
Answer:
Explanation: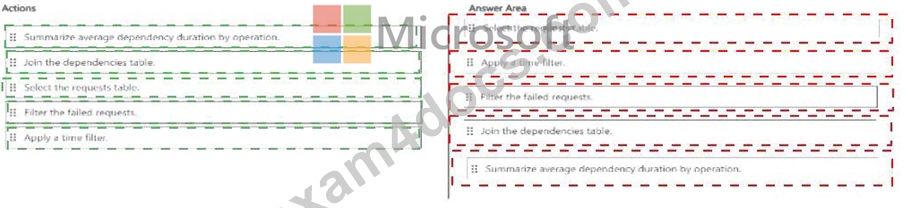
Explanation: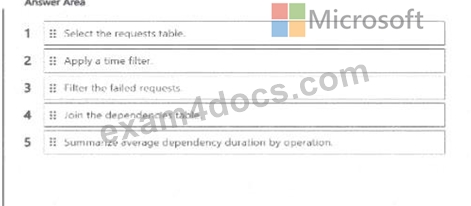
Verified answer: 1) Select the requests table; 2) apply the 24-hour time filter; 3) filter failed requests; 4) join the dependencies table; 5) summarize average dependency duration by operation.
Detailed Explanation: KQL performs best when high-selectivity filters are applied as early as possible, especially the time predicate that limits the amount of data scanned. Starting from AppRequests, restricting to the last 24 hours, and then filtering failures reduces the left-side dataset before the join. The dependency table is then correlated with those requests, and aggregation is performed last to calculate average dependency duration by operation. Joining or summarizing before the time and failure filters would process more data than necessary.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Optimize log queries in Azure Monitor
NEW QUESTION # 97
......
We have thousands of satisfied customers around the globe so you can freely join your journey for the Developing AI Cloud Solutions on Azure certification exam with us. Exam4Docs also guarantees that it will provide your money back if in any case, you are unable to pass the Microsoft AI-200 Exam but the terms and conditions are there that you must have to follow.
Dumps AI-200 Download: https://www.exam4docs.com/AI-200-study-questions.html