When candidates decide to pass the AI-500 exam, the first thing that comes to mind is to look for a study material to prepare for their exam. The most people will consider that choose AI-500 question torrent, because it has now provided thousands of online test papers for the majority of test takers to perform simulation exercises, helped tens of thousands of candidates pass the AI-500 Exam, and got their own dream industry certificates. AI-500 exam prep has an extensive coverage of test subjects, a large volume of test questions, and an online update program.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Evaluate solution quality
|
| Topic 2: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20-25% | - Deploy multi-agent solutions to Azure
|
| Topic 4: Develop multi-agent solutions in Azure | 30-35% | - Design and implement agent memory, context management, and knowledge integration
|
DumpsQuestion proudly says that its product is accurate and trustworthy because it was formulated according to the prescribed content of the Microsoft AI-500 actual test. We offer Microsoft AI-500 Exam Questions free updates for up to 12 months after purchasing. These free updates of actual AI-500 questions will follow the fresh updates in the exam content.
NEW QUESTION # 59
You have a multi-agent solution hosted in an Azure App Service plan.
You use Azure App Configuration to store runtime settings.
A release adds a new planner agent and changes the prompt routing
You need to recommend a release plan that meets the following requirements:
* Slowly rolls out the release to users
* Uses end-user health alerts as rollout gates
* Increases exposure without redeploying the application
* Limits production exposure until the health metrics remain green
* Implements the solution without deploying a second environment
What should you recommend? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.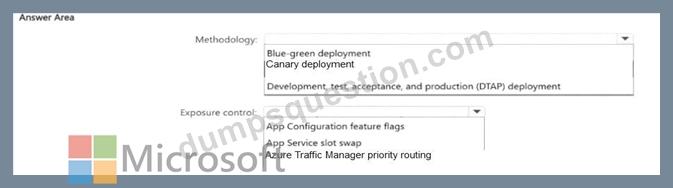
Answer:
Explanation: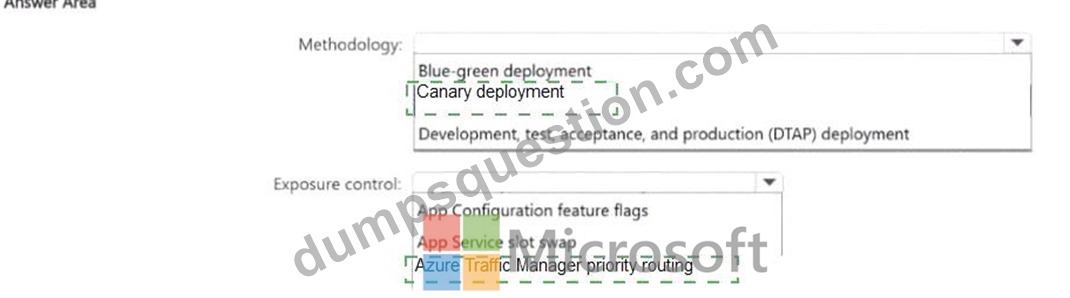
Explanation:
Methodology: Canary deployment; Exposure control: Azure App Configuration feature flags.
A canary release deliberately exposes a new behavior to a limited subset of users and expands that exposure only when operational health remains acceptable. That directly matches the requirement to use end-user health alerts as rollout gates. Azure App Configuration feature flags provide the runtime control needed to change the exposed percentage or audience without redeploying the application. Microsoft documents feature management as a way to decouple deployment from release, which is essential here because the application must stay in one environment while exposure changes. Blue/green deployment normally maintains a second production-like environment or slot, conflicting with the stated constraint. DTAP describes environment progression but not the requested gradual production exposure. Therefore canary plus App Configuration feature flags satisfies gradual rollout, health gating, dynamic exposure, and the no-second-environment requirement. Least privilege remains the governing principle: grant only the identity, data, tool, or deployment access required for the specific operation. The selected answer preserves that boundary while still allowing the workflow to satisfy its functional requirement.
Official Microsoft reference: Azure App Configuration - feature management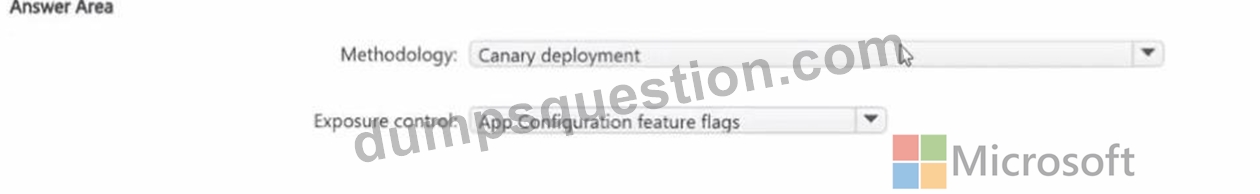
NEW QUESTION # 60
You have a Microsoft Foundry multi-agent solution that uses Microsoft Agent Framework and LangGraph.
Telemetry from the workload is sent to Application Insights.
You need to implement observability components to meet the following requirements:
* Support the investigation of user interactions across agents, models, tools, functions, and API boundaries without relying on verbose production logs.
* Produce recurring and comparable measurements of deployed response quality and safety over time.
What should you use? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.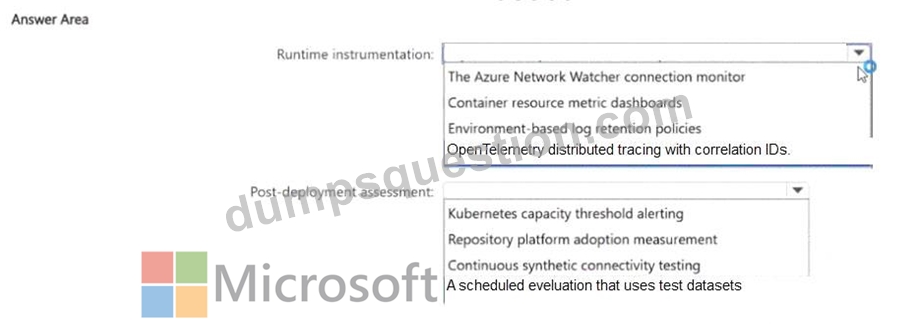
Answer:
Explanation: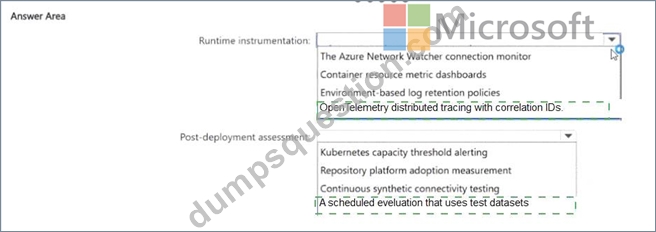
Explanation:
Runtime instrumentation: OpenTelemetry distributed tracing with correlation IDs; Post-deployment assessment: A scheduled evaluation that uses test datasets.
Distributed tracing is the correct runtime mechanism because the objective is to reconstruct a user interaction across agents, models, tools, functions, and API boundaries without relying on verbose log text. Microsoft Foundry uses OpenTelemetry-compatible traces and Application Insights so related spans can be correlated into one execution path. Correlation identifiers allow operators to isolate one conversation and inspect where latency, failures, or unexpected behavior originated. The second requirement is different: it asks for recurring, comparable measurements of deployed response quality and safety. Scheduled evaluations against stable test datasets provide that longitudinal benchmark and are more appropriate than ad hoc tracing or infrastructure- only dashboards. Together, OpenTelemetry answers "what happened in this run?" while scheduled evaluation answers "is behavior getting better or worse over time?" The selected pair therefore covers both operational diagnosis and quality regression monitoring. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry observability concepts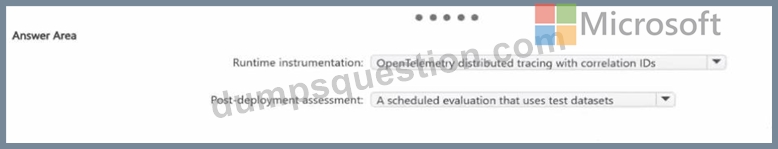
NEW QUESTION # 61
You have a Microsoft Foundry agent that answers questions about products. You evaluate the agent responses and discover the following issues:
* Questions about a product named product1 make up 40 percent of user traffic, and responses are returned in inconsistent formats.
* Questions about a product named product2 appear infrequently in the existing logs but have high escalation rates.
The available chat logs include customer names and contact details, and the labeling budget enables subject matter experts (SMEs) to review only a limited subset of training examples.
You need to design a dataset preparation plan to fine-tune the agent. The solution must meet the following requirements:
* Match usage patterns for the product1 questions.
* Cover the product2 questions.
* Meet General Data Protection Regulation < GDPR) and Health Insurance Portability and Accountability Act (HIPAA) privacy requirements for names and contact details.
* Minimize SME review efforts during labeling.
What should you include in the design? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.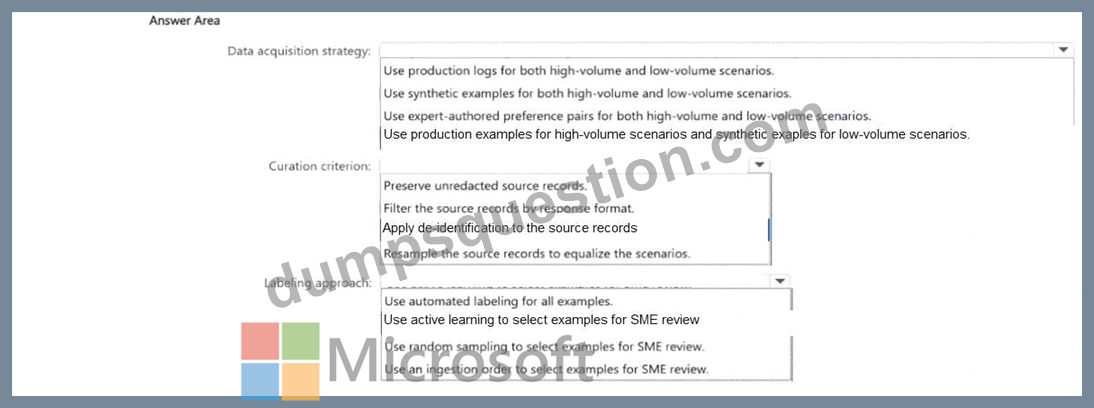
Answer:
Explanation: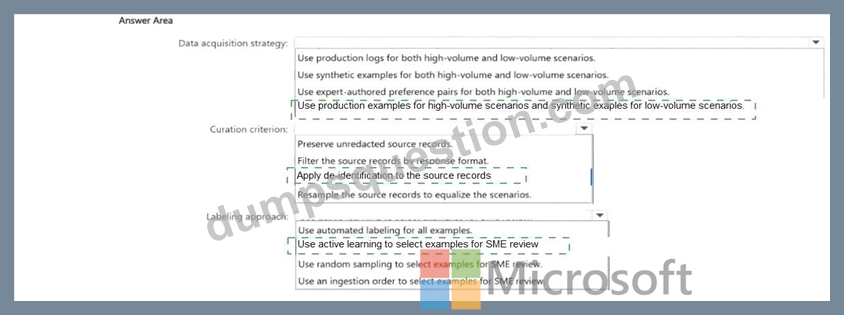
Explanation:
Data acquisition: Production examples for high-volume product1 and synthetic examples for sparse product2; Curation: De-identify source records; Labeling: Use active learning to prioritize SME review.
Product1 represents a large share of real traffic, so production examples best preserve its true usage distribution. Product2 appears infrequently but has high escalation impact, making synthetic generation appropriate for filling the coverage gap without waiting for more production traffic. Because the available logs contain names and contact information, those records should be de-identified before they are reused for training or labeling. Finally, the SME budget is limited, so active learning should prioritize the examples where expert labels are most informative instead of reviewing a uniform random sample. Microsoft Foundry guidance supports synthetic fine-tuning data when real examples are sparse, and Microsoft healthcare/privacy tooling supports de-identification of sensitive identifiers. This design balances representativeness, rare-case coverage, privacy, and labeling efficiency. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Foundry - synthetic fine-tuning data generation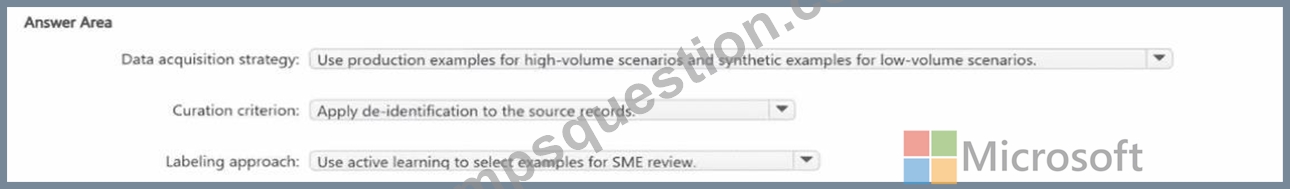
NEW QUESTION # 62
You need to design a solution to resolve the Scheduling agent issue.
What should you include in the design?
Answer: B
Explanation:
The Scheduling agent ' s MCP server fails transiently during peak load. Microsoft Azure reliability guidance recommends retries with exponential backoff for transient faults so that callers do not immediately repeat requests at the same rate and worsen a temporarily overloaded dependency. Immediate retries can create a retry storm, especially when many agent requests encounter the same service condition. Routing the tool call through a different agent does not remove the underlying MCP dependency and would only add coupling. A well-designed retry policy should normally include a bounded retry count, increasing delay, jitter where appropriate, and respect for server-provided retry guidance when available. The scenario asks which design element directly addresses the timeouts, and exponential backoff is the established resilience pattern for transient service saturation. Therefore A is the correct choice. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Azure Well-Architected Framework - Handle transient faults
NEW QUESTION # 63
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.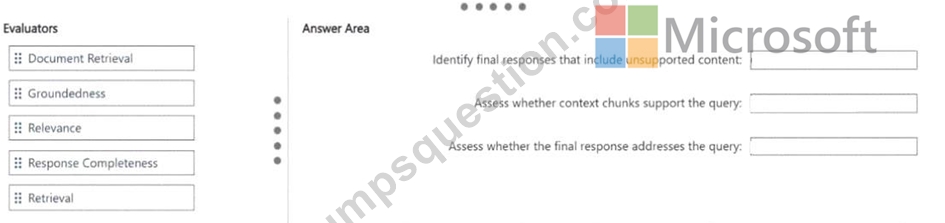
Answer:
Explanation: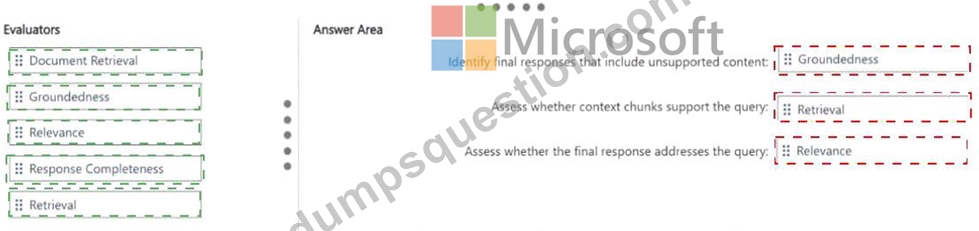
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators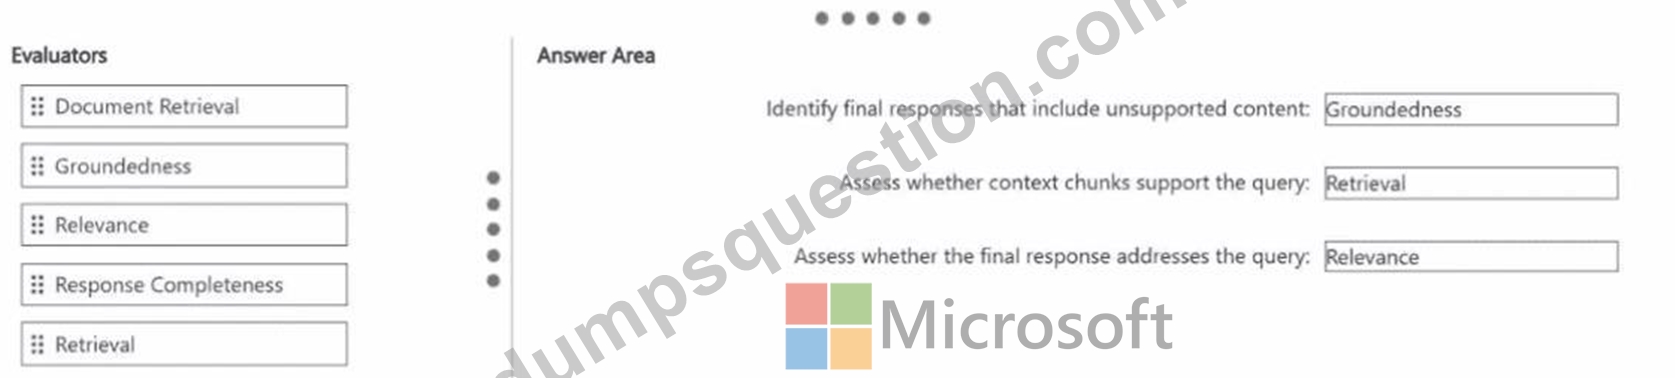
NEW QUESTION # 64
......
The Microsoft AI-500 certification is one of the hottest career advancement credentials in the modern Microsoft world. The AI-500 certification can help you to demonstrate your expertise and knowledge level. With only one badge of AI-500 certification, successful candidates can advance their careers and increase their earning potential. The Microsoft AI-500 Certification Exam also enables you to stay updated and competitive in the market which will help you to gain more career opportunities.
Test AI-500 Valid: https://www.dumpsquestion.com/AI-500-exam-dumps-collection.html