DOWNLOAD the newest ActualPDF AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1yLaGPBL_o2syB5lmzfBEo5Xu_EXI5UTq
There are many users that are using Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam questions and rated it as one of the best in the market. The customers are pleased with Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam questions and all of them have passed the Operationalizing Machine Learning and Generative AI Solutions (AI-300) certification exam on the very first try.
| Section | Objectives |
|---|---|
| Operationalizing machine learning solutions | - Deployment and monitoring
|
| Implement secure and scalable AI systems | - Scalability and performance optimization
|
| Design and implement generative AI solutions | - RAG (Retrieval Augmented Generation) solutions
|
| Plan and design AI solutions using Azure AI services | - Requirements gathering and solution architecture
|
If you want to get through the AI-300 practice exam quickly with less time and efforts, our learning materials is definitely your best option. One or two days' preparation and remember the correct AI-300 test answers, getting the certification will be simple for our candidates. Free trials of AI-300 Exam PDF are available for everyone and great discounts are waiting for you. Join us and realize your dream.
NEW QUESTION # 74
You manage a Retrieval-Augmented Generation (RAG) system that uses Azure AI Search to retrieve documents from an indexed knowledge base.
The system must support the following retrieval requirements:
Queries that include exact policy identifiers must return matching documents even when semantic similarity is low.
Natural-language questions must prioritize semantically relevant documents even when keywords are not an exact match.
You need to configure the retrieval approach to meet the requirements.
How should you configure the retrieval behavior for each requirement? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.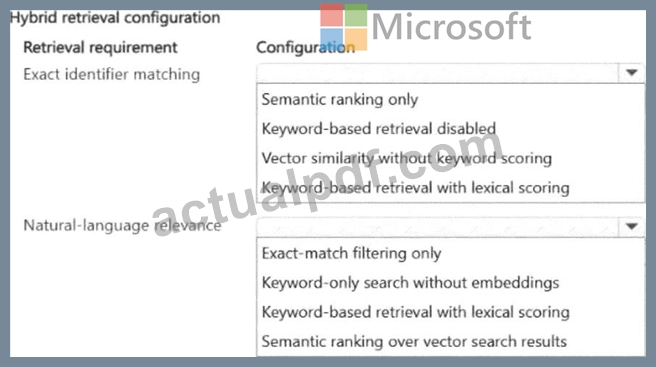
Answer:
Explanation: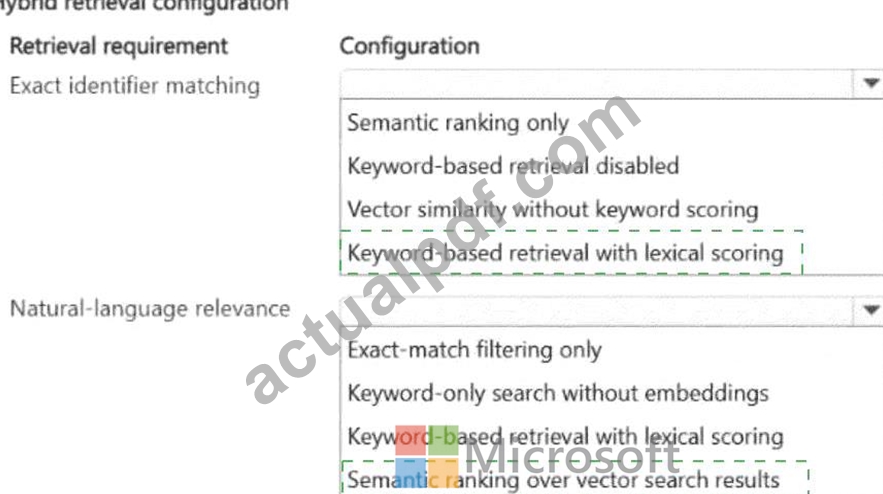
Explanation:
Different query types require fundamentally different retrieval algorithms. For queries that include exact policy identifiers, keyword or BM25 search is the correct choice because BM25 scores documents based on term frequency and inverse document frequency - an exact match on a specific policy identifier such as POL-
2024-HR-042 scores very highly regardless of semantic context. This is the right approach when semantic similarity is low but exact term matching is critical. For natural-language questions where keywords may not be an exact match, semantic or vector search is the correct choice because vector embeddings capture meaning rather than exact tokens, finding relevant documents even when the user ' s vocabulary differs from the document ' s terminology. Azure AI Search supports both modes through its hybrid search capability, and the correct configuration maps each query type to its optimal retrieval algorithm.
Microsoft Learn Reference Topic: Configure hybrid search in Azure AI Search - BM25 keyword search vs.
semantic vector search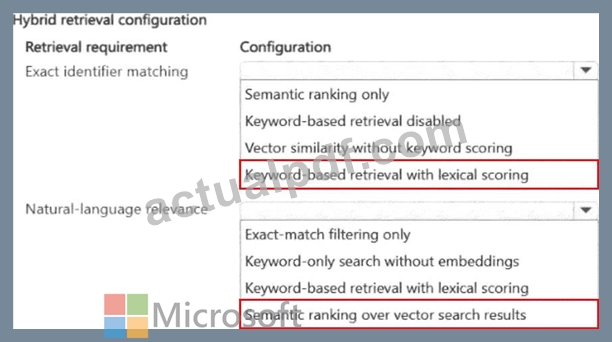
NEW QUESTION # 75
You train and register an Azure Machine Learning model
You plan to deploy the model to an online endpoint
You need to ensure that applications will be able to use the authentication method with a non-expiring artifact to access the model.
Solution:
Create a managed online endpoint with the default authentication settings. Deploy the model to the online endpoint.
Does the solution meet the goal?
Answer: B
NEW QUESTION # 76
A team is deploying machine learning models to a production inference endpoint in Azure Machine Learning.
The team requires a safe way to validate a new model version without disrupting existing users.
You need to recommend a deployment strategy for controlled testing of a new model version.
What should you configure?
Answer: B
Explanation:
A managed online endpoint can host multiple named deployments simultaneously, and you control what percentage of incoming traffic each deployment receives. With traffic splitting, you route a small percentage of live traffic to the new deployment while the majority continues to the proven existing model. You then monitor error rates, latency, and output quality for both deployments in real time under genuine production load. If the new model underperforms, you instantly route traffic back - no downtime, no user disruption. If it outperforms, you gradually increase its traffic share to 100%. Updating the registry version (option B) does not affect running deployments. A staging endpoint (option C) does not validate under real production load.
An evaluation script (option D) is a pre-deployment step. Traffic splitting is the blue/green and canary deployment pattern that Microsoft recommends for safe production rollouts.
Microsoft Learn Reference Topic: Perform safe rollout of new model deployments using traffic splitting - Azure Machine Learning
NEW QUESTION # 77
You manage an Azure Machine Learning workspace. You create an experiment named experiment1 by using the Azure Machine Learning Python SDK v2 and MLflow. You are reviewing the results of experiment1 by using the following code segment: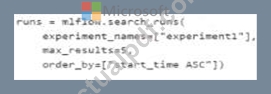
For each of the following statements, Select Yes if the statement is true Otherwise, select No.
Answer:
Explanation:
Explanation: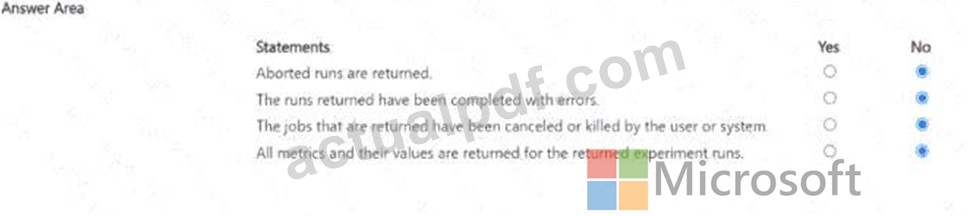
NEW QUESTION # 78
A team develops multiple AI applications in Microsoft Foundry that rely on shared prompt templates.
The team requires a centralized way to track, version, and reuse prompt content across projects.
You need to recommend a solution to track and reuse prompt content.
Which approach should you recommend?
Answer: D
Explanation:
In Microsoft Foundry, centralizing prompt templates in a Git repository (such as GitHub) is a recommended GenAIOps practice to ensure consistency, versioning, and reuse across multiple AI applications.
Storing prompts as versioned files in a Git repository is an excellent approach for Microsoft Foundry applications. It treats prompts like code (PromptOps), enabling clear audit trails, peer reviews via Pull Requests, and easy rollbacks.
To make this centralized system effective, you should consider these three components:
Centralized Repository: Use a single "Prompt Bank" repo where templates are stored in a structured format like JSON or YAML. Include metadata like model version, temperature, and input variables.
Prompt Registry / SDK: Develop a small internal utility (or use a tool like Azure AI Studio's Prompt Flow) that allows applications to fetch the "latest" or a "tagged" version of a prompt via API or as a Git submodule.
CI/CD Integration: Automate testing so that when a prompt file is updated, it triggers a "prompt evaluation" pipeline to ensure the change doesn't degrade AI performance across the dependent projects.
Reference:
https://www.getmaxim.ai/articles/best-practices-for-prompt-management-in-ai-applications
NEW QUESTION # 79
......
Our company is professional brand established for compiling AI-300 exam materials for candidates, and we aim to help you to pass the examination as well as getting the related AI-300 certification in a more efficient and easier way. Owing to the superior quality and reasonable price of our AI-300 Exam Materials, our company has become a top-notch one in the international market. Our AI-300 exam torrents are not only superior in price than other makers in the international field, but also are distinctly superior in many respects.
AI-300 Reliable Dumps Questions: https://www.actualpdf.com/AI-300_exam-dumps.html
P.S. Free & New AI-300 dumps are available on Google Drive shared by ActualPDF: https://drive.google.com/open?id=1yLaGPBL_o2syB5lmzfBEo5Xu_EXI5UTq