弊社JpshikenのAI-300テストブレインダンプを習得するのに20〜30時間しかかからず、試験に参加すれば、AI-300試験に合格する可能性が非常に高くなります。多くの人々にとって、彼らは現役のスタッフであろうと学生であろうと、仕事や家族生活などで忙しいのです。ただし、AI-300準備トレントを購入すると、主に仕事、学習、または家族の生活に時間とエネルギーを費やすことができ、毎日Operationalizing Machine Learning and Generative AI Solutions試験トレントを学ぶことができます。また、AI-300試験の質問で簡単にAI-300試験に合格できます。
| Section | Weight | Objectives |
|---|---|---|
| Implement machine learning model lifecycle and operations | 25–30% | - Deploy models to production
|
| Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
AI-300の有効な学習ガイド資料は、何十年にもわたる専門家や教授の骨の折れる努力により、世界市場で主導的な地位を占めていることがわかっています。当社のAI-300学習練習問題のAI-300試験の準備をしている多くの人々が重い負担を軽減するのを助けるために、AI-300学習教材には多くの特別な機能があります。散発的な時間の使用。 AI-300試験の質問を購入する必要がある場合、AI-300試験に簡単に合格できます。
質問 # 11
You have an Azure Machine Learning workspace.
You plan to use Azure Machine Learning Python SDK v2 to define a pipeline component that trains an image classification model. The execution logic of the component is contained in the train() function in the file named modeljrain.py.
You write code to import all required libraries and store it as train_component.py in the same folder that contains model_train.py.
You need to complete the remaining code in train_component.py.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.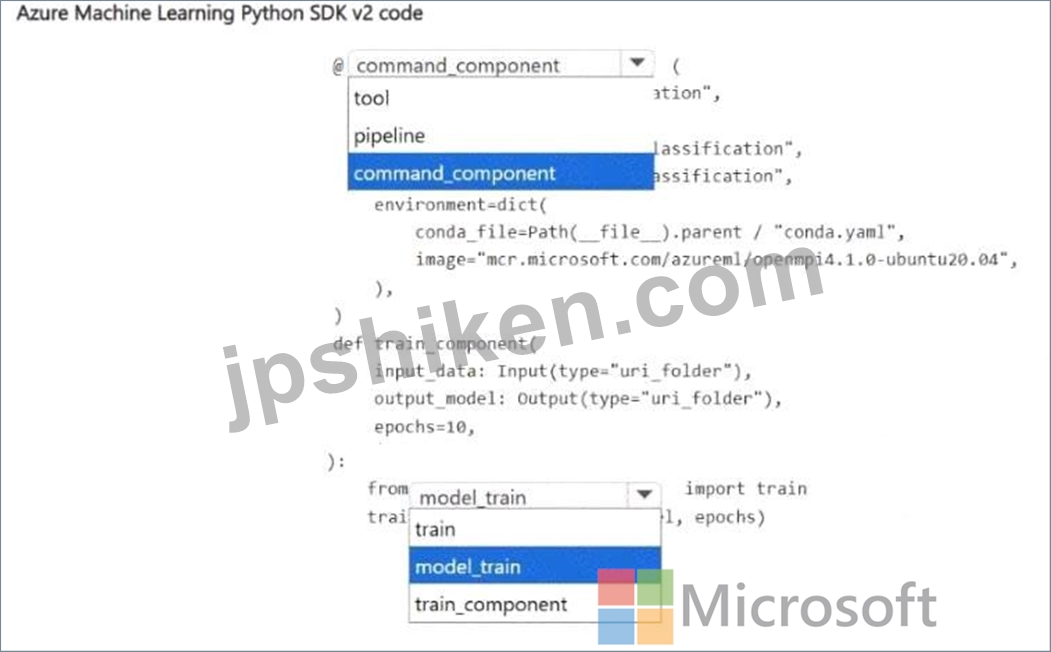
正解:
解説: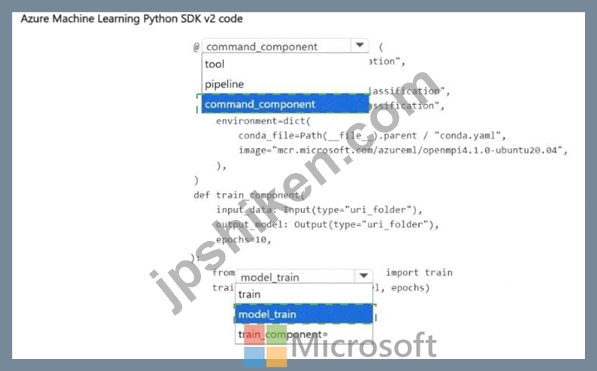
Explanation: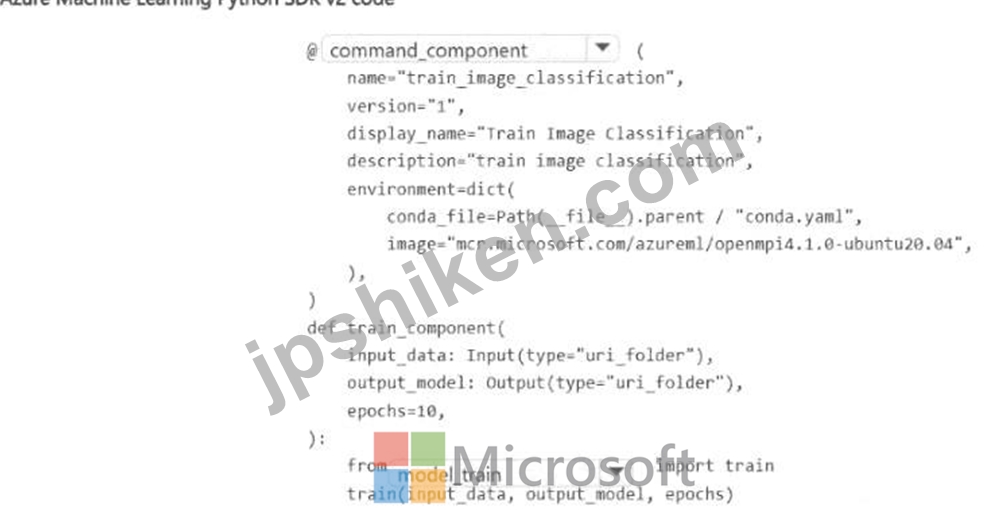
質問 # 12
A Retrieval-Augmented Generation (RAG) solution returns incomplete answers because relevant content is inconsistently retrieved from the knowledge source.
You need to improve RAG accuracy without changing the embedding model currently in use. You need to achieve this goal while minimizing operational costs.
Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point. Choose two .
正解:A、D
解説:
Microsoft ' s RAG optimization guidance identifies two high-impact, low-cost improvements for retrieval quality that do not require changing the embedding model. First, tuning chunk size and overlap (option A):
chunk size determines how much context each retrieved piece contains - too large and irrelevant content dilutes the signal; too small and answers may be split across chunks. Adjusting these parameters requires only re-indexing the documents with zero additional compute cost. Second, implementing a re-ranker (option B): a re-ranker is a cross-encoder model that takes the top-N retrieved chunks and re-scores them based on their specific relevance to the query, significantly improving precision by filtering out contextually irrelevant chunks. Re-rankers add modest compute cost but are far cheaper than changing the embedding model, which would require re-embedding the entire knowledge base. Increasing token limits (option C) and optimizing embedding vector length (option D) do not address retrieval accuracy without an embedding model change.
Microsoft Learn Reference Topic: Optimize RAG pipelines - Chunk size tuning and re-ranking in Azure AI Search and Azure Machine Learning
質問 # 13
A team manages an Azure Machine Learning workspace where they deploy models to online endpoints.
The team needs to introduce a new version of a model to production without disrupting existing users.
The team must validate the new version before full rollout.
You need to reduce risk during deployment.
What should you do?
正解:D
解説:
To introduce a new model version in Azure Machine Learning without service interruption, you should use Blue/Green Deployment with Traffic Splitting.
This strategy allows you to run two versions of a model simultaneously under a single Online Endpoint, gradually shifting users to the new version once it is validated.
Key Benefits
Zero Downtime: The endpoint URL stays the same; only the backend routing changes.
Easy Rollback: If the new model fails, you can instantly flip traffic back to 100% on the old version.
Risk Mitigation: Only a small subset of users is exposed to the unproven model initially.
Implementation Steps
1. Create the "Green" Deployment
Deploy the new model version as a second deployment under the existing online endpoint.
Initially, set its traffic allocation to 0%.
2. Canary Testing (Initial Split)
Shift a small percentage of traffic (e.g., 10%) to the new deployment. Monitor performance metrics, error rates, and model accuracy in a real-world environment.
3. Validation & Monitoring
Use Azure Monitor and Application Insights to compare the two deployments. Check for:
Latency: Is the new model slower?
HTTP Status Codes: Are there 4xx or 5xx errors?
Model Drift: Is the prediction quality as expected?
4. Full Rollout
If the new version is stable, increase the traffic split (e.g., 50/50) until the new model handles
100% of the traffic.
5. Cleanup
Once the "Green" deployment is confirmed as the new production standard, you can delete the old ("Blue") deployment to save costs.
Reference:
https://learn.microsoft.com/en-us/azure/well-architected/ai/operations
質問 # 14
A product team is building a customer support assistant that must respond consistently across multiple channels.
Early testing shows that small wording changes in prompts cause large differences in tone and factual accuracy.
The team needs prompts that are reliable, reusable, and adaptable across multiple use cases without retraining the underlying model.
You need to design prompts that improve response quality while remaining flexible for future changes.
Which two actions should you perform? Each correct answer presents part of the solution. (Choose two.)
正解:C、D
解説:
B and C provide the strongest architecture for reusable and predictable prompts. Separating persistent application instructions from dynamic user input establishes a clear instruction hierarchy . The stable portion of the prompt can define application behavior while channel-specific or request-specific content remains variable. This reduces coupling between user wording and the behavioral rules of the assistant and makes the prompt easier to reuse, version, test, and modify.
The system prompt should establish the model ' s role, behavioral boundaries, tone, communication style, response format, and other persistent rules. Microsoft specifically describes system messages as high-priority instructions used to define an assistant ' s role and boundaries and to set tone and communication style.
Fine-tuning for every conversational variation is unnecessarily expensive and contradicts the requirement to remain adaptable without retraining. Increasing temperature increases randomness and therefore works against consistent responses. Although repeating important instructions can sometimes mitigate recency effects, Microsoft treats this as an optional prompt-engineering technique to experiment with, not the primary architectural technique for producing reusable prompts.
Study Guide Reference: Design and implement a GenAIOps infrastructure - design and develop prompts, prompt management, prompt variants, system instructions, and reusable prompt structures.
質問 # 15
You have an Azure Machine Learning workspace that includes an AmICompute cluster and a batch endpoint.
You clone a repository that contains an MLflow model to your local computer. You need to ensure that you can deploy the model to the batch endpoint.
Solution: Create a data asset in the workspace.
Does the solution meet the goal?
正解:A
質問 # 16
......
世界大手の企業の中で、大部分の企業はMicrosoft製品を主として運用しています。だから、Microsoftの認証を取得したら、激しい競争の中でもいい仕事を探せます。受験生は試験に合格したいなら、AI-300問題集をしようするのは一番迅速の方法です。多くの受験生たちはこの方法を通して試験に合格しました。
AI-300日本語練習問題: https://www.jpshiken.com/AI-300_shiken.html